because i read the scientific literature ancedotal reports mean almost nothing if the rate is around 5%
RESEARCH
-
Starving for Intelligence: Massive Compute Constraints Challenge
By
–
We are starving for Intelligence and we are still massively compute constrained.
-
Neural Network Expert Disputes AI Model Hallucination Claims
By
–
I am blocking you unless you retract this. I have been working on neural networks for 30 years. A recent survey showed my technical predictions have been over 90% correct. Your own data (ie the data that you pointed) supported my claim that current models still hallucinate.
-
VoxCPM 2: Revolutionary Open-Source Text-to-Speech Model Released
By
–
Loved collaborating with @OpenBMB on this.
— Charly Wargnier (@DataChaz) 6 avril 2026
♻️ Show some love with a repost if you enjoyed the content. Supporting small teams is how we build the future 🤗
Stay ahead with daily drops on LLMs, agents, and workflows by following me → @datachaz https://t.co/tXpDPDlS6GLoved collaborating with @OpenBMB on this. ♻️ Show some love with a repost if you enjoyed the content. Supporting small teams is how we build the future 🤗 Stay ahead with daily drops on LLMs, agents, and workflows by following me → @datachaz Charly Wargnier (@DataChaz) 🚨 The new era of Open-Source TTS is here. @OpenBMB's VoxCPM 2 just dropped and it changes the game for voice synthesis. We are moving past fixed speaker presets to true "Concept-to-Voice" generation. Just describe the voice you want in text, and the 2B model builds it. How does it beat discrete token-based models like Qwen3-TTS? VoxCPM 2 uses a cutting-edge Diffusion-Autoregressive Continuous Representation framework. → Eliminates discrete token data loss → Preserves raw acoustic metadata → Outputs natively in 48,000Hz CD-quality audio The studio-grade expressiveness is phenomenal. I gave it a specific text prompt: "Deep booming male voice, strong resonant vocal, rhythmic hype pace." It dynamically calculates natural breathing, chest vibrations, and micro-pauses. It actually performs the text naturally. Best of all, the entire stack is fully open-source and highly developer-friendly. → Native PyTorch inference workflows → LoRA and full-parameter fine-tuning → Compatible with voxcpm-nanovllm Repo and demos links in 🧵↓ — https://nitter.net/DataChaz/status/2041289800695873546#m
-
Generative AI will enable sophisticated creative rewrites in six years
By
–
Lisez bien. Dans moins de 6 ans, les IA génératives seront tellement puissantes que vous pourrez prompter 20 fois "procède à la réécriture du livre de Victor Hugo « Les Misérables » et fait en sorte que ça se finisse bien pour Fantine Gavroche Éponine, ajoute des détails
-
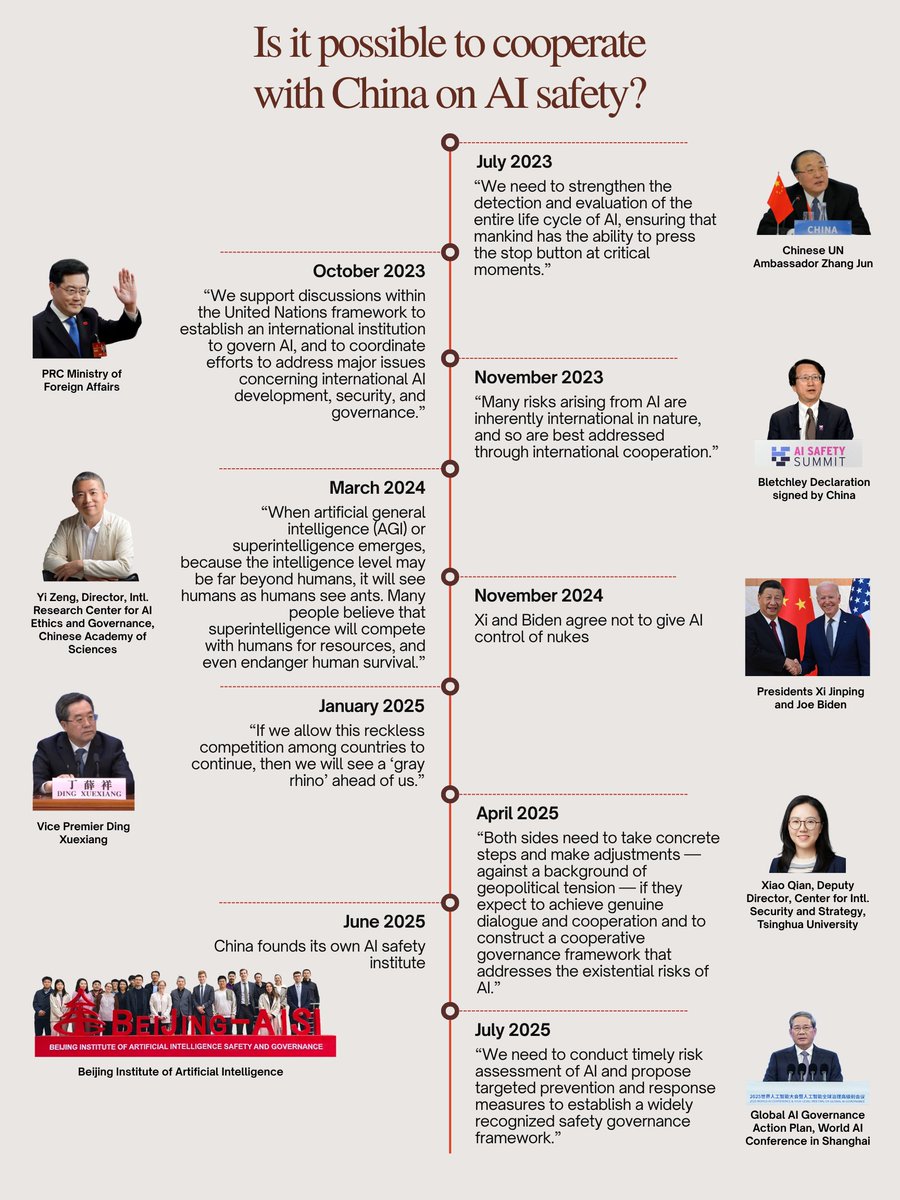
Possibility of AI governance coordination between US and China
By
–
Is it possible to coordinate with China on AI governance? Critics of our proposed international agreement say no. But statements from Chinese government officials and academic figures paint a more optimistic picture:
→ View original post on X — @esyudkowsky, 2026-04-06 22:47 UTC
-
Gary Marcus Challenges Claims of Near-Zero LLM Hallucination Rates
By
–
This ML Prof told me that the hallucination rate for frontier reasoning LLMs is “next to nil” And then gave me data, only after I pushed him, showing a best-case rate of 4.6% (which of course is benchmark specific). 4.6% is not “next to nil”. Imagine if your accountant hallucinated 4.6% of the time. Or worse, your pilot. Aran Nayebi (@aran_nayebi) Have you had a chance to try the latest reasoning models? You'll see their hallucination rate is next to nil. In fact, there’s a big difference between frontier reasoning models & the base LLMs that're freely available to the public, see e.g. here: nitter.net/aran_nayebi/status/202… — https://nitter.net/aran_nayebi/status/2041249684698648922#m
→ View original post on X — @garymarcus, 2026-04-06 22:25 UTC
-
AI Hallucinations Remain Unsolved According to Gary Marcus
By
–
The plot gets wilder: the prof's evidence for hallucinations has been allegedly solved is a chart from OpenAI showing that all models test hallucinated at least 4.6% of the time on known (therefore somewhat gameable) benchmark. That certainly isn't "solved". Imagine if your accountant hallucinated 4.6% of the time. Or your pilot. [Translated from EN to English]
→ View original post on X — @garymarcus, 2026-04-06 22:21 UTC
-
LLM Hallucination Rates Remain Critical Barrier for Production
By
–
Your best data are still a 4.6% hallucination rate, and on a handpicked benchmark at that. Game over. 4.6% isn’t even close to zero. And for many applications that’s deadly. Thanks for playing, and goodbye.
-
Symbolic Learning vs Curve-Fitting: Reverse-Engineering Generative Programs
By
–
With curve-fitting, you are recording a lossy approximation of the output of some generative program. With symbolic learning, you are losslessly reverse-engineering the source code of the generative program. Symbolic learning won't be the best fit for all problems, but for the ones where the latent program is reasonably simple, it will outperform by many orders of magnitude.