A blank screen after 45 minutes has zero recovery rate. A mediocre behavioral answer still passes. That asymmetry is the whole reason to take this seriously now.
RESEARCH
-
AMD Telemetry Dataset Reveals Anthropic Changes Confirmation
By
–
An AMD director with 7,000 sessions of telemetry is not vibes. That's a dataset and Anthropic admitting to the changes after the data dropped is the confirmation that matters.
-

TactileAloha: Giving Robots the Sense of Touch
By
–
TactileAloha: Empowering #Robots with the Sense of Touch
— Ronald van Loon (@Ronald_vanLoon) 13 avril 2026
by @IntEngineering
#Robotics #ArtificialIntelligence #MachineLearning #EmergingTech #Innovation pic.twitter.com/SA7jbU2fVqTactileAloha: Empowering #Robots with the Sense of Touch
by @IntEngineering #Robotics #ArtificialIntelligence #MachineLearning #EmergingTech #Innovation -

LLMs Fairness and Consistency in AI Model Evaluation
By
–
Are LLMs truly fair and consistent when judging other AI models? A collaborative team from Peking University, NUS, Institute of Science Tokyo, Nanjing University, Carnegie Mellon, Westlake, and Southeast University has the answer! They introduce TrustJudge, a probabilistic
-

Mouse-Inspired Robot Learns Brain-Based Place Recognition
By
–
How a Mouse-Inspired Robot Learns to Recognize Places Like a Brain
— Ronald van Loon (@Ronald_vanLoon) 13 avril 2026
by @lukas_m_ziegler
#Robotics #Engineering #ArtificialIntelligence #Innovation #Technology pic.twitter.com/EPjRBzZMwnHow a Mouse-Inspired Robot Learns to Recognize Places Like a Brain
by @lukas_m_ziegler #Robotics #Engineering #ArtificialIntelligence #Innovation #Technology -
Can Codes and Symbols Emerge in Neural Networks?
By
–
Can codes and symbols emerge in a single neural network? Thinking from the "Neural Computers" paper @rmaruy
rmaruy.hatenablog.com/entry/… [Translated from EN to English] -

Context length benchmarks up to 180k tokens
By
–
Ran some benchmarks on different context lengths all the way to 180k Findings below
-
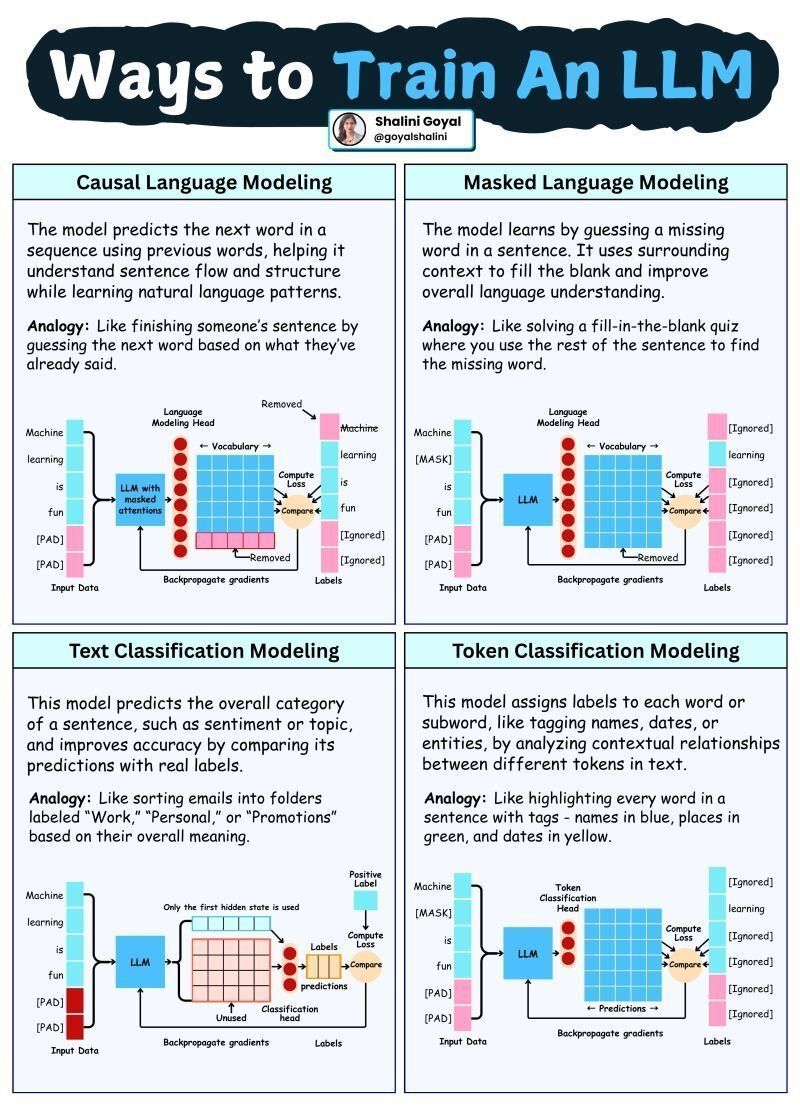
Ways to Train Large Language Models Effectively
By
–
Ways to Train an #LLM
by @goyalshaliniuk #GenAI #ArtificialIntelligence #MachineLearning #ML -

Exploring dense new format with tests in BF16, FP8, NVFP4 and TP scaling
By
–

it's very dense, a new format that I am playing with still need to test it in concurrency + try it in nvfp4 hopefully will be able to compare perplexity in bf16 / fp8 / nvfp4 as well as TP performance jumps from 2 -> 4 -> 8 nodes across all 3 formats most important thing
-
Does Uber Intelligence Come Before Superintelligence?
By
–
does uberintelligence come after or before superintelligence