Simply retrieving a reasoning trace looks a lot like human reasoning, until it's time to navigate uncharted territory. If you memorized all reasoning traces of humans from 10,000 BC, you could automate their lives but you could not invent modern civilization.
RESEARCH
-
Centenarians as Norm: Societal Implications of Cognitive Enhancement
By
–
Centenarians who are sharp and still running things is already happening without any of the upgrades. The interesting question is what happens when that becomes the norm rather than the exception.
-
Open access paper confirmed no paywall required
By
–
That's correct there's no paywall on the paper!
-

Machine Learning Transforms IoT Computing with New Perspectives
By
–


#MachineLearning Puts New Lens on #IoT Computing! by @gp_pulipaka! #BigData #Analytics #DataScience #AI #IIoT #PyTorch #Python #RStats #TensorFlow #Java #ReactJS #GoLang #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #100DaysofCode geni.us/New-Lens-IoT
→ View original post on X — @gp_pulipaka, 2026-04-14 04:57 UTC
-

GPT, Generative AI, and LLMs Conference by Aver Conferences
By
–

GPT, Generative AI, and LLMs! @AverConferences #BigData #Analytics #DataScience #AI #MachineLearning #NLProc #IoT #IIoT #Python #RStats #TensorFlow #JavaScript #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #100DaysOfCode geni.us/Aver-Confer
→ View original post on X — @gp_pulipaka, 2026-04-14 04:57 UTC
-

Deep Reinforcement Learning for Nuclear Fusion Artificial Sun Engineering
By
–


Illuminating the Gateway Path to Deep Reinforcement Learning to Engineer an Artificial Sun with Nuclear Fusion! #BigData #Analytics #DataScience #AI #MachineLearning #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #GoLang #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #100DaysofCode geni.us/Building-Sun
→ View original post on X — @gp_pulipaka, 2026-04-14 04:57 UTC
-

GPT and Generative AI Conference at Star Conferences
By
–

GPT, Generative AI and LLM! @starconfs #BigData #Analytics #DataScience #AI #MachineLearning #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #ReactJS #GoLang #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #100DaysofCode cstar.global
→ View original post on X — @gp_pulipaka, 2026-04-14 04:57 UTC
-

Machine Learning for Obesity Classification Using 3D Body Scanning
By
–

Grade Body Measurement with Machine Learning Grading a patient’s obesity level is a critical component of effective healthcare. Obesity is a significant risk factor for a range of serious diseases, including chronic conditions, type-2 diabetes, heart disease, and certain cancers. Understanding a person's obesity status can serve as a powerful catalyst for individuals to take control of their weight. Additionally, intentional weight management not only mitigates health risks but also offers the compelling benefit of reducing disease susceptibility. Despite its widespread use, the Body Mass Index (BMI) – the standard metric defined by the World Health Organization (WHO) – fails to capture the complexities of obesity, as it overlooks essential body-type variations. Furthermore, nutritional needs differ markedly across regions and body types, underscoring the necessity for a more nuanced approach to obesity assessment. Traditional anthropometric measurements, while effective, are often impractical due to the requirement for trained professionals to perform them accurately. In response to this challenge, innovative research utilizing 3D scanning technology is gaining momentum as a less-invasive and more accessible alternative. Unlike Computed Tomography (CT) or Dual-energy X-ray absorptiometry (DXA)—considered the gold standard for measuring body fat percentage (bf%)—3D scanners eliminate the risks associated with radiation exposure during frequent assessments. Moreover, evaluating health risks demands a multifaceted approach rather than relying solely on a singular measure. In this study, we collected paired data from 3D body scans and DXA for a Korean population, providing a more comprehensive understanding of obesity and paving the way for improved health management strategies. This pioneering research has the potential to transform how we assess and respond to obesity, ultimately leading to healthier outcomes for individuals and communities alike. #BigData #Analytics #DataScience #AI #MachineLearning #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #GoLang #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #100DaysofCode References Jeon, S., Kim, M., Yoon, J., & et al. (2023). Machine learning-based obesity classification considering 3D body scanner measurements. Scientific Reports, 13, 3299. Retrieved February 27, 2025, from doi.org/10.1038/s41598-023-3…
→ View original post on X — @gp_pulipaka, 2026-04-14 04:57 UTC
-

The Future of Data Science and Parallel Computing
By
–
The Future of #DataScience and #ParallelComputing! #BigData #Analytics #AI #MachineLearning #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #ReactJS #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #100DaysofCode geni.us/Future-of–DSci
→ View original post on X — @gp_pulipaka, 2026-04-14 04:57 UTC
-
GAIA: Revolutionary LLM Benchmark for Advanced AI Evaluation
By
–
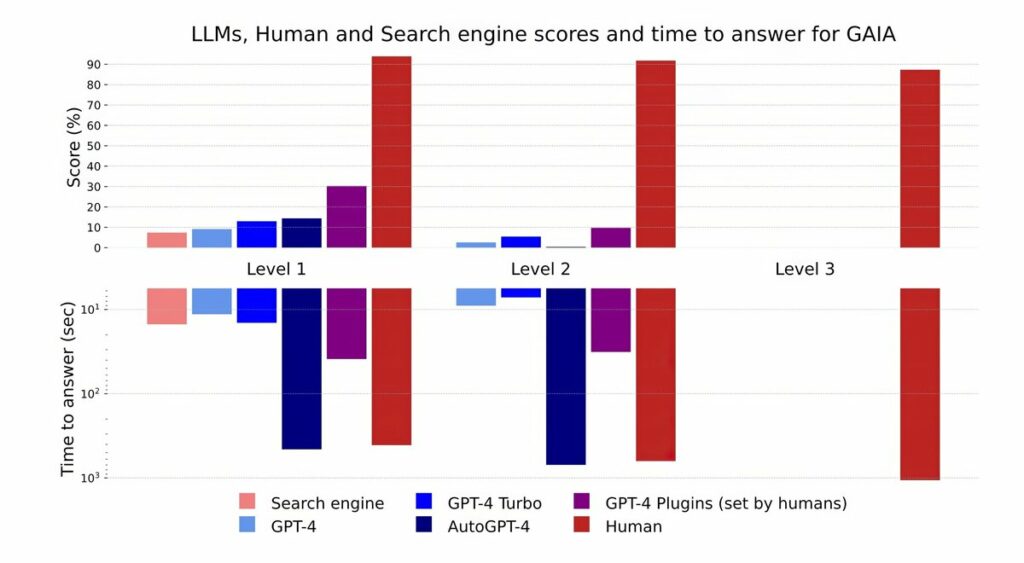
GAIA: An LLM Benchmark. Large Language Models (LLMs) herald a new era for artificial general intelligence general-purpose systems, showcasing remarkable fluency, extensive knowledge, and a notable alignment with human preferences. These advanced models can be augmented with powerful tools like Hyperbrowser, web browsers and code interpreters, operating effectively in zero or few-shot scenarios. Despite these advancements, evaluating their performance remains a formidable challenge. As LLMs continue to evolve, they are rapidly surpassing traditional AI benchmarks at an unprecedented pace. In pursuit of more demanding evaluations, the prevailing trend is toward identifying tasks that not only pose significant challenges for humans but also stretch the capabilities of LLMs. That includes complex educational assessments in fields such as STEM and Law, or even ambitious endeavors like crafting a coherent book. However, it’s crucial to recognize that tasks difficult for humans may not equate to similar challenges for these cutting-edge systems. For instance, benchmarks like MMLU and GSM are nearing resolution, likely due to the rapid advancements in LLM technology coupled with potential data contamination impacts. Moreover, open-ended generation necessitates a paradigm shift in evaluation methods, often relying on human or model-based assessments. As task complexity escalates—evident in longer outputs or specialized skills—the feasibility of human evaluation diminishes. How can we assess a book generated by AI or evaluate solutions to intricate math problems that are beyond the grasp of most experts? Conversely, model-based evaluations are inherently limited; they depend on prior models that may not adequately assess new state-of-the-art models and can introduce subtle biases, such as favoring the initial choice presented. In summary, as we advance into uncharted territories of AI capabilities, it is imperative to innovate our assessment frameworks to ensure they accurately reflect the profound potential of these transformative technology. That's where GAIA reigns. #BigData #Analytics #DataScience #AI #MachineLearning #NLProc #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #GoLang #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #100DaysofCode References Mialon, G., Fourrier, C., Swift, C., Wolf, T., LeCun, Y., & Scialom, T. (2023, November 21). GAIA: A benchmark for General AI Assistants. arXiv. doi.org/10.48550/arXiv.2311.…
→ View original post on X — @gp_pulipaka, 2026-04-14 04:57 UTC