
Our experiment shows that through a simple strategy – having humans chat with models while completing a task – we can help humans perform better at these tasks. This is very encouraging, albeit preliminary!
PROMPT ENGINEERING
-
Leveraging Model Capabilities While Maintaining Supervisory Control
By
–
This is tricky: To do this, we’ll need ways for the human who’s supervising the model to use any relevant knowledge or skills that the model already has, even though they can’t trust the model to be reliably helpful.
-

Cohere NLP JumpStart Webinar with TechCrunch and Google Cloud
By
–
Cohere is helping developers and startups build meaningful apps with language AI. Join us for an #NLPJumpStart session with Kemi Tijani, who will host the @TechCrunch webinar available on November 10, 2022, in partnership with @gcloudpartners
. → https://
hubs.li/Q01rFN3w0 -

HOLOSHEET and GPT3 Google Sheet for Deforum Prompts Demo
By
–
@fabianstelzer will be demo’ing HOLOSHEET and a GPT3 powered Google Sheet for Deforum prompts. Check it out on Fabian’s Twitter:
-
Demo Day: GPT-3 Powered Tools and Innovations
By
–
Spend Friday at Demo Day with us, @fabianstelzer
, and Diwank Singh. We’ll be demo’ing GPT3 powered prompt generators on Google Sheets, satirical pitch decks, and more. Join our Discord to be a part of it: -
Prompt Engineering for AI Agents: Step-by-Step Operation Sequencing
By
–
The game is “least to most” — have it write out the most mechanical, reliably performed operations first. Then gradually move up to more interpretive and analytical steps, so it’s never asked to do anything multi-step in its head. The prompt should feel like an income tax form.
-
GPT-3 Tokenization Challenges and Model Limitations
By
–
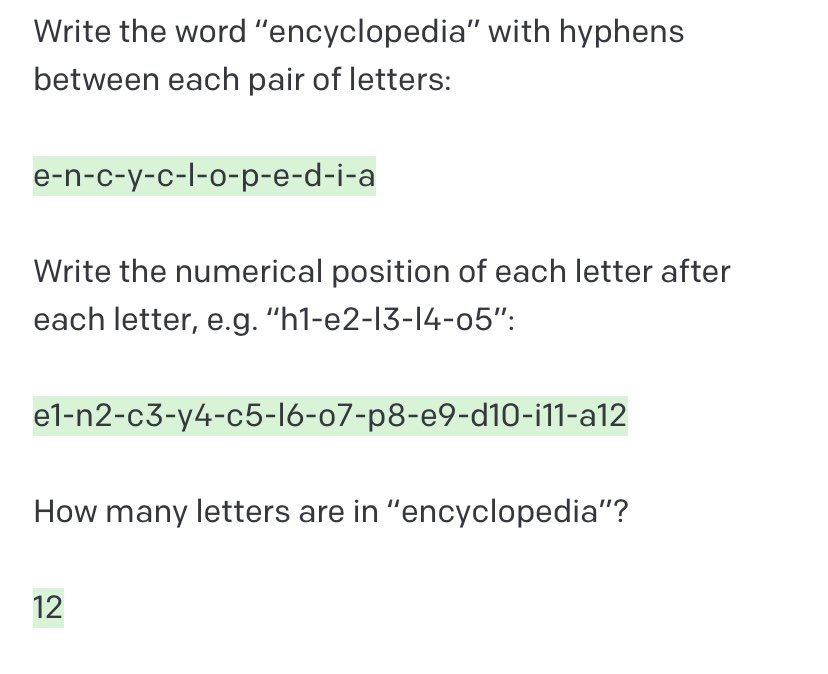
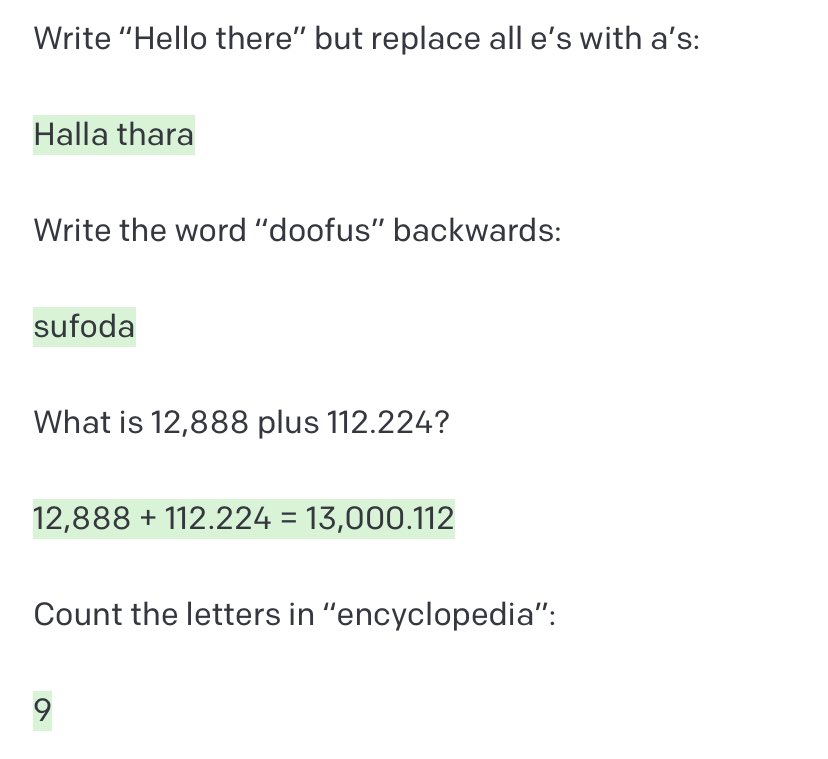
+1 for this approach. GPT-3’s tokenization is a big gotcha. Model doesn’t see text as sequences of characters unless you add spacing/hyphens. It can’t even reliably tell you the last letter of a word without first rewriting it that way. Similar for counting length:
-
K-Shot Learning for Non-RLHF Tuned LLMs
By
–
I’ve never seen it work on anything other than RLHF-tuned GPT-3. I’ve wondered if you could k-shot a non-RLHF model with meta-examples of instruction templates followed by input/output pairs for each, but haven’t tried it.
-
Few-shot Prompt Setup Notes for Scaling Law Experiments
By
–
Some setup notes (cc @EthanJPerez
) – We used the exact 2-shot prompt for Quote Repetition, which is already U-shaped for Gopher/Chinchilla – We used fewer shots for Hindsight – We did few-shot instead of 0-shot for Negation QA – We also showed inverse scaling up to PaLM 62B -
U-shaped Scaling and the Limitations of Inverse Scaling Tasks
By
–
Implications: 1. U-shaped scaling means that inverse scaling may not hold when extrapolated to larger models. 2. The term “inverse scaling task” is underspecified. A task can be inverse scaling for one type of prompting and positive or U-shaped for another type of prompting.