Vector Search, Building An Open-Source Business, and Digital Tech via Language with Bob Van Luijt — James Le https://
bit.ly/3tLT94O #AI #MachineLearning #DeepLearning #LLMs #DataScience
OPEN SOURCE
-
Vector Search, Open-Source Business, and Language-Driven Digital Tech
By
–
-
Specialized AI Models Outperform Large General Models in Cost and Speed
By
–
Our CSO @w4nderlus7 shares how #specializedAI models are faster, more performant, and more cost effective than large general models. For these reasons we expect open-source #LLMs to soon overtake large commercial LLMs for most task-specific applications. https://
pbase.ai/40fMlIL -
Getting Started with Llama-2: Comprehensive Tutorial Guide
By
–
How to get started with Llama-2 ?
Here is a comprehensive tutorial. -
Perplexity Launches pplx-7b and pplx-70b Chat Models
By
–
We’re excited to announce two models we’ve been training in-house: pplx-7b-chat and pplx-70b-chat! Both these models are built on top of open-source LLMs and fine-tuned for chat. They are available as an alpha release, via Labs and pplx-api. Try it out: https://t.co/2yYQB9jln7 pic.twitter.com/pNxHEWsyjp
— Perplexity (@perplexity_ai) 27 octobre 2023We’re excited to announce two models we’ve been training in-house: pplx-7b-chat and pplx-70b-chat! Both these models are built on top of open-source LLMs and fine-tuned for chat. They are available as an alpha release, via Labs and pplx-api. Try it out: http://
labs.pplx.ai -
Free Practical Uses of GPT-4 and Llama-2 Models
By
–
Not how it works or what is the theory behind the models, but what YOU can do with GPT-4 (or open-source alternatives like Llama-2), and all for free. I also introduce a new segment to the newsletter in the second point…
-
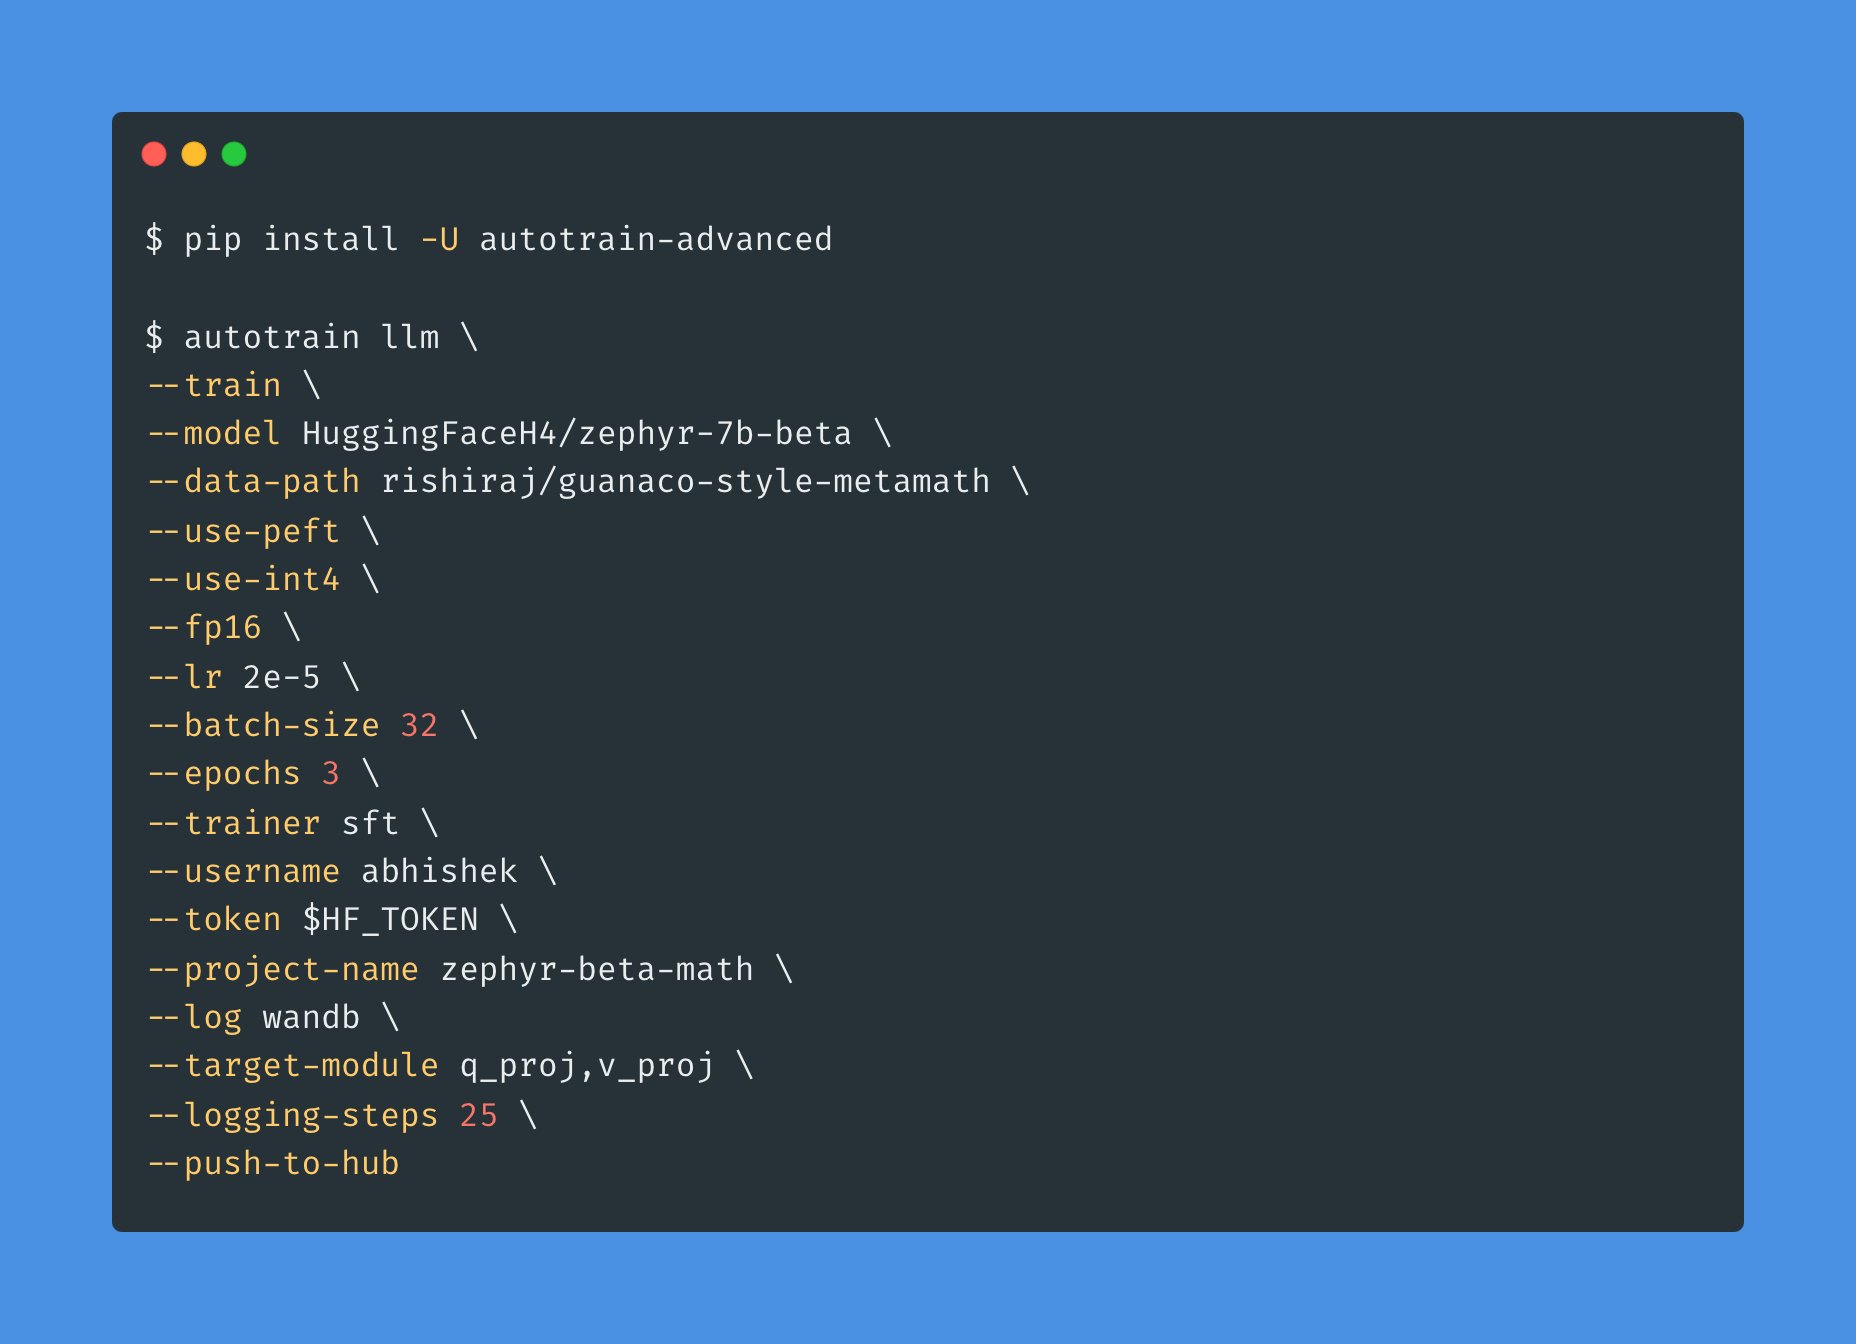
Fine-tuning models with AutoTrain Advanced now available
By
–
And you can already fine tune it using AutoTrain Advanced
-
OSS Startup Featured in ROSS Q3 2023 Index
By
–
Extremely grateful to be featured as top trending OSS startup in ROSS Q3 2023 index by @RunaCapital
-
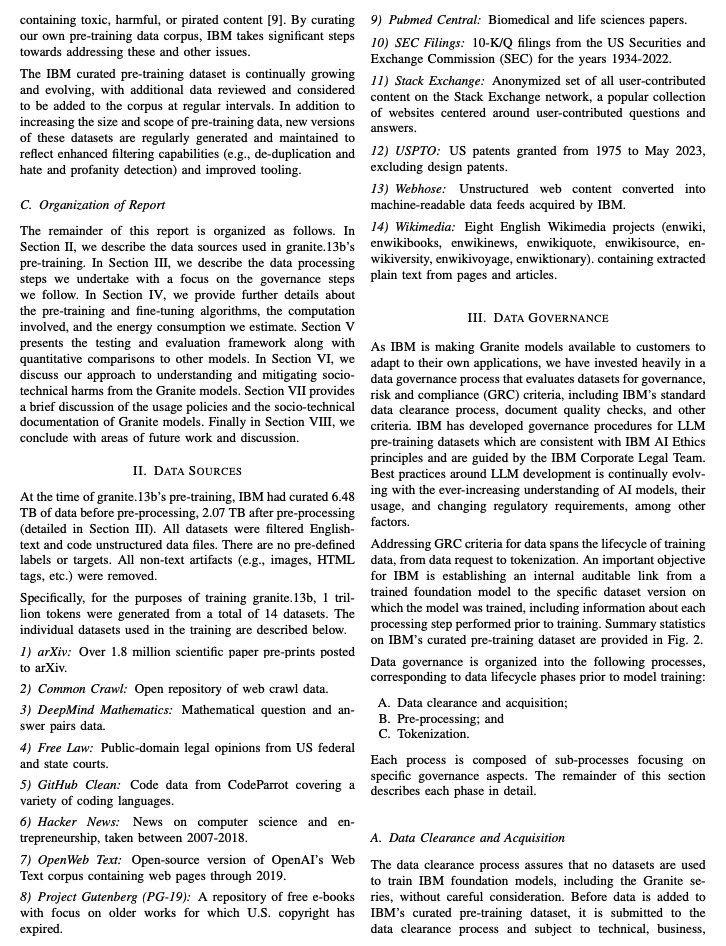
IBM Granite 13B LLM Training Datasets Revealed
By
–
datasets that IBM used to train its granite.13b LLM: Arxiv, Common Crawl, DeepMind Mathematics, Free Law, GitHub Clean, Hacker News, OpenWeb Text, Project Gutenberg, Pubmed Central, SEC filings, Stack Exchange, USPTO, Webhose, Wikimedia https://
ibm.com/downloads/cas/
X9W4O6BM
… -
Training State-of-the-Art LLM with AutoTrain Advanced
By
–
Training state of the art LLM model with experiment tracking using weights & biases without writing a single line of code with AutoTrain Advanced
-
Contribute to Open Source: Fix Issues or Improve Documentation
By
–
You go to an open source github page, and either find an issue to fix, or find something not well documented and document it, and do it!