
MIT researchers discovered a phenomenon called "context pollution" where llms get WORSE by reading their own prior responses errors, hallucinations, and stylistic artifacts from earlier turns propagate forward because the model treats its own output as ground truth and removing
OPEN SOURCE
-
Qwen’s New Models Defy Expectations
By
–
Qwen just dropped 4 new models and the math doesn’t make sense.
— God of Prompt (@godofprompt) 3 mars 2026
> 4B nearly matches their previous 80B A3B
> 9B rivals GPT OSS 120B at 13x smaller
> 0.8B and 2B run on your phone
All free, offline, and open source
Let that sink in. https://t.co/1rqKBiiCgR pic.twitter.com/0pCYM8tRTjQwen just dropped 4 new models and the math doesn’t make sense. > 4B nearly matches their previous 80B A3B
> 9B rivals GPT OSS 120B at 13x smaller
> 0.8B and 2B run on your phone All free, offline, and open source Let that sink in. -

Qwen Drops 4 Small Multimodal Models
By
–
BREAKING: Qwen just mass-dropped 4 small models and nobody’s freaking out enough. Qwen3.5-0.8B, 2B, 4B, and 9B. All native multimodal. All built on the same foundation as their flagship. The 0.8B runs on your phone. The 9B is closing the gap with models 10x its size.
This is -
Context engineering is the new bottleneck
By
–
the broader observation matters more than this specific paper. context engineering is quietly becoming the real bottleneck. not model capability, not training data, not inference cost. the unglamorous plumbing of what information reaches the model, when, and how. Anthropic
-
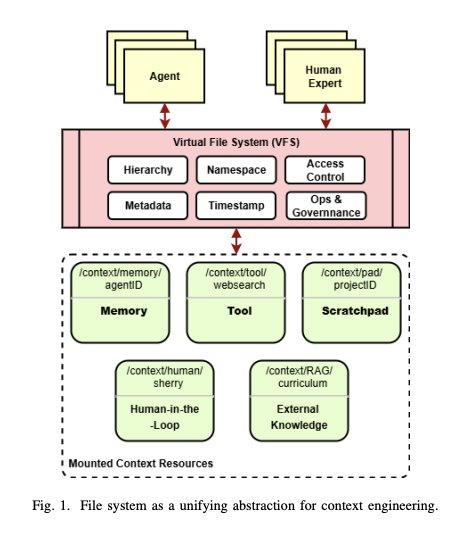
Agent frameworks’ context handling flaws
By
–
the problem is real and underappreciated. right now, most agent frameworks handle context like this: load memory at session start. stuff it into the prompt. when the window fills, summarize and compress. hope the important parts survive. the paper calls this out directly. once
-

4B model rivals 120B on knowledge, ideal for agentic core
By
–


It's crazy that a 4B model can match GPT-OSS-120B **even on knowledge benchs** like MMLU and GPQA! Knowledge was long a limitation of smol models ; not anymore. This 4B could be a good candidate for the "agentic core" model described by @karpathy
-

LM Studio Model Performance: GPT OSS 120B Impresses
By
–
I’ll believe it when I see it. So far I have not been impressed with any other model in LM studio aside from GPT OSS 120B.
-
QueryWeaver GitHub Project Promotes AI-Related Categories
By
–
QueryWeaver GitHub: (don't forget to star )
-
Open-Source Text-to-SQL Solution Tackles LLM and Schema Issues
By
–
Finally! A Text-to-SQL solution that actually works!
— Akshay 🚀 (@akshay_pachaar) 2 mars 2026
(and it's open-source)
When Text-to-SQL doesn’t work, we often blame the LLM or poor prompt engineering.
But the real issue is usually the schema.
Let me explain:
You ask: “Which publishers have received royalty payments… pic.twitter.com/OCa7S8Z3v0Finally! A Text-to-SQL solution that actually works! (and it's open-source) When Text-to-SQL doesn’t work, we often blame the LLM or poor prompt engineering. But the real issue is usually the schema. Let me explain: You ask: “Which publishers have received royalty payments
-

Alibaba Releases Qwen 3.5 Models
By
–

Alibaba released a new family of Qwen 3.5 models with a "strong multimodal base for lightweight agents." – Qwen3.5-0.8B – Qwen3.5-2B – Qwen3.5-4B – Qwen3.5-9B Small and open-source models have gained significant value since OpenClaw was introduced. Testing time