
Navigation World Models A controllable video generation model that predicts future visual observations for navigation tasks based on past observations and actions. Problem: Visual-motor agents struggle with planning flexible navigation trajectories, especially in dynamic or
MULTIMODAL AI
-

Open-Sora Plan: Open-Source High-Resolution Video Generation
By
–
Open-Sora Plan: Open-Source Large Generation Model An open-source framework for generating high-resolution, long-duration videos from diverse user inputs. Problem: Existing video generation models struggle with high-resolution, long-duration video outputs due to high
-

Latest AI Papers: Navigation Models and Video Generation
By
–
Trending AI papers on alphaXiv this week, featuring an incredible week for the computer vision and multimodal communities – Navigation World Models (discussion with author @_amirbar
)
– Open-Sora Plan: Open-Source Large Generation Model (discussion with author -
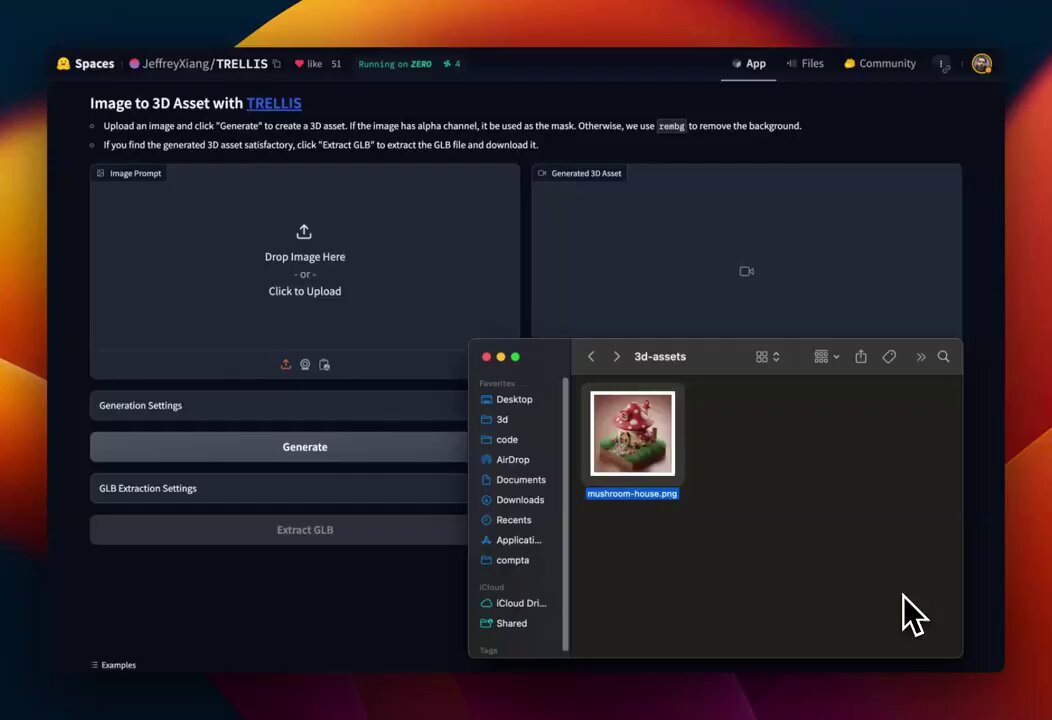
Microsoft TRELLIS 3D Generation Model for Free Asset Creation
By
–
This is RICULOUSLY good, TRELLIS 3D Generation model by Microsoft! 🔥
— Vaibhav (VB) Srivastav (@reach_vb) 8 décembre 2024
Generate high-quality 3D assets from text or image prompts. Supports various formats like Radiance Fields, 3D Gaussians, and meshes
Available for FREE on Hugging Face! pic.twitter.com/V9VHdiAe8lThis is RICULOUSLY good, TRELLIS 3D Generation model by Microsoft! Generate high-quality 3D assets from text or image prompts. Supports various formats like Radiance Fields, 3D Gaussians, and meshes Available for FREE on Hugging Face!
-
Copilot Vision: Multimodal AI Interaction Breakthrough Demonstrated
By
–
Talked to Rowan this week about Copilot Vision and how different it feels to interact with a computer when it can see what you see. Why saying what's "this" or tell me more about "that" is such a leap, plus a sneak peek of what's next: https://
youtu.be/dQP2zLYmCG8?si
=z4HSjEavdXP9x-Kw
… -

WordPress categories focused on AI topics
By
–

For anyone else reading along, tested this idea in a new post:
-
OuteTTS and LLM Direction in Text-to-Speech Technology
By
–
Good call – I quite liked OuteTTS recently, thinking the LLM direction is still a bit slept on.
-
Genie 2: Foundation Model Generates Playable 3D AI Training Environments
By
–
2). Genie 2 – a foundation world model that generates playable 3D environments from single prompt images, enabling endless training scenarios for AI agents with features like physics simulation, character animation, and object interactions…https://t.co/OvKvtfJLVz
— DAIR.AI (@dair_ai) 8 décembre 20242). Genie 2 – a foundation world model that generates playable 3D environments from single prompt images, enabling endless training scenarios for AI agents with features like physics simulation, character animation, and object interactions…
-
Deep Visual Proteomics Enables Breakthrough Treatment for Toxic Epidermal Necrolysis
By
–
Commentary by @NordmannThierry @labs_mann @MundAndreas on Deep Visual Proteomics, the transformative innovation used to identify a successful treatment for patients with toxic epidermal necrolysis