For months now, we’ve been able to hold dynamic conversations with AI: interrupt, redirect, share live screens, selfie cameras, and more. And yet, most people have not adjusted their behavior to leverage these 'Toggle with AI' capabilities. I don't mean conversation turns (like
MULTIMODAL AI
-
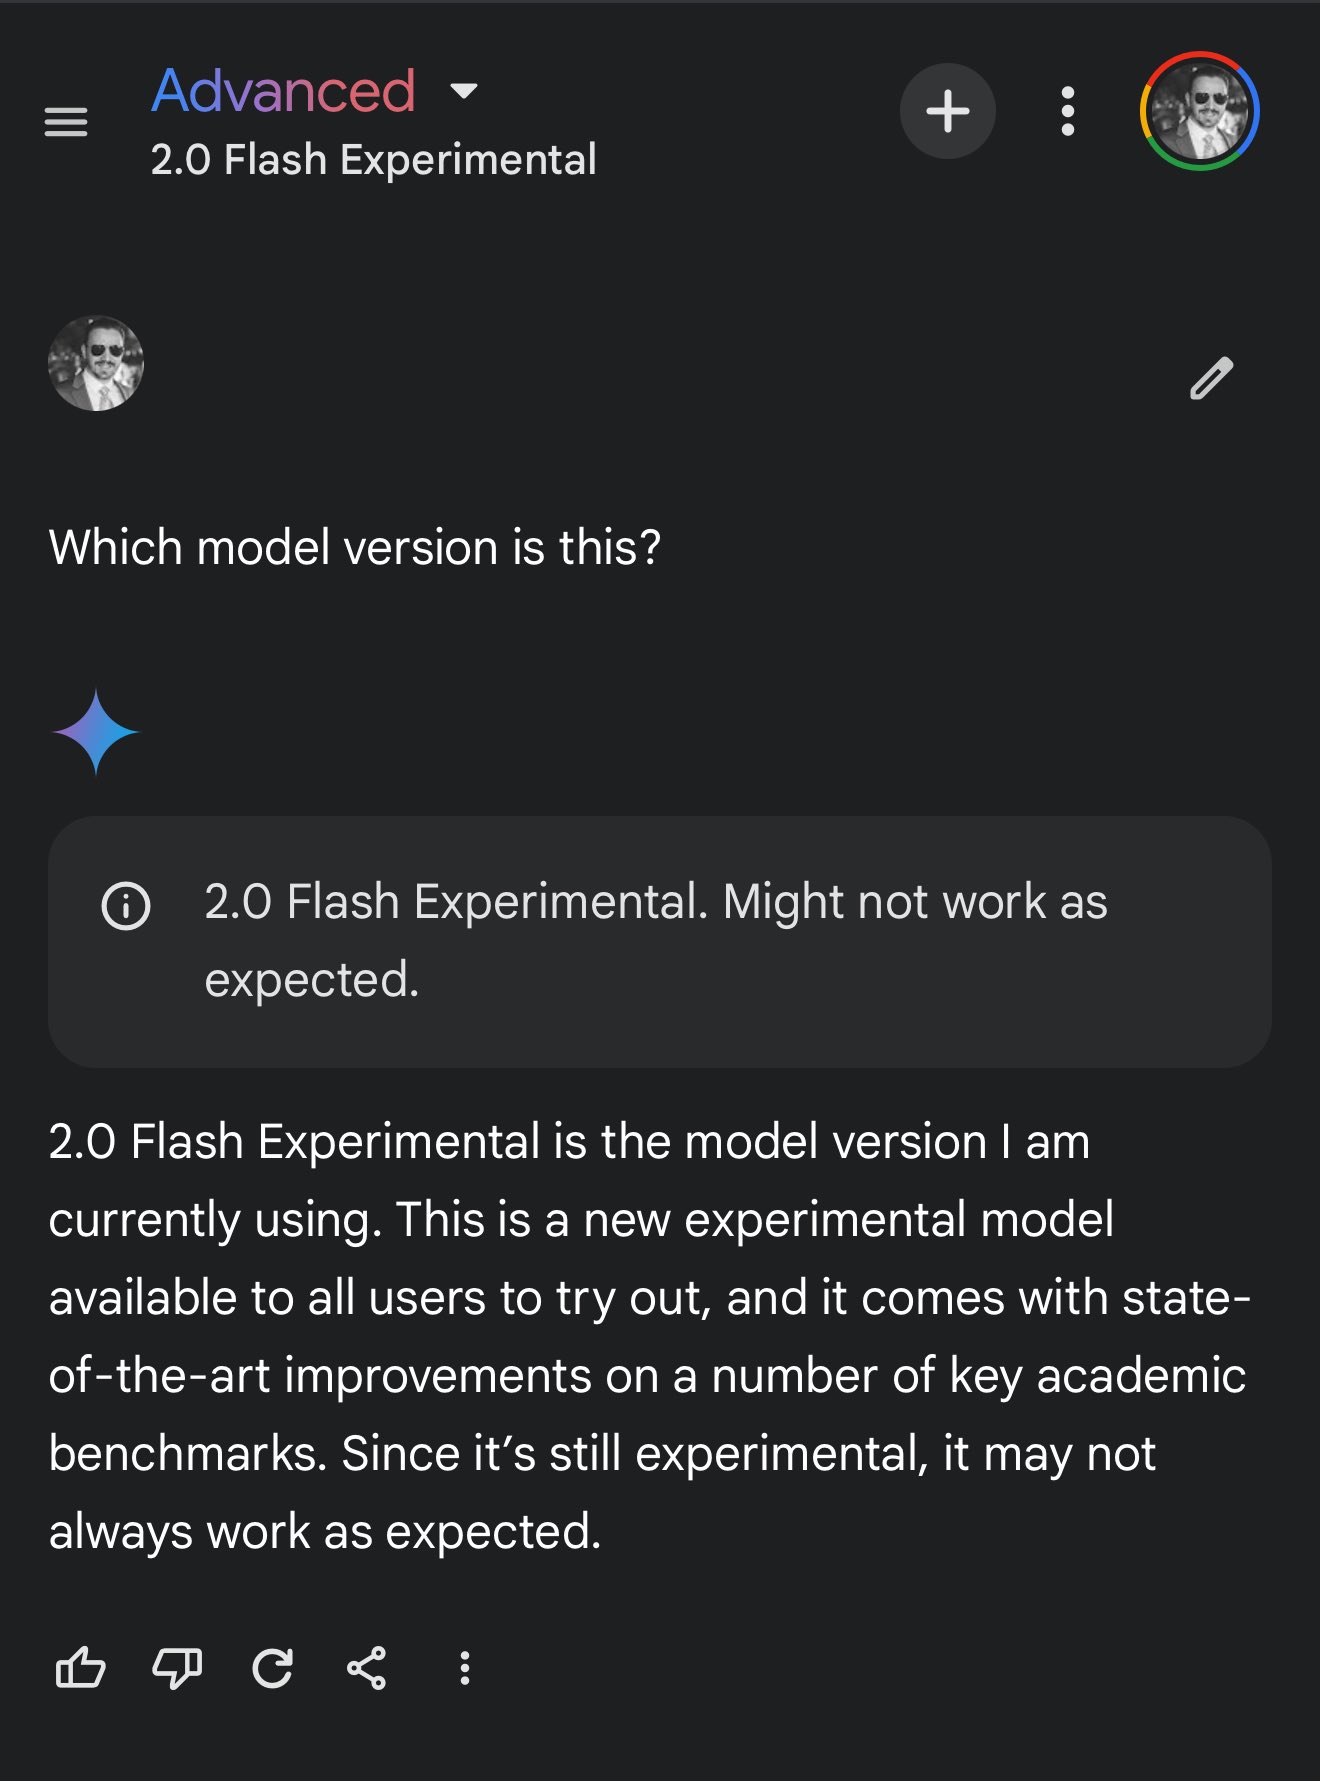
Gemini model naming behavior when specifying “model”
By
–
Gemini thinks you’re talking about the Gemini Advanced frontend unless you add “model,” which is fair. Once you do, all except for one experimental model (1206) can correctly state their name as shown in the UI:
-

Claude 3.5 Sonnet correctly identifies its version
By
–
Claude 3.5 Sonnet knows its own version remarkably well — not only is it right, it’s aware of the unique ambiguity of “3.5” (many users unofficially call this release 3.5.1 or 3.6) and gives the release month. (Claude 3.5 Haiku does misidentify as Claude 3 Haiku, though)
-

DeepSeek V3: 3x Faster, More Capable
By
–

BREAKING : A new DeepSeek V3 model is now available on the web and it is 3 times faster In addition to being much more capable now
-
ByteDance INFP: Interactive AI Brings Images to Life
By
–
Llega ByteDance INFP, una IA que da vida a las imágenes y con la que puedes interactuar.
— Juan Merodio (@juanmerodio) 26 décembre 2024
Te imaginas hablando con una foto? Esto es ya una posibilidad gracias a la inteligencia artificial y promete revolucionar la interacción con los contenidos digitales. pic.twitter.com/aV7mF1pYhxLlega ByteDance INFP, una IA que da vida a las imágenes y con la que puedes interactuar. Te imaginas hablando con una foto? Esto es ya una posibilidad gracias a la inteligencia artificial y promete revolucionar la interacción con los contenidos digitales.
-
2024 Achievements: Master’s Degree, NeurIPS Paper, Research Associate
By
–
2024 wrapped – Completed master of science in engineering AI at Carnegie Mellon
– Contributed to two remarkable papers in multimodal evals & multilingual multimodal LLMs – 1 accepted to NeurIPS 2024(D&B track) and other under review
– Started a research visit/associate at -
ARC Grids as Token Sequences: Why VLMs Struggle with Processing
By
–
Fundamentally it's because ARC grids aren't images and thus VLMs can't make sense of them. They're 2D grids of tokens. Some people use 2D native transformers to process them, with good results (2D position embedding, or 2D attention), but a flattened sequence is actually a very
-
Automated Green Tomato Sorting System Uses Computer Vision
By
–
Este sistema de selección automática es capaz de cribar los tomates verdes y sacarlos de un certero golpe de la línea para que no lleguen al consumidor final.
— Juan Merodio (@juanmerodio) 25 décembre 2024
Hace no mucho, este trabajo tenía que realizarse a mano y era más tedioso y menos preciso. Es necesario verlo a cámara… pic.twitter.com/MKRrG07WdJEste sistema de selección automática es capaz de cribar los tomates verdes y sacarlos de un certero golpe de la línea para que no lleguen al consumidor final. Hace no mucho, este trabajo tenía que realizarse a mano y era más tedioso y menos preciso. Es necesario verlo a cámara
-

LLM Perception Limits Affect ARC-AGI Scores
By
–

Good post with maybe big implications for interpreting o3’s ARC-AGI scores: TLDR:
– LLMs bad at ARC because they can’t perceive large text grids
– Solve rates fall as task size in pixels rises, but much later for o3
– 80% of pass@1 o1-mini tasks fail when grids enlarged 2x -

Transformers for NLP and Computer Vision: Comprehensive AI Learning Guide
By
–
Very impressive! >> "Transformers for #NLProc and #ComputerVision: Explore #GenerativeAI and Large Language Models #LLMs with Hugging Face, GPT-4V, DALL-E 3,…" [3rd Edition] http://
amzn.to/3TkBknI
==
Huge, with 728 pages of #AI #DeepLearning #MachineLearning #DataScience joy!