Gemini 2.5 Pro is incredible at video understanding, try posting a YouTube link into AI studio http://
ai.dev and asking it questions about the video. You will be amazed!
MULTIMODAL AI
-
Gemini 2.5 Pro Excels at Video Understanding with AI Studio
By
–
-

llama.cpp now fully compatible with Vision Language Models
By
–
llama.cpp is now fully compatible with VLMs HUGE kudos to @ngxson from HF and to the @ggml_org team Here are a selection of pre-quantized models, ready to be used, from:
– @GoogleDeepMind Gemma
– @MistralAI Pixtral
– @Alibaba_Qwen VL
– @huggingface SmolVLM Give them a -
Diffusion Policies and Multimodal Image-Based Action Representations
By
–
It would be the same math/algorithms. The paper I shared uses a diffusion policy. Images are actions. Eg if you generate a spectrogram image, you can decode it immediately to speech. Speech acts can do a lot! We tend to imagine 1D embeddings for all modalities, but 2D
-
Gemini 2.5 Pro Video Capabilities: New 66-Token Frame Mode
By
–
Some nice examples of what you can do with Gemini 2.5 Pro's video capabilities in the thread. Account then: there's a new 66-tokens-per-frame mode (instead of 258 tokens) that allows putting more than 6 hours of video (at 1 fps) in the 2M token context.
-

Google Preparing New Image and Video Generation Models for May
By
–


BREAKING : Google is preparing new image and video generation models to be released later in May. – veo-3.0-generate-preview
– imagen-4.0-generate-preview-05-20
– imagen-4.0-ultra-generate-exp-05-20 Plus some model refs -
Tencent Launches HunyuanCustom High-Quality Video Model
By
–
Il y a moins de 24 heures, Tencent a lancé HunyuanCustom !
— VISION IA (@vision_ia) 9 mai 2025
Un nouveau modèle vidéo haute qualité qui permet de générer des vidéos à partir d’images de référence. pic.twitter.com/ctXGlO2YbpIl y a moins de 24 heures, Tencent a lancé HunyuanCustom ! Un nouveau modèle vidéo haute qualité qui permet de générer des vidéos à partir d’images de référence.
-
Gen-4 References Update Enhances Quality and Scene Composition
By
–
We've released an update to Gen-4 References that brings marked improvements to aesthetic quality, scene composition and identity preservation. Alongside this update comes a number of exciting new use cases which we'll be sharing more about in the coming days. Gen-4 References
-
PyMuPdf drops figures; keeping images requires switching to VLM
By
–
Just PyMuPdf! So figures are dropped, a good direction for improvement would be to keep images, but then we'd need to switch to a VLM instead of LLM.
-

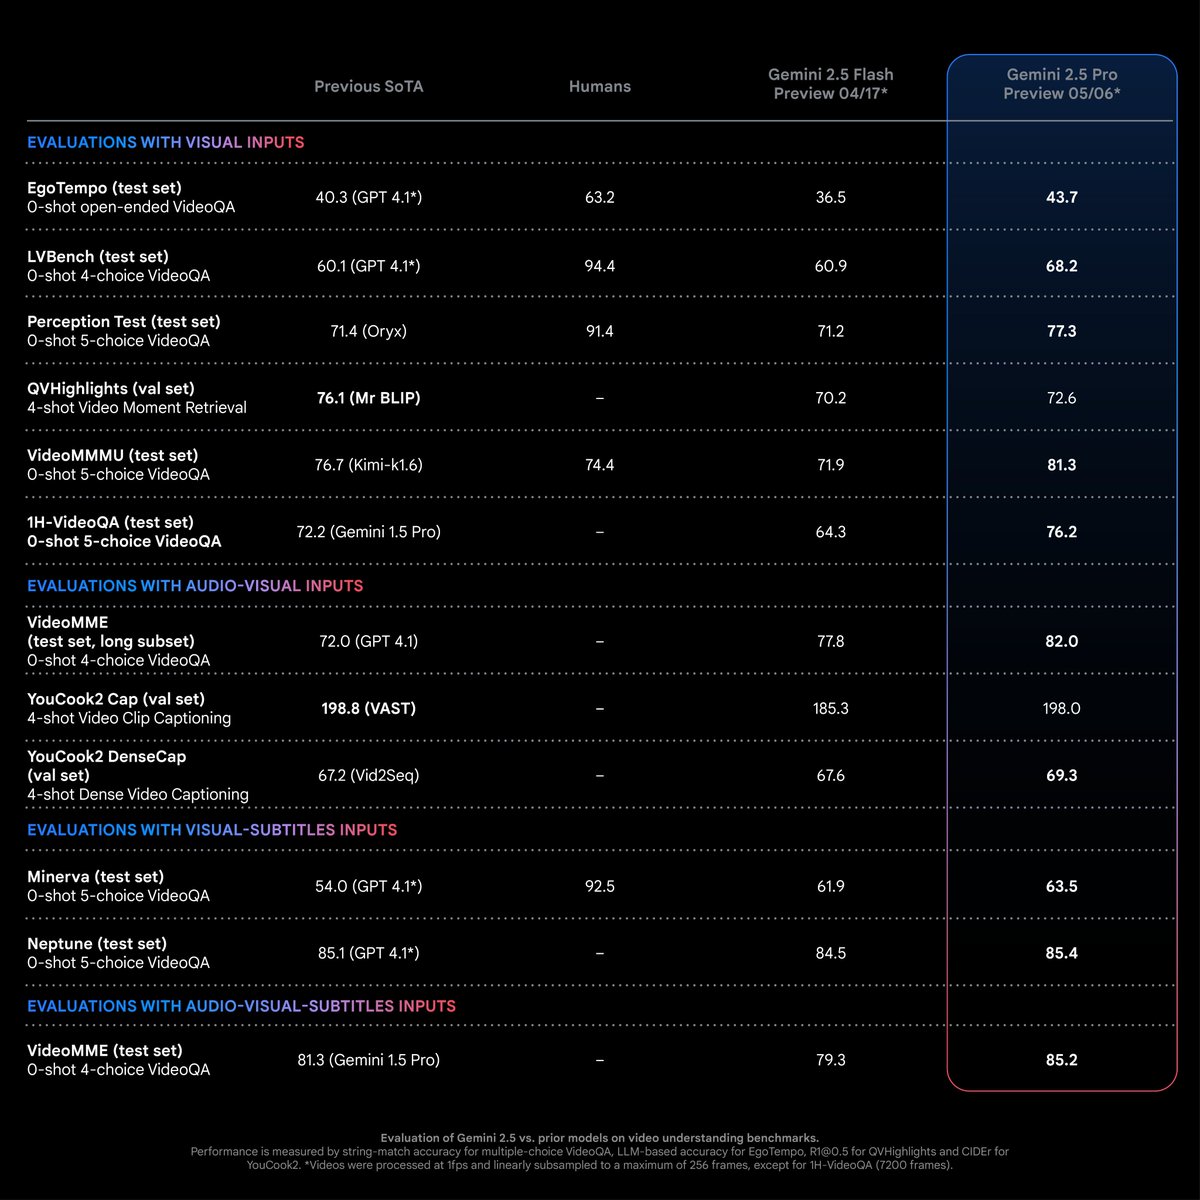
Gemini 2.5 Pro Achieves State-of-the-Art Video Understanding
By
–
Gemini 2.5 Pro (05-06) is SOTA at most video understanding tasks (by a large margin) . Lots of work by the Gemini multimodal team to make this happen, excited to see developers push this capability in new ways. More details below!
-
Multimodal AI team releases YouTube video understanding feature
By
–
Congrats to @AniBaddepudi @AntoineYang2 @MarioLucic_ @jalayrac + the rest of the MM team on this! And in AI Studio and the API, you can paste a YouTube link and test this very quickly : ) Learn more: