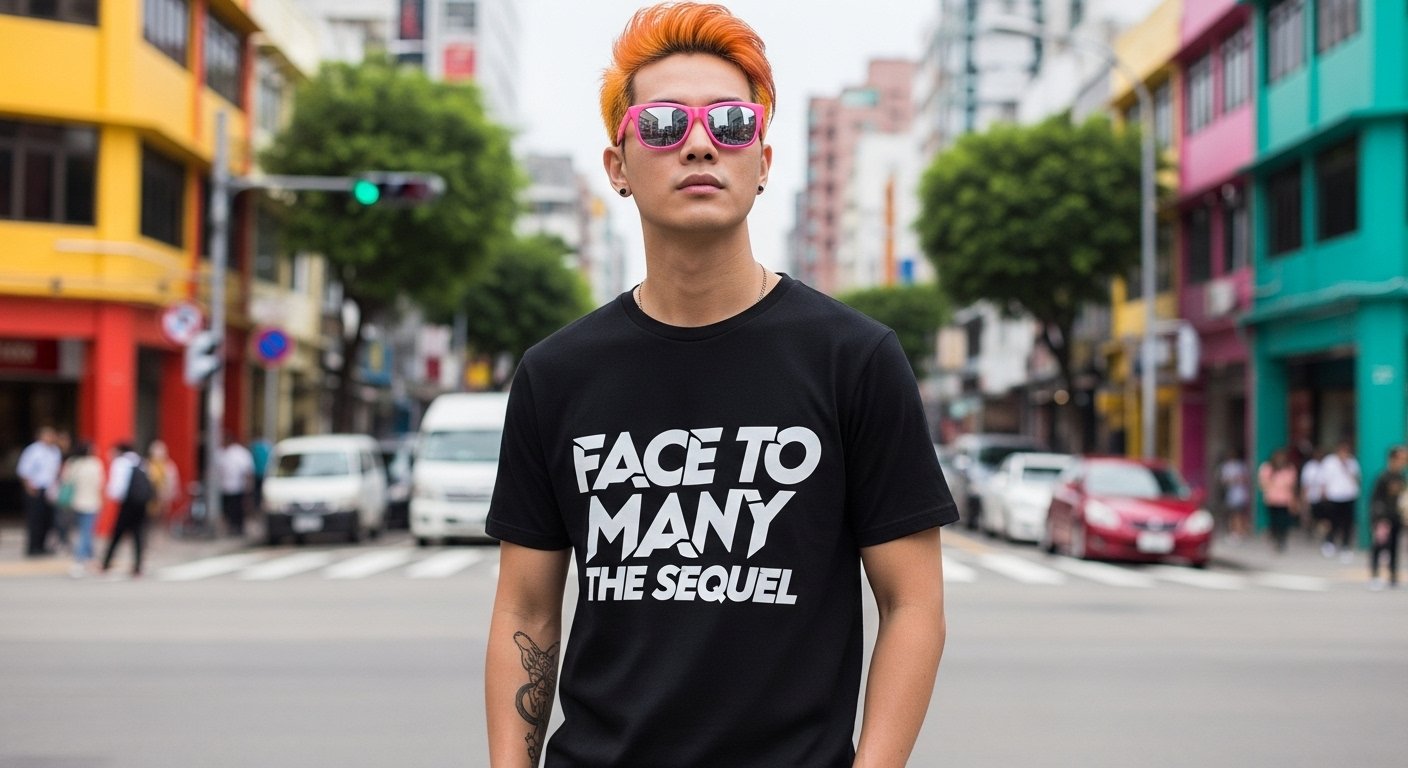
I've added some new styles and personas: – lego minifigure
– action figure toy
– simpsons
– south park
– na'vi https://
replicate.com/flux-kontext-a
pps/face-to-many-kontext
…
MULTIMODAL AI
-
Flux Kontext Adds New AI Face Generation Styles and Personas
By
–
-
Ambient Intelligence Detects Early Cognitive Decline Signs
By
–
Early signs of cognitive decline are often invisible to healthcare providers. @StanfordHAI Faculty Affiliate @eadeli
's research offers a solution using ambient intelligence, enabling timely interventions. https://
stanford.io/43sJI9Y -

Face-to-Many Flux App: AI-Powered Creative Face Transformation Tool
By
–
I made a thing https://
replicate.com/flux-kontext-a
pps/face-to-many-kontext
… -
Gemini 2.5 Pro Preview Evals Released
By
–
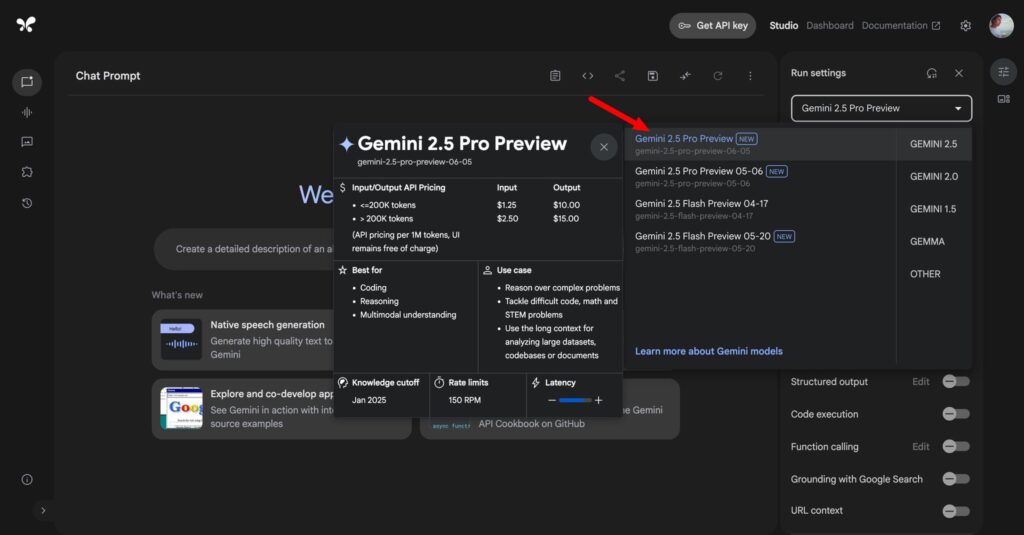
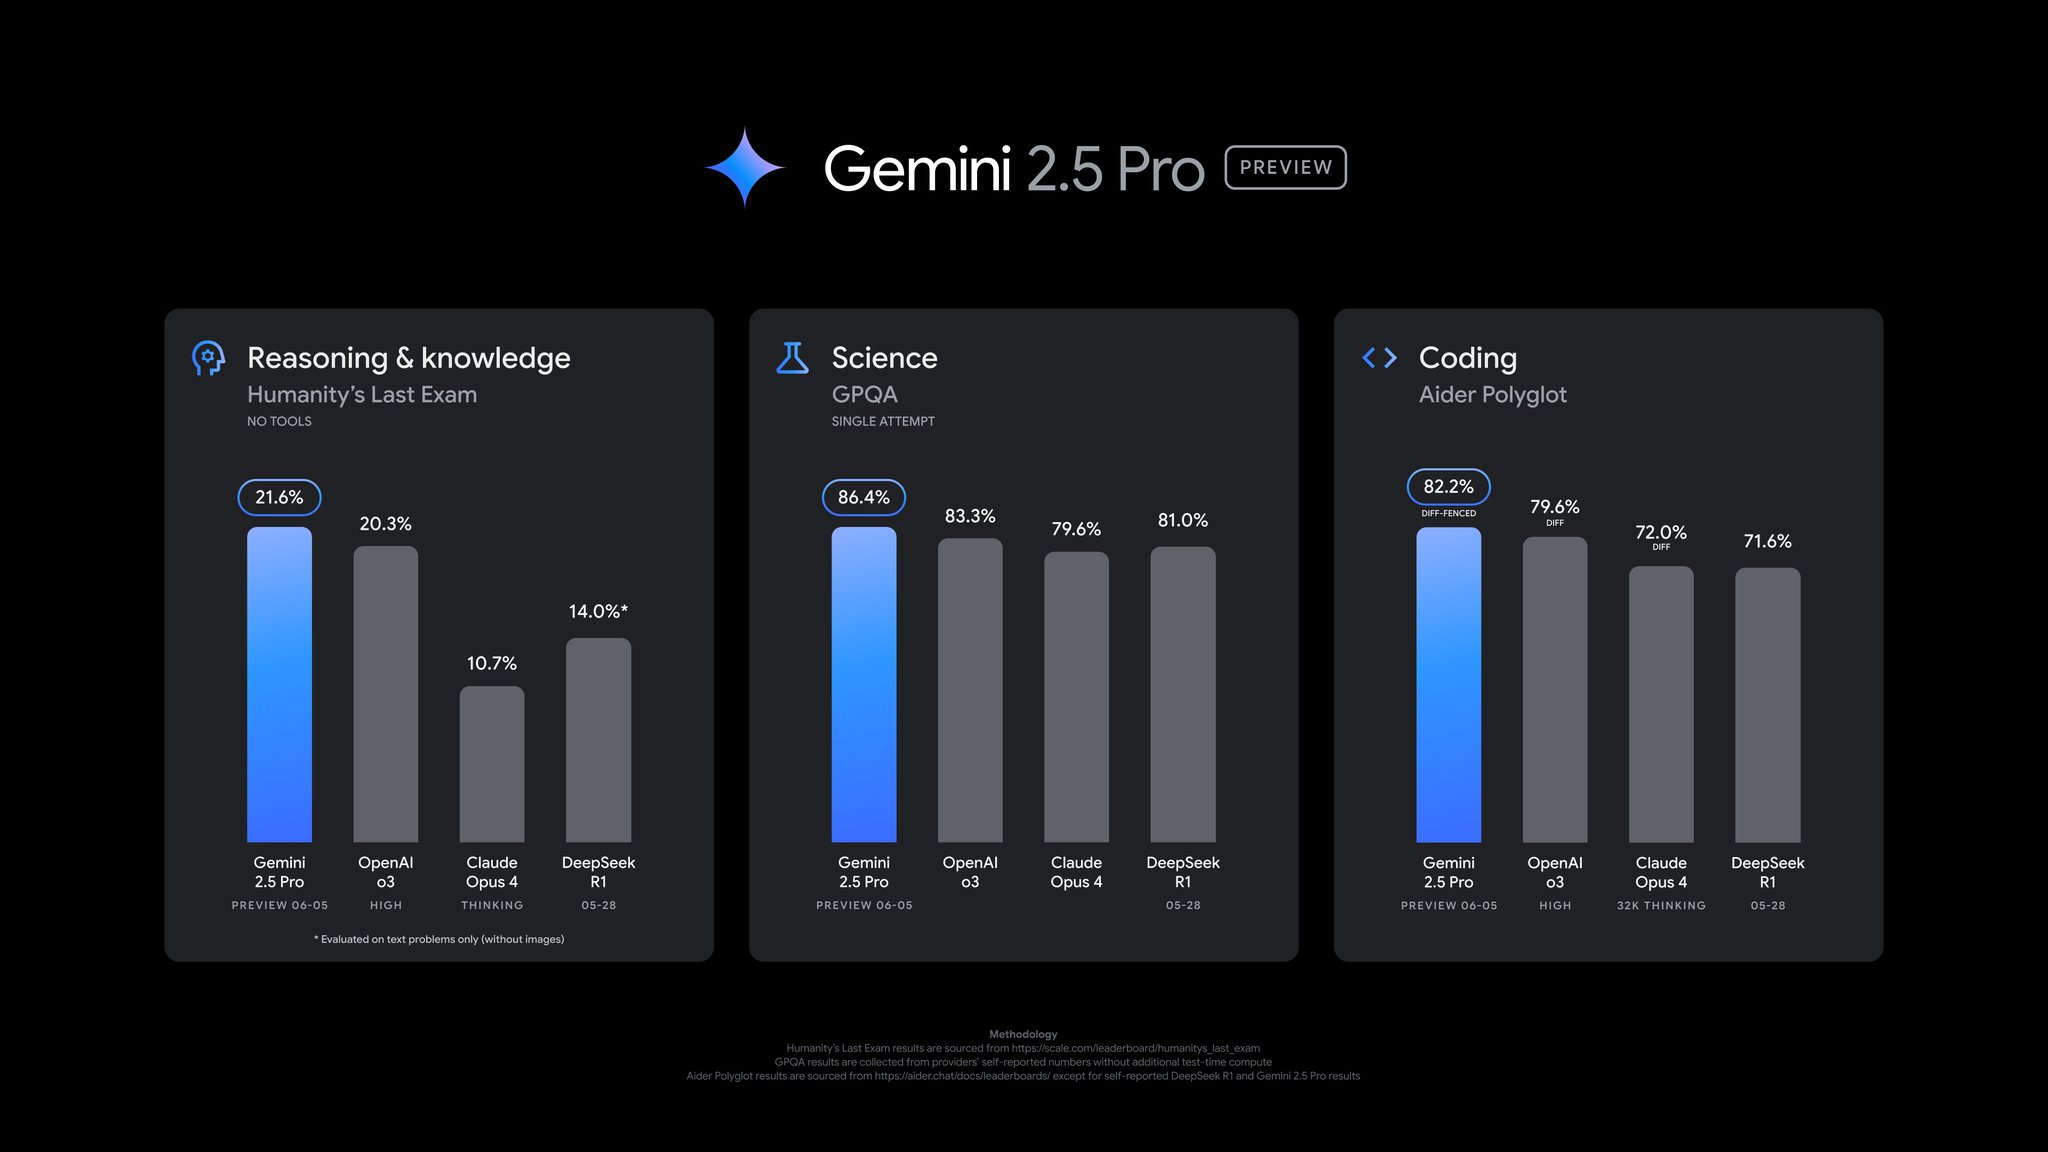
The latest evals for Gemini 2.5 Pro Preview! It also doesn't seem to be a "kingfall" model that was spotted yesterday, but rather a gradual update to a regular 2.5 Pro.
-
Future of Education Beyond Podcasts: Personalized Learning Modalities
By
–
So does this mean the future of edu (besides AP Gov…) is all personalized podcasts, all the time? No. Some people will want visuals or aren’t auditory learners. Some people are faster readers than they are listeners and will always go for the time-saving option.
-
Personalized AI Podcasts Boost Student Comprehension in Education
By
–
For philosophy and psych, the group that got personalized podcasts saw it pay off – they scored higher on comprehension quizzes than students who learned from either the non-personalized podcasts or the textbook.
-
AI-Generated Podcasts Beat Textbooks for Student Learning
By
–
Researchers took 180 US college students + divided them up:
– 60 read a textbook chapter (on philosophy, psych, or gov)
– 60 listened to an AI-gen podcast about the chapter
– 60 listened to a personalized AI-gen podcast based on (self-reported) learning style/interests/etc. -
Touch and Vision Grounding in Artificial Intelligence
By
–
Agreed @tdietterich that touch is part of grounding. It’s a very precise and high fidelity grounding in a highly localized way (typically within square centimeters or at best square feet scale), whereas vision is a much more expansive grounding of the world that can extend very
-
CapSpeech: Guidelines for Expressive Text-to-Speech Systems
By
–
CapSpeech provides guidelines for data construction & model design to develop prompt-guided expressive text-to-speech systems across use cases like cinematic narration, game character voiceovers, conversational chatbots, emotion therapy, & more.
-
CapSpeech: AI Text-to-Speech with Controllable Voice Design
By
–
MIT CSAIL, JHU, & USC researchers have developed "CapSpeech," a text-to-speech framework that generates voices w/controllable timbre & speaking style via text prompts.
— MIT CSAIL (@MIT_CSAIL) 5 juin 2025
Imagine designing a voice just by describing it. CapSpeech can customize age, timbre, accent, emotion, & more:… pic.twitter.com/Dw0i6JUG19MIT CSAIL, JHU, & USC researchers have developed "CapSpeech," a text-to-speech framework that generates voices w/controllable timbre & speaking style via text prompts. Imagine designing a voice just by describing it. CapSpeech can customize age, timbre, accent, emotion, & more: