Great points from @karpathy
, including this one: "Video is the highest bandwidth input to brain"
MULTIMODAL AI
-
Video as Highest Bandwidth Input to AI Brain
By
–
-
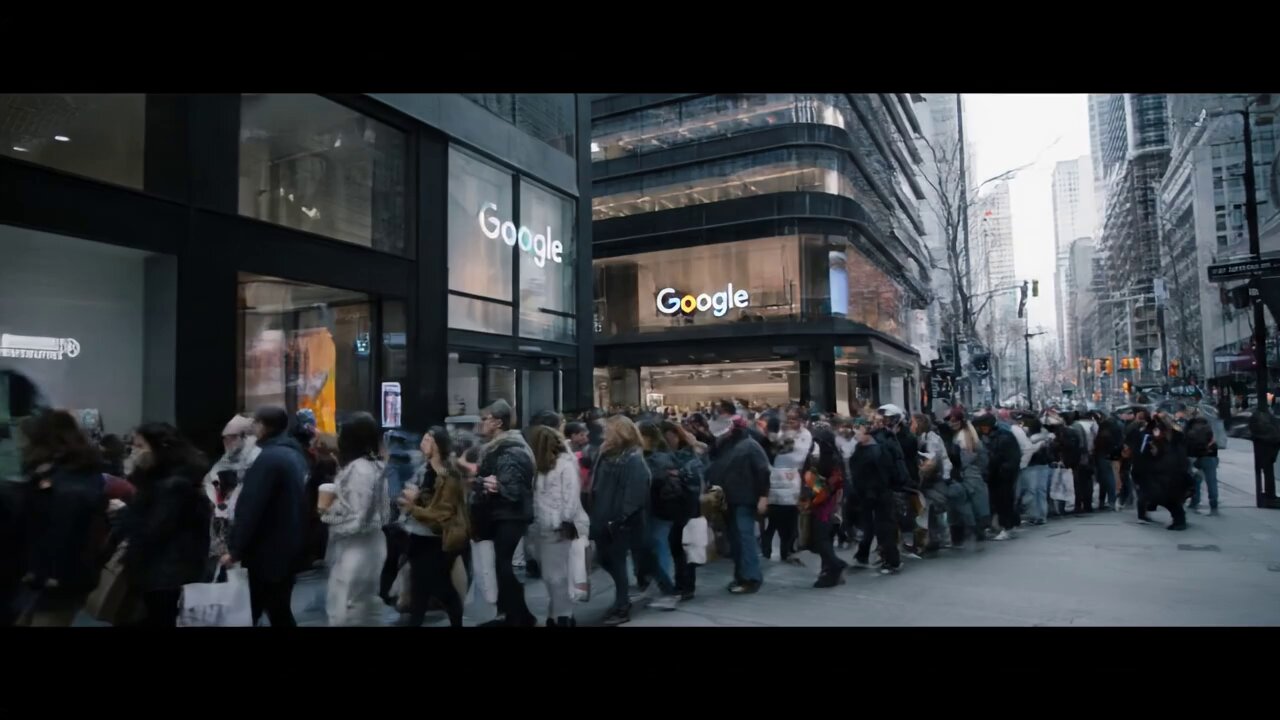
Google Veo 3 Devices Showcase Advanced AI Video Generation
By
–
I love that you can see each device says Veo 3 on it, and that it's a Google store.
— fofr (@fofrAI) 6 juin 2025
That guy @gooserep can prompt. https://t.co/Bjhe050bdgI love that you can see each device says Veo 3 on it, and that it's a Google store. That guy @gooserep can prompt.
-
Google Shares Veo 3 Prompting Guide with Replicate
By
–
Google shared a Veo 3 prompting guide with us. Read about it here: https://
replicate.com/blog/veo-3 -
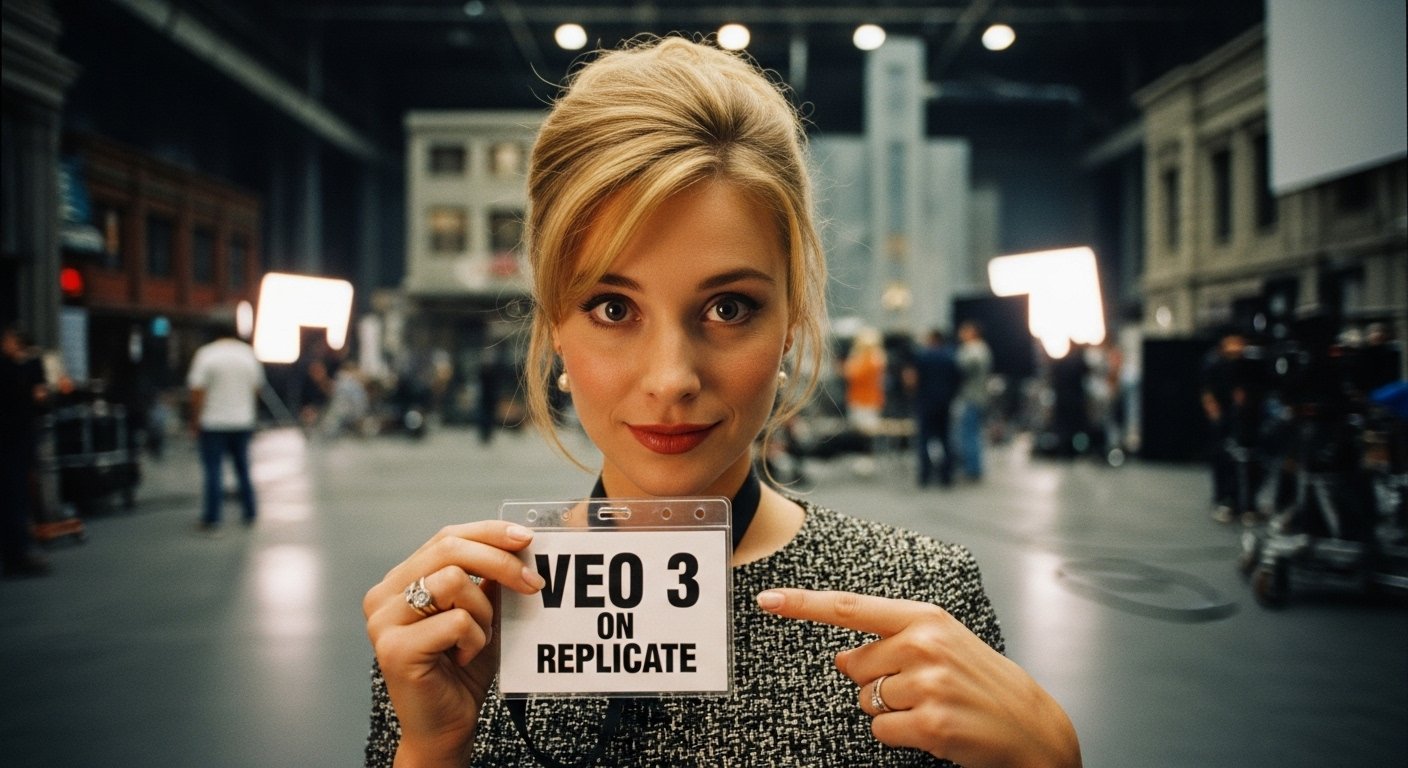
Google’s Veo 3 AI Model Now Available on Replicate
By
–
Veo 3 is live on Replicate https://
replicate.com/google/veo-3 Let's go -
Stable Image Ultra: Image-to-Image Styling in One Minute
By
–
Today, we're breaking down how to use image-to-image with Stable Image Ultra in less than a minute ⏰
— Stability AI (@StabilityAI) 5 juin 2025
This workflow allows you to:
1️⃣ Apply a new style while preserving structure
2️⃣ Maintain a consistent look across a full set of assets
3️⃣ Iterate faster by working from a… pic.twitter.com/PyVImNPAD8Today, we're breaking down how to use image-to-image with Stable Image Ultra in less than a minute This workflow allows you to: Apply a new style while preserving structure Maintain a consistent look across a full set of assets Iterate faster by working from a
-
Google Veo-3 Now Available to Try Out
By
–
Try it out!https://t.co/3loQiuVPsl https://t.co/5CxYC32o2r
— Replicate (@replicate) 5 juin 2025Try it out! http://
replicate.com/google/veo-3 -
Google’s Veo 3 Text-to-Video Model Now Available on Replicate
By
–
Google’s flagship Veo 3 text to video model with audio
— Replicate (@replicate) 5 juin 2025
Now on Replicate: https://t.co/3loQiuWnhT pic.twitter.com/hh67k4HQ0JGoogle’s flagship Veo 3 text to video model with audio Now on Replicate: http://
replicate.com/google/veo-3 -
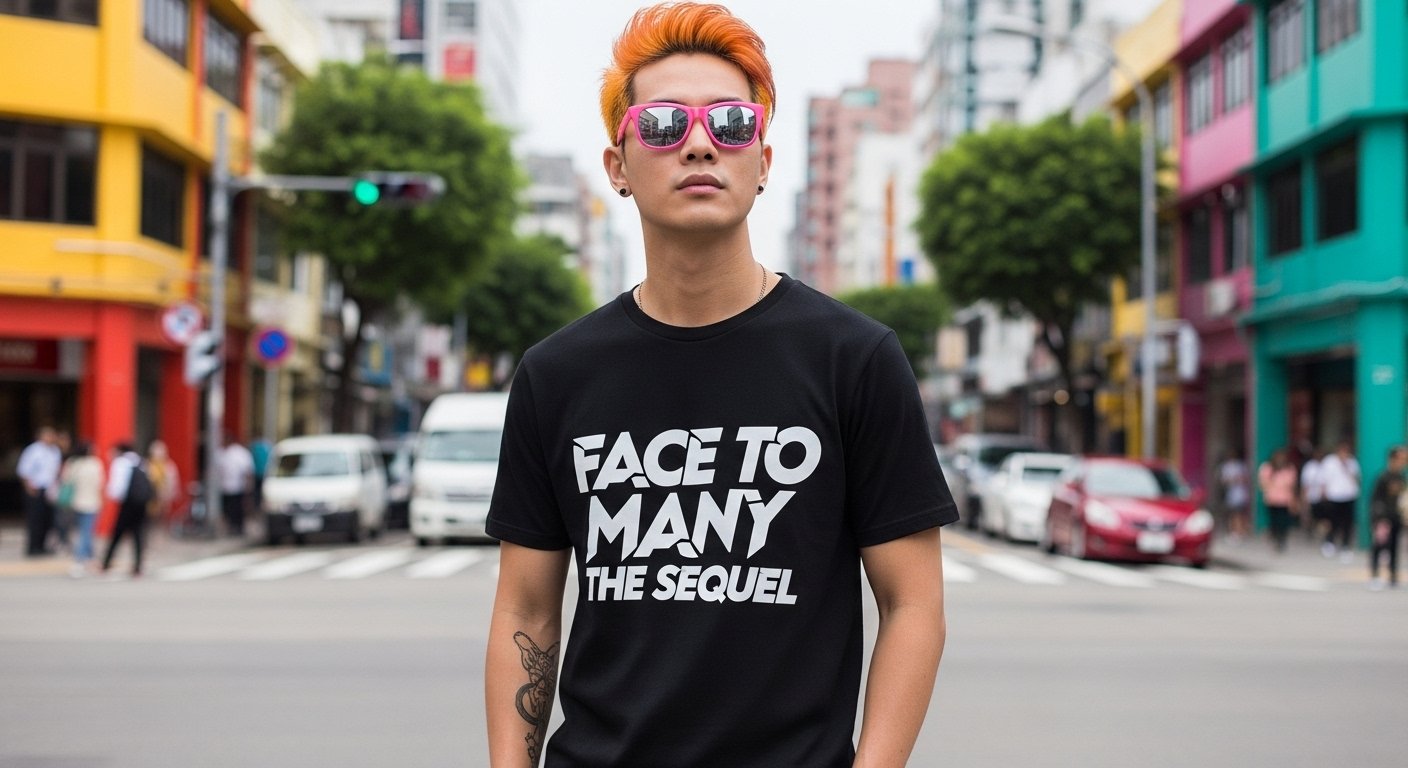
Face-to-Many Evolution: From ControlNet to Prompt-Based Generation
By
–
The first face-to-many (March 2024): – depth controlnet
– instantid for identity (with controlnet and face analysis)
– SDXL loras for each style This face-to-many (June 2025): – prompts -
Tencent Releases Open Source AI Avatar Animation Tool
By
–
Tencent vient de lâcher une nouvelle IA open source.
— VISION IA (@vision_ia) 5 juin 2025
Une seule image + un fichier audio : et votre avatar chante, parle, s’anime… avec émotions, lèvres synchronisées, gestes réalistes.
Extrait de ma dernière vidéo sur les outils IA : https://t.co/QpNiKxISKM pic.twitter.com/qAW9mf6tHfTencent vient de lâcher une nouvelle IA open source. Une seule image + un fichier audio : et votre avatar chante, parle, s’anime… avec émotions, lèvres synchronisées, gestes réalistes. Extrait de ma dernière vidéo sur les outils IA :