Yeah, I had some outputs with a more accurate looking theremin, but they kept grabbing it.
MULTIMODAL AI
-

Google Gemini 2.5 Flash-Lite: Fastest New AI Model Update
By
–
Google just dropped another monster AI update in June — and it’s PACKED! From genome-level breakthroughs to voice-first AI search to generative wallpapers from Jupiter … Here’s what’s new in AI @Google : Gemini 2.5 Flash-Lite: their fastest + most efficient model
-

Multimodal LLMs Fail 3D Puzzles: MARBLE Benchmark
By
–
Multimodal LLMs can write essays.
They can chat, caption, and even summarize papers. But give them a Portal map or a 3D puzzle, they break instantly. Zero percent accuracy. Welcome to the edge of AI reasoning: The MARBLE Benchmark -
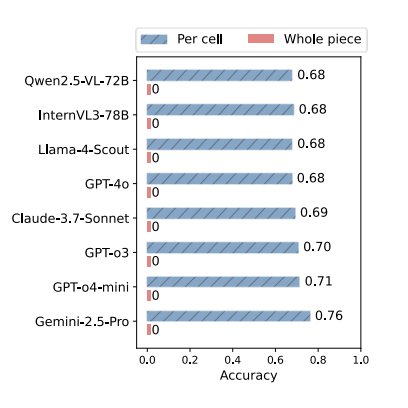
MLLMs fail at simple grid transcription and shape recognition tasks
By
–
Perception is the bottleneck.
MLLMs can’t even transcribe a simple 5×5 grid from an image.
The best models got 0% accuracy on full-shape recognition.
They see… but don’t understand. -
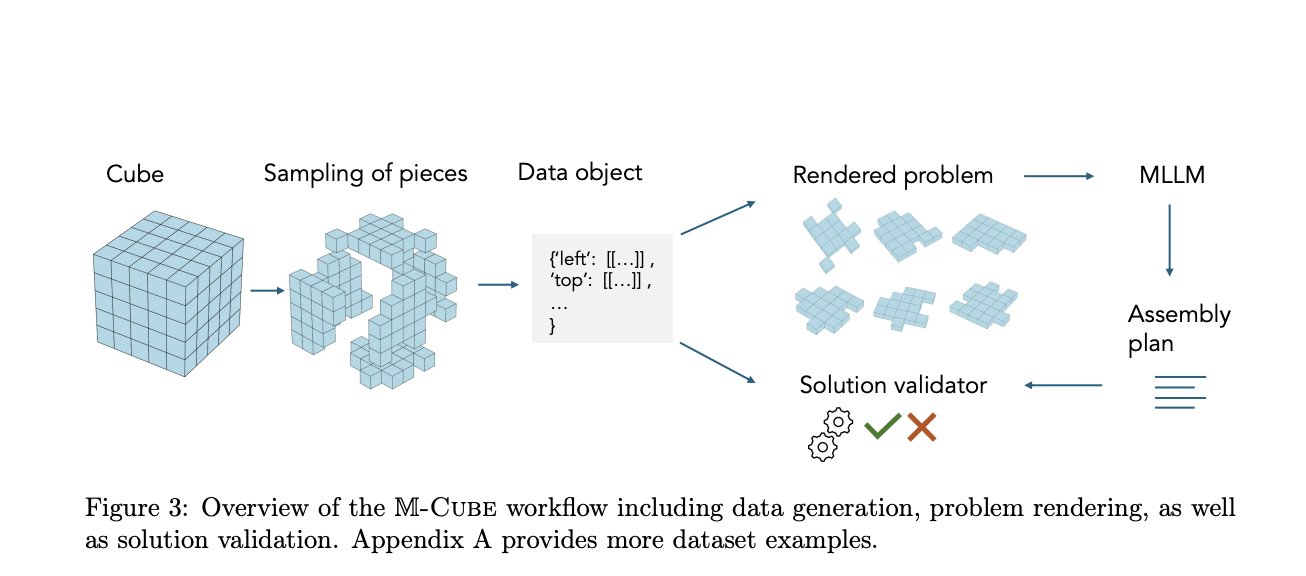
M-Portal and M-Cube: MLLMs fail at visual, planning, spatial logic
By
–
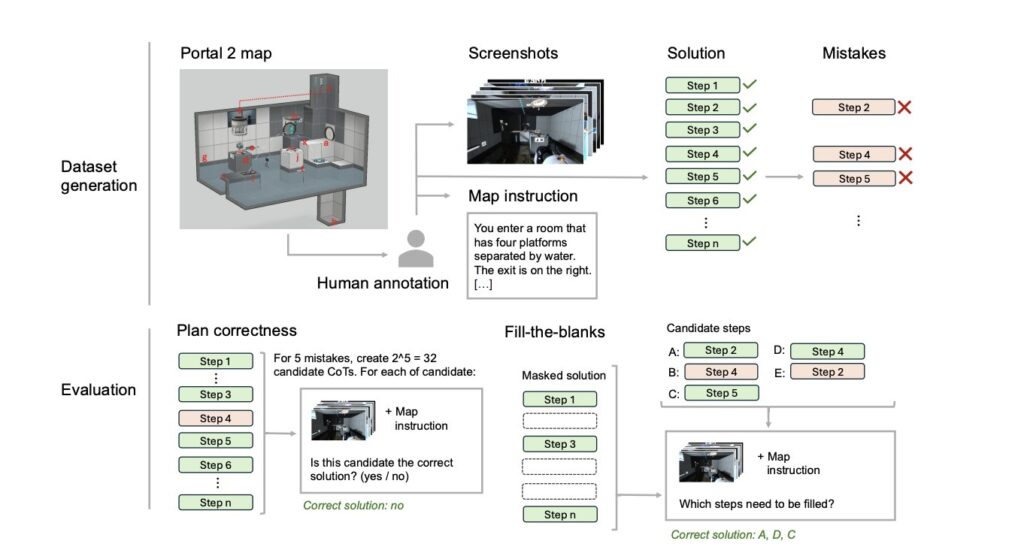
There are two tasks: M-Portal: Reason like a Portal 2 player. M-Cube: Rebuild a 3D object from 2D slices. Both require: Visual perception, Multistep planning, and Spatial logic MLLMs today fail at all three.
-
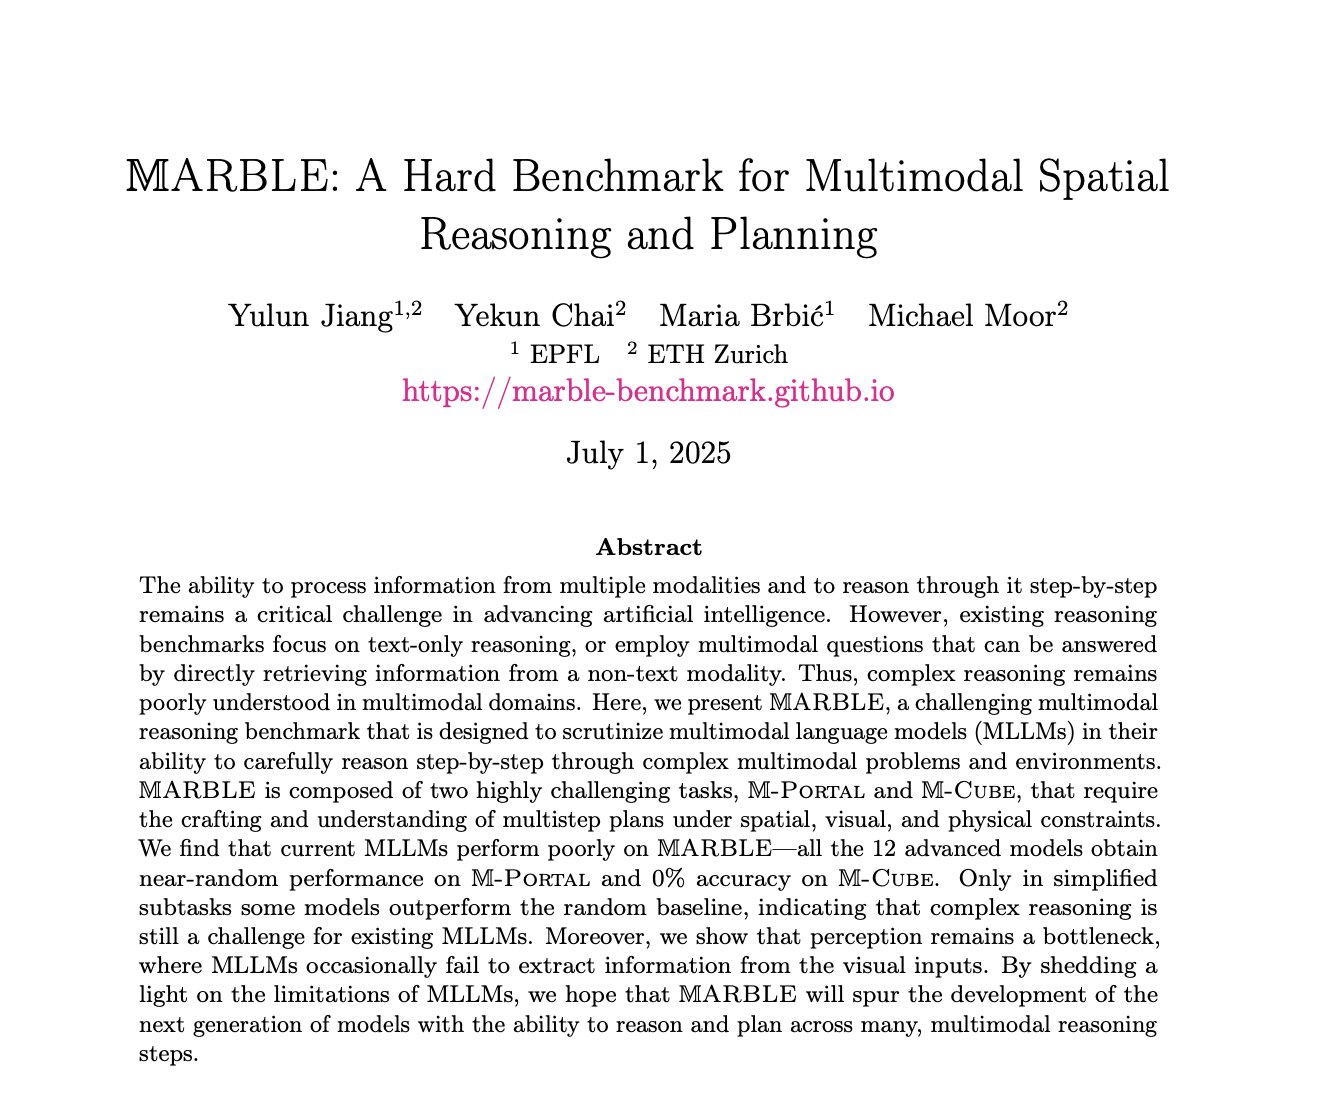
AI Reasoning Limits: MARBLE Benchmark Highlights Multimodal LLM Weaknesses
By
–
Multimodal LLMs can write essays.
They can chat, caption, and even summarize papers. But give them a Portal map or a 3D puzzle, they break instantly. Zero percent accuracy. Welcome to the edge of AI reasoning: The MARBLE Benchmark -
Code Interpreter: Why Neurosymbolic AI Deserves More Attention
By
–
Code Interpreter is neurosymbolic, as @fchollet made clear a year ago. Why aren’t more people talking about that?
-
Veo 3 Impresses with Detailed Hurdy-Gurdy Video Generation
By
–
Veo 3:
— fofr (@fofrAI) 6 juillet 2025
> a man playing a hurdy-gurdy
Very impressed it has handled this so well. pic.twitter.com/J5wABh8n8tVeo 3: > a man playing a hurdy-gurdy Very impressed it has handled this so well.
-
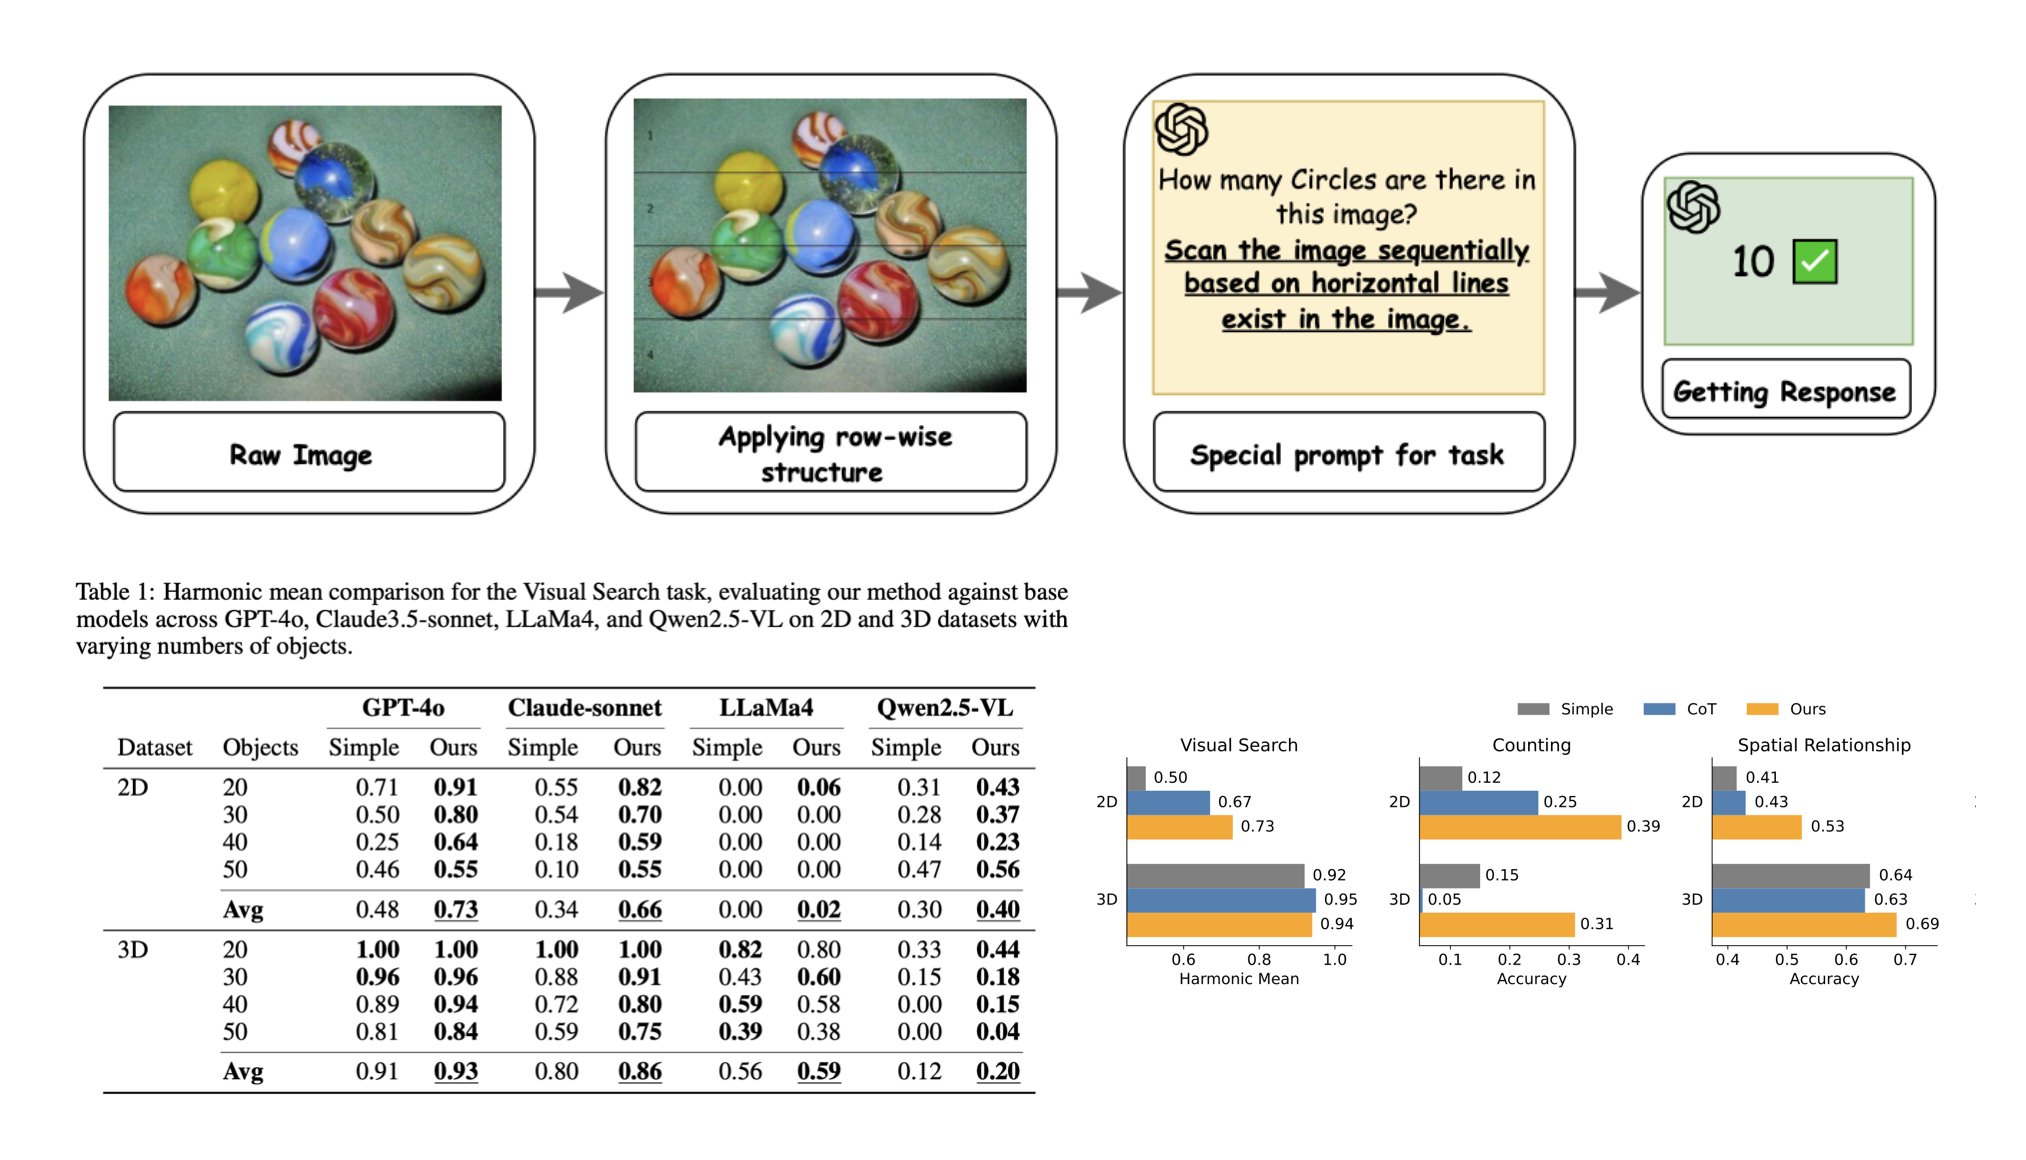
Visual Structures Enhance GPT-4o Feature Binding Reasoning
By
–
9. Visual Structures Help Visual Reasoning This study shows that adding simple spatial structures (like horizontal lines) to images significantly boosts GPT-4o’s visual reasoning by improving feature binding.