
Qwen drops Qwen-Image A new text-to-image model from Alibaba’s AI powerhouse.
MULTIMODAL AI
-
Higgsfield Launches Topaz-Powered Image Upscaling Feature
By
–
3️⃣ Higgsfield adds Upscale
— Futurepedia – Learn to Leverage AI (@futurepedia_io) 13 août 2025
New Topaz-powered feature to supercharge your image resolution. pic.twitter.com/FGHgXSvje7Higgsfield adds Upscale New Topaz-powered feature to supercharge your image resolution.
-

100M+ AI Characters with Unique Personalities
By
–
not just looks.. we've got personalities too (¬‿¬) here are 100M+ characters with peculiar personalities you can talk to http://
c.ai -
Weekly Roundup of Major AI Model Releases and Breakthroughs
By
–
What a crazy week in AI.. – OpenAI's GPT-5 Launch
– Anthropic's Claude Opus 4.1 Release
– Google's Genie 3 World Simulator
– ElevenLabs Music Generation Model
– xAI's Grok Imagine with 'Spicy' Mode
– Alibaba’s Qwen-Image Model
– Tesla AI Breakthroughs for Robotaxi FSD
– -
Genie 3 and Gemini 2.5 Advance Toward AGI with Better Benchmarks
By
–
To reach artificial general intelligence, we’ll need both advanced AI models that can think and understand the world around us and better benchmarks to evaluate their progress.
— Google AI (@GoogleAI) 12 août 2025
Listen in as @demishassabis and @OfficialLoganK chat about how our new world model Genie 3, Gemini 2.5… pic.twitter.com/aYSdmCqzyKTo reach artificial general intelligence, we’ll need both advanced AI models that can think and understand the world around us and better benchmarks to evaluate their progress. Listen in as @demishassabis and @OfficialLoganK chat about how our new world model Genie 3, Gemini 2.5
-

LFM2-VL Models: 1.6B and 450M Vision-Language Released
By
–
We also provide an inference and a fine-tuning Colab notebooks. LFM2-VL-1.6B: https://
huggingface.co/LiquidAI/LFM2-
VL-1.6B
… LFM2-VL-450M: https://
huggingface.co/LiquidAI/LFM2-
VL-450M
… -

Liquid Releases Fast 450M and 1.6B Parameter VLM Models
By
–
Liquid just released two 450M and 1.6B param VLMs! They're super fast and leverage SigLIP2 NaFlex encoders to handle native resolutions without distortion. Available today on @huggingface
! -

CulturalGround Fine-tuning Achieves State-of-the-Art Performance on Cultural Benchmarks
By
–
To demonstrate the effectiveness of CulturalGround, we fine-tune an existing multimodel model Pangea on a subset of the dataset. The resulting model achieves state-of-the-art performance for its model size on multiple cultural benchmarks in PangeaBench and other benchmarks. Below
-
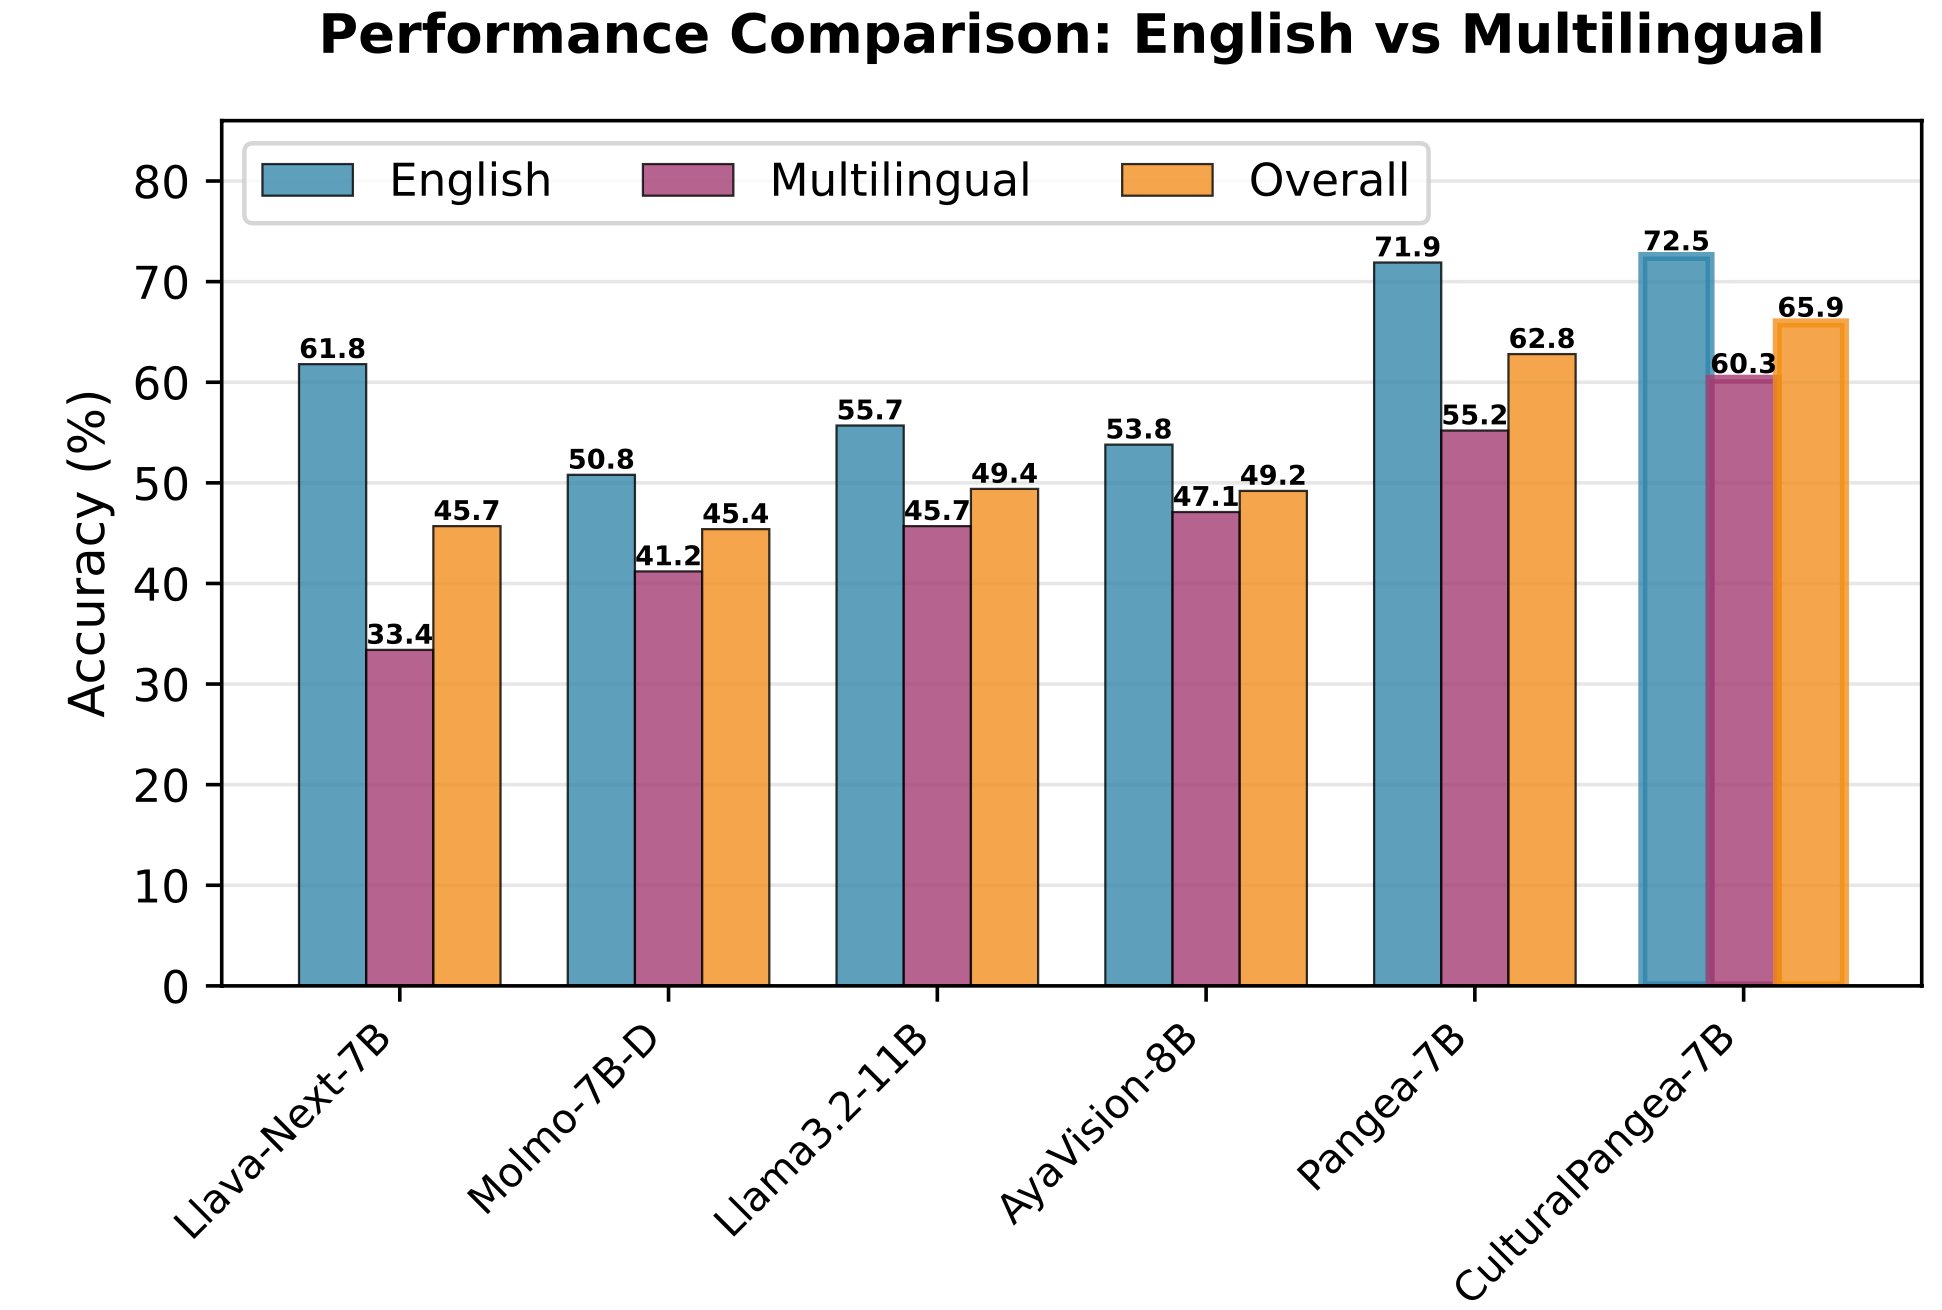
CulturalPangea Excels in Multilingual and English Performance
By
–
CulturalPangea not only achieves good performance on multilingual cultural understanding, but also perform well on English, and overall.
-

CulturalGround: Building Inclusive Multimodal LLMs for Global Contexts
By
–
Current multimodal LLMs excel in English and Western contexts but struggle with cultural knowledge from underrepresented regions and languages. How can we build truly globally inclusive vision-language models? We are introducing CulturalGround, a large-scale dataset with 22M