Last week, we announced Veo 3.1 and a series of new features that give you more creative control over your video generations. Here are a few additional tips to make sure you’re using this new model to the fullest. After reading this thread, you can put your Veo skills to the
MULTIMODAL AI
-

DeepSeek-OCR technical data training approach
By
–
4. Data Engine OCR 1.0 to 2.0 They didn’t just train on text scans. DeepSeek-OCR’s data includes: • 30M+ PDF pages across 100 languages
• 10M natural scene OCR samples
• 10M charts + 5M chemical formulas + 1M geometry problems It’s not just reading it’s parsing scientific -

Technical Overview of DeepSeek-OCR Multi-Resolution Gundam Mode
By
–
3. Multi-Resolution “Gundam” Mode Documents vary invoices ≠ blueprints ≠ newspapers. To handle this, DeepSeek-OCR supports multiple resolution modes: Tiny, Small, Base, Large, and Gundam. Gundam mode combines local tiles + a global view scaling from 512×512 to 1280×1280
-
DeepEncoder: A Technical Overview of the Optical Compressor Architecture
By
–
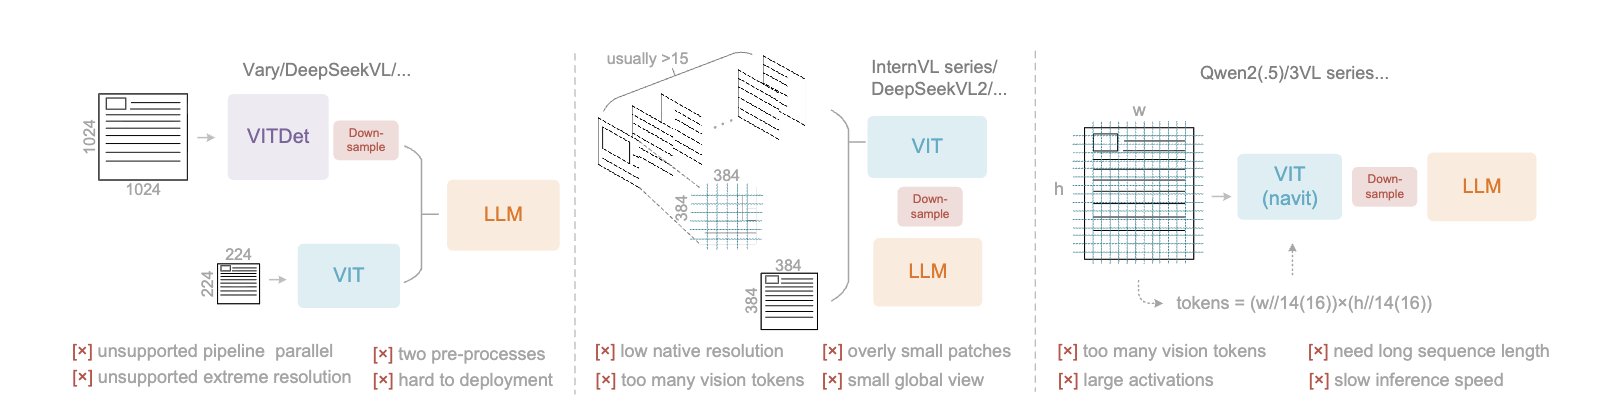
2. DeepEncoder – The Optical Compressor Meet the star: DeepEncoder. It uses two backbones SAM (for perception) and CLIP (for global vision) bridged by a 16× convolutional compressor. This allows it to maintain high-res understanding without exploding activation memory. The
-
Technical Analysis of DeepSeek-OCR Vision-Text Compression
By
–
1. Vision-Text Compression: The Core Idea LLMs struggle with long documents because token usage scales quadratically with length. DeepSeek-OCR flips that: instead of reading text, it encodes full documents as vision tokens each token representing a compressed piece of visual
-
DeepSeek Introduces High-Efficiency OCR System Using Vision Tokens
By
–
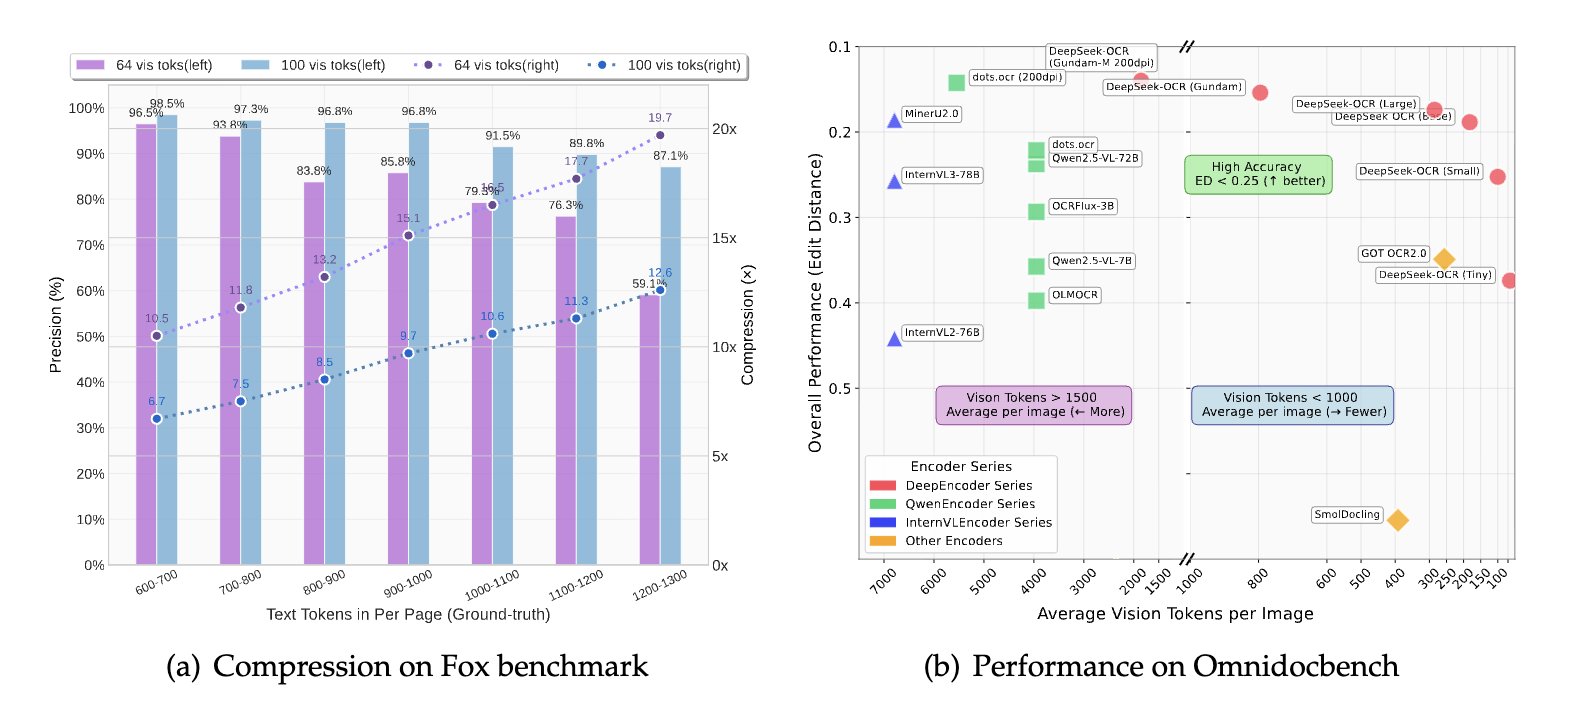
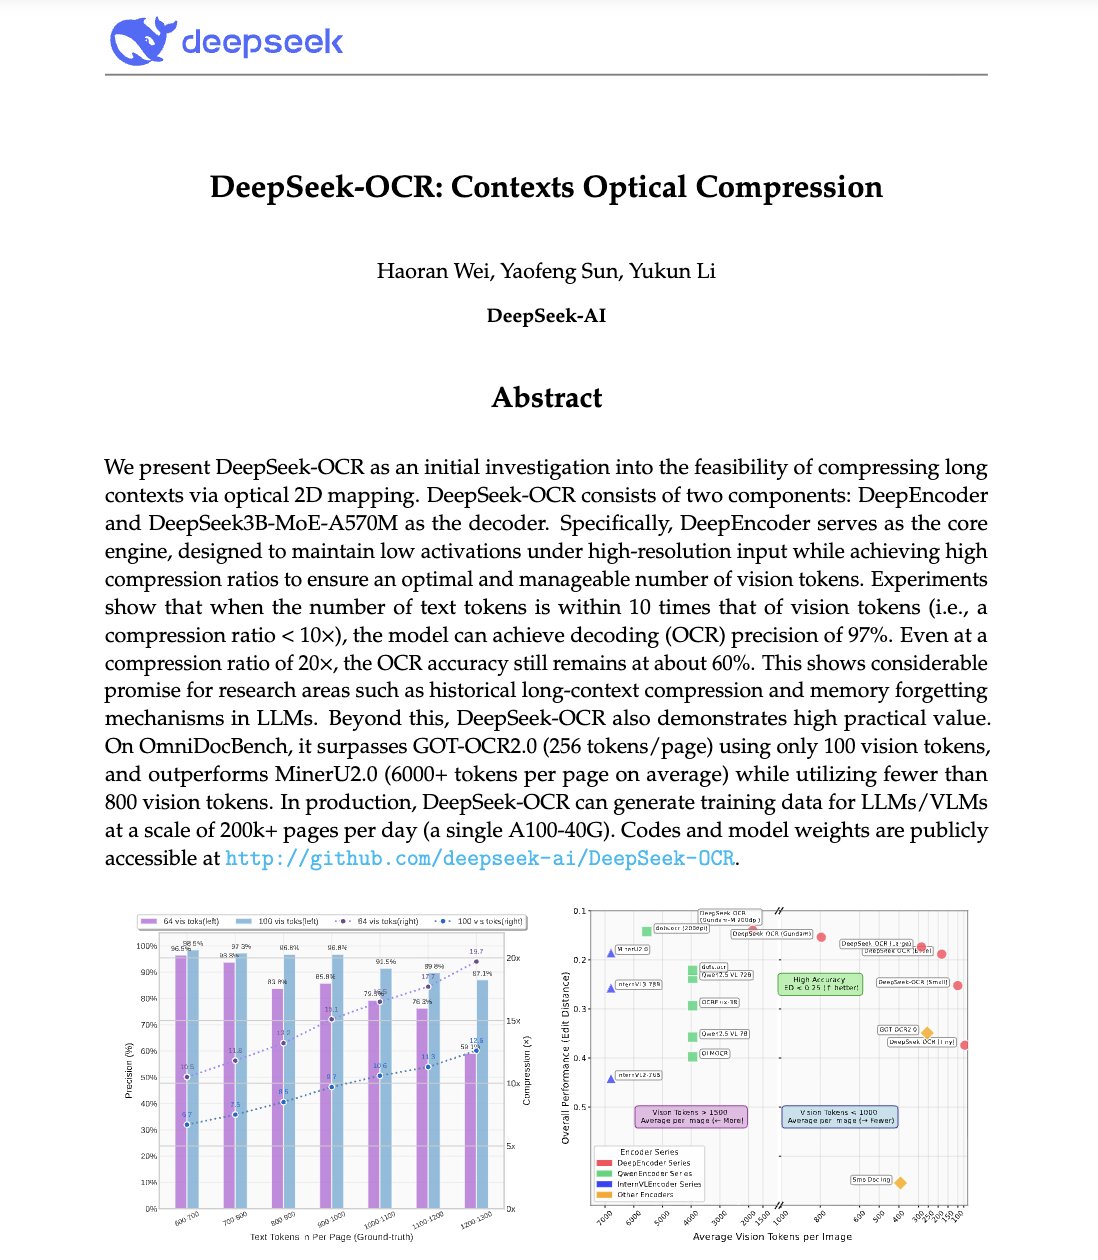
DeepSeek just did something wild. They built an OCR system that compresses long text into vision tokens literally turning paragraphs into pixels. Their model, DeepSeek-OCR, achieves 97% decoding precision at 10× compression and still manages 60% accuracy even at 20×. That
-
High School Geometry Improves Spatial Intelligence in AI Models
By
–
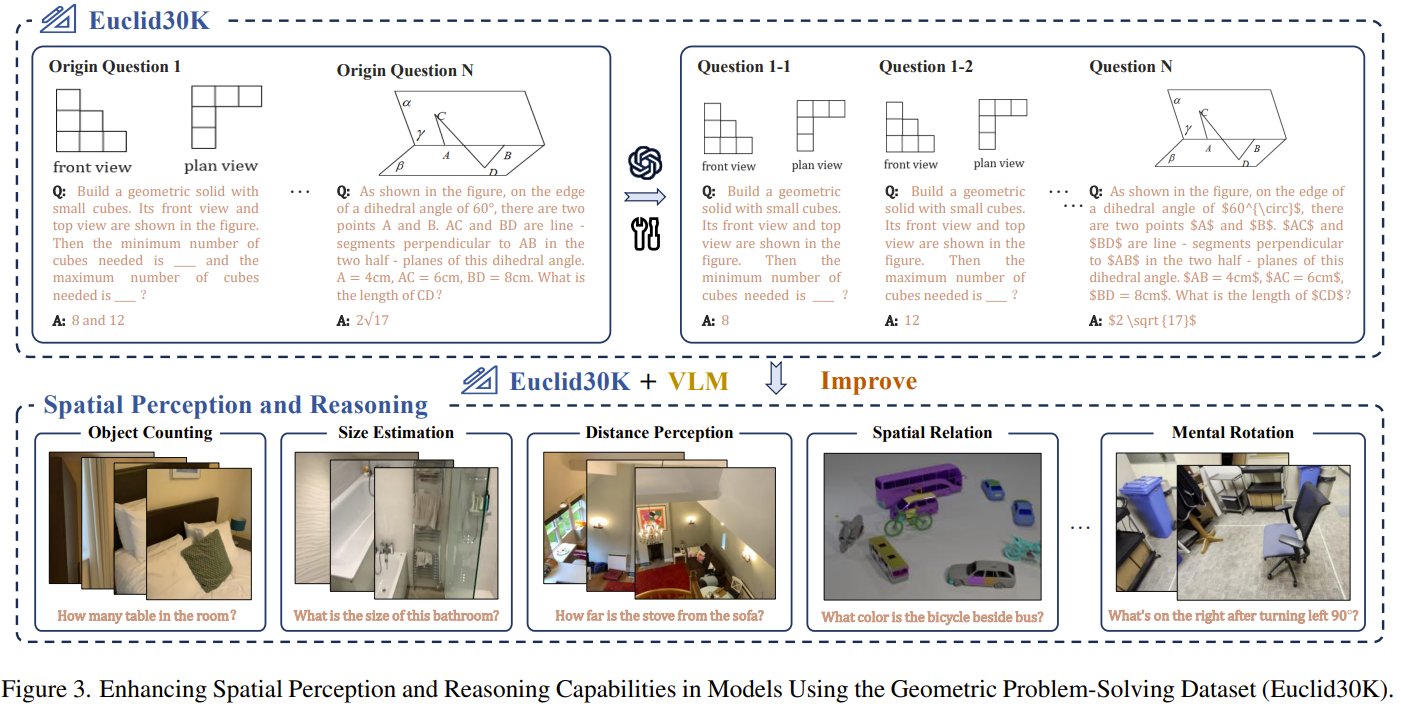
Can high school geometry teach AI to understand space? A new study tackles the critical challenge of spatial intelligence in Multimodal Large Language Models (MLLMs). Researchers found that fine-tuning models on Euclid30K, a new dataset of ~30,000 Euclidean geometry
-
Bounding Boxes Feature Expands AI Vision Model Use Cases
By
–
Having the ability to get bounding boxes of images would make it useful for a much wider variety of use cases, where reconstruction of the original or access to all the information is needed.
-
Microsoft adds video generation and shopping sidebar to Copilot
By
–
Microsoft prepares to add video generation capabilities to Copilot. Video generation will likely be powered by Sora 2 and will be available from the same Copilot app.
— 🚨 AI News | TestingCatalog (@testingcatalog) 19 octobre 2025
Shopping is also expected to expand and get a dedicated link from the sidebar. pic.twitter.com/xhRPWsjts0Microsoft prepares to add video generation capabilities to Copilot. generation will likely be powered by Sora 2 and will be available from the same Copilot app. Shopping is also expected to expand and get a dedicated link from the sidebar.
-
Parametric Semantic Abstraction from Real World Captures
By
–
Agree. On that last bit – what are the coolest things you’re seeing on creating parametric or semantically meaningful abstracted representations from real world captures?