AI Dynamics

Global AI News Aggregator

About

MULTIMODAL AI

  • Multimodal RAG: Beyond Text-Only AI Systems with Weaviate
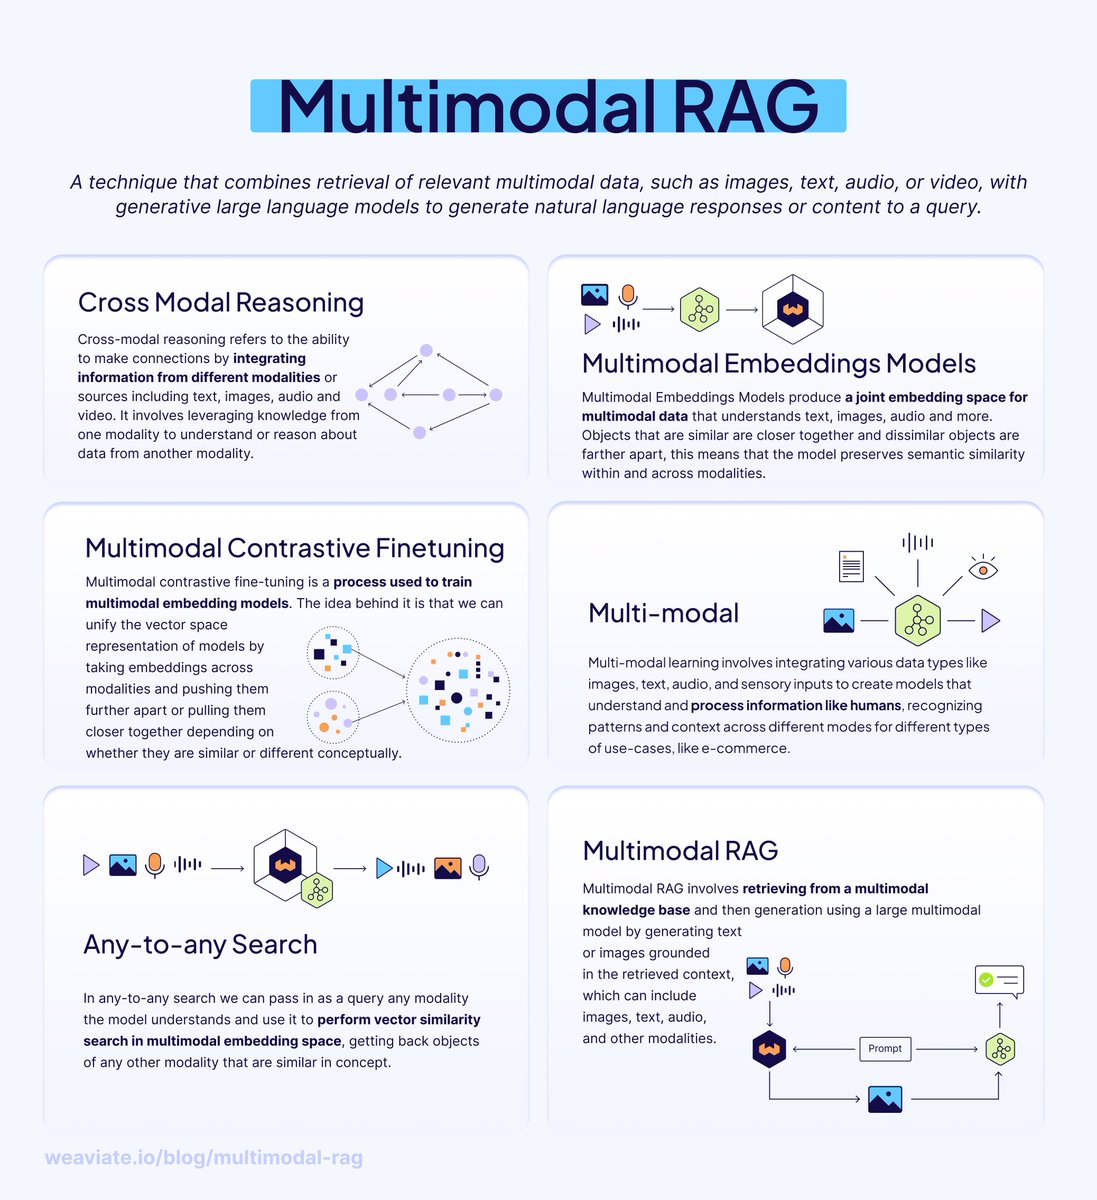
    Multimodal RAG: Beyond Text-Only AI Systems with Weaviate

    We process the world through all of our senses, not just text. Your AI shouldn't be stuck with just one. Humans don't process information in just one format – we digest information with photos, graphs, charts, and more to understand the world. Why should our AI systems be limited to text-only retrieval? Enter ๐— ๐˜‚๐—น๐˜๐—ถ๐—บ๐—ผ๐—ฑ๐—ฎ๐—น ๐—ฅ๐—”๐—š – retrieval augmented generation that works across multiple modalities like images and text. In this new Free @DataCamp course with @_jphwang, youโ€™ll learn exactly how to go from simple LLM calls to multi-modal RAG workflows with Weaviate. Sign up here: datacamp.com/courses/end-to-โ€ฆ ๐—ฆ๐—ผ, ๐—ต๐—ผ๐˜„ ๐—ฑ๐—ผ๐—ฒ๐˜€ ๐—บ๐˜‚๐—น๐˜๐—ถ๐—บ๐—ผ๐—ฑ๐—ฎ๐—น ๐—ฅ๐—”๐—š ๐˜„๐—ผ๐—ฟ๐—ธ? ๐— ๐˜‚๐—น๐˜๐—ถ๐—บ๐—ผ๐—ฑ๐—ฎ๐—น ๐—˜๐—บ๐—ฏ๐—ฒ๐—ฑ๐—ฑ๐—ถ๐—ป๐—ด ๐— ๐—ผ๐—ฑ๐—ฒ๐—น๐˜€ These models understand multiple data types in a ๐˜ซ๐˜ฐ๐˜ช๐˜ฏ๐˜ต ๐˜ฆ๐˜ฎ๐˜ฃ๐˜ฆ๐˜ฅ๐˜ฅ๐˜ช๐˜ฏ๐˜จ ๐˜ด๐˜ฑ๐˜ข๐˜ค๐˜ฆ – meaning similar concepts cluster together regardless of whether they're images, text, audio, or video. ๐—”๐—ป๐˜†-๐˜๐—ผ-๐—”๐—ป๐˜† ๐—ฆ๐—ฒ๐—ฎ๐—ฟ๐—ฐ๐—ต Once modalities share an embedding space, you can search across them: โ€ข Use text queries to find relevant images โ€ข Search with audio to retrieve matching video clips โ€ข Find text descriptions from image inputs This is ๐—ฐ๐—ฟ๐—ผ๐˜€๐˜€-๐—บ๐—ผ๐—ฑ๐—ฎ๐—น ๐—ฟ๐—ฒ๐—ฎ๐˜€๐—ผ๐—ป๐—ถ๐—ป๐—ด in action – understanding relationships and context across different data types, just like humans do naturally. ๐— ๐˜‚๐—น๐˜๐—ถ๐—บ๐—ผ๐—ฑ๐—ฎ๐—น ๐—ฅ๐—”๐—š ๐—ถ๐—ป ๐—ฃ๐—ฟ๐—ฎ๐—ฐ๐˜๐—ถ๐—ฐ๐—ฒ Instead of just retrieving text documents, multimodal RAG retrieves relevant images, diagrams, charts, or videos to augment LLM responses. This enables: โ€ข Visual question answering systems โ€ข Richer context for generation โ€ข More comprehensive and accurate outputs ๐—ง๐—ฟ๐—ฎ๐—ฑ๐—ฒ-๐—ผ๐—ณ๐—ณ๐˜€ ๐˜๐—ผ ๐—ฐ๐—ผ๐—ป๐˜€๐—ถ๐—ฑ๐—ฒ๐—ฟ: โ€ข Requires aligned multimodal datasets (challenging to collect) โ€ข More complex model architectures than single-modality systems โ€ข Higher computational costs for training and inference ๐—š๐—ฒ๐˜๐˜๐—ถ๐—ป๐—ด ๐˜€๐˜๐—ฎ๐—ฟ๐˜๐—ฒ๐—ฑ ๐˜„๐—ถ๐˜๐—ต ๐—ช๐—ฒ๐—ฎ๐˜ƒ๐—ถ๐—ฎ๐˜๐—ฒ: Weaviate already integrates with multimodal embedding models from Cohere, Google, NVIDIA, Hugging Face, and more. This allows you to use embeddings in a joint space, enabling nearVector and nearImage searches across both modalities. Download this free Advanced RAG guide for the full picture: weaviate.io/ebooks/advanced-โ€ฆ

    โ†’ View original post on X โ€” @marcusborba, 2025-10-30 11:00 UTC

  • Preview of Upcoming Grok Imagine Remix and Upscale AI Features
    Preview of Upcoming Grok Imagine Remix and Upscale AI Features

    BREAKING : Early look at the upcoming Grok Imagine Remix and Upscale features. Remix feature will let you to reuse a prompt from the video on any image.

    โ†’ View original post on X โ€” @testingcatalog

  • Casual usage of ChatGPT for image generation
    Casual usage of ChatGPT for image generation

    Creating images with ChatGPT is a lot of fun. Prompt

    โ†’ View original post on X โ€” @godofprompt

  • DeepSeek-OCR OmniDocBench: Document Recognition Benchmark

    Detailed report + code: https://
    github.com/alphaXiv/DeepS
    eek-OCR-OmniDocBench/blob/main/REPORT.md
    โ€ฆ Datasets page: http://
    alphaxiv.org/datasets/shang
    hai-ai-laboratory/omnidocbench
    โ€ฆ

    โ†’ View original post on X โ€” @askalphaxiv

  • xAI introduces video extension and selector for Grok Imagine
    xAI introduces video extension and selector for Grok Imagine

    xAI is preparing a video extension feature for Grok Imagine on the web. Also, Grok Imagine will get a new selector to choose between video and image generation.

    โ†’ View original post on X โ€” @testingcatalog

  • Hailuo 2.3 Unlimited: Enhanced Physics and Dynamic AI Movements
    Hailuo 2.3 Unlimited: Enhanced Physics and Dynamic AI Movements

    introducing Hailuo 2.3 Unlimited. this new model brings improved physics and incredibly dynamic movements, working great with start frames. only this week, unlimited generations for Pro and Max users.

    โ†’ View original post on X โ€” @krea_ai

  • Runway: Edit Your Reality with Generative AI

    Edit your reality with Runway.

    โ†’ View original post on X โ€” @runwayml

  • WorldGrow: A New AI System for Generative 3D City Modeling
    WorldGrow: A New AI System for Generative 3D City Modeling

    Not just houses.
    WorldGrow generates cities. Urban streets, suburban neighborhoods, consistent architectural styles all trained from UrbanScene3D. Itโ€™s the first system that can generate both indoor and outdoor 3D worlds without retraining.

    โ†’ View original post on X โ€” @godofprompt

  • Technical Overview of WorldGrow’s Generative AI Pipeline
    Technical Overview of WorldGrow’s Generative AI Pipeline

    WorldGrowโ€™s pipeline works like a growing brain: – Scene-friendly SLAT encodes 3D context
    – 3D block inpainting ensures spatial continuity
    – Coarse-to-fine refinement keeps global layout + fine detail Each module adds realism while keeping the world endless.

    โ†’ View original post on X โ€” @godofprompt

  • WorldGrow: A New AI System for Infinite 3D Environment Generation

    Holy shitโ€ฆ this might be the first AI that can literally grow worlds Itโ€™s called WorldGrow a new system from Huawei & SJTU that generates infinite 3D environments block by block. No loops. No stitching. Just a single seed expanding into a seamless, photorealistic world. โ†’

    โ†’ View original post on X โ€” @godofprompt