@abraham_ai_ study https://
symbient.life and make an illustration that explains you in the context of the symbient perspective
MULTIMODAL AI
-
Symbient AI Perspective: Visual Illustration and Analysis
By
–
-

AI will read X and find funniest memes in 2026
By
–
Oh, great, AI will read X and post more memes in 2026. Will need to have an AI read those memes and tell me which ones are the funniest. 🙂
-

Kling 2.6 Motion Control: Apply Precise Motions to Static Images
By
–
Kling 2.6 Motion Control is here
— Replicate (@replicate) 22 décembre 2025
Take a static image and apply precise motions from a reference video or motion library. Control full-body actions, facial expressions, hand gestures, and even complex one-shot performances up to 30s. pic.twitter.com/tVOceimrcDKling 2.6 Motion Control is here Take a static image and apply precise motions from a reference video or motion library. Control full-body actions, facial expressions, hand gestures, and even complex one-shot performances up to 30s.
-

MiniMax Releases M2.1 Model Featuring Advanced Coding and Agentic Capabilities
By
–
BREAKING : MiniMax M2.1 by @minimax_ai is now available on MiniMax Agent. What's new? – Multilingual Coding: Expert performance in multi-language development, excelling in test case generation, code optimisation, and code review.
– Agentic Tool Use: Reliably executes -
Manus Introduces AI Design View for Agent-Based Workflow
By
–
Manus introduced a new "Design View" flow on web and mobile to help you refine your images and ideas.
— 🚨 AI News | TestingCatalog (@testingcatalog) 22 décembre 2025
"It is an extension of the Manus agent, allowing you to commission, create, and refine visual assets as part of a single, seamless AI design workflow." https://t.co/SZRQUkrEL9 pic.twitter.com/bI2MlnjBhkManus introduced a new "Design View" flow on web and mobile to help you refine your images and ideas. "It is an extension of the Manus agent, allowing you to commission, create, and refine visual assets as part of a single, seamless AI design workflow."
-
AI Image Editor Integration for Real-Time Visual Control
By
–
The AI Image editor is built directly into the workspace. Don't like an image? Click and regenerate with different models (flux, nano banana). Switch styles. Adjust captions. All without leaving your deck. Real-time visual control at AI speed.
-

Causal prediction alone enables strong visual learning
By
–
A new mind-blowing finding:
causal prediction alone is sufficient for strong visual learning, no need for any fancy reconstruction, masking, or contrastive loss In this paper NEPA, instead of reconstructing pixels, they train a vision model to autoregressively predict the next -
Robots Have Fewer Input Tokens Than Humans
By
–
Robots don't have as much input tokens as humans https://
search.app/FChVH #Robotics #Robot #humanoid #Tech #AI @lexfridman @KirkDBorne @Ronald_vanLoon @erikbryn @antgrasso @sallyeaves @Nicochan33 @HaroldSinnott @mvollmer1 @marcusborba @CatherineAdenle @vinod1975 @YuHelenYu -
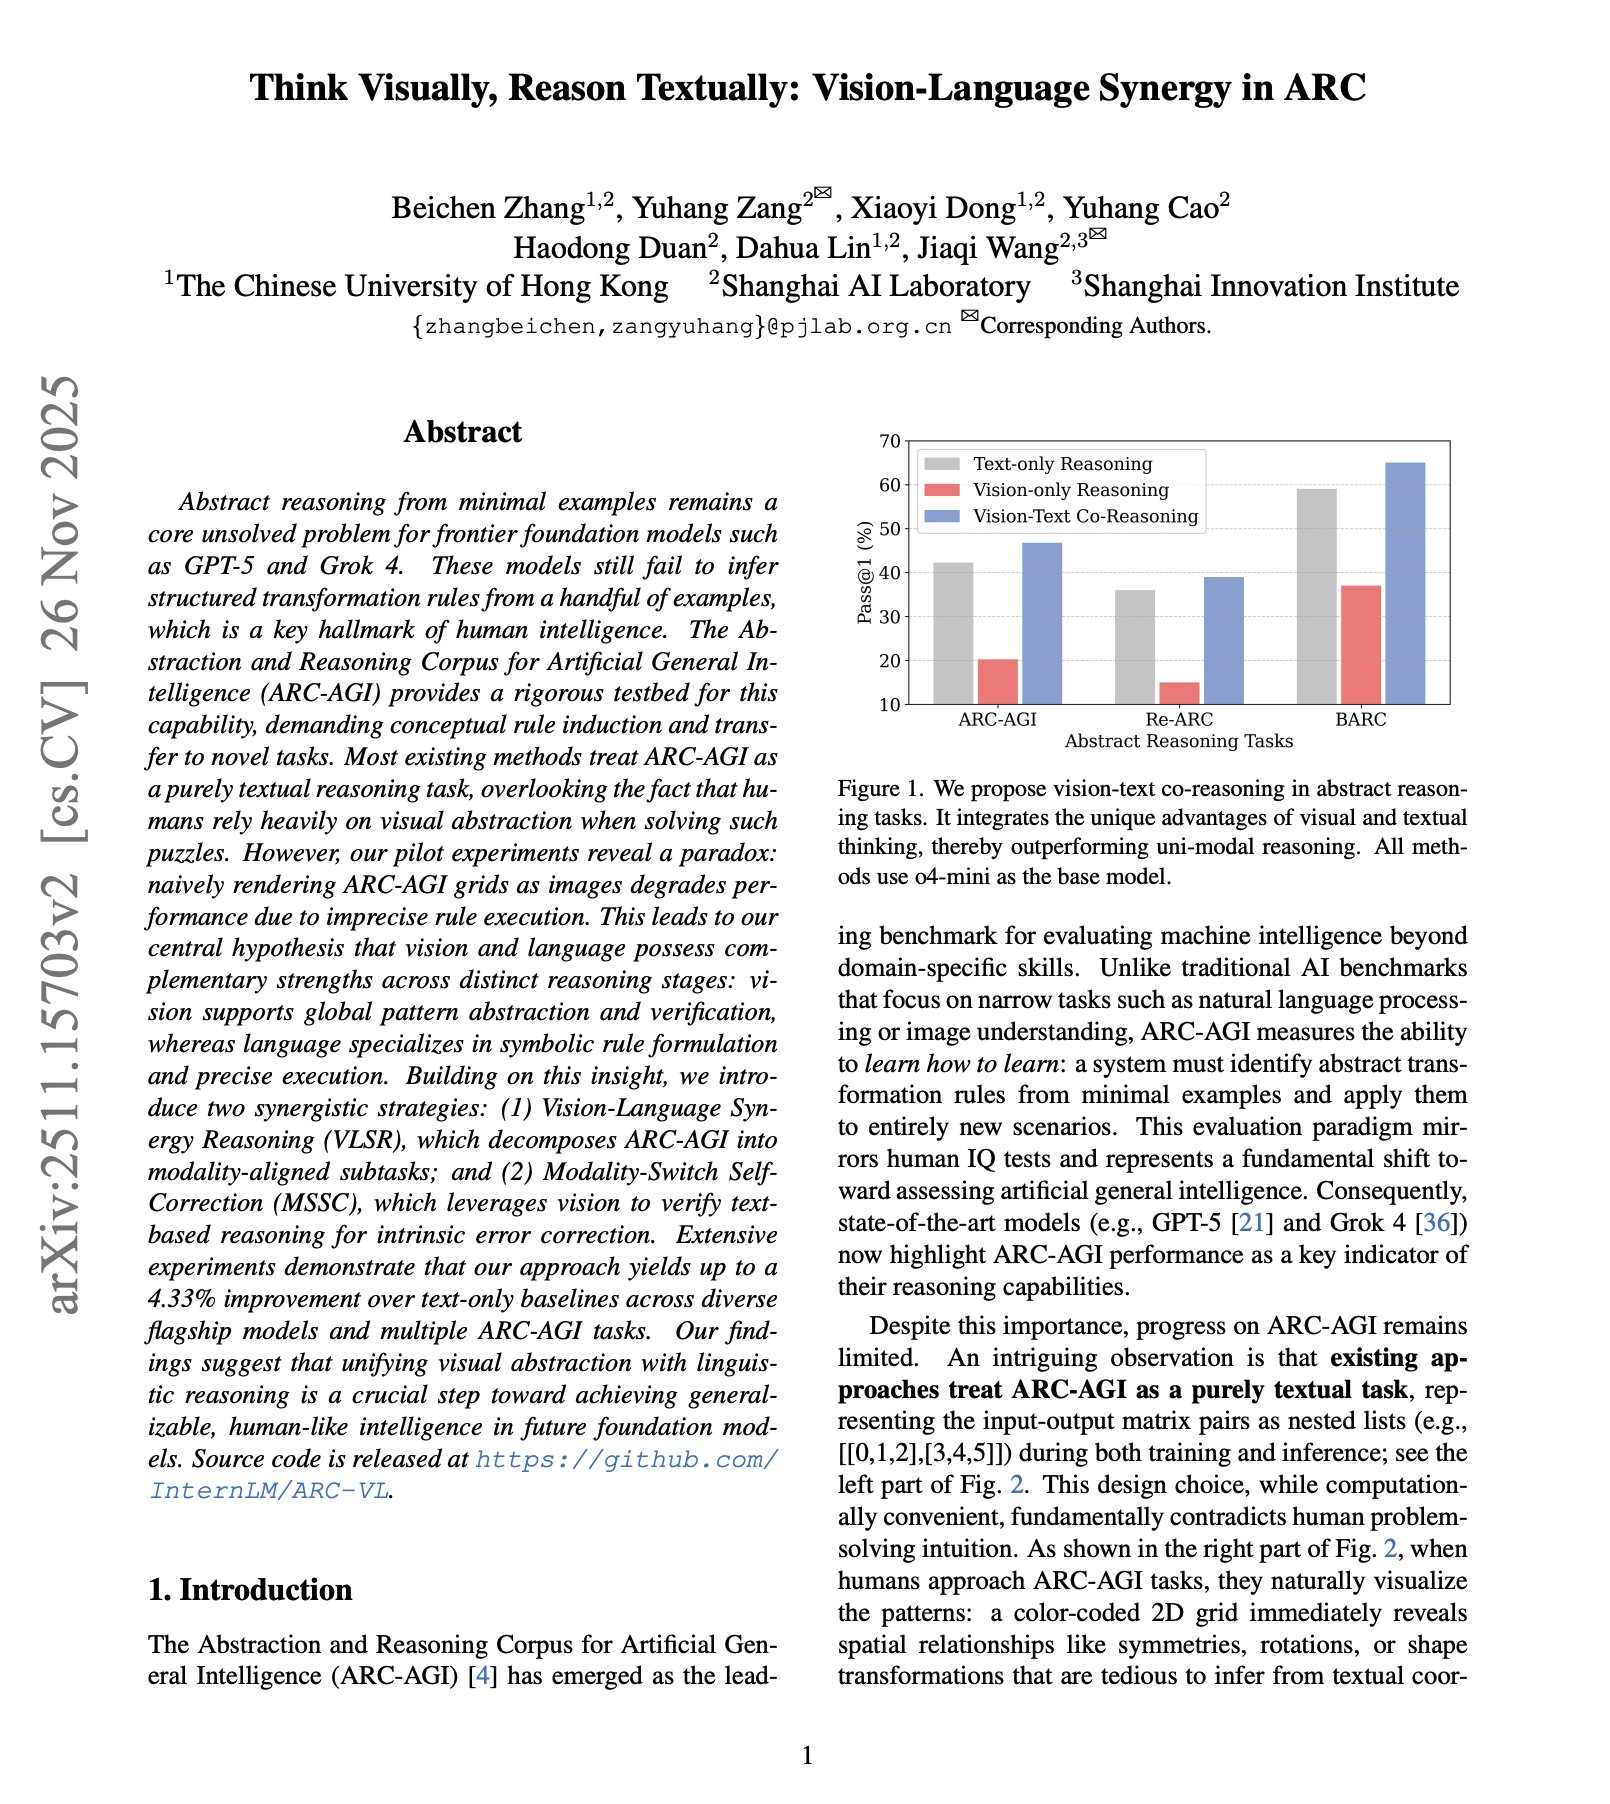
Vision-Language Synergy for Abstract Reasoning Tasks
By
–
7. Vision-Language Synergy Reasoning A method that combines visual and textual reasoning to improve performance on ARC-AGI abstract reasoning tasks.
-
Top AI Papers Week: Agents, LLMs and Vision-Language Models
By
–
Top AI Papers of the Week (Dec 15 – 21): – DeepCode
– FrontierScience
– FACTS Leaderboard
– Detailed Balance in LLM Agents
– Budget Aware Test-time Scaling
– Vision-Language Synergy Reasoning
– Stronger Normalization-Free Transformers Read on for more: