
What if an AI's "thoughts" could be seen as pictures, not just text? Researchers at Tencent present Render-of-Thought (RoT), a new method that turns an AI's text-based reasoning steps into visual images. This makes the AI's internal logic traceable and cuts down on processing
MULTIMODAL AI
-
Google Gemini 3 Flash Agentic Vision Think-Act-Observe Loop
By
–
AI models just stopped guessing and started investigating. Google just dropped "Agentic Vision" for Gemini 3 Flash, and it’s a total game-changer for how AI "sees." Instead of a static glance, the model now uses a Think-Act-Observe loop to: Zoom into tiny details (like
-
Anthropic developing Sketch tool for Claude with Knowledge base and Cowork updates
By
–
Anthropic is developing a new Sketch tool for Claude, allowing users to draw their ideas directly on the canvas before uploading them as an attachment.
— 🚨 AI News | TestingCatalog (@testingcatalog) 28 janvier 2026
Additionally 👀
– Updated system prompt for Knowledge bases.
– A possibility to start Cowork tasks from Projects.
– A new… pic.twitter.com/pH2ENJweAEAnthropic is developing a new Sketch tool for Claude, allowing users to draw their ideas directly on the canvas before uploading them as an attachment. Additionally – Updated system prompt for Knowledge bases.
– A possibility to start Cowork tasks from Projects.
– A new -
Gemini 3 Flash Launches Agentic Vision for Advanced Image Understanding
By
–
Introducing Agentic Vision — a new frontier AI capability in Gemini 3 Flash that converts image understanding from a static act into an agentic process. By combining visual reasoning with code execution, one of the first tools supported by Agentic Vision, the model grounds
-
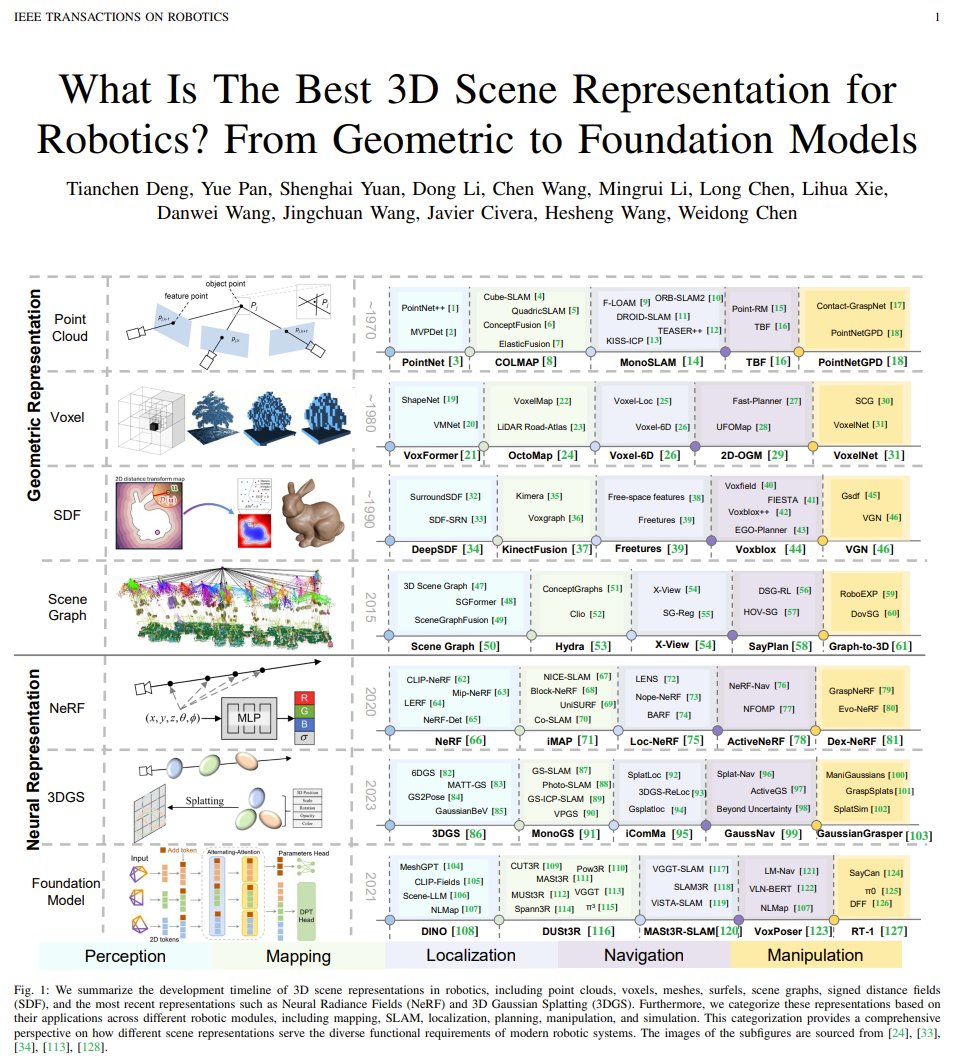
3D World Models: The Key to Truly Intelligent Robots
By
–
What's the single biggest roadblock to creating truly intelligent robots? A new survey tackles this. They argue that moving beyond simple point clouds to dense, AI-powered 3D "world models" is key. These neural scene representations, like NeRF and 3D Gaussian Splatting,
-
LobeHub: multi-model, direct API, agent marketplace, 70k GitHub stars
By
–
Claude Cowork: $200/month. One model. macOS only.
Manus: VM-based browsing. Slow. Unstable. Expensive. LobeHub:
→ Multi-model support (switch freely)
→ Direct API access (faster, more accurate)
→ Agent marketplace to discover and remix
→ 70k GitHub stars foundation More -
K2.5 Agent Swarm Creates New Language for Deep Sea Species
By
–
K2.5 Agent Swarm designed an entirely new language in just 38 minutes for an intelligent species that lives in the deep sea and communicates by emitting light through its skin.
— 机器之心 JIQIZHIXIN (@jiqizhixin) 27 janvier 2026
(The video is sped up 20×.) https://t.co/MNlgtB4fAD pic.twitter.com/76HtUFdGp5K2.5 Agent Swarm designed an entirely new language in just 38 minutes for an intelligent species that lives in the deep sea and communicates by emitting light through its skin. (The video is sped up 20×.)
-
Claude enables Asana timelines, Slack messages, Figma diagrams from text
By
–
Build project timelines in Asana. Draft and send Slack messages with formatting preview. Create Figma diagrams from text.
— God of Prompt (@godofprompt) 27 janvier 2026
All of this happens inside your conversation with Claude.
This isn't just integration. It's transformation. pic.twitter.com/WWm215YEqTBuild project timelines in Asana. Draft and send Slack messages with formatting preview. Create Figma diagrams from text. All of this happens inside your conversation with Claude. This isn't just integration. It's transformation.
-

Anthropic develops inline voice mode for seamless text-voice switching
By
–

Anthropic is working on a new inline voice mode UI for its mobile apps. Users will be able to seamlessly switch between text and voice conversations.
-

Fine-Tuning Video Models for Visuomotor Robot Control
By
–
"Fine-Tuning Models for Visuomotor Control and Planning" This paper proposes Cosmos Policy, showing a pretrained latent video diffusion model (Cosmos-Predict2) can be adapted into a SoTA robot policy via a single post-training stage on robot demonstrations, without