
Why does AI-generated text still look so distorted or blurry? Huazhong University of Science and Technology and ByteDance present TextPecker, a groundbreaking solution! TextPecker is a clever plug-and-play strategy that teaches text-to-image AI to "see" and correct structural
MULTIMODAL AI
-
Agent 4 Buildathon: Idea to Launch in Three Weeks with Prizes
By
–
3,000+ builders signed up! Three weeks to go from idea to launch. $57K+ in prizes. 🔥
— Replit ⠕ (@Replit) 24 mars 2026
The Agent 4 Buildathon kicks off today at 9 AM PT / 12 PM ET.
Join the livestream and start building! https://t.co/IGzVjF38FD3,000+ builders signed up! Three weeks to go from idea to launch. $57K+ in prizes. The Agent 4 Buildathon kicks off today at 9 AM PT / 12 PM ET. Join the livestream and start building!
-

Google DeepMind and Agile Robots Partner for Advanced Robots
By
–
Google DeepMind 🤝 Agile Robots Our new research partnership will integrate the Gemini foundation models with their hardware to help build the next generation of more helpful and useful robots. Find out more → goo.gle/4lKu7de [Translated from EN to English]
-

DM0: Embodied-Native VLA Framework for Physical Understanding
By
–
How do we build AI that truly understands the physical world from the ground up, not as an afterthought? A team from Dexmal & @StepFun_ai just unveiled DM0, a groundbreaking Embodied-Native Vision-Language-Action (VLA) framework. Unlike adapting web-trained models, DM0 learns
-
Multimodality Integration: The Real Upgrade for Production AI Systems
By
–
My takeaway: The real upgrade is not just multimodality. It is collapsing text, vision, long context, and reasoning into one coherent workflow. That is how you move from demos to production-grade AI systems. I break it all down in my new video on Kimi K2.5 by Moonshot AI.
-
True Multimodal AI: Moonshot’s Native Text-Vision Integration
By
–
Most “multimodal” AI is just duct tape.
— Ronald van Loon (@Ronald_vanLoon) 24 mars 2026
One model for text.
Another for vision.
A pipeline to glue it together.
But what happens when text + vision are native in the same model, with a 256K context window?
That is what Moonshot AI just changed.
A thread on what I learned from… pic.twitter.com/CmnuE9FNJxMost “multimodal” AI is just duct tape. One model for text.
Another for vision.
A pipeline to glue it together. But what happens when text + vision are native in the same model, with a 256K context window? That is what Moonshot AI just changed. A thread on what I learned from -
Native Multimodal Models: Architectural Shift in AI Integration
By
–
The biggest shift is architectural. This is not text routed to a vision model. It is a native multimodal model. → Send base64 images or even videos directly into a chat completion request
→ Reason across text and visuals in the same workflow
→ No fragile orchestration layer -

AI Quietly Handles Small Tasks Across Workflows Daily
By
–
AI is quietly eating every ‘small task’ in your workflow.
In the last hour alone, people have used AI to: Restore blurry old photos
Draft SQL pipelines
Offload multi-step digital work to agents
Turn selfies into scroll-stopping videos
Even run fleets of ‘AI employees’ -
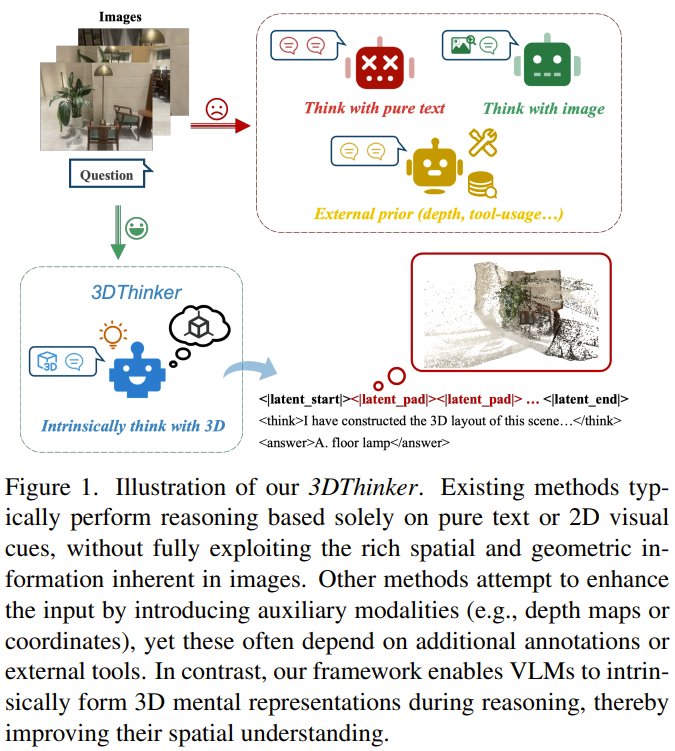
3DThinker: AI Framework for 3D Spatial Reasoning
By
–
Can AI really 'think in 3D' from limited 2D views, just like us? Researchers from Tsinghua University, Meituan, NUS, Beihang University, and LMMs-Lab introduce 3DThinker. This groundbreaking framework lets AI mentally 'imagine' 3D shapes and spatial relationships from 2D
-
Chinese AI Studios Use Seedance 2 to Create Full TV Series
By
–
Chinese AI studios are now creating full TV show series using Seedance 2.#AIstudio #TVshow #AIart️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️ #AIvideo #AI #AIshow #movies #AImovies #tech #artificialintelligence… pic.twitter.com/VQ3tXSgFCU
— Amitav Bhattacharjee (@bamitav) 24 mars 2026Chinese AI studios are now creating full TV show series using Seedance 2. #AIstudio #TVshow #AIart️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️ #AIvideo #AI #AIshow #movies #AImovies #tech #artificialintelligence