Reference to replicate.com/wan-video/wan-… [Translated from EN to English]
→ View original post on X — @replicate, 2026-04-03 13:31 UTC
By
–
Reference to replicate.com/wan-video/wan-… [Translated from EN to English]
→ View original post on X — @replicate, 2026-04-03 13:31 UTC
By
–
Image to replicate.com/wan-video/wan-2.7-i2v [Translated from EN to English]
→ View original post on X — @replicate, 2026-04-03 13:31 UTC
By
–
Text to replicate.com/wan-video/wan-… [Translated from EN to English]
→ View original post on X — @replicate, 2026-04-03 13:30 UTC
By
–
Wan 2.7 Video is now on Replicate
— Replicate (@replicate) 3 avril 2026
generation, editing, cloning, restyling, and continuation controlled by text, image, audio, or video
here's what that looks like 🧵 pic.twitter.com/OcO7LKPRph
Wan 2.7 is now on Replicate generation, editing, cloning, restyling, and continuation controlled by text, image, audio, or video here's what that looks like 🧵
→ View original post on X — @replicate, 2026-04-03 13:30 UTC
By
–
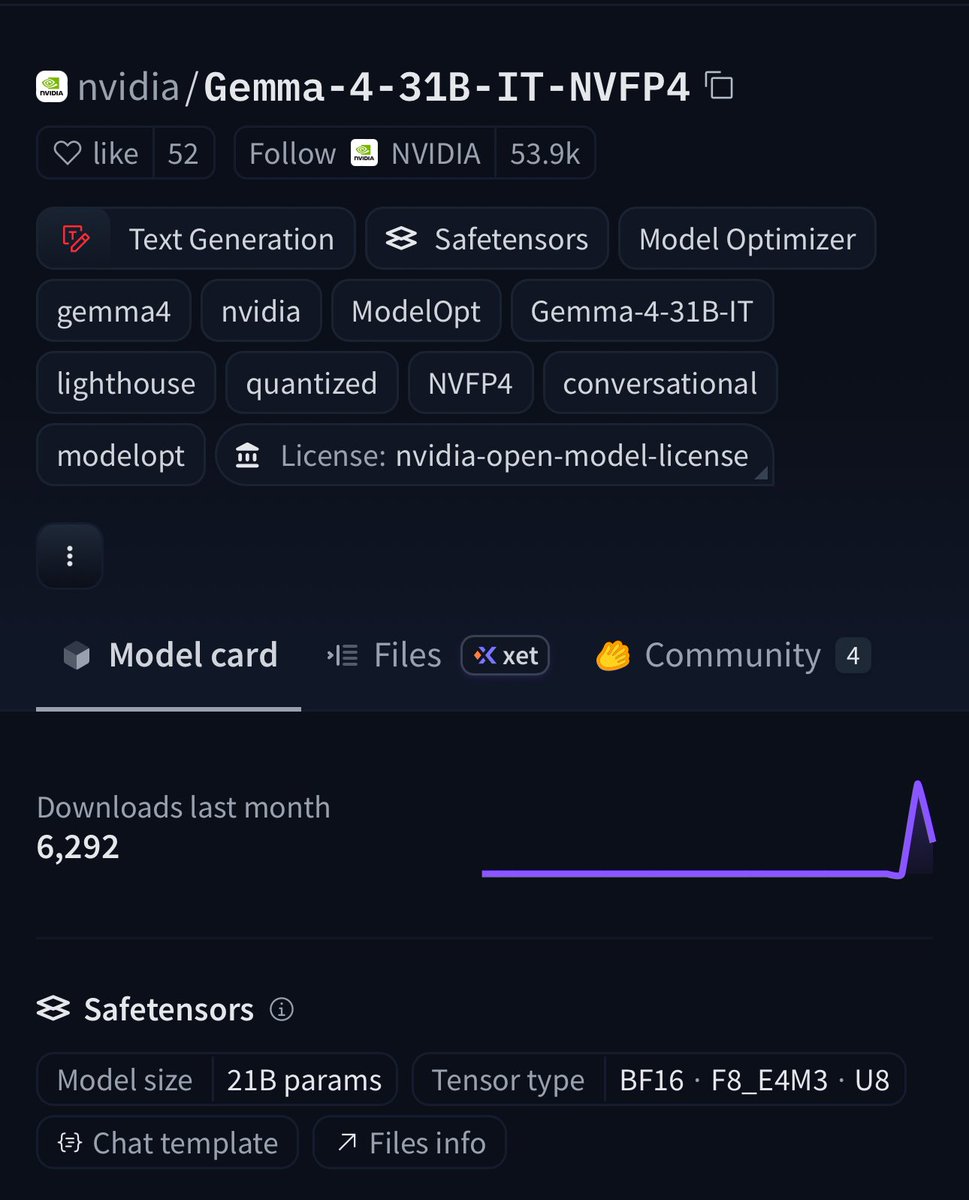
BREAKING:🚨 NVIDIA just quantized Gemma 4 31B on Hugging Face 🔥 NVFP4 compression = 4x smaller weights with frontier-level accuracy. ✅99.7% of baseline on GPQA (75.46% vs 75.71%). 📈256K context window. 🧐Multimodal (text + images + video). vLLM-ready + Blackwell optimized. VRAM requirements: ⚡️Weights only: ~16–21 GB 🚀Everyday use: Runs on 24 GB GPUs 📈Full 256K context = 32 GB VRAM sweet spot (RTX 5090-class consumer GPUs) This is the 31B-class frontier model you can actually run locally on a high-end rig. Try it today👉 huggingface.co/nvidia/Gemma-…
→ View original post on X — @huggingface, 2026-04-03 13:30 UTC
By
–
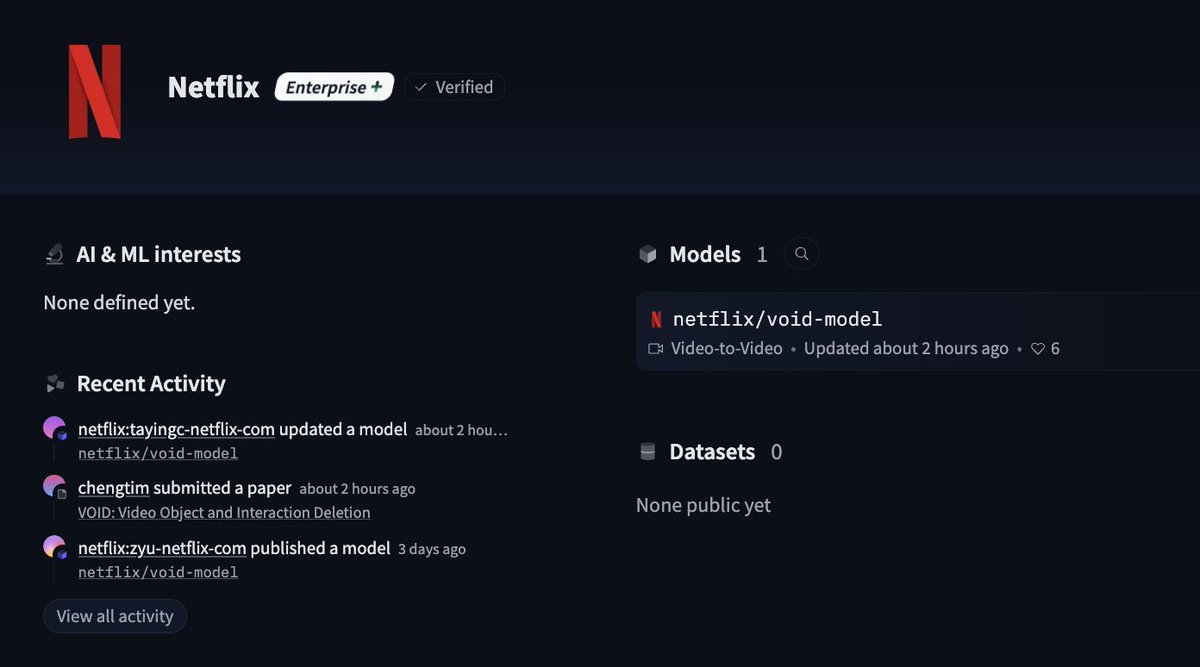
Netflix: surprise we just released our new AI model VOID on @huggingface. Capabilities of Netflix's VOID Model:
– Object Removal with Environmental Awareness.
– Physical Interaction Handling.
– Open-Weight Access. [Translated from EN to English]
→ View original post on X — @huggingface, 2026-04-03 13:20 UTC
By
–
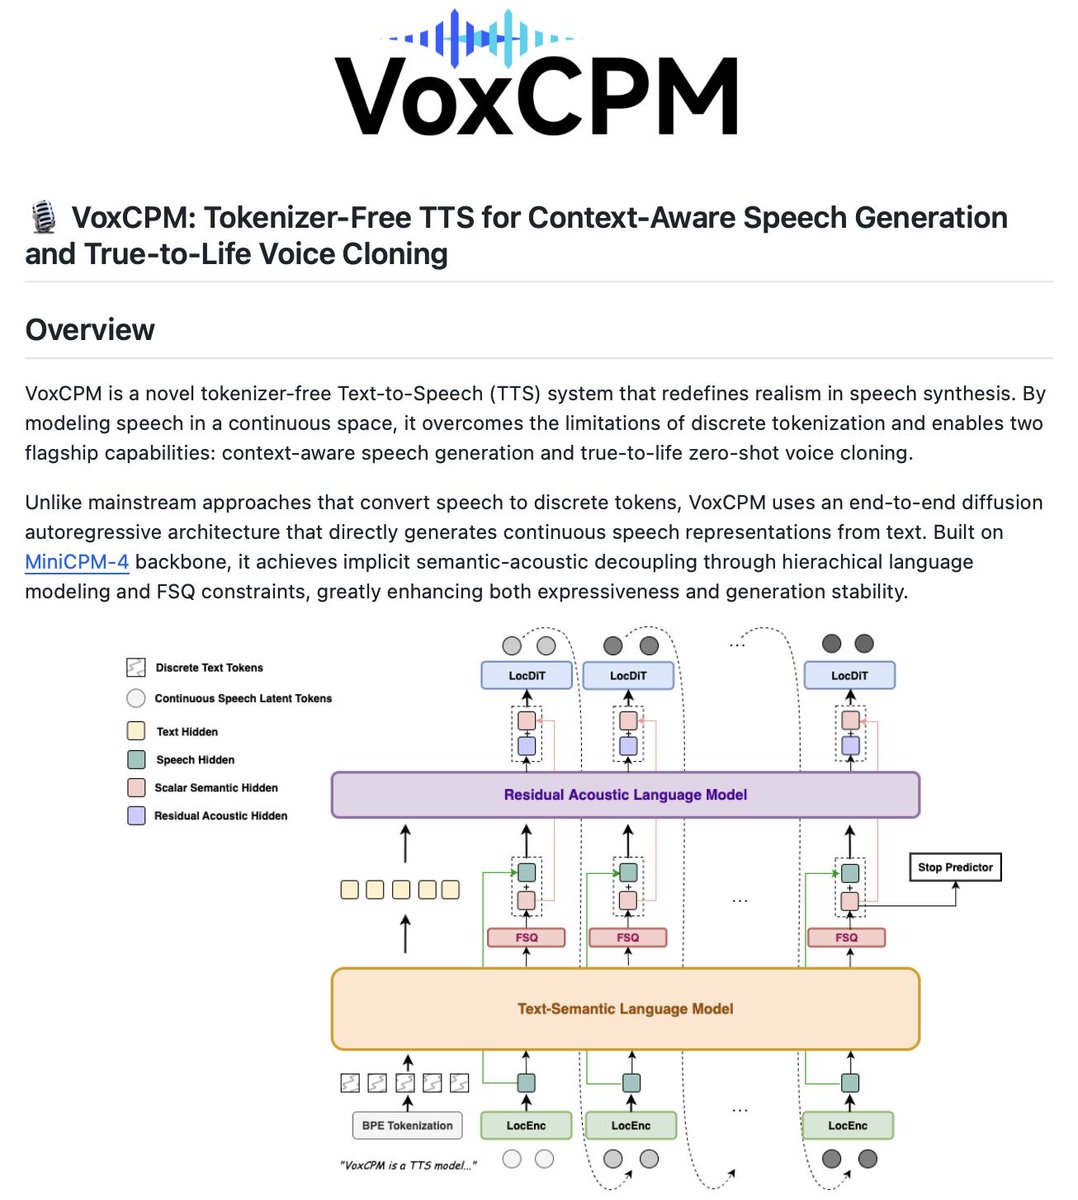
If you found it useful, reshare it with your network Follow me → @Sumanth_077 for more insights and tutorials on AI Engineering! nitter.net/Sumanth_077/status/204… Sumanth (@Sumanth_077) Clone a human voice in real time without tokenization! VoxCPM is an open-source text-to-speech system that models speech in continuous space instead of discrete tokens. Most TTS systems convert speech to discrete tokens before generation. This quantization creates a fundamental trade-off: tokens provide stability but lose acoustic details like breath, vocal texture, and subtle articulation. VoxCPM skips tokenization entirely. It models speech directly in continuous space using an end-to-end diffusion autoregressive architecture built on MiniCPM-4. The system uses hierarchical language modeling with two specialized components: a Text-Semantic Language Model that captures high-level prosody and structure, and a Residual Acoustic Model that recovers fine-grained acoustic details. This separation eliminates dependency on external speech tokenizers and prevents error accumulation from multi-stage pipelines. Two flagship capabilities: 1. Context-aware speech generation: The model comprehends text to infer appropriate prosody and speaking style. Explanations slow down naturally, emphasis appears in the right places, questions sound like questions. 2. Zero-shot voice cloning: With just 3-10 seconds of reference audio, it replicates speaker timbre, accent, emotional tone, rhythm, and pacing. Key features: • Tokenizer-free architecture with continuous speech modeling • Context-aware prosody generation without manual tuning • Zero-shot voice cloning from short reference audio • Streaming synthesis support for real-time applications • SFT and LoRA fine-tuning support It's 100% open source Link to the GitHub repo in the comments! — https://nitter.net/Sumanth_077/status/2040055394958286903#m
→ View original post on X — @sumanth_077, 2026-04-03 13:15 UTC
By
–
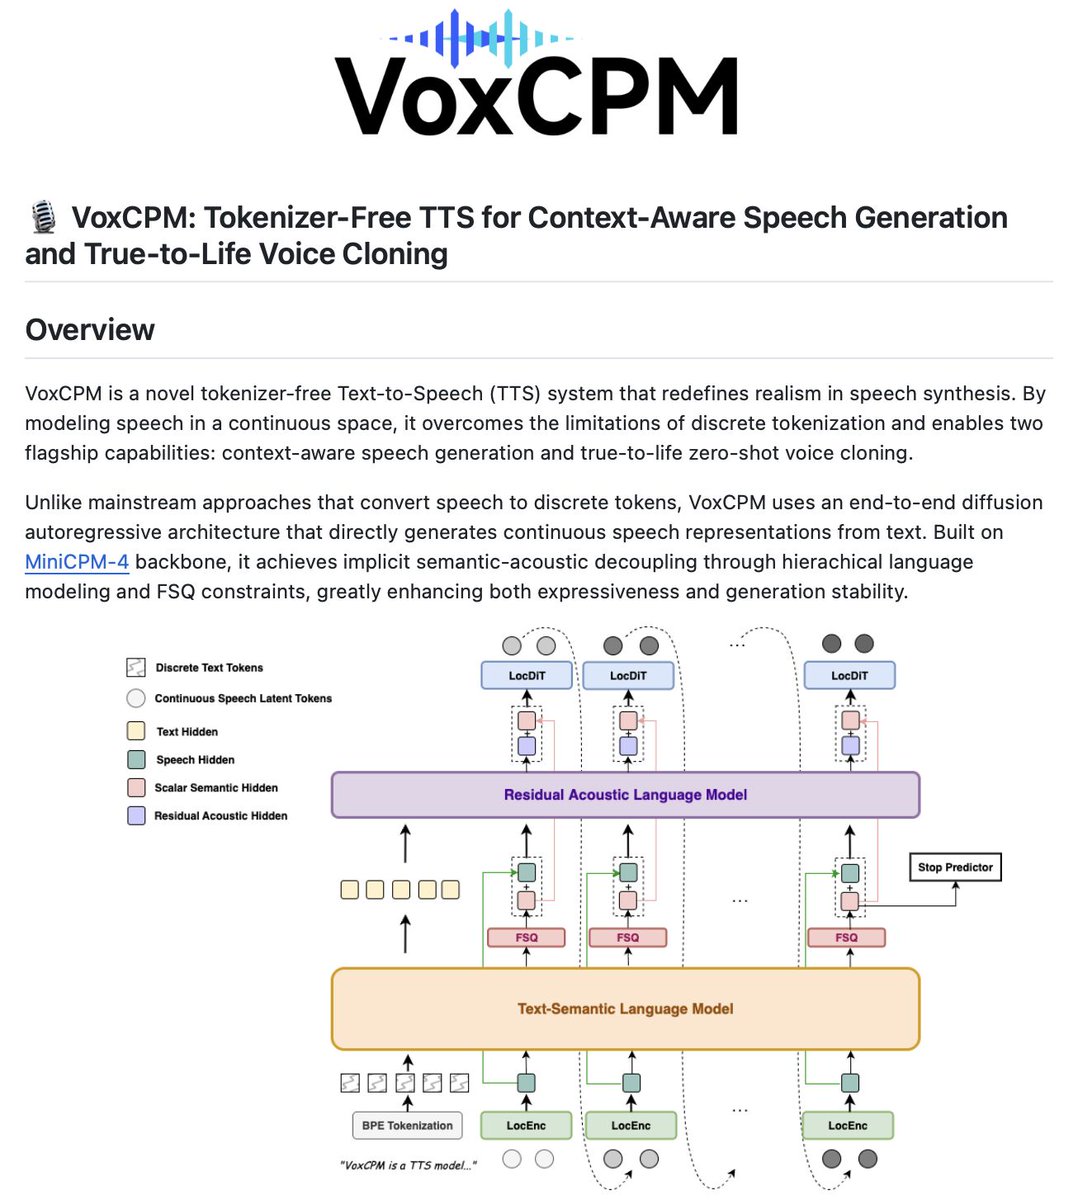
Clone a human voice in real time without tokenization! VoxCPM is an open-source text-to-speech system that models speech in continuous space instead of discrete tokens. Most TTS systems convert speech to discrete tokens before generation. This quantization creates a fundamental trade-off: tokens provide stability but lose acoustic details like breath, vocal texture, and subtle articulation. VoxCPM skips tokenization entirely. It models speech directly in continuous space using an end-to-end diffusion autoregressive architecture built on MiniCPM-4. The system uses hierarchical language modeling with two specialized components: a Text-Semantic Language Model that captures high-level prosody and structure, and a Residual Acoustic Model that recovers fine-grained acoustic details. This separation eliminates dependency on external speech tokenizers and prevents error accumulation from multi-stage pipelines. Two flagship capabilities: 1. Context-aware speech generation: The model comprehends text to infer appropriate prosody and speaking style. Explanations slow down naturally, emphasis appears in the right places, questions sound like questions. 2. Zero-shot voice cloning: With just 3-10 seconds of reference audio, it replicates speaker timbre, accent, emotional tone, rhythm, and pacing. Key features: • Tokenizer-free architecture with continuous speech modeling
• Context-aware prosody generation without manual tuning
• Zero-shot voice cloning from short reference audio
• Streaming synthesis support for real-time applications
• SFT and LoRA fine-tuning support It's 100% open source Link to the GitHub repo in the comments! [Translated from EN to English]
→ View original post on X — @sumanth_077, 2026-04-03 13:14 UTC

By
–
8 RAG architectures for AI Engineers: (explained with usage) 1) Naive RAG – Retrieves documents purely based on vector similarity between the query embedding and stored embeddings. – Works best for simple, fact-based queries where direct semantic matching suffices. 2) Multimodal RAG – Handles multiple data types (text, images, audio, etc.) by embedding and retrieving across modalities. – Ideal for cross-modal retrieval tasks like answering a text query with both text and image context. 3) HyDE (Hypothetical Document Embeddings) – Queries are not semantically similar to documents. – This technique generates a hypothetical answer document from the query before retrieval. – Uses this generated document’s embedding to find more relevant real documents. 4) Corrective RAG – Validates retrieved results by comparing them against trusted sources (e.g., web search). – Ensures up-to-date and accurate information, filtering or correcting retrieved content before passing to the LLM. 5) Graph RAG – Converts retrieved content into a knowledge graph to capture relationships and entities. – Enhances reasoning by providing structured context alongside raw text to the LLM. 6) Hybrid RAG – Combines dense vector retrieval with graph-based retrieval in a single pipeline. – Useful when the task requires both unstructured text and structured relational data for richer answers. 7) Adaptive RAG – Dynamically decides if a query requires a simple direct retrieval or a multi-step reasoning chain. – Breaks complex queries into smaller sub-queries for better coverage and accuracy. 8) Agentic RAG – Uses AI agents with planning, reasoning (ReAct, CoT), and memory to orchestrate retrieval from multiple sources. – Best suited for complex workflows that require tool use, external APIs, or combining multiple RAG techniques. 👉 Over to you: Which RAG architecture do you use the most? _____ Share this with your network if you found this insightful ♻️ Find me → @akshay_pachaar ✔️ For more insights and tutorials on LLMs, AI Agents, and Machine Learning!
→ View original post on X — @akshay_pachaar, 2026-04-03 12:54 UTC

By
–
📰 Microsoft MAI 3 Model Simultaneous Release — New Models for Voice, Image, and Transcription Microsoft has started simultaneously providing MAI-Transcribe-1 (highest accuracy in 25 languages, 50% reduction in GPU usage), MAI-Voice-1 (60-second audio generation in under 1 second), and MAI-Image-2 (ranked 3rd in Arena AI) through Microsoft Foundry. 💡 Why It Matters
This move clearly demonstrates Microsoft's strategy to develop proprietary models independent of OpenAI and Google. Notably, Transcribe-1 has high practical value as a successor to Whisper.
MAI-Voice-1's real-time audio generation is expected to be used in customer support and video production, while Image-2 offers competitive advantages in advertising creative generation.
Microsoft's strategy of embedding AI capabilities into its platform is accelerating, representing an important signal of changing competitive dynamics when considering the positioning of marketing AI OS like ENSOR. 🔗 techcommunity.microsoft.com/blog/azure-ai-foundry-blog/introducing-mai-transcribe-1-mai-voice-1-and-mai-image-2-in-microsoft-foundry/4507787 [Translated from EN to English]