
Every AI model speaks a different language. Midjourney wants keywords + flags. Nano Banana Pro and ChatGPT Image 2 want full sentences. Seedance and Kling Omni want you to direct, not describe. Same idea, 5 dialects. Most people use one prompt for all of them, and wonder why
MULTIMODAL AI
-
NVIDIA’s LocateAnything speeds object detection 10x by fixing coordinate bottleneck
By
–
🚨 @NVIDIA just dropped LocateAnything, making object detection ~10x faster by fixing one core bottleneck:
— Charly Wargnier (@DataChaz) 17 juin 2026
How the model writes coordinates.
Standard AI models do visual grounding the slow way.
They predict coordinates piece by piece: Token 1, Token 2, Token 3, Token 4 etc.… pic.twitter.com/GAyr0taCbX@NVIDIA just dropped LocateAnything, making object detection ~10x faster by fixing one core bottleneck: How the model writes coordinates. Standard AI models do visual grounding the slow way. They predict coordinates piece by piece: Token 1, Token 2, Token 3, Token 4 etc.
-
Grok Imagine Video 1.5 launches with sharper realism and physics
By
–
Grok Imagine Video 1.5 is here
— xAI (@xai) 17 juin 2026
Our new image-to-video model with sharper realism, better physics and faster generations 🧵https://t.co/zGhs9czkC5 pic.twitter.com/9X4YicpMH8Grok Imagine 1.5 is here Our new image-to-video model with sharper realism, better physics and faster generations http://
grok.com/imagine -
Seedance 2.0, Hyperframes, Remotion with Claude for programmatic videos
By
–
Seedance 2.0 for pixel video generation, Hyperframes and Remotion with Claude models for programmatic videos.
-
Seedance 2.0 Shows How Far AI Video Has Come
By
–
Seedance 2.0 Shows How Far AI Has Come https://
youtu.be/6n9fjS0of5o?si
=OAas0qmRSQUYbmxr
… via @YouTube #seedance #artificialintelligence #AI #AIart️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️️ #AIartist #AIvideo #video @SpirosMargaris -
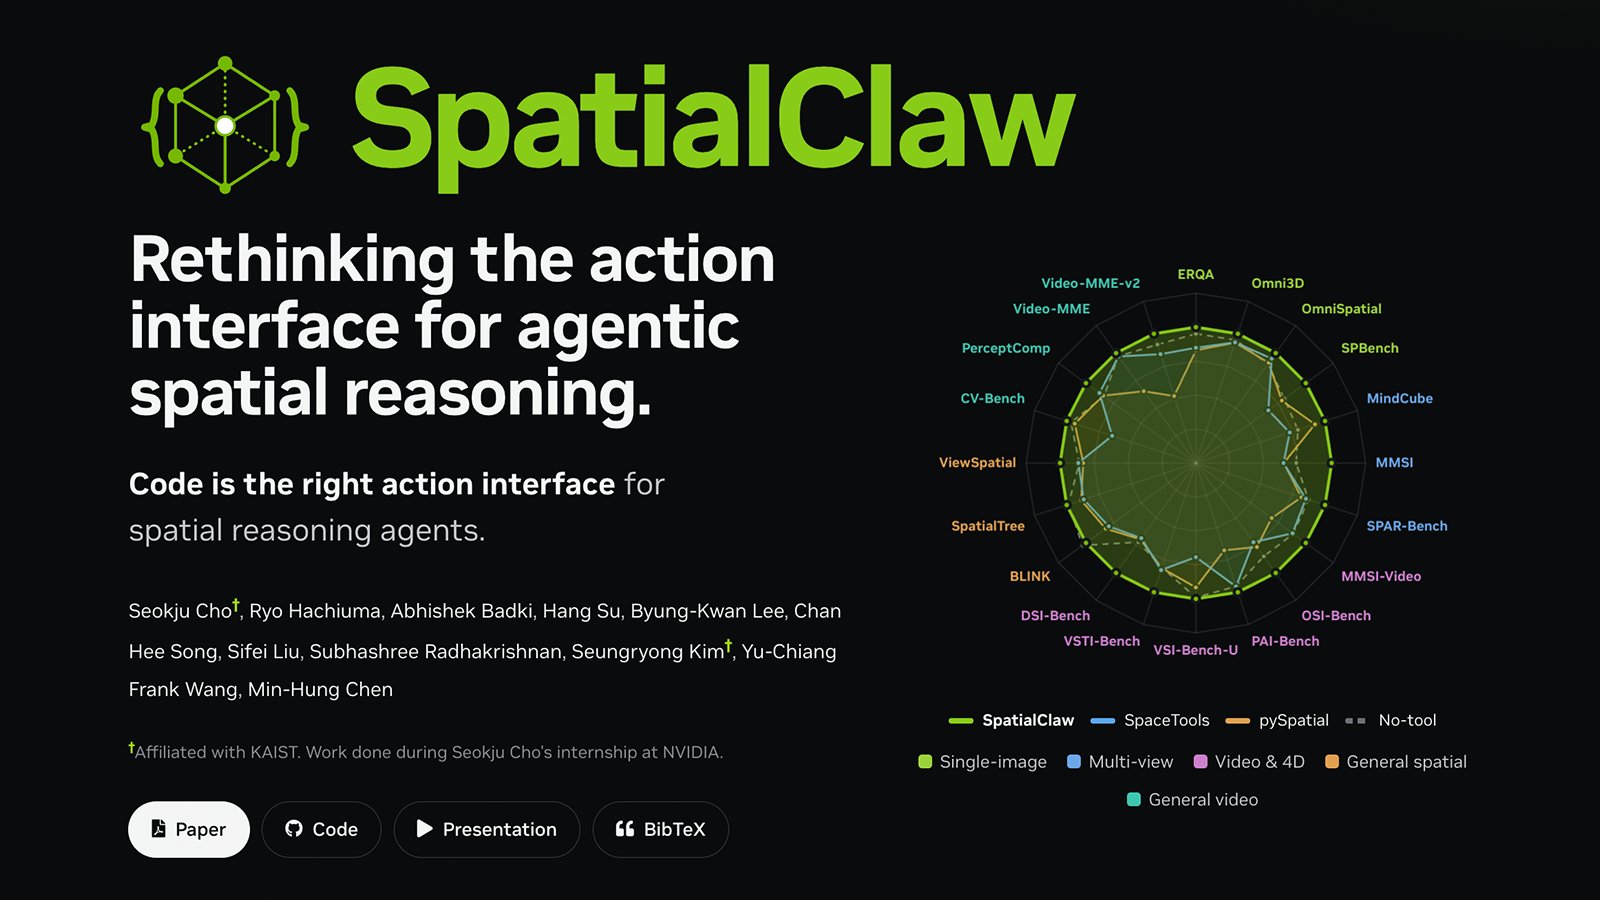
SpatialClaw: training-free agent using code for visual tasks
By
–
Code is the right action interface for spatial reasoning agents. New from NVIDIA Research: SpatialClaw, a training-free agent that uses code as its action interface for complex visual tasks. Instead of calling a fixed set of pre-defined tools, the agent writes Python inside a
-

AI AGENTS TEST YOUR LOCAL UNCOMMITTED CODE IN THE CLOUD
By
–
AI AGENTS CAN NOW TEST YOUR UNCOMMITTED LOCAL CODE DIRECTLY IN THE CLOUD Zero commits. Zero pushes. No waiting for CI loops. … and it’s entirely open-source! A new project called Crabbox just dropped, and it fixes the slowest part of cloud-dependent development.
-
Frontier AI recreates world’s literature as playable video games
By
–
using frontier ai to recreate the world's literature as playable video games ftw!
-

Long video reasoning with DeepSeek sparse attention and multimodal MoE
By
–
"Kwai Keye-VL-2.0 Technical Report" This paper makes long-video reasoning much more feasible by adapting DeepSeek Sparse Attention to a GQA-based multimodal MoE, reaching 256K context with only 3B active parameters. As dense attention makes hour-level context way too expensive,
-
Sora shows hype leads to number one but not profit
By
–
7/ At the end of the day, Sora proved something the whole industry is about to face. Hype gets you to number one. It does not pay the compute bill. And the bill always comes. Source: OpenAI, with figures from Forbes, Cantor Fitzgerald, WSJ, and Appfigures.