Do we have Kimi K2.7 scores yet? If so, how does it compare?
MACHINE LEARNING
-
Multi-step Workflows: Persistent State and Parallel Bursting
By
–
You run multi-step workflows where state must persist across tool calls. You need bursting capability (i.e., thousands of parallel environments for RL training or evaluations) that must go from zero to scale in
-
Mythos-class models: 4-8 months to harden IT systems
By
–
Assuming open models continue to lag about 8-12 months behind closed source (at least in coding), the countdown to hardening IT systems against Mythos-class models is now at 4-8 months Having publicly available and relatively safe defensive Mythos-class models today is important
-
Codex internal memory API endpoints for managing notes
By
–
not exposed to the end user (for good measure) but as an in-built tool that codex can call it can do the following: memories/list
memories/read
memories/search
memories/add_ad_hoc_note -
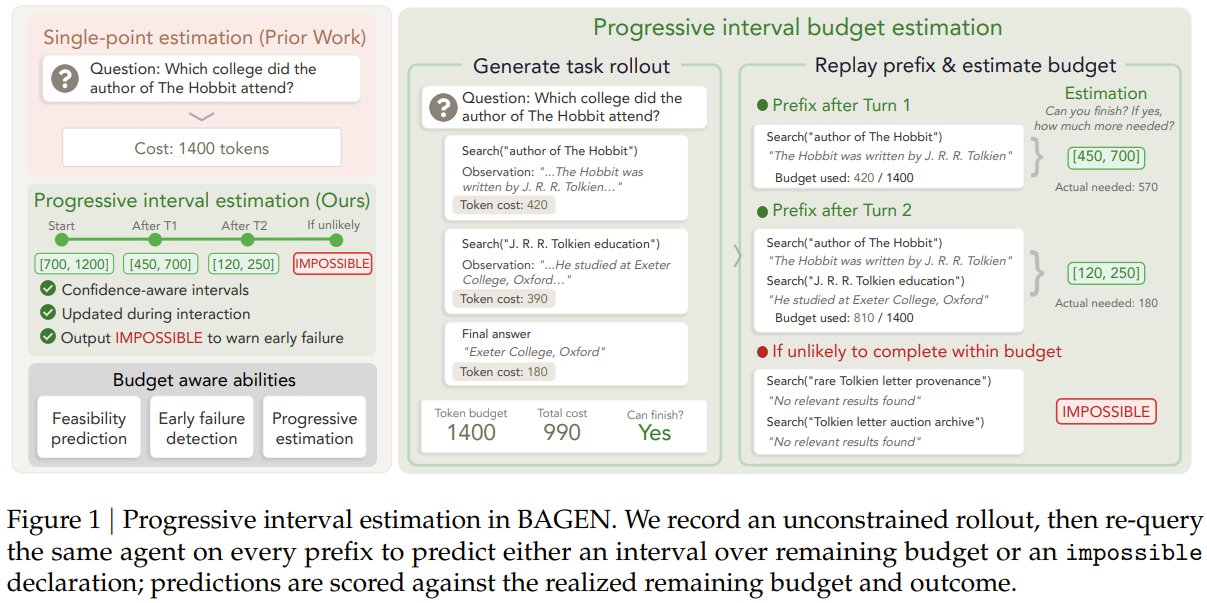
AI agents learn to predict remaining budget intervals to avoid waste
By
–
Can AI agents learn to stop wasting resources on doomed tasks? Researchers from Northwestern, Michigan, Cornell, Stanford & others introduce BAGEN. It trains agents to predict remaining budget intervals and alert users early, instead of blindly overspending. Key results:
-
Run local models with agent harnesses like Codex or Claude Code
By
–
You can run local models at home and use any agent harness like Codex or Claude Code with them https://t.co/e5blwOYytx
— Ahmad (@TheAhmadOsman) 16 juin 2026You can run local models at home and use any agent harness like Codex or Claude Code with them
-
Deep Agents Part 2: Context Management
By
–
Deep Agents deep dive Part 2 | Context Management
— LangChain (@LangChain) 16 juin 2026
A <2 min explanation on one of the most important capabilities in the Deep Agents harness from @SydneyRunkle pic.twitter.com/tnIsx9aiLiDeep Agents deep dive Part 2 | Context Management A
-
Beautiful summer model, fat but sparse family, early access in July
By
–
First of all, we have a beautiful model arriving this summer – we hope it will delight and surprise with some abilities. It will be the beginning of a new family of models, fat indeed, but sparse. We are opening an early access program in July for the
-
NVIDIA Blackwell platform dominates MLPerf Training 6.0 benchmarks
By
–
The NVIDIA Blackwell platform just swept MLPerf Training 6.0, delivering fastest performance and largest scale.
— NVIDIA (@nvidia) 16 juin 2026
Beyond the benchmarks, capabilities like the Reliability, Availability, and Serviceability Engine and NVIDIA Resiliency Extension deliver fewer interruptions and… pic.twitter.com/QH77j4UA8nThe NVIDIA Blackwell platform just swept MLPerf Training 6.0, delivering fastest performance and largest scale. Beyond the benchmarks, capabilities like the Reliability, Availability, and Serviceability Engine and NVIDIA Resiliency Extension deliver fewer interruptions and
-

Transfer Learning Book: 390 Pages on Adaptive Systems
By
–
TRANSFER LEARNING book [390 pages]: http://
amzn.to/3R4G0zm Amazon Summary:
"Transfer learning deals with how systems can quickly adapt themselves to new situations, tasks and environments. It gives machine learning systems the ability to leverage auxiliary data and models to