#MachineLearning with R — Techniques for building & improving #ML models, from data preparation to model tuning, evaluation, & working with big data (4th Edition. Huge 762 pages) available at https://
amzn.to/45sDq98 ————
#Rstats #DataScience #Analytics #DataScientist
MACHINE LEARNING
-
Machine Learning with R: Complete Guide to Model Building and Tuning
By
–
-
XGBoost for Regression, Predictive Modeling, and Time Series Analysis
By
–
XGBoost for Regression, Predictive Modeling, and Time Series Analysis — Learn how to build, evaluate, & deploy predictive models: http://
amzn.to/4l2YcU9 v/ @PacktDataML —
My review: XGBoost is definitely the focal point and central contribution of this book, along with all -
Python Feature Engineering Cookbook 3rd Edition Released
By
–
3rd Edition! "Python Feature Engineering Cookbook", complete guidebook with recipes for crafting powerful features for #MachineLearning models: http://
amzn.to/4rDWUT9 by @Soledad_Galli Her course: https://
trainindata.com/p/feature-engi
neering-for-machine-learning
…
——
#AI #ML #DataLiteracy #DataScience #DataScientist -
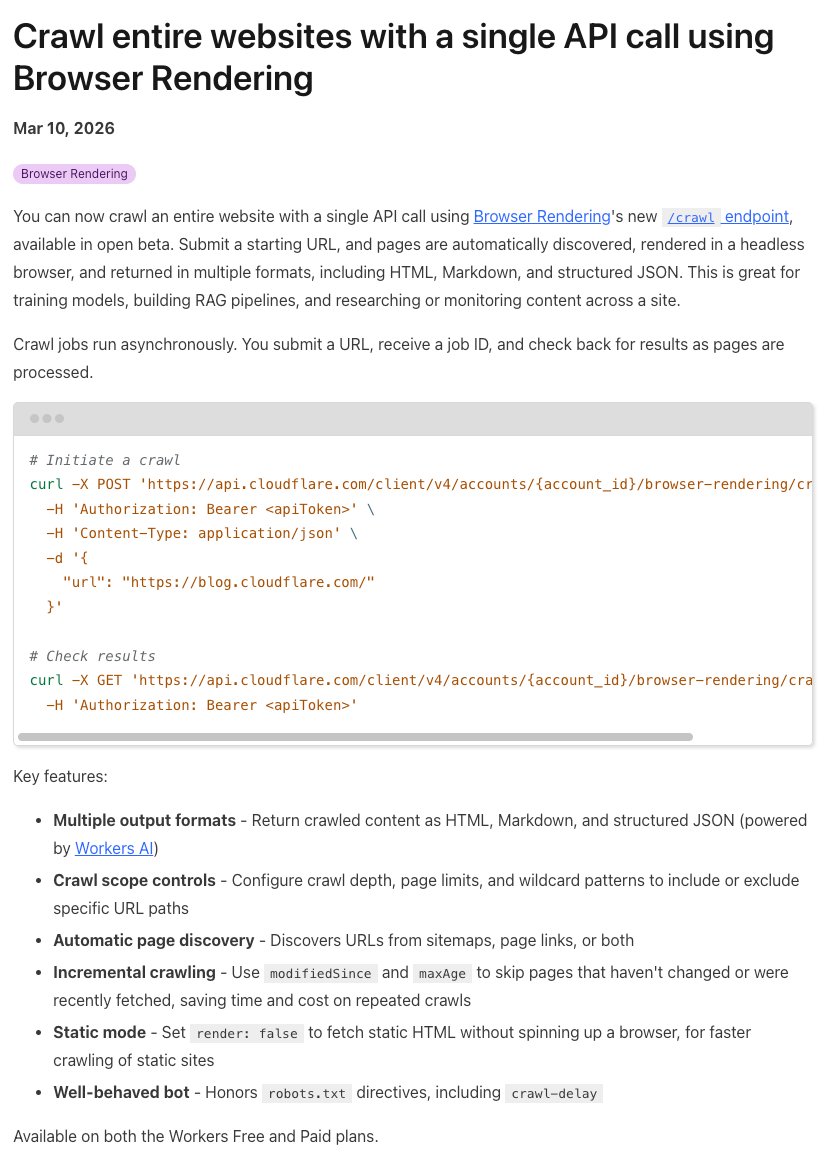
Cloudflare introduces new crawler endpoint for AI training and RAG
By
–
You just initiate a crawl job with just a URL to get a job ID back. Simply poll or wait for the results. It’s ace for training models, RAG, research, and even monitoring content More about @Cloudflare
's new `/crawl` endpoint here:
→ https://
developers.cloudflare.com/changelog/post
/2026-03-10-br-crawl-endpoint/
… -
Explaining why AI’s ability to condense information is the future we need
By
–
C’est le futur dont nous avons besoin, mais la plupart des gens qui ne comprennent pas comment fonctionne l’IA ne comprendront pas pourquoi.
— Defend Intelligence (Anis Ayari) (@DFintelligence) 11 mars 2026
Donc laissez-moi vous expliquer rapidement.
L’IA générative a pris une telle puissance parce qu’on a trouvé un moyen de mieux “condenser”… https://t.co/wcdfvTurG3This is the future we need, but most people who don’t understand how AI works won’t understand why. So let me explain it to you quickly. Generative AI has gained such power because we’ve found a way to better “condense” information and, above all, to learn this condensation
-
Flash Attention 4: Advanced AI Model Optimization
By
–
Paper: https://
github.com/Dao-AILab/flas
h-attention/blob/main/assets/fa4_paper.pdf
…
Code: https://
github.com/Dao-AILab/flas
h-attention
… Our report: https://
mp.weixin.qq.com/s/b0npsCoBPrbE
GhvadM-n_A
… -
Paged Attention: Kernel Level Overhead vs. System-Wide Throughput Gain
By
–
Good writeup. Here's an interesting fact about paged attention: It isn't free at the kernel level. As expected, the non-contiguous memory reads add roughly 20-26% overhead per attention kernel call. But the system-wide gain (2-4x throughput) overshadows that because you can
-
AI Optimizes Delivery Routes for Remote Community Support
By
–
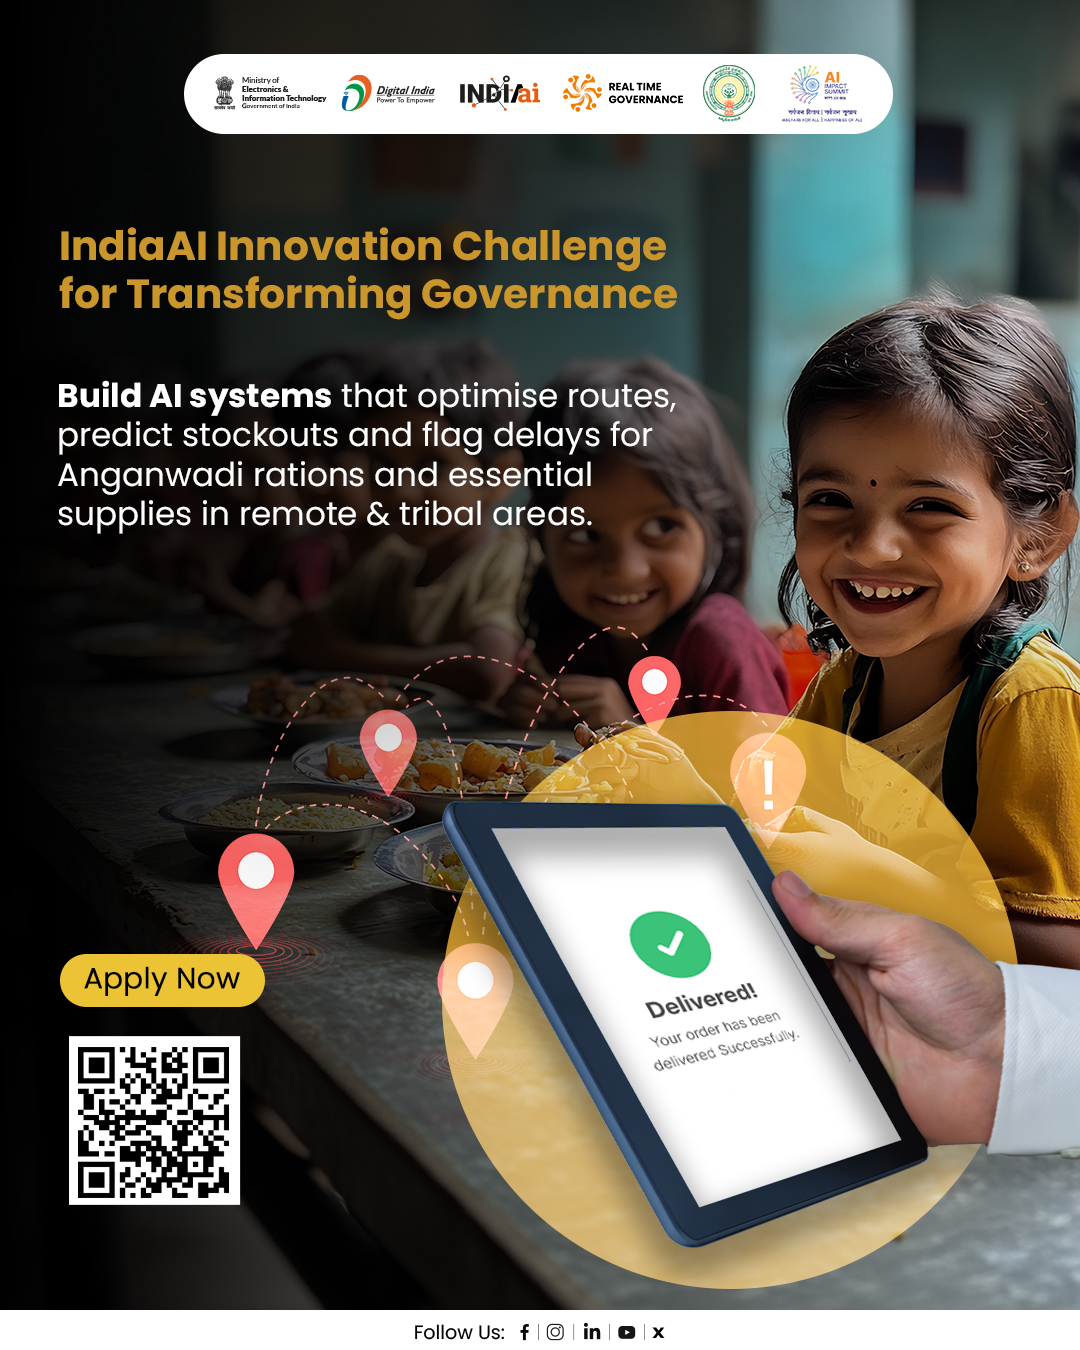
Imagine AI systems that can optimise delivery routes, predict stockouts, and flag delays for Anganwadi rations and essential supplies, ensuring timely support reaches remote and tribal communities. The IndiaAI Innovation Challenge for Transforming Governance invites innovators
-
Safe Robotic Arms: Passive Torque Control Framework
By
–
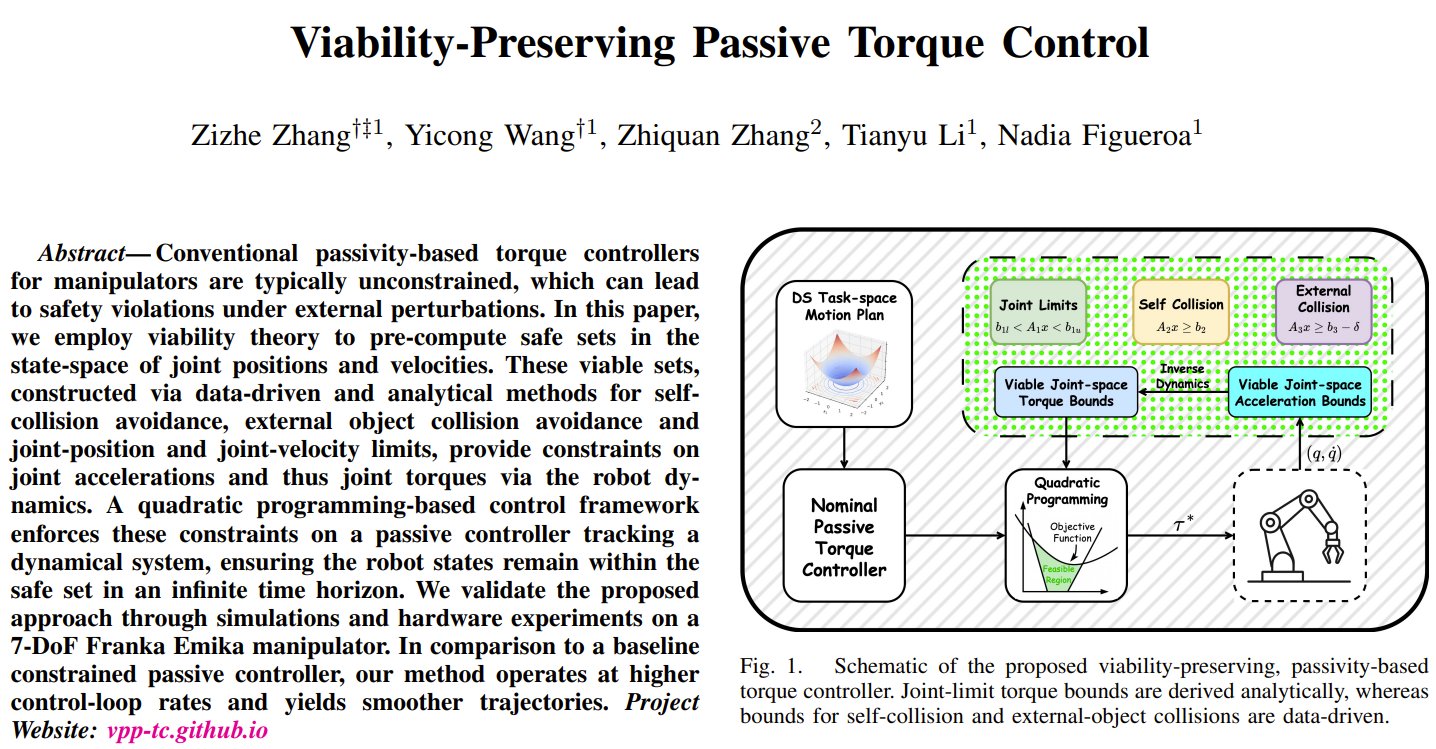
How can we ensure robotic arms never crash, even when hit by unpredictable external forces? Researchers at University of Pennsylvania & UIUC present a new framework for viability-preserving passive torque control. By pre-calculating safe zones for joint movement and speed, the
-
AI Engineers Reinventing Data Engineering Without Historical Knowledge
By
–
somewhat unsure if ai engineers not knowing anything about the last 10 years of data engineering and slowly having to reinvent everything from first principles is a good or bad thing