Yes. For one, “Bayesian inference” is not Bayesian. Every (frequentist) n-gram model uses Bayes’ theorem. For another, LLMs have high capacity and are trained to minimize cross-entropy, which is equivalent to maximizing likelihood, so it’s not surprising they produce accurate
MACHINE LEARNING
-
General-Purpose Humanoid Robot with Unified Brain Architecture
By
–
"One Brain for Diverse Uses" General-Purpose Humanoid #Robot
— Ronald van Loon (@Ronald_vanLoon) 19 mars 2026
via @ZappyZappy7
#Robotics #Tech #Engineering #Innovation #RPA pic.twitter.com/7DoPqUssRp"One Brain for Diverse Uses" General-Purpose Humanoid #Robot
via @ZappyZappy7 #Robotics #Tech #Engineering #Innovation #RPA -
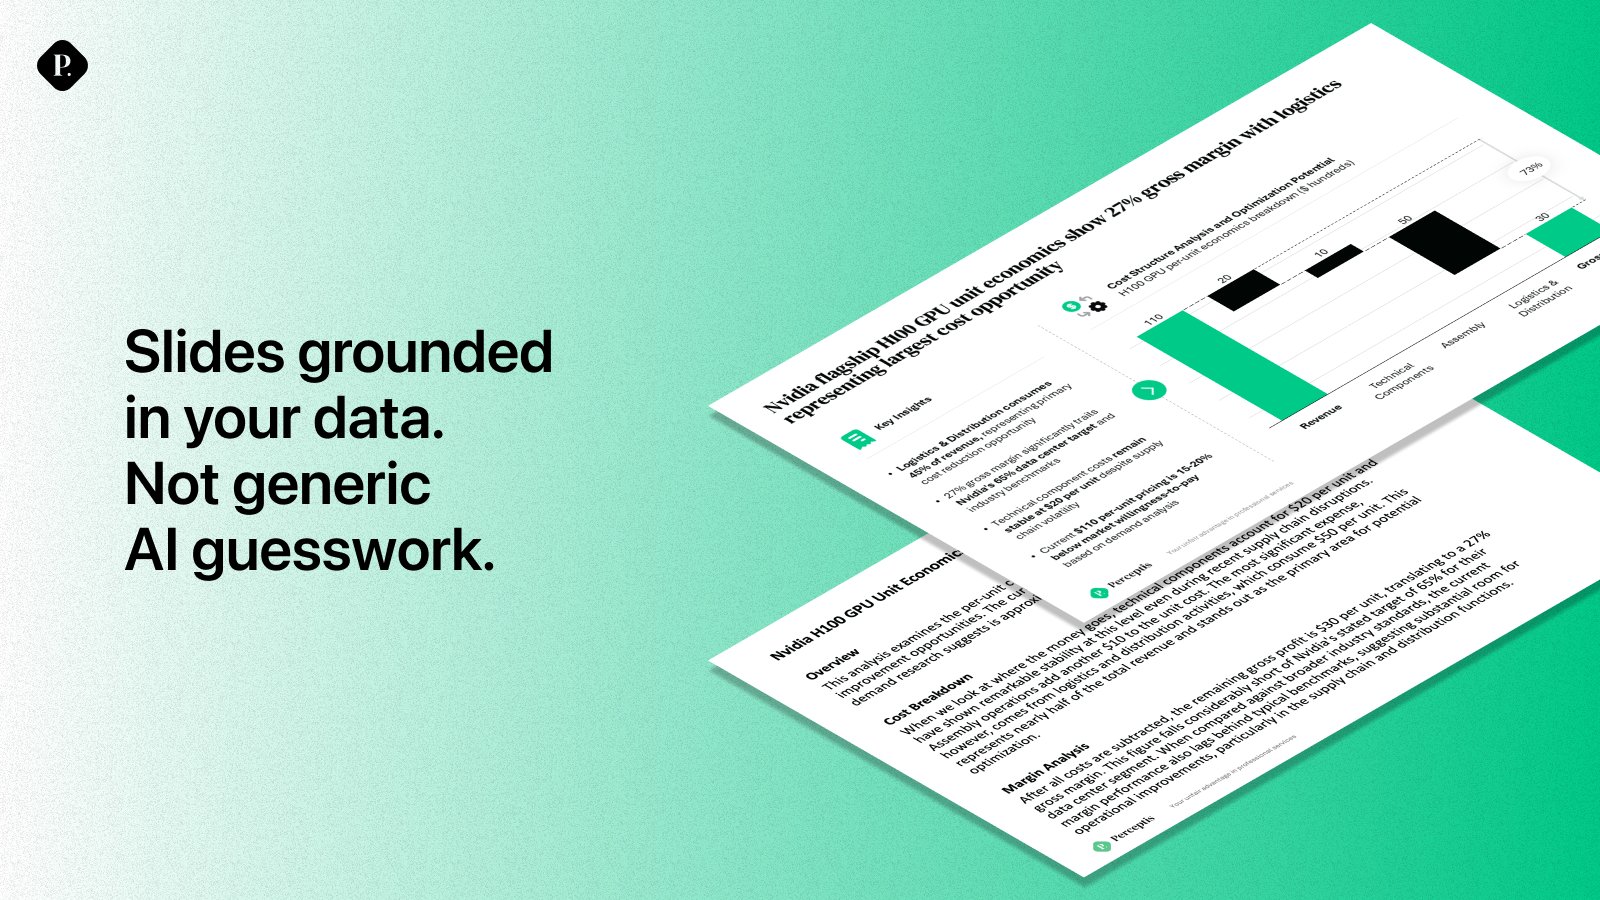
AI connects to company knowledge base, learns tone and methodology
By
–
it also connects to your company's knowledge base and learns your tone and methodology over time. built by ex-McKinsey, Big Four, and ex-Apple AI.
-
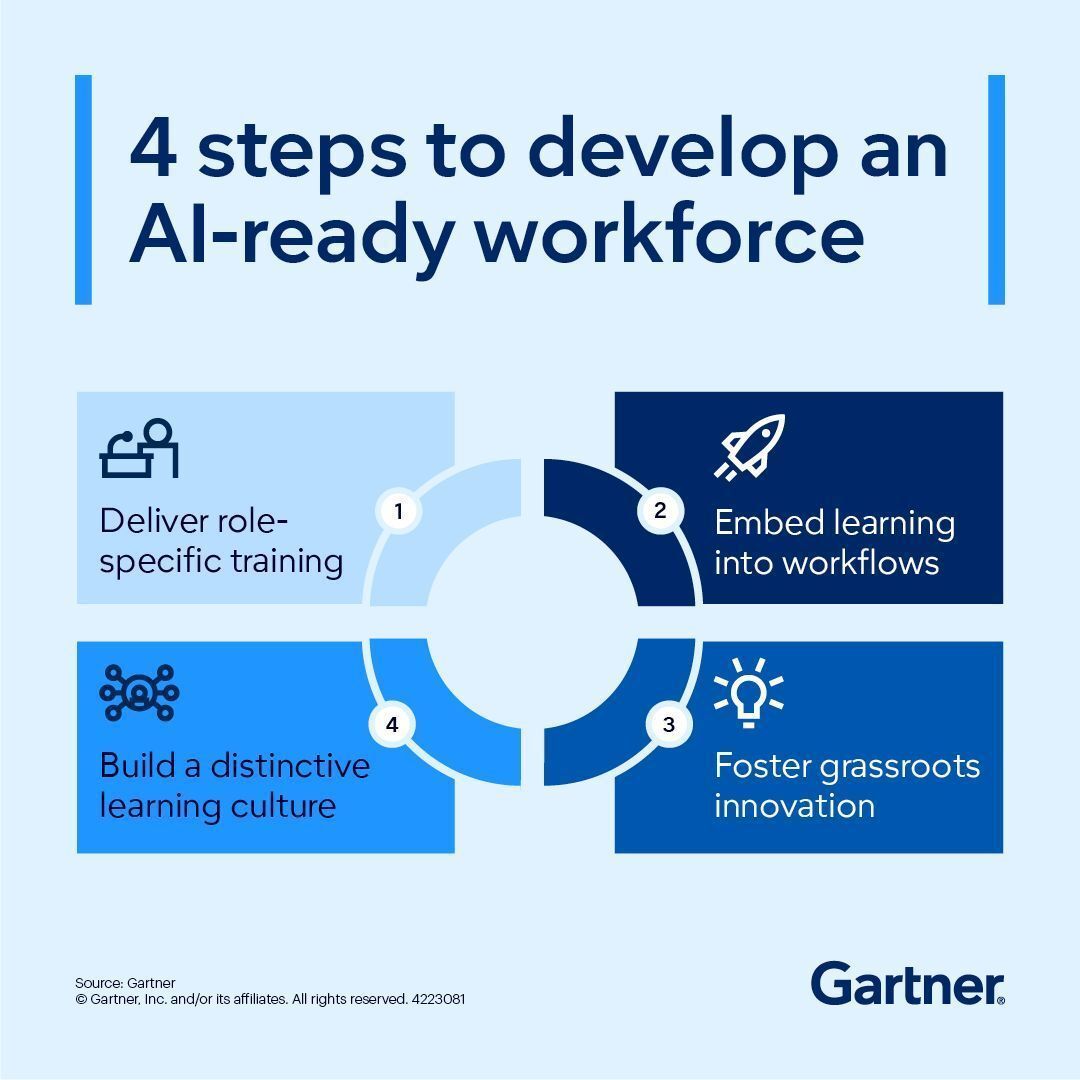
Four Steps to Develop an AI-Ready Workforce
By
–
4 Steps to develop an #AI-ready workforce
by @Gartner_inc #ArtificialIntelligence #MachineLearning #ML -
TRON 1 Robot Enhanced with 3D Perception for Better Navigation
By
–
TRON 1 Upgraded with #3D Perception Kit for Smarter Navigation and Terrain Mastery
— Ronald van Loon (@Ronald_vanLoon) 19 mars 2026
by @CyberRobooo
#Robotics #AI #ArtificialIntelligence #MachineLearning #RPA #ML #MI pic.twitter.com/aVBBvebdguTRON 1 Upgraded with #3D Perception Kit for Smarter Navigation and Terrain Mastery
by @CyberRobooo #Robotics #AI #ArtificialIntelligence #MachineLearning #RPA #ML #MI -
AI5 punches above its weight thanks to co-designed AI stack
By
–
AI5 will punch far above its weight, because the entire Tesla AI software stack is designed to make maximally effective use of every circuit. We co-signed our AI software and hardware. Bear in mind that AI5, while it can be used for training in data centers, is primarily
-
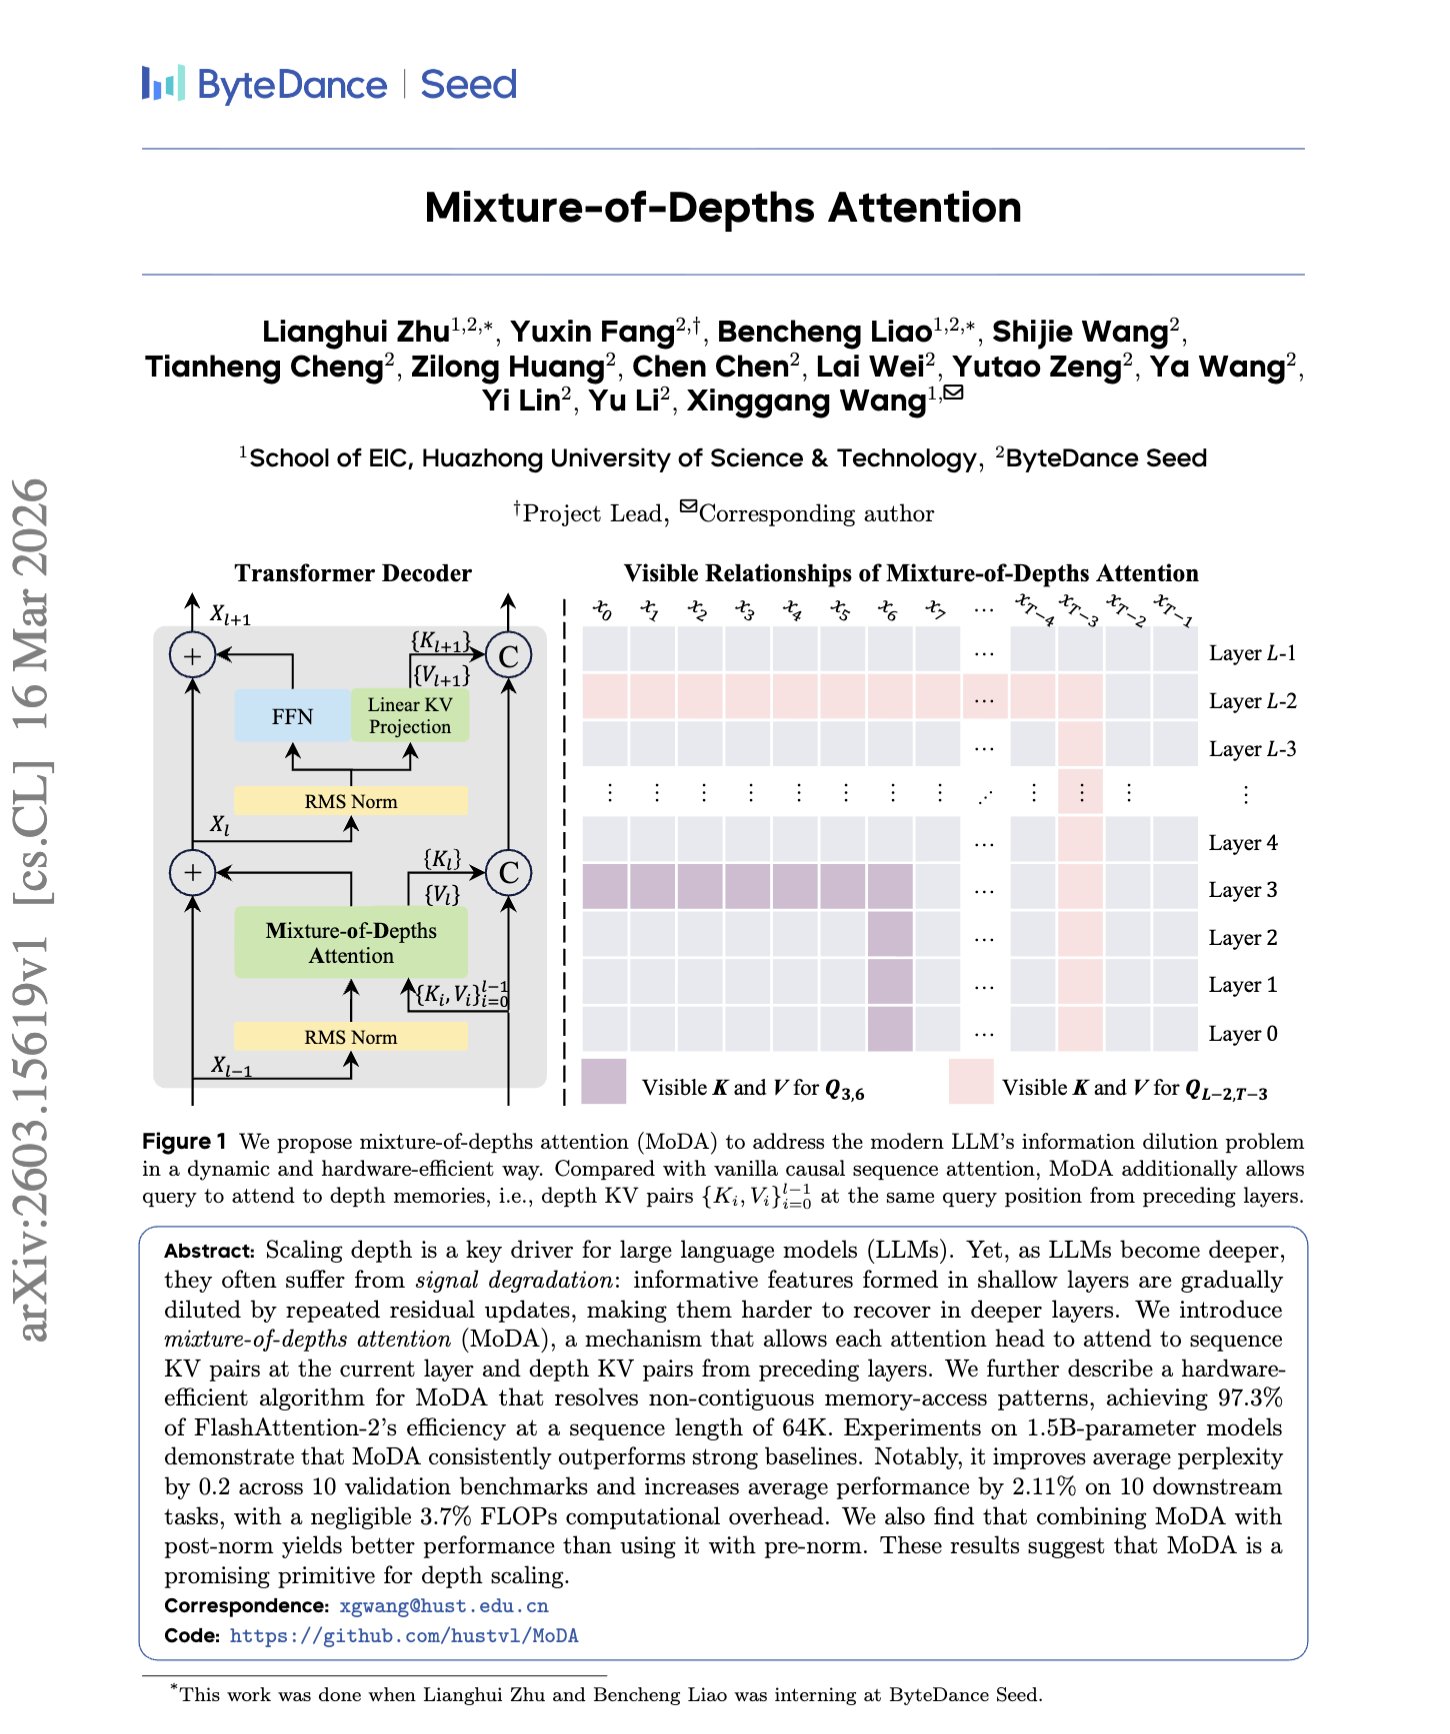
Mixture-of-Depths Attention: Transformer Architecture Innovation
By
–
"Mixture-of-Depths Attention" This paper teaches a Transformer to attend not just across tokens, but also to depth KV from its earlier layers. That helps recover shallow-layer signals that standard residual stacking tends to dilute, improving performance with only a small extra
-
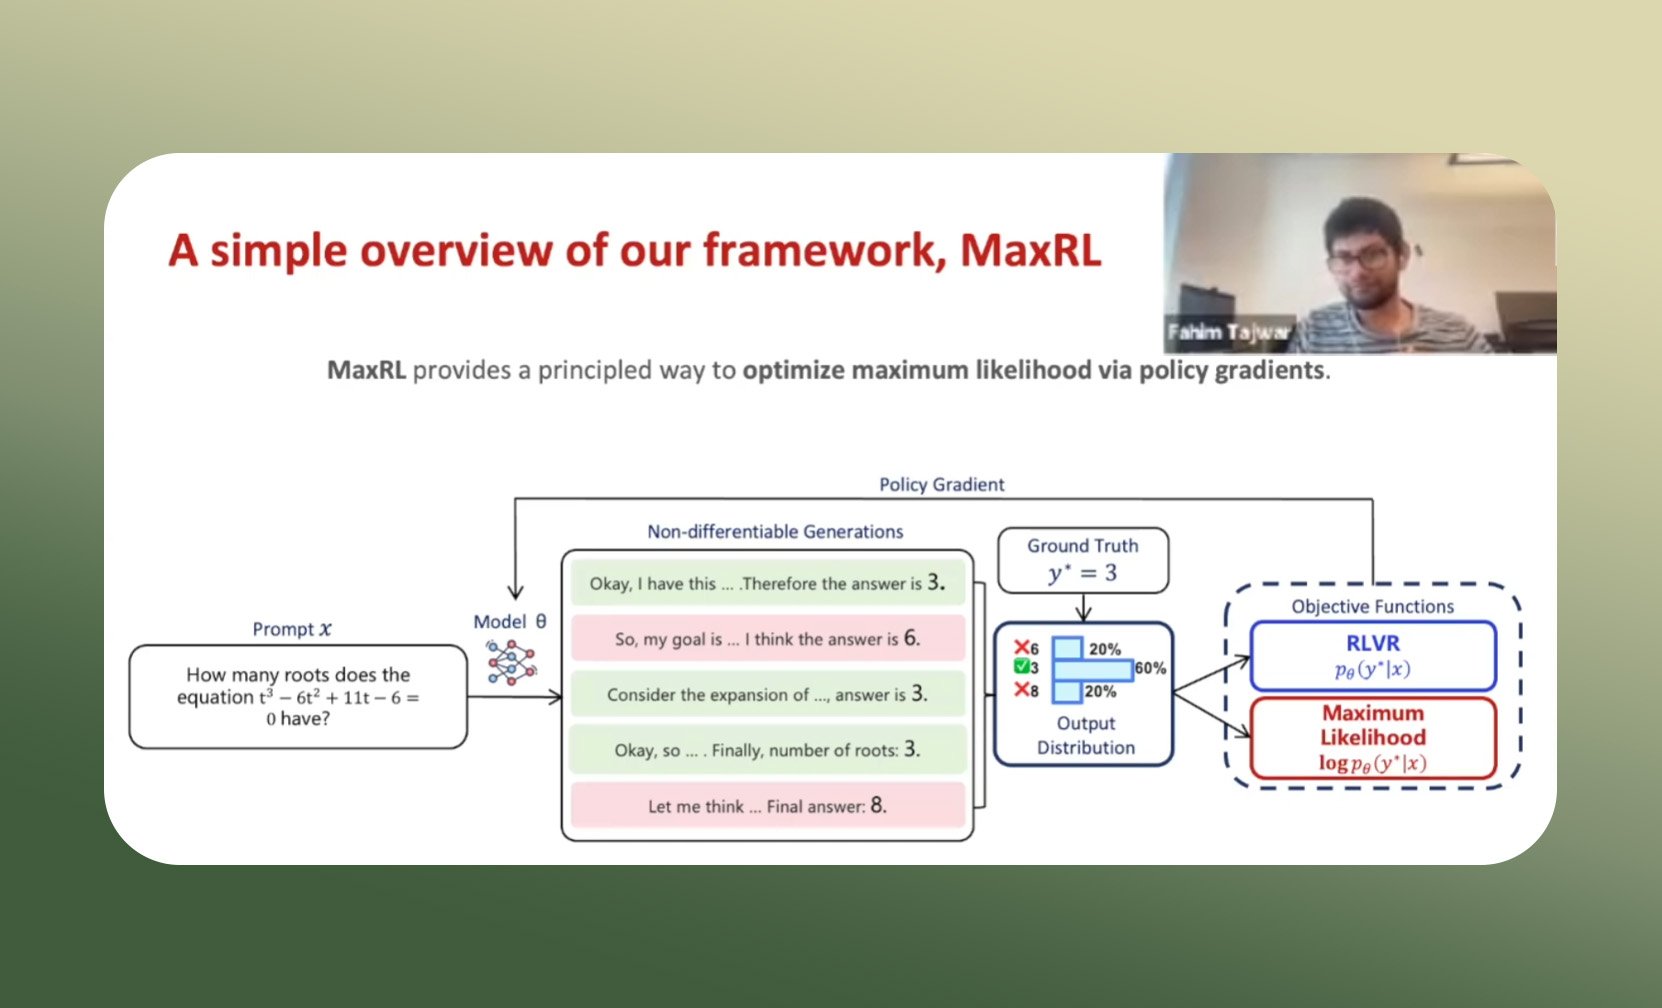
Maximum Likelihood RL Framework for Math Reasoning Models
By
–
The current RL setup might not be the right objective for reasoning models In our latest AI4Science talk, Fahim (
@FahimTajwar10
), PhD student at CMU, presented “Maximum Likelihood Reinforcement Learning”, a new framework for binary-reward tasks like math reasoning, navigation, -
Robot Hand with Bidirectional Bending Achieves Superhuman Dexterity
By
–
This #Robot Hand Bends Both Ways — Unlocking Superhuman Dexterity
— Ronald van Loon (@Ronald_vanLoon) 19 mars 2026
via @ZappyZappy7#AI #Robotics #MachineLearning #ArtificialIntelligence #ML #MI pic.twitter.com/vw1PyDRGmhThis #Robot Hand Bends Both Ways — Unlocking Superhuman Dexterity
via @ZappyZappy7 #AI #Robotics #MachineLearning #ArtificialIntelligence #ML #MI -
Attention Head as a Differentiable Multiplexer
By
–
An attention head is a differentiable multiplexer.