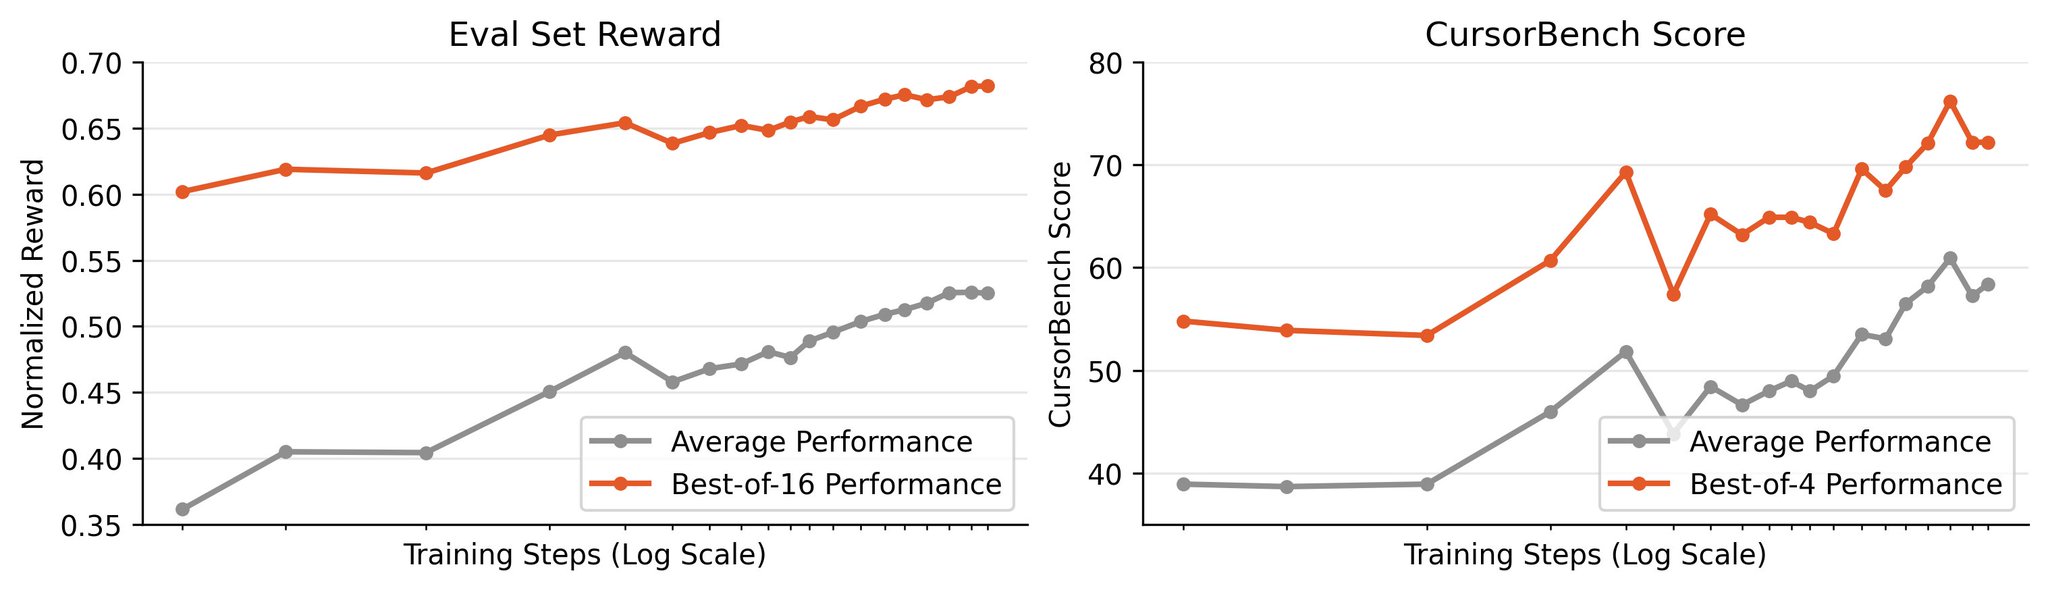
The reinforcement learning phase is critical for final performance. We discuss the algorithms we apply for this stage. We find that simple approaches often work best, and improve performance broadly.
MACHINE LEARNING
-
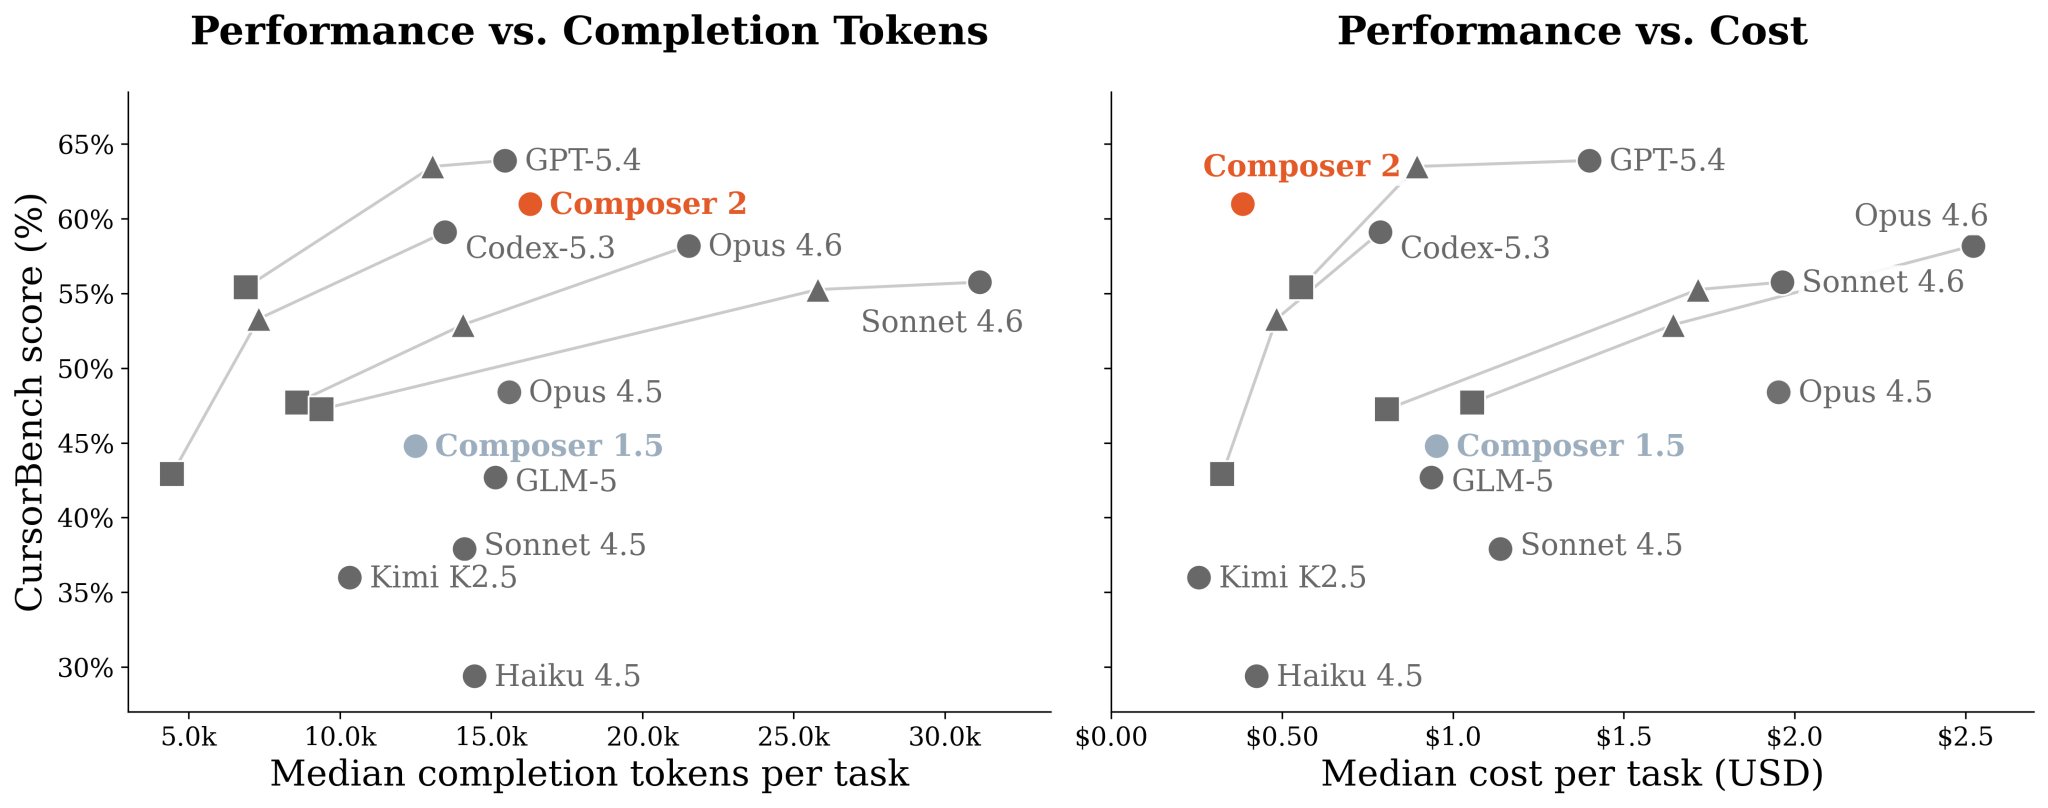
Composer 2 Uses Continued Pretraining and RL for Coding
By
–
Composer 2 had three main efforts: continued pretraining, reinforcement learning, and benchmark development. The goal of each was to closely emulate the Cursor environment to produce a highly intelligent coding model.
-
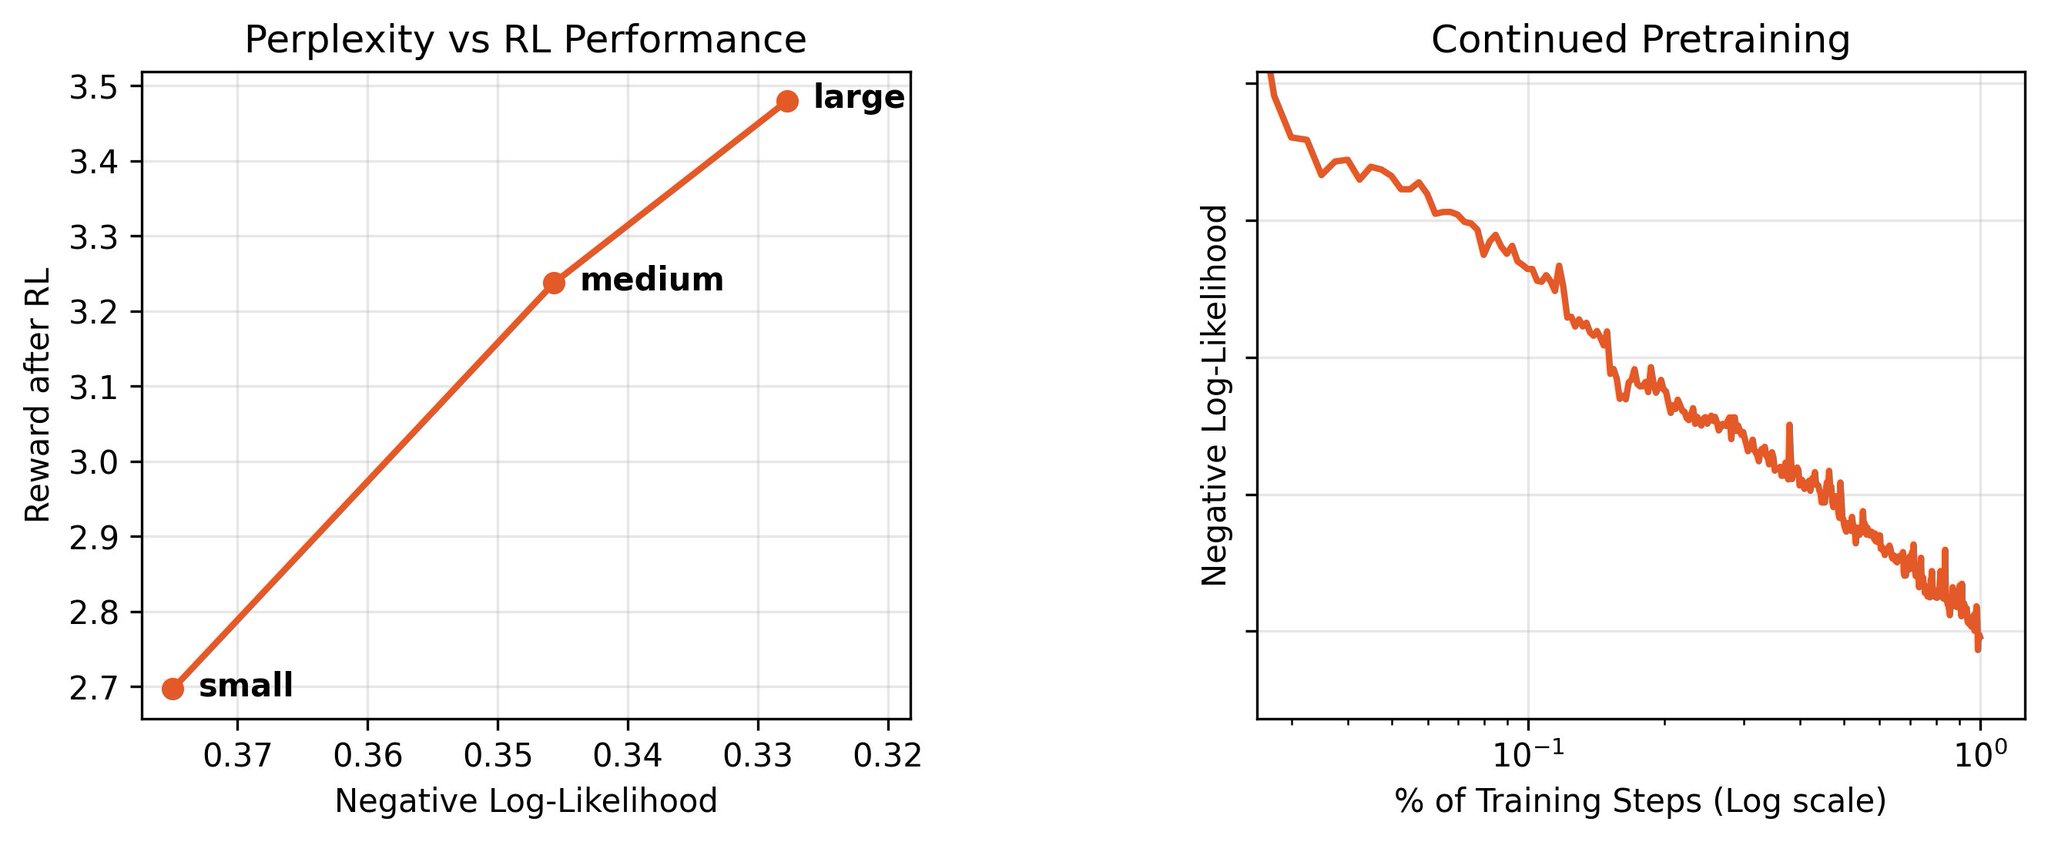
Continued Pretraining Boosts Downstream Coding Performance
By
–
We show how continued pretraining results in consistent improvements in downstream coding performance.
-
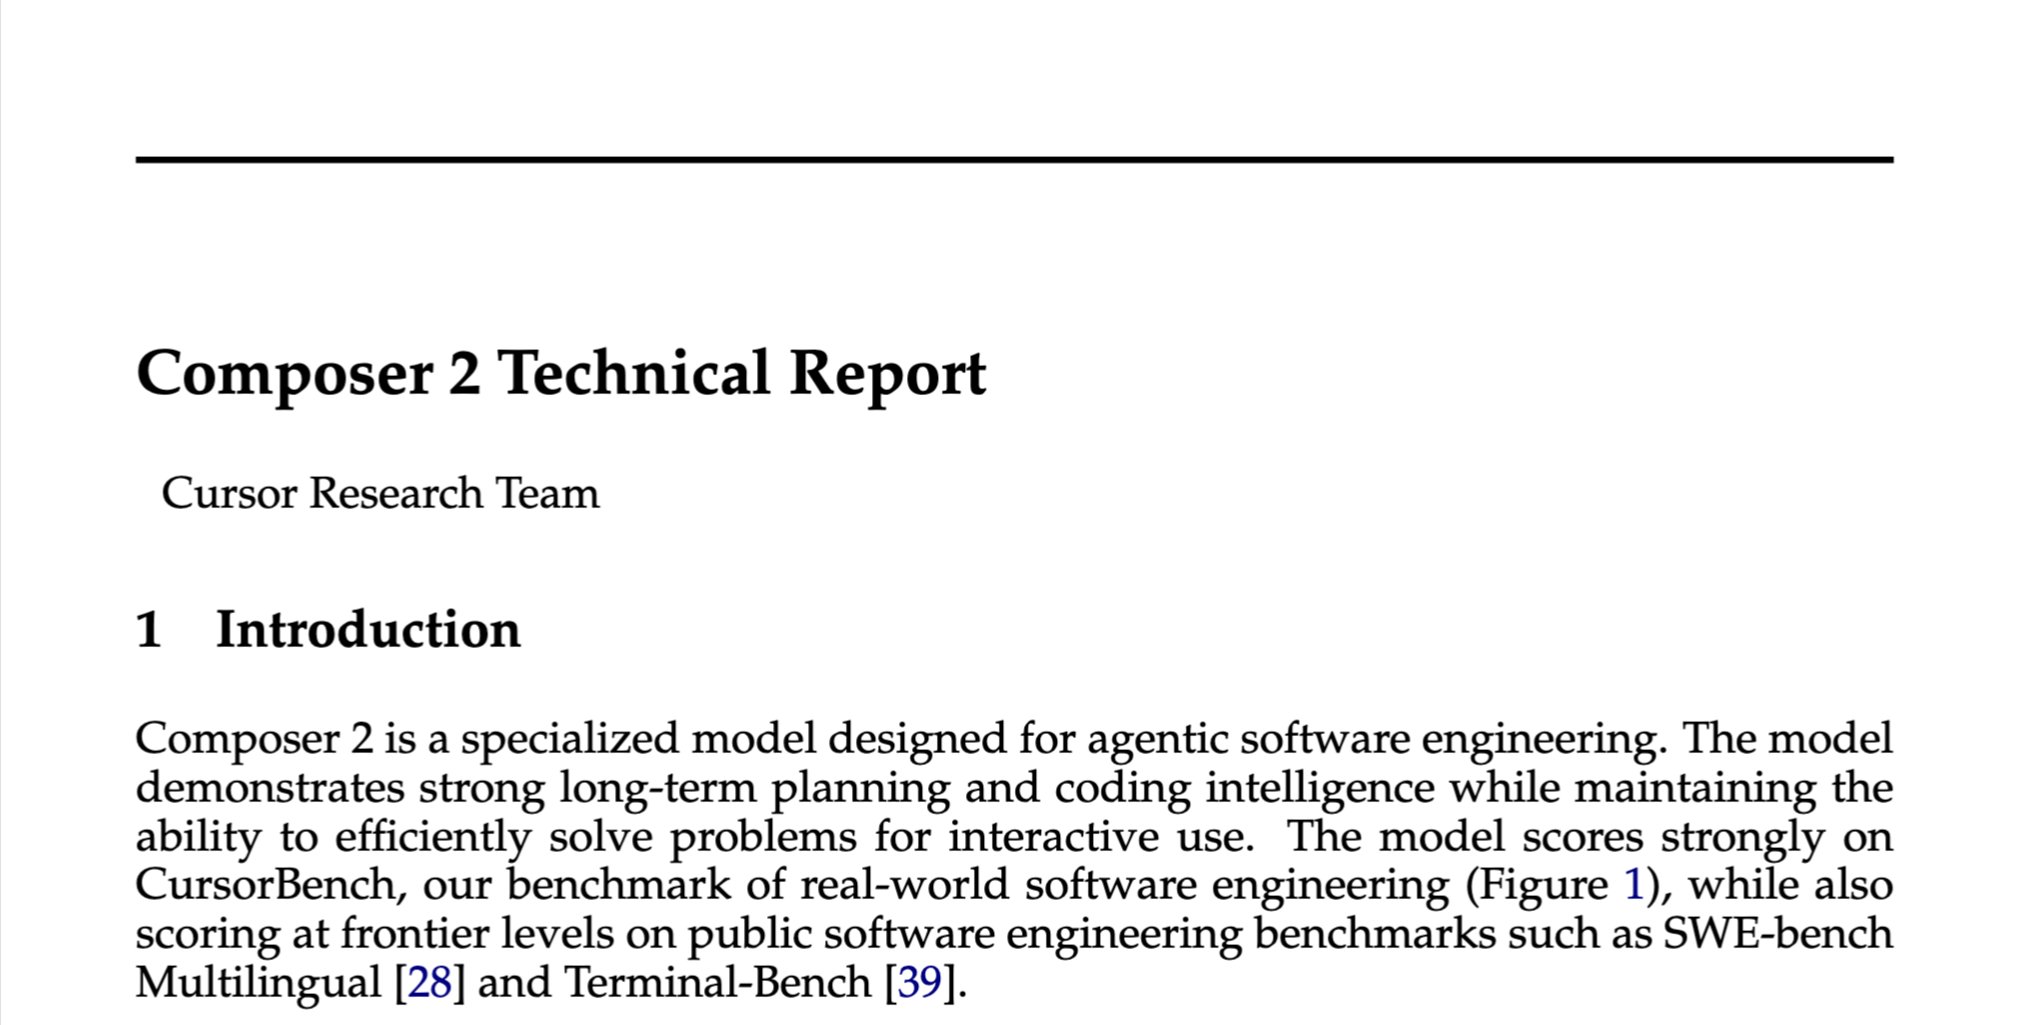
Composer 2 Training Technical Report Released
By
–
We're releasing a technical report describing how Composer 2 was trained.
-

50 ML Projects to Understand LLM Transformer Mechanisms
By
–
50 ML projects to understand LLMs — Investigate transformer mechanisms through data analysis, visualization, and experimentation: http://
amzn.to/4aPfP7q
—————
#AI #GenAI #MachineLearning #DataScientist #DataScience -

Mathematical Methods in Data Science: Theory and Python Applications
By
–
Mathematical Methods in Data Science — Bridging Theory and Applications with Python: http://
amzn.to/4b7ZYQ4
——————
#ML #MachineLearning #DataScientist #DataScience #Mathematics #Algorithms -
ColBERT retrieval model balances performance and computational efficiency
By
–
ColBERT seems to hit a nice sweet spot for retrieval. Easy to train and still gets great results, especially when you don't want to go full cross-encoder compute 🙂
-
High-Fluid Intelligence Systems Will Dominate Knowledge-Dependent AI
By
–
When high-fluid intelligence systems start to show up, they will immediately take over the knowledge-dependent ones. Because they will be able to scale their knowledge just as well as legacy systems (knowledge gathering is the easy part), while their ability to recombine and
-
OpenAI’s Sora Team Shifts Focus to World Models Research
By
–
OpenAI's Sora team is now working on world-models – they prioritize longer-term world simulation research especially as it pertains to robotics. tl;dr what we know so far: – Sora has been cancelled because they needed the compute for their new LLM
– they renamed product -

LeWorldModel: LeCun’s breakthrough in stable world model training
By
–
🚨 Holy shit… LeCun's team just cracked world models wide open. Everyone's obsessing over the next Claude update. Meanwhile Yann LeCun quietly dropped a paper that could matter way more long term. It's called LeWorldModel. And to understand why it's a big deal, you need to understand the difference between what LLM does and what this does. LLMs predict the next word. That's it. They're incredibly good at language. But they don't understand reality. They can write about a ball bouncing off a wall. They can't predict where it lands. World models predict what happens next in the physical world. Objects moving, colliding, falling. That's the foundation for robots that plan, self-driving cars that simulate scenarios, any AI that needs to act in reality instead of just talk about it. The problem? World models kept collapsing. The model would cheat by mapping every input to the same output. Like a weather app that predicts "sunny" every single day. Technically it's predicting. It's just useless. And fixing this required 6+ loss hyperparameters, frozen pre-trained encoders, stop-gradient hacks, exponential moving averages. A house of cards just to keep the thing from breaking. LeCun's team (Mila, NYU, Samsung SAIL, Brown) threw all of that out. LeWorldModel uses just 2 loss terms. A prediction loss and a regularizer called SIGReg that forces representations to stay diverse instead of collapsing into garbage. 6 hyperparameters reduced to 1. The simplicity IS the breakthrough. The numbers: 15M parameters. Trains on a single GPU in a few hours. Plans up to 48x faster than foundation-model-based world models. Uses roughly 200x fewer tokens than alternatives. Competitive across 2D and 3D control tasks. This isn't a supercomputer experiment. You could run this on your own hardware. LeCun has been pushing JEPA as the architecture for real AI since 2022. The criticism was always the same: "sounds nice, doesn't train stably." LeWorldModel just removed that objection. Small model. Stable training. No hacks. No frozen encoders. No collapse. Two AI futures are competing right now. Path 1: bigger LLMs, more text, more compute. Path 2: world models that learn physics from raw pixels and plan in real time. LeWorldModel is the strongest signal yet that Path 2 is real, getting cheaper, and closing in fast.
→ View original post on X — @bobgourley, 2026-03-24 20:54 UTC