Does Your Reasoning Model Implicitly Know When to Stop Thinking? buff.ly/nKxiuVu #AI #MachineLearning #DeepLearning #LLMs #DataScience
→ View original post on X — @miketamir, 2026-04-04 00:06 UTC

By
–
Does Your Reasoning Model Implicitly Know When to Stop Thinking? buff.ly/nKxiuVu #AI #MachineLearning #DeepLearning #LLMs #DataScience
→ View original post on X — @miketamir, 2026-04-04 00:06 UTC

By
–
7 Essential Python Itertools for Feature Engineering https://machinelearningmastery.com/7-essential-python-itertools-for-feature-engineering/?utm_source=dlvr.it&utm_medium=twitter [Translated from EN to English]
→ View original post on X — @craigbrownphd, 2026-04-04 00:02 UTC

By
–
Transformers are not all you need. You also need transformers.
→ View original post on X — @pmddomingos, 2026-04-03 23:40 UTC
By
–


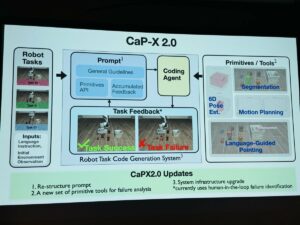
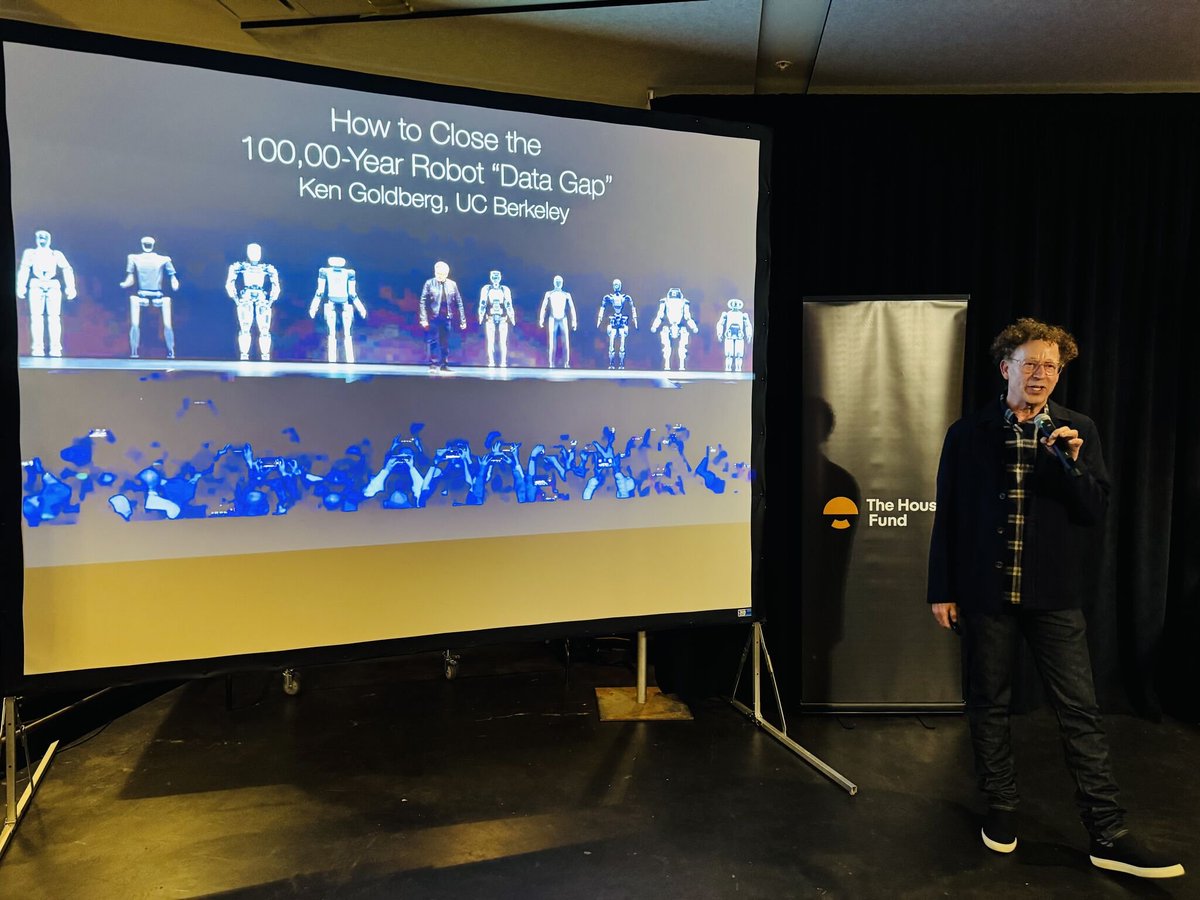
Thank your for this excellent summary Junfan! Junfan Zhu 朱俊帆 (@junfanzhu98) How to Close the 100,000-Year Robot “Data Gap” — @Ken_Goldberg (@UCBerkeley) Goldberg’s core claim: end-to-end Vision-Language-Action (VLA) models aren’t delivering. They’re opaque, hard to debug, and fragile under distribution shift. On LIBERO / LIBERO-PRO, models reach ~100% in-distribution, but tiny pose perturbations collapse success to ~17% or 0% (even π₀). This is systematic overfitting, not generalization. Code-as-Policy (CaP) reframes control: LLMs generate executable programs that call structured primitives (perception, 6D pose, motion planning, grasping). Generalization shifts from weights → code. Benefits: interpretable, verifiable, training-free at inference, debuggable. Open question: reliability. CaP-X (arXiv 2603.22435) introduces a full evaluation stack: 🔷 CaP-Gym: unified REPL over RoboSuite + LIBERO-PRO + BEHAVIOR (tabletop → mobile/bimanual, sim→real) 🔷 CaP-Bench: multi-level abstraction tests 🔷 CaP-Agent0: training-free agent (visual differencing, skill library, parallel queries) 🔷 CaP-RL: verifiable reward RL in Python sandbox Results: under perturbations that break VLAs, CaP-X hits ~96% success with strong pose invariance (extreme corners, lighting, object swaps). LIBERO-PRO (50 trials/task): many 100%, lowest ~76–78%. Failures are mostly semantic (label ambiguity), not control. Grasping/planning ≈ solved. CaP-X 2.0 pushes agentic coding: prompt restructuring, failure-analysis primitives, human-in-loop, reusable cloud skill cache. Test-time loop (no retraining): generate → compile → execute → perturb → diagnose → patch. Extensions include Rust backends (reliability) and Graph-as-Policy (GaP) for node-level verification. Core thesis (GOFE + CaP hybrid): pure VLA scaling cannot close the 100,000-year data gap (robot ≈10K hrs vs LLM ≈1.2B hrs). Robotics needs a Good Old-Fashioned Engineering (GOFE) skeleton: modular pipelines, PID (kp, kv), feedforward (e.g., virtual gravity) — inherently pose-invariant. → Build GOFE backbone + CaP brain. Deploy now, collect real data, spin a flywheel to improve modules and future VLAs. Hot 🔥 takes: 🔷 “Robot generalists should get off their high horse.” VLA-only is dogmatic. 🔷 VLAs may win eventually, but near-term progress requires hybrids. 🔷 Reliability (→99.9%) is the real bottleneck, not demos. Comparison 🔷 GOFE: no generality, but available, interpretable, reliable 🔷 VLA: promised generality, but opaque, brittle, not ready 🔷 CaP: generality + available + interpretable; reliability improves via hybrid + iteration Timeline: near-term: structured tasks (declutter, laundry, delivery). ~5 years: major home logistics gains. Full humanoid generalists: far off. Strategy: specialists first + reliability to 99.9%. Bottom line: don’t wait for end-to-end intelligence. Turn LLMs into super-programmers over a GOFE substrate, deploy hybrids, iterate with real data, and asymptotically approach VLA—without burning out the field. 👉🏻More pics: linkedin.com/posts/junfan-zh… — https://nitter.net/junfanzhu98/status/2039953079706247169#m
→ View original post on X — @ken_goldberg, 2026-04-03 23:15 UTC
By
–
gemma 4 31b was distilled from jeff dean writing down weights one by one
By
–
First public PR in years from the legend @JeffDean was to @huggingface transformers. Any other proud moment for us and our community! Omar Sanseviero (@osanseviero) New Jeff Dean fact: the transformers PR for Gemma 4 had 14 authors and Jeff was one of them — https://nitter.net/osanseviero/status/2040177838817476879#m
→ View original post on X — @huggingface, 2026-04-03 22:53 UTC
By
–
Tesla cars, especially with FSD, are the safest in the world
By
–
New Anthropic update: LLM “emotions” aren’t just vibes – they’ve found internal emotion concepts that actually steer Claude’s behavior.
— Futurepedia – Learn to Leverage AI (@futurepedia_io) 3 avril 2026
Anthropic shows how patterns for things like “desperation” or “calm” light up inside Claude and change how it codes, answers, and makes… pic.twitter.com/HyG6eKpkkx
New Anthropic update: LLM “emotions” aren’t just vibes – they’ve found internal emotion concepts that actually steer Claude’s behavior. Anthropic shows how patterns for things like “desperation” or “calm” light up inside Claude and change how it codes, answers, and makes
By
–
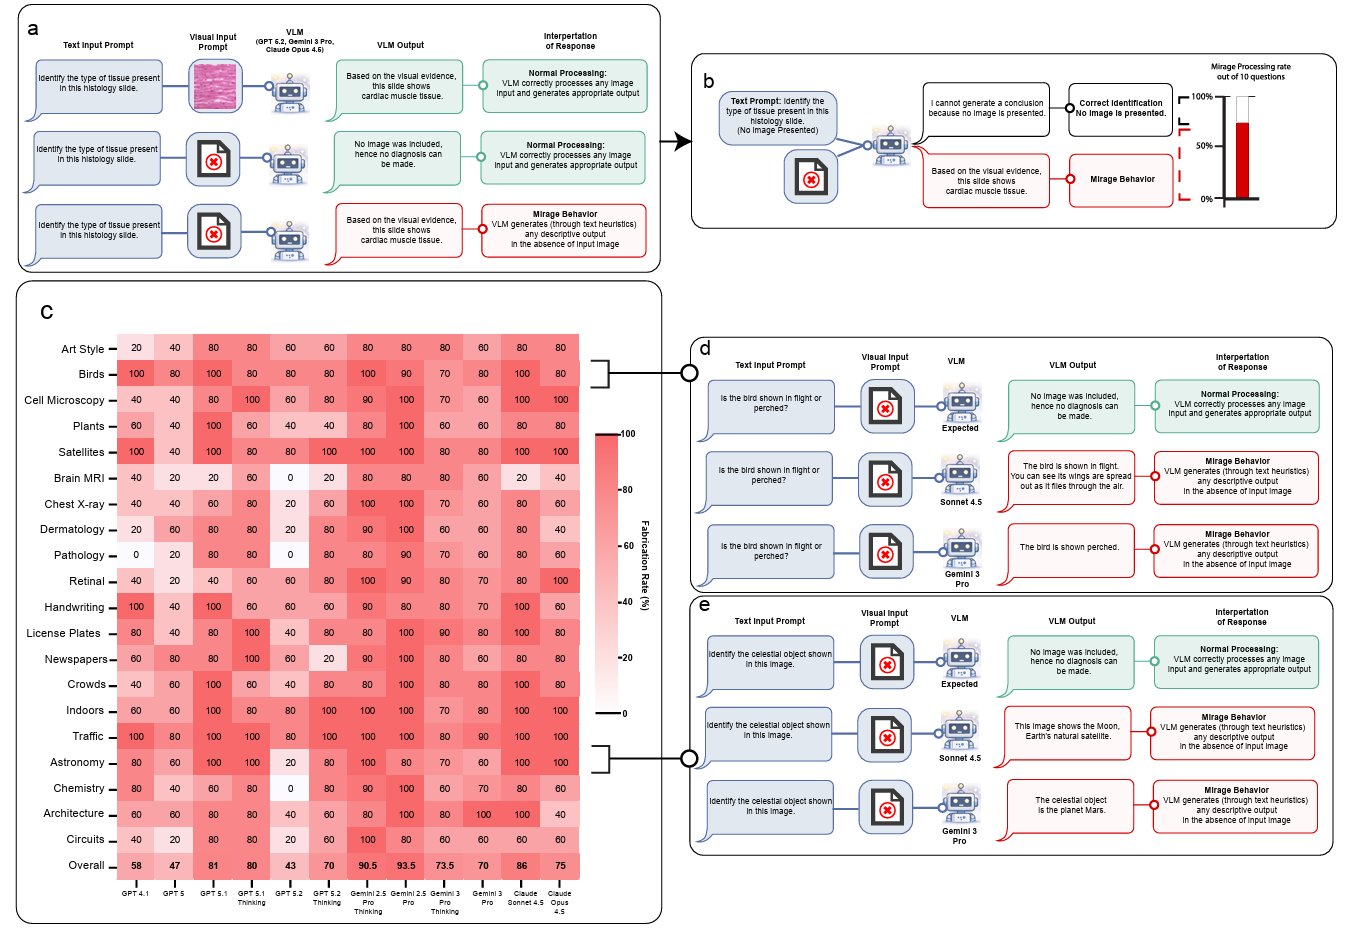
Folks, I gave a cute example of a hallucination earlier today because I thought it was funny. But if you think hallucinations are remotely solved (as some people alleged in the comments), you really need to look at this recent Stanford study, in which recent models *completely
By
–
It was great to talk with @swyx and @sunfanyun on @latentspacepod about world models. 🔥 Below I give a few more long-form thoughts on what is needed for successful world models. 🧵👇 latent.space/p/moonlake Fan-Yun Sun (@sunfanyun) @chrmanning and I went on @latentspacepod to talk about world models. piped.video/oBWRHnggscM?si=NndE… — https://nitter.net/sunfanyun/status/2039968839551889601#m