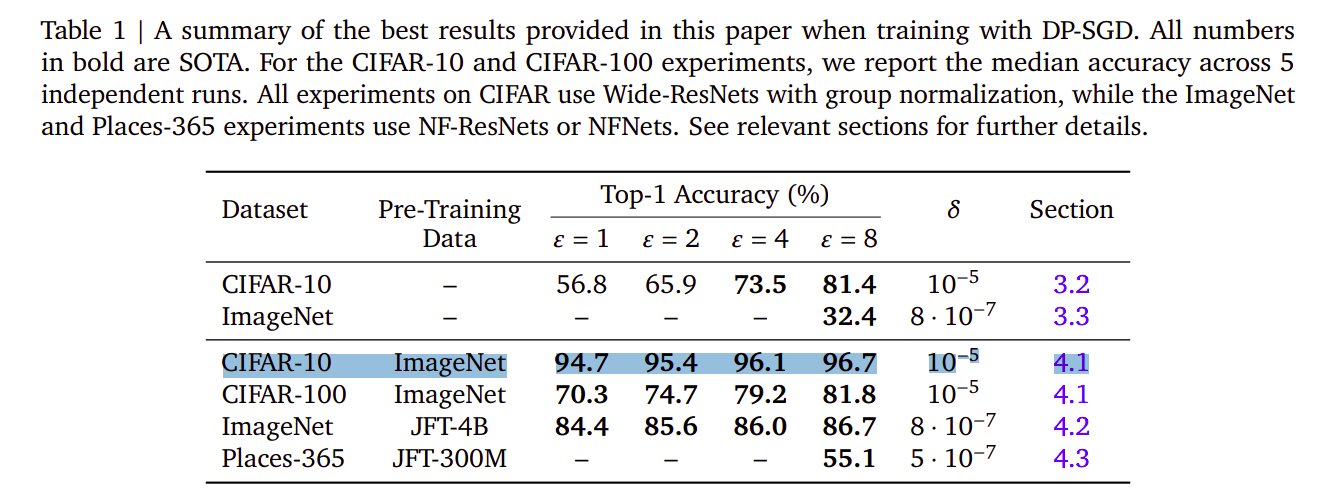
The good news is, public data can help dramatically! Pre-training on ImageNet (without privacy constraints) and fine-tuning on CIFAR-10 (privately) gets us up to 95%+ (figure from the same paper). Takes it from bad (and in some cases, unusable) to pretty good! 3/n
MACHINE LEARNING
-
Differential Privacy in ML: CIFAR-10 Performance Gap Challenge
By
–
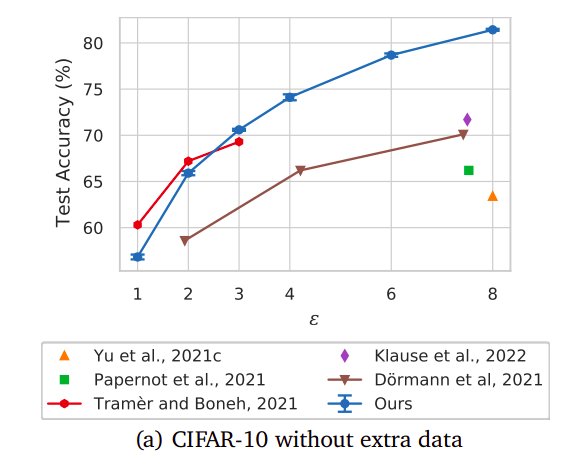
Differentially private ML is hard. Even basic "solved" tasks in the non-private setting are very hard to do with privacy. Figure from a nice paper by @sohamde_ @LeonardBerrada et al (
https://
arxiv.org/abs/2204.13650), showing SOTA results on CIFAR10.. 60-80%, versus 99%+ non-privately 2/n -
Differential Privacy Challenges in Large-Scale AI Pretraining
By
–
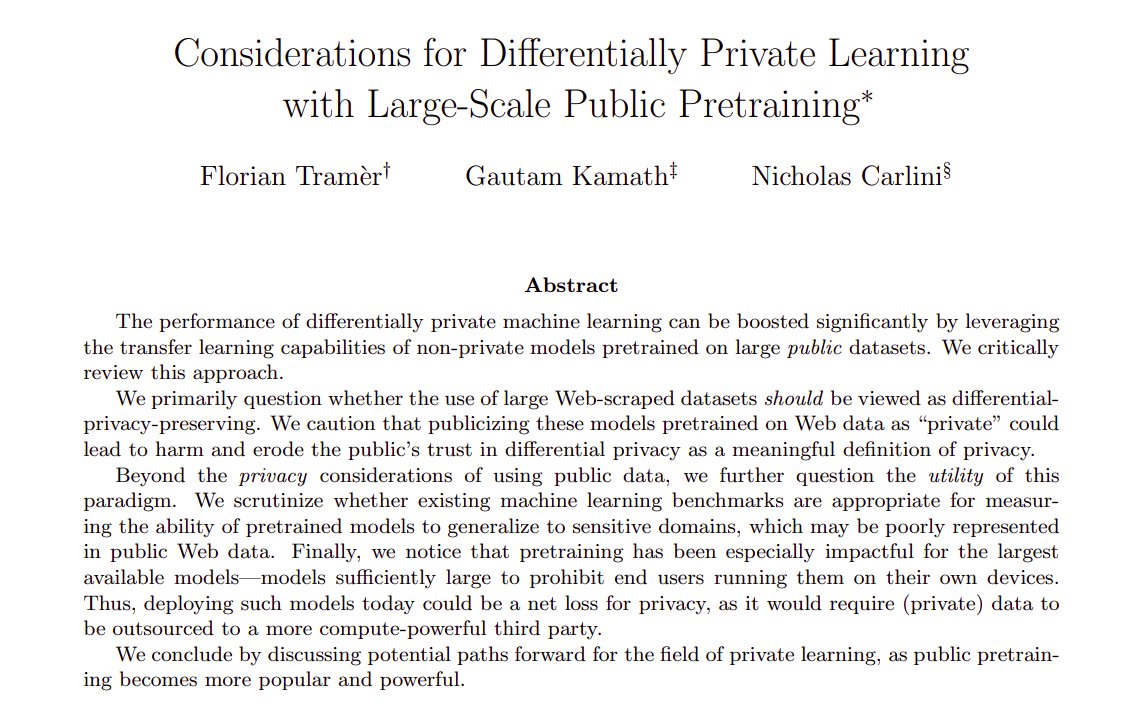
New paper w Nicholas Carlini & @florian_tramer
: "Considerations for Differentially Private Learning with Large-Scale Public Pretraining." We critique the increasingly popular use of large-scale public pretraining in private ML. Comments welcome. https://
arxiv.org/abs/2212.06470 1/n -
FairMOT: Solving Re-identification in Deep Learning Object Tracking
By
–
Most Deep Learning Multiple Object Trackers have no trouble with the detection task but perform poorly in the re-identification task. This is where FairMOT comes into the picture. Check out our read on Object Tracking with FairMOT.https://t.co/0x5fOXrG7N#fairmot #ai #ml #dl pic.twitter.com/z5YnJ1M14c
— Satya Mallick (@LearnOpenCV) 15 décembre 2022Most Deep Learning Multiple Object Trackers have no trouble with the detection task but perform poorly in the re-identification task. This is where FairMOT comes into the picture. Check out our read on Object Tracking with FairMOT. https://
learnopencv.com/object-trackin
g-and-reidentification-with-fairmot/
… #fairmot #ai #ml #dl -
Challenge Approach: Reimplementing Techniques from Foundations in Python
By
–
(Oh BTW personally for this challenge I'm following the "from the foundations" rules we're using for our current course: only using techniques I've first reimplemented from scratch in pure Python. But y'all can use external libs and stuff if you like…)
-
RLHF automates human evaluation and generates tuning data
By
–
Later, reinforcement learning was used to automate the task of human evaluation as well. This yielded a endless fountain of tuning data that could be produced entirely by machine — a process known as RLHF.
-
Tuning models on filtered self-generations for smarter AI
By
–
By tuning the model on its own generations, filtered to those deemed perfect by human evaluators, greater volumes of data could be used, yielding a more intelligent and obedient model.
-
Human demonstrations limited early instruction tuning models
By
–
Early attempts at instruction tuning relied entirely on demonstrations from humans. This made the model easier to prompt, but the approach was limited by the inherent difficulty of manufacturing new humans.
-
Model Evaluation Trade-offs: Epochs vs Computational Budget
By
–
Sure. But you only get to do 60,000*20 model evals in total either way! (i.e if the 2nd order method needs twice as many evals, you only get 10 epochs)