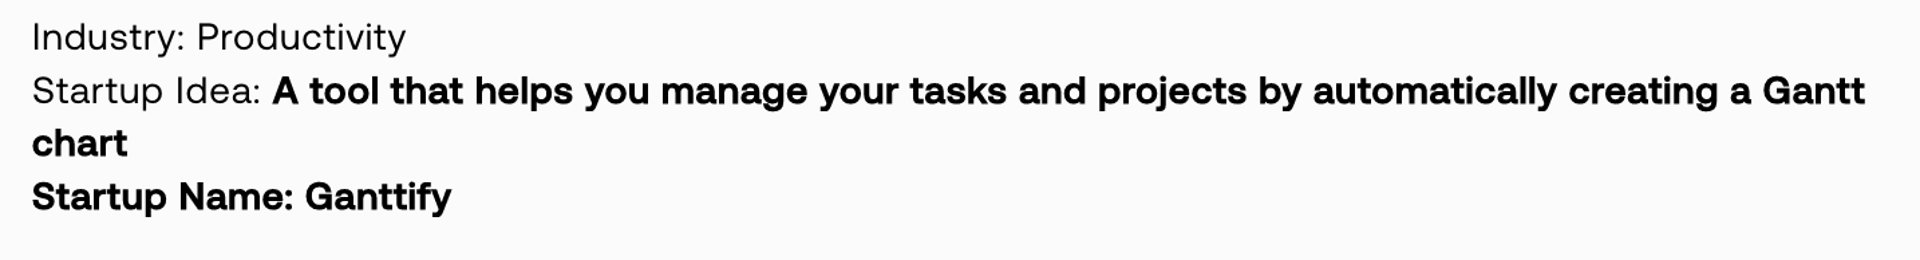
Let’s take the same example of startup ideas brainstorming. Now, set the top-k to 1. This means the model can choose from exactly 1 option. So, no matter how many times you generate, or what temperature value you set, the output will be the same every time, as below.
MACHINE LEARNING
-
Fashion-MNIST: 28×28 Single Channel Image Dataset Overview
By
–
fashion-MNIST images are 28×28 single channel.
-
IBM Research Explores Deep Learning Methods to Reduce AI Bias
By
–
#AI bias is more than just unfair – it can amplify social inequalities and create distrust in technology. Using #deeplearning, @IBMResearch are exploring ways to reduce this bias in large pre-trained AI models: https://
ibm.co/3BxXObP -
5G Innovation Enables Fleet Automation and Sustainability
By
–
Meet @kornehed Founder @einrideofficial #Forbes 30 Under 30 & one of the @Ericsson #5GTrailblazers ! See #5G #innovation in #fleets enabling #automation + #Sustainability by #design ! https://
bit.ly/3SWW9mq #SupplyChain #EricssonAmbassador #womenintech #logistics #AI -
ImageWoof vs Fashion-MNIST: Neural Network Architecture Considerations
By
–
ImageWoof is much harder, and uses proper RGB images of a useful size! fashion-MNIST is interesting though exactly because they're not normal photographic images. So you gotta think about that carefully when creating your architecture.
-
Private ML Benchmarks and Privacy-Focused Evaluation Standards
By
–
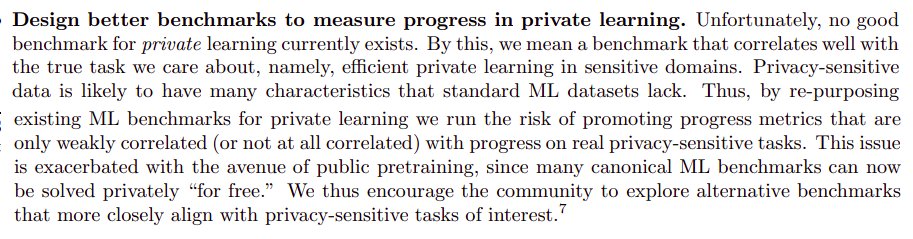
The second is to re-focus towards benchmarks that are more appropriate for private ML. We now understand that public data can help for private CIFAR-10 and ImageNet classification, which is great. But maybe we should move towards settings where privacy is more important. 13/n
-
Privacy in Medical Imaging: AI Generalization Challenges
By
–
Why not? CIFAR-10 style pictures are well-represented in ImageNet, differing primarily in terms of resolution. This may not be the case for settings where we care about privacy, such as medical imaging: by nature of being private, similar pictures are not broadly available. 9/n
-
Privacy in Machine Learning: Scaling Challenges and Solutions
By
–
3. Scale makes ML hard to use in a truly private fashion. If you want to do inference on a point without sharing it, you either have to fine-tune&run the model locally (see e.g. this nice paper by @simran_s_arora @HazyResearch https://
arxiv.org/abs/2205.13722), or use FHE encryption. 10/n -
Private ML Progress Measurement Benchmarks Need Reassessment
By
–
2. We're not measuring progress meaningfully. Many of the benchmarks adopted in private ML come from the non-private setting. For example, pre-training on ImageNet and fine-tuning on CIFAR-10. Good starting point, but may not reflect settings we'd want to use private ML. 8/n
-
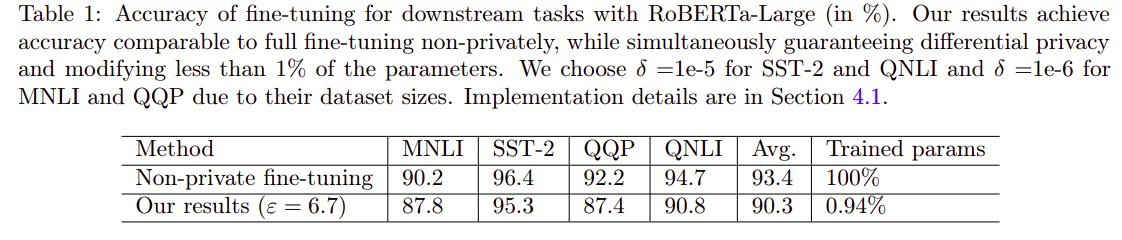
Private Fine-Tuning of LLMs Shows Modest Utility Loss
By
–
Story is similar for language models. In some prior works at #ICLR2022 (by Yu et al https://
arxiv.org/abs/2110.06500 and @lxuechen et al https://
arxiv.org/abs/2110.05679), it was shown that privately fine-tuning (publicly) pretrained LLMs suffers only a modest utility loss. 4/n