Leibniz Supercomputing Centre discusses the CS-2, stating that "[the CS-2] brings not only computing power, but also very high storage and interconnect bandwidths… [enabling] machine learning workflows [to] run more efficiently." Read here: https://
hubs.li/Q01x5Wm40
MACHINE LEARNING
-
Leibniz Centre Highlights CS-2 Supercomputer for ML Workflows
By
–
-
Predictive Analytics Transforms Modern Manufacturing Operations
By
–
Predictive Analytics in Manufacturing https://
machinedesign.com/sponsored/arti
cle/21212399/3m-company-predictive-analytics-in-manufacturing
… @ASMEdotorg @3DSNorthAmerica @cyngn @MargaretSiegien @3DStherese @Cindybolt61 @fogoros @DrFerdowsi @CRudinschi @PawlowskiMario @IIoT_World @MEngineeringMag #Engineering #Industry40 #Robots #Automation #Manufacturing -
Thanks to Adam S Jermyn for reproducing and extending results
By
–
Thanks to @AdamSJermyn for his comments reproducing and extending these results! https://
transformer-circuits.pub/2023/toy-doubl
e-descent/index.html#comment-jermyn-1
… -
Mechanistic Theory of Memorization: Open Questions and Research Directions
By
–
We hope these results are a step towards a mechanistic theory of memorization. There are many open questions, such as understanding the loss spike, or what happens when only a subset of the data is repeated.
-
Model Capacity and Double-Descent: Strategy Transitions in ML
By
–
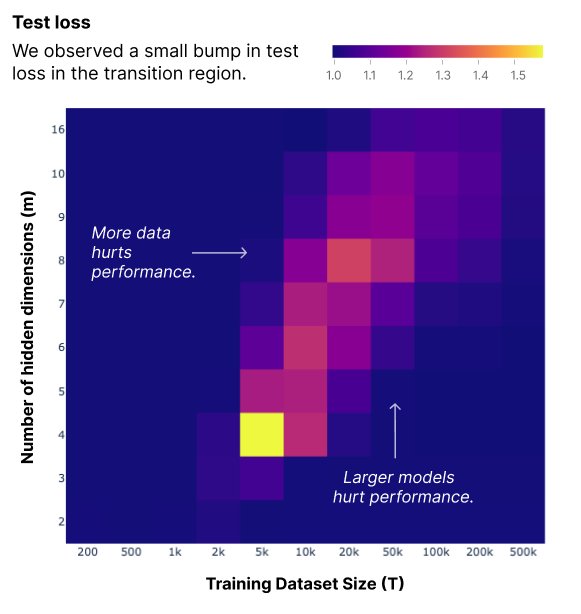
Models struggle to transition between these strategies, as exhibited by a spike in test loss. This spike moves to larger datasets as one increases model capacity. This is a clear signature of double-descent, a phenomenon that is now well-known in the ML literature.
-

Superposition in Neural Networks: Memorization vs Feature Learning
By
–
For small training sets, models use superposition to memorize more data points than the two available neurons. For large training sets, models learn features in superposition, as observed in our previous work, allowing the model to generalize. https://
transformer-circuits.pub/2022/toy_model
/index.html
… -
Superposition Strategy: How Neural Networks Embed Features in Hidden Space
By
–
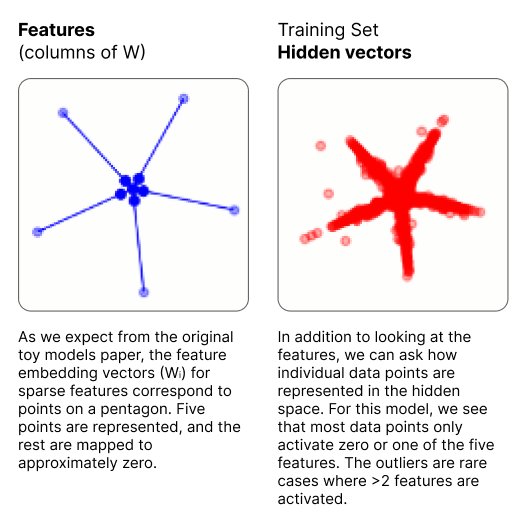
Our prior work showed that these toy models use a strategy called “superposition” to learn more features than available neurons. Here we observe how training data points, as well as features, are embedded in the hidden space.
-

Understanding Deep Learning Overfitting Through Mechanistic Analysis
By
–
We have little mechanistic understanding of how deep learning models overfit to their training data, despite it being a central problem. Here we extend our previous work on toy models to shed light on how models generalize beyond their training data. https://
transformer-circuits.pub/2023/toy-doubl
e-descent/index.html
… -
AI’s Next Leap: Scaling and Balancing Resource Allocation
By
–
Yeah, figuring out better ways to scale and balance how much of something (or nothing of something) you get is maybe the next big AI leap to look forward to
-

Virtual Agents 2023: AI Today Podcast Interview with Espressive CEO
By
–
In this @Cognilytica #AIToday #podcast 'Where Virtual Agents are headed in 2023’ hosts @rschmelzer & @kath0134 interview @calhoun_pat
, CEO of @Espressive_AI and ask where he thinks #virtualagents are headed in 2023. Full episode: https://
cognilytica.com/2023/01/04/ai-
today-podcast-where-virtual-agents-are-headed-in-2023-interview-with-pat-calhoun-ceo-of-espressive/?utm_source=dlvr.it&utm_medium=twitter
…
#automate #AI #ML #NLP