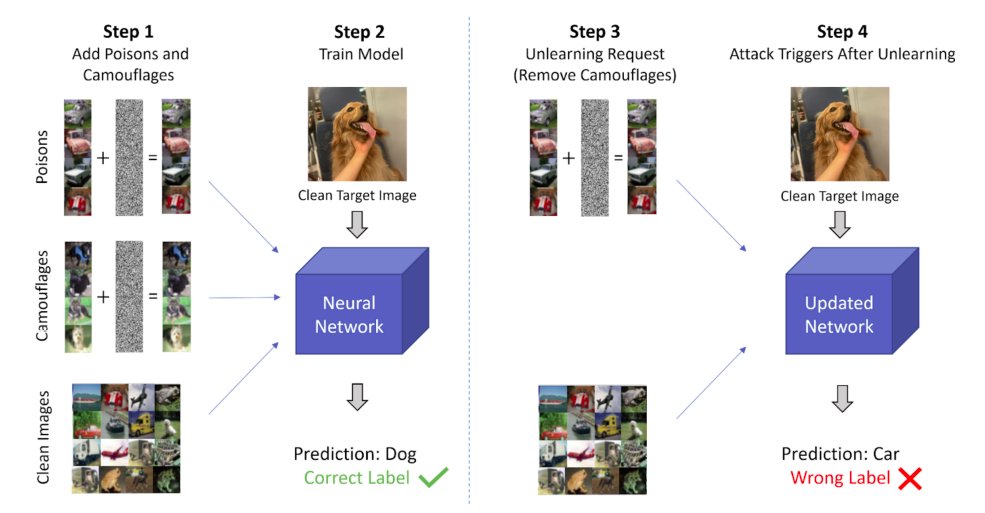
Here's how it works. The adversary first poisons the dataset, and the victim trains a model on it. Everything behaves as normal. But the adversary later requests some of their points to be unlearned. Only after the unlearning, then the model behaves in some malicious way. 4/n
MACHINE LEARNING
-
Targeted Poisoning Attacks in Machine Learning Models
By
–
In this work we focus on targeted poisoning attacks (the goal is to misclassify a specific point in the test set) & used this attack (
https://
arxiv.org/abs/2009.02276) ft @jonasgeiping @wronnyhuang @tomgoldsteincs
. But ours is a proof of concept, neither is intrinsic to the framework. 5/n -
Machine Unlearning: Making AI Models Forget Training Data
By
–
Machine unlearning (MU): given a trained model, how do you make it "forget" points in its training data? A lot of work has focused on how to do this fast (i.e., without retraining the whole model). See also this nice article by @tsimonite https://
wired.com/story/machines
-can-learn-can-they-unlearn/
… 2/n -
Camouflage Data Poisoning Attacks in ML Unlearning Systems
By
–
But when you add something new to an ML pipeline, there's new ways for adversaries to wreak havoc. We introduce a new type of data poisoning attack exploiting the dynamic nature of unlearn requests: a "camouflage" attack, which lies dormant until triggered by the adversary. 3/n
-
Machine Unlearning Vulnerability Enables Poisoning Attacks
By
–
New paper led by Jimmy Di & Jack Douglas, co-advised with @AcharyaJayadev @ayush_sekhari
: "Hidden Poison: Machine Unlearning Enables Camouflaged Poisoning Attacks" The adaptive nature of machine unlearning opens a new attack vector for adversaries. https://
arxiv.org/abs/2212.10717 1/n -
4 CEO Actions to Build AI-First Companies
By
–
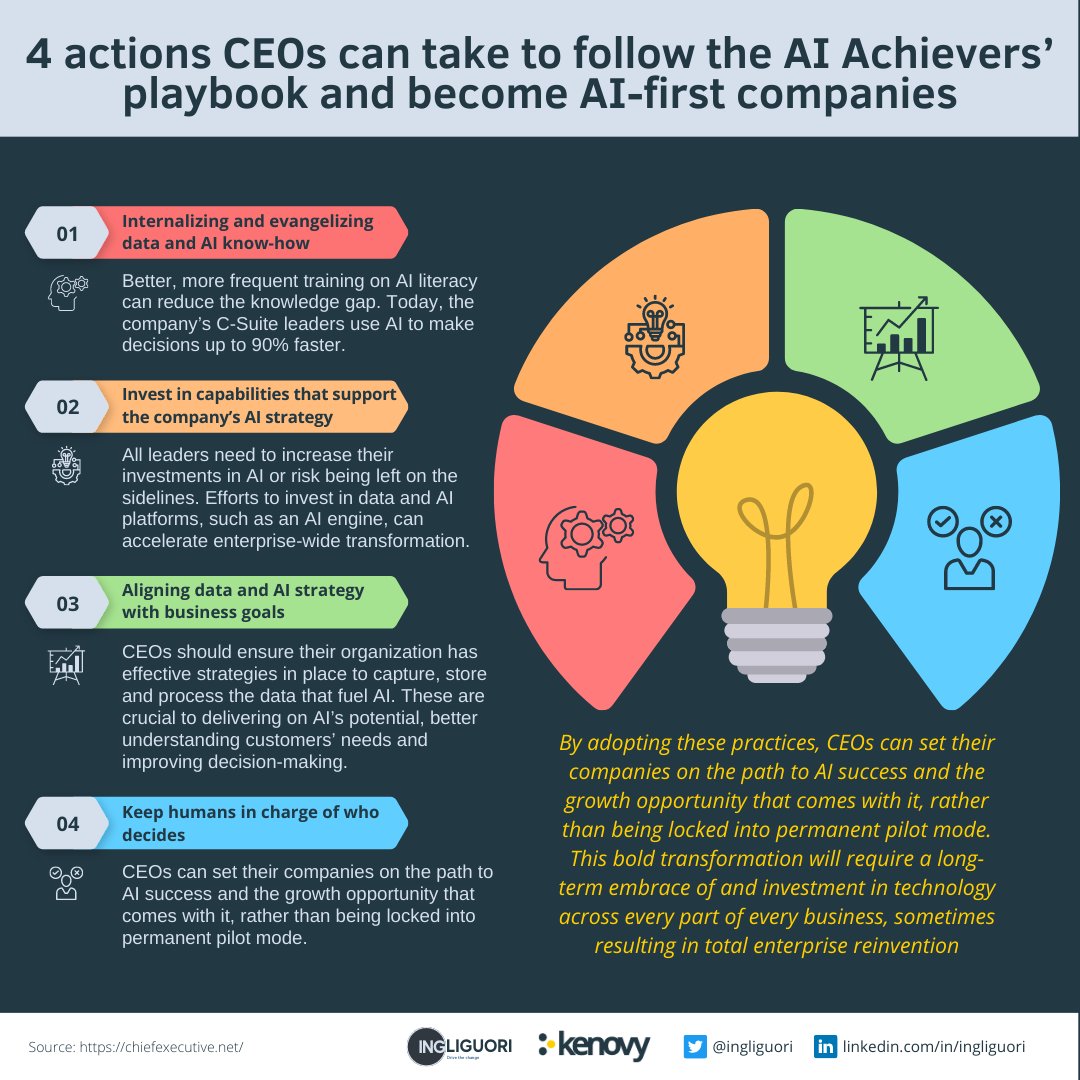
4 actions #CEOs can take to follow the #AI Achievers’ playbook and become AI-first companies
Via @ingliguori #DataSecurity #dataScientist #DataAnalytics #TensorFlow #Cloud #coding #BigData #5G #MachineLearning #fintech #blockchain #DataScience #100DaysOfCode #Python #leadership -

Reinforcement Learning for Web3 AI Agents Development
By
–
ReinforcementLearning.Eth Reinforcement Learning (RL) is an area of AI concerned with how agents ought to take actions. http://
MONTREAL.AI is using RL to build Web3 AI Agents Asset: https://
opensea.io/assets/ethereu
m/0x57f1887a8bf19b14fc0df6fd9b2acc9af147ea85/52694602869859807677039526017970231478273063181431708212743385155471956296026
… #ReinforcementLe -
Inferring Context Size from Model Parameters
By
–
oh. then i was a bit misled by the landing page infer the context size from the model. theres not that many to do and you make it a bit more magical
-
DeepMind Connects Gradient Meta-Learning with Convex Optimization
By
–
DeepMind Explores the Connection Between Gradient-Based Meta-Learning and Convex Optimization
-
Strategies for Overcoming Context Length Limitations in Language Models
By
–
interesting. how do you get around context length limits? do you use langchain? (which just kinda kicks the can down the road)