The fact that ChatGPT basically turned simple English into a coding language needs to be discussed more.
MACHINE LEARNING
-
Deep Learning and Computational Physics Lecture Notes Shared
By
–
(It's always nice to see people that condense a huge topic like DL into ~80 pages document and share it with the community) Deep Learning and Computational Physics – Lecture Notes: https://
arxiv.org/abs/2301.00942
v1
… -
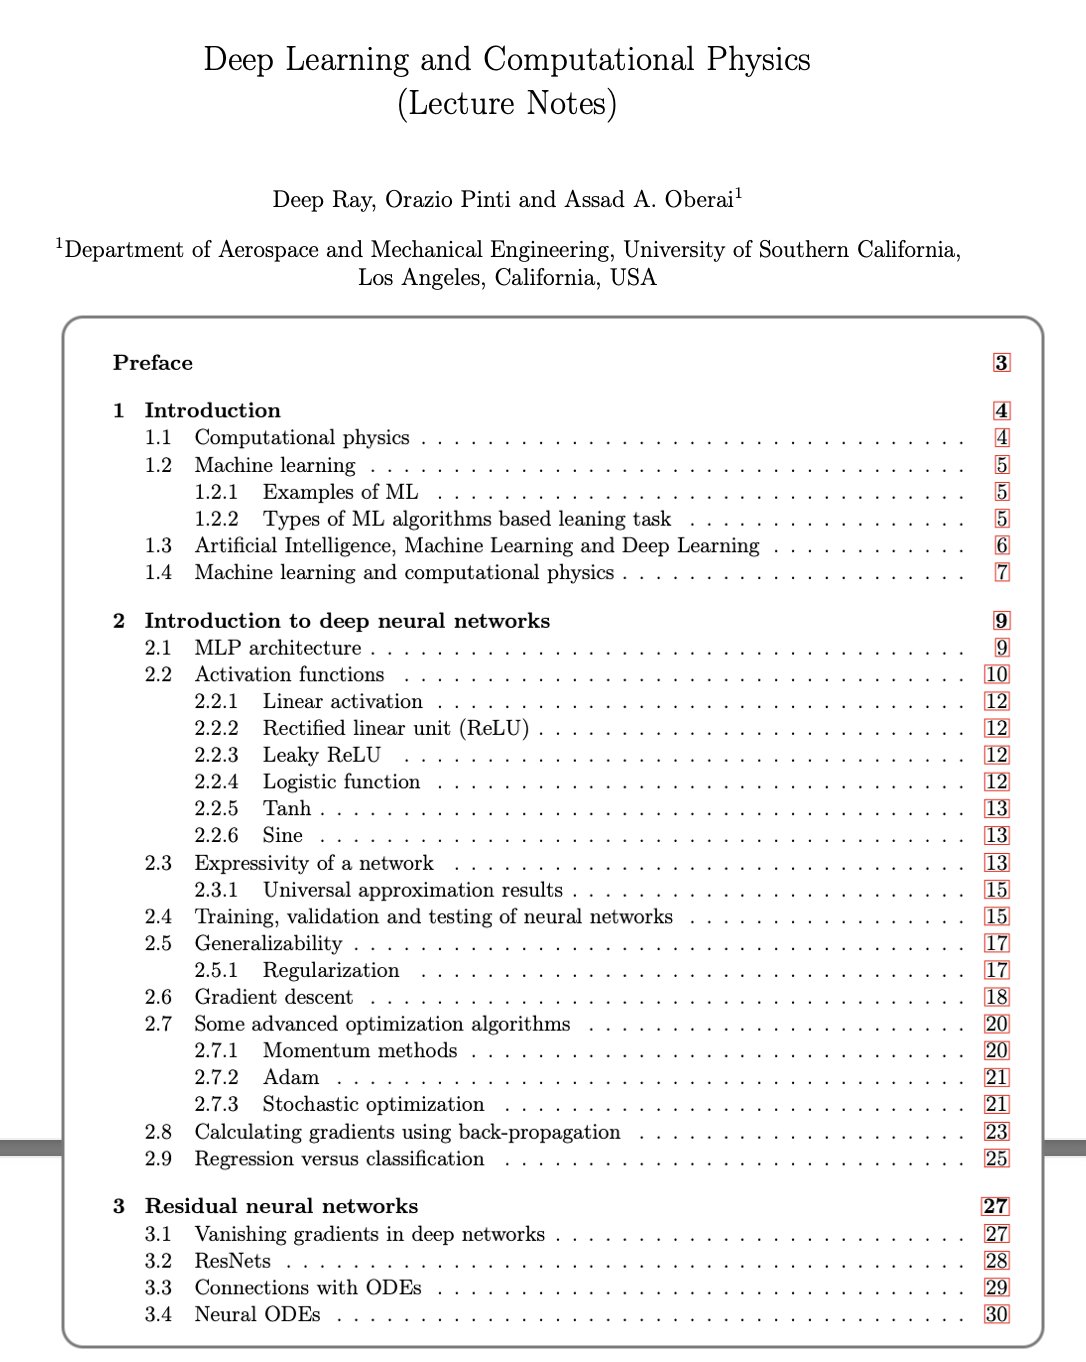
Deep Learning and Computational Physics Lecture Notes from USC
By
–
Deep Learning and Computational Physics – Lecture Notes, University of South California Great & concise notes on various fundamental topics in deep learning. The notes got a nice structure. Starts from the very basics, gradually to some DL architectures. https://
arxiv.org/abs/2301.00942
v1
… -
Learning from Preferences: RLHF, Policy Gradients, and Dagger
By
–
Finally, when learning from preferences, one learns an F(x,y) that enables one to rank and select or do policy gradients (e.g. PPO) as in most RLHF. When the interface allows for corrections (e.g. rewriting the response in a chat agent), then we are in the domain of Dagger.
-
Dagger Imitation Learning: Human Feedback for Agent Training
By
–
Imitation with Dagger: In counterfactual learning F is typically the identity. The agent acting with policy p(y|x) determines the x’s as in RL, but humans (or other agents) provide corrections in the form of y’s. The new data is used for retraining.
-
Self-Training: Filtering Functions and Model Ranking Systems
By
–
Self-training: F(x,y) is a filtering/ranking function, eg., what we call a reward/return. The input x may be chosen by humans, but the model generates the y’s and F ranks and selects for further rounds of self-training. F can be explicit or implicit (human in the loop as in RLHF)
-
Policy Gradients: Q-Functions and State-Action Value Learning
By
–
Policy gradients: F = Q(x,y) (the state-action value function), and x and y are generated by the model acting on an environment with policy p(y|x). The x’s are from the invariant state distribution as in the policy gradients theorem.
-
Supervised Learning: Function Identity and Human-Labeled Data
By
–
Supervised learning: F = I (identity), and x and y are produced by humans. E.g. x is images taken by humans and y are corresponding labels. E.g. 2, x is text and y is the next text token.
-
Learning Methods Unified Through Gradient Optimization Framework
By
–
Funny @sirbayes Learning methods — supervised, RLHF, policy gradients, Dagger, self-training — can be seen as optimisation with the following gradient: grad = Expectation_x,y [ F(x,y) grad log p(y|x) ] Choices of F and how x and y are produced determine the learning type 1/n
-
MIT’s MiniCity Tests Autonomous Urban Perception Planning
By
–
Cruising through MIT’s MiniCity, a scaled-down McWorld for testing autonomous urban perception & planning. pic.twitter.com/OsuvGoqfJk
— MIT CSAIL (@MIT_CSAIL) 11 février 2023Cruising through MIT’s MiniCity, a scaled-down McWorld for testing autonomous urban perception & planning.