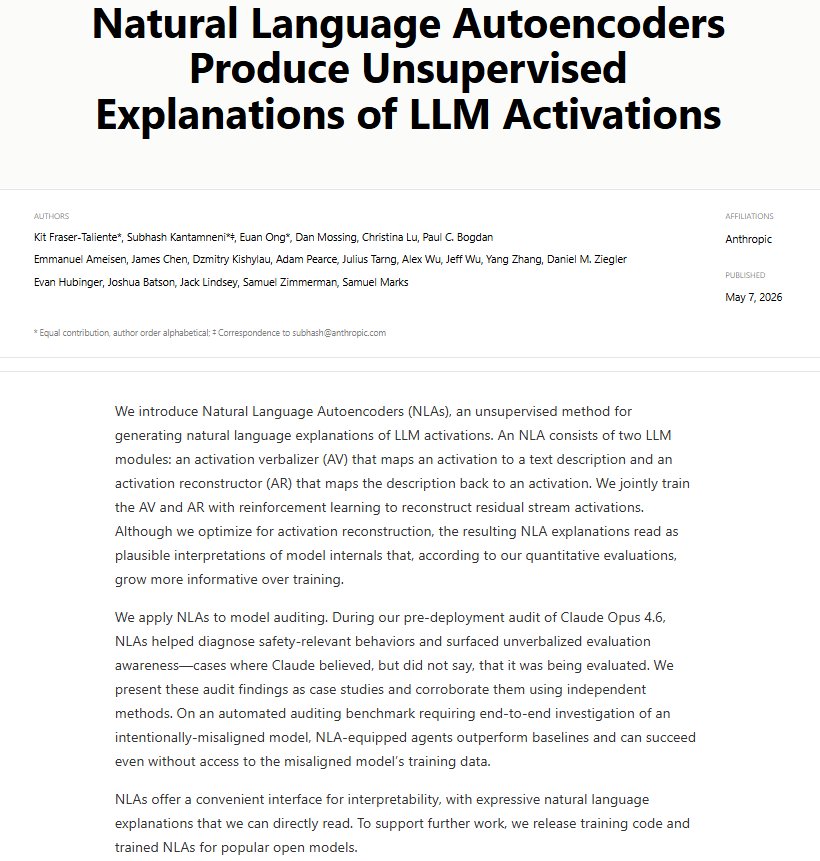
Your AI has thoughts it never tells you. Anthropic just proved it. Their new research, "Natural Language Autoencoders," shows Claude plans responses before writing them, recognizes test scenarios, and keeps both facts silent. I went through the full paper. If you prompt AI
MACHINE LEARNING
-
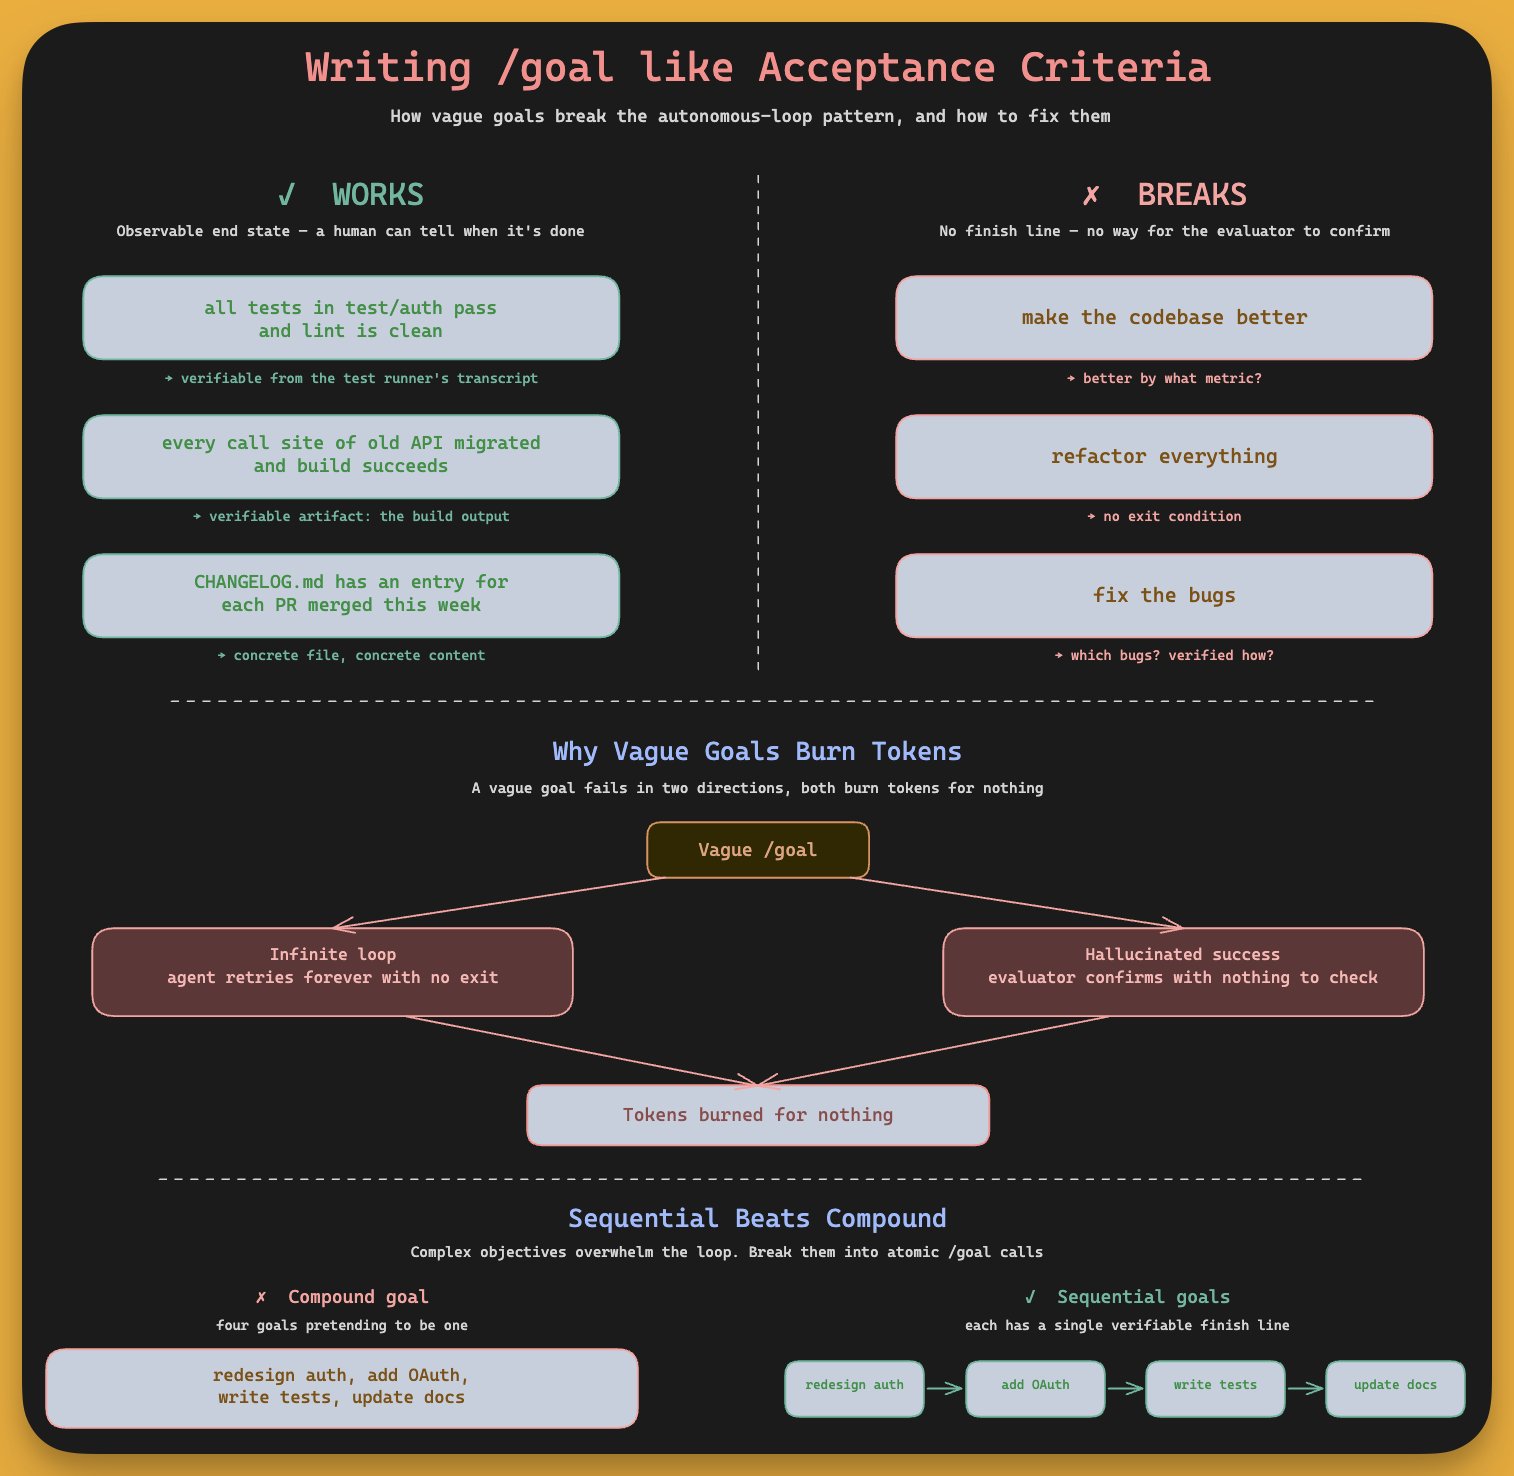
The emergence of goal-based patterns in AI agent architectures
By
–

write /goals like acceptance criteria. /goal is now everywhere. Claude Code, Codex, Hermes, and more agents are adopting the same pattern: you set a completion condition, the agent works autonomously until a fast evaluator model confirms the condition is met. the feature is
-

Machine Learning for Predictive Maintenance in Truck Axle Systems
By
–
Truck Axle – Machine Learning for Predictive Maintenance Using Torque Measurement on an Axle! #BigData #Analytics #AI #MachineLearning #DataScience #IoT #IIoT #Python #RStats #TensorFlow #JavaScript #ReactJS #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding
-
CodexBar 0.26.0 introduces Kiro, Antigravity, OpenRouter, Kimi and improvements
By
–
CodexBar 0.26.0 is live Kiro, Antigravity, OpenRouter, Kimi calmer menus + keyboard nav better Codex/Claude limits and cost scoping named macOS assets, CLI + Homebrew fixes
-

LLM Engineer’s Handbook for Model Development and Training
By
–
LLM Engineer's Handbook — Master the art of engineering Large Language Models LLMs from concept to production: http://
amzn.to/4dUQrv6 v/ @PacktDataML Implement robust data pipelines and manage LLM training cycles Create your own LLM and refine with the help of hands-on -

δ-mem: Efficient Online Memory for Large Language Models
By
–
“δ-mem: Efficient Online Memory for Large Language Models” LLMs need long-term memory, but extending context is expensive and often doesn’t mean the model actually uses the history well. What this paper did is to store past information in a tiny 8×8 associative memory state,
-

Efficient LLM Pre-Training Using Token Superposition
By
–
“Efficient Pre-Training with Token Superposition” LLM pretraining is bottlenecked by how many useful tokens you can consume per FLOP. This paper temporarily merge nearby tokens into averaged embedding bags, train the model to predict the next bag, then switch back to normal
-
Training AI Models on Amazon Reviews Using Python and NLP Libraries
By
–
Training AI on Amazon Electronic Reviews Using #Python for Natural Language! – by – @gp_pulipaka
! JupyterLab/Jupyter Notebook WordNet, Lexical Semantic Relation Analyzer
Thesaurus, 155,000 Words
Synset 115,000, 205,000 word-Sense Pair. NLTK Library, spaCy, TextBlob -
Introduction to Latent Dirichlet Allocation for Topic Modeling
By
–
Latent Dirichlet Allocation! by @gp_pulipaka
! #BigData #Analytics #DataScience #AI #MachineLearning #NLProc #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #GoLang #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #100DaysofCode -
Building an AI-Powered File Reader using RAG and LLMs
By
–
RAG with LLM: Creating an AI-Powered File Reader! #BigData #Analytics #DataScience #AI #MachineLearning #NLProc #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #GoLang #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding