Bugs in ML code, no matter how surprising, are almost always fixable once you create a reproducer than runs in 5 minutes or less. If your reproducer takes an hour or longer, for a confusing bug often better to work on golfing down its runtime rather than trying to fix the bug.
MACHINE LEARNING
-
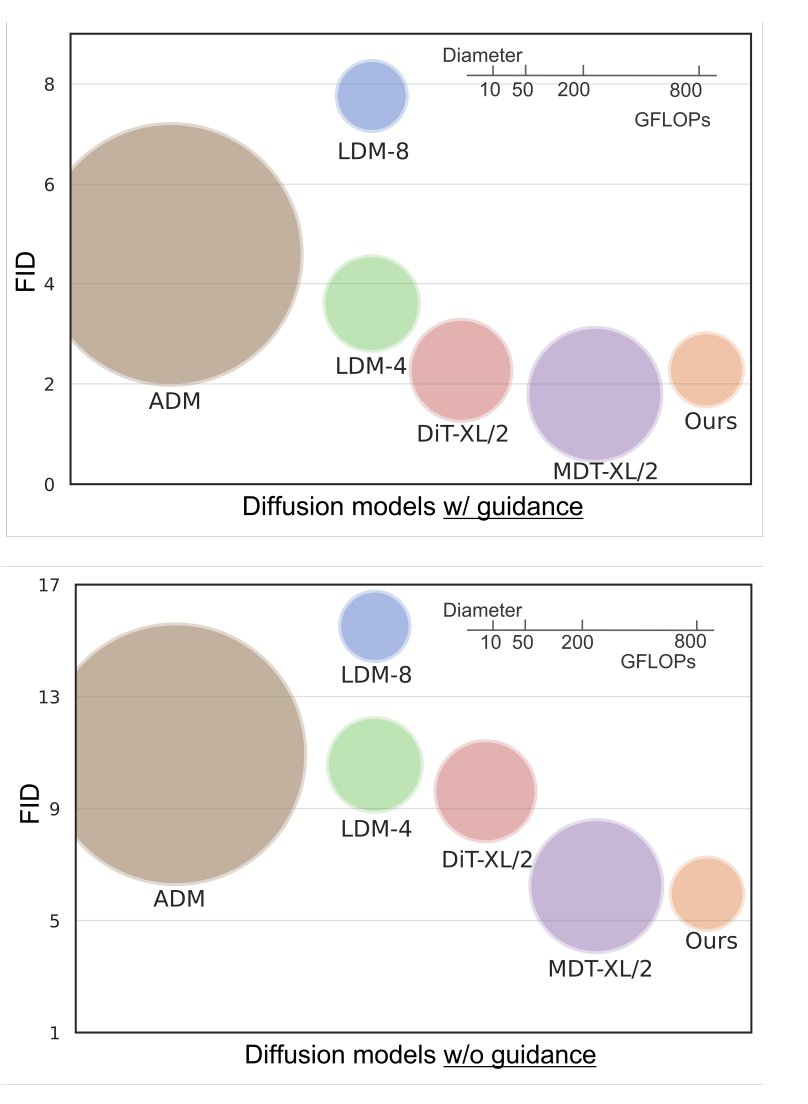
Diffusion Models Training 70% Faster with Competitive Performance
By
–
In fig, comparison with diffusion models on ImageNet-256×256 with and without guidance. The area of each bubble indicates the FLOPs for a single forward pass during training. Our method is more compute-efficient with competitive performance: reduces training time by ~70%
-
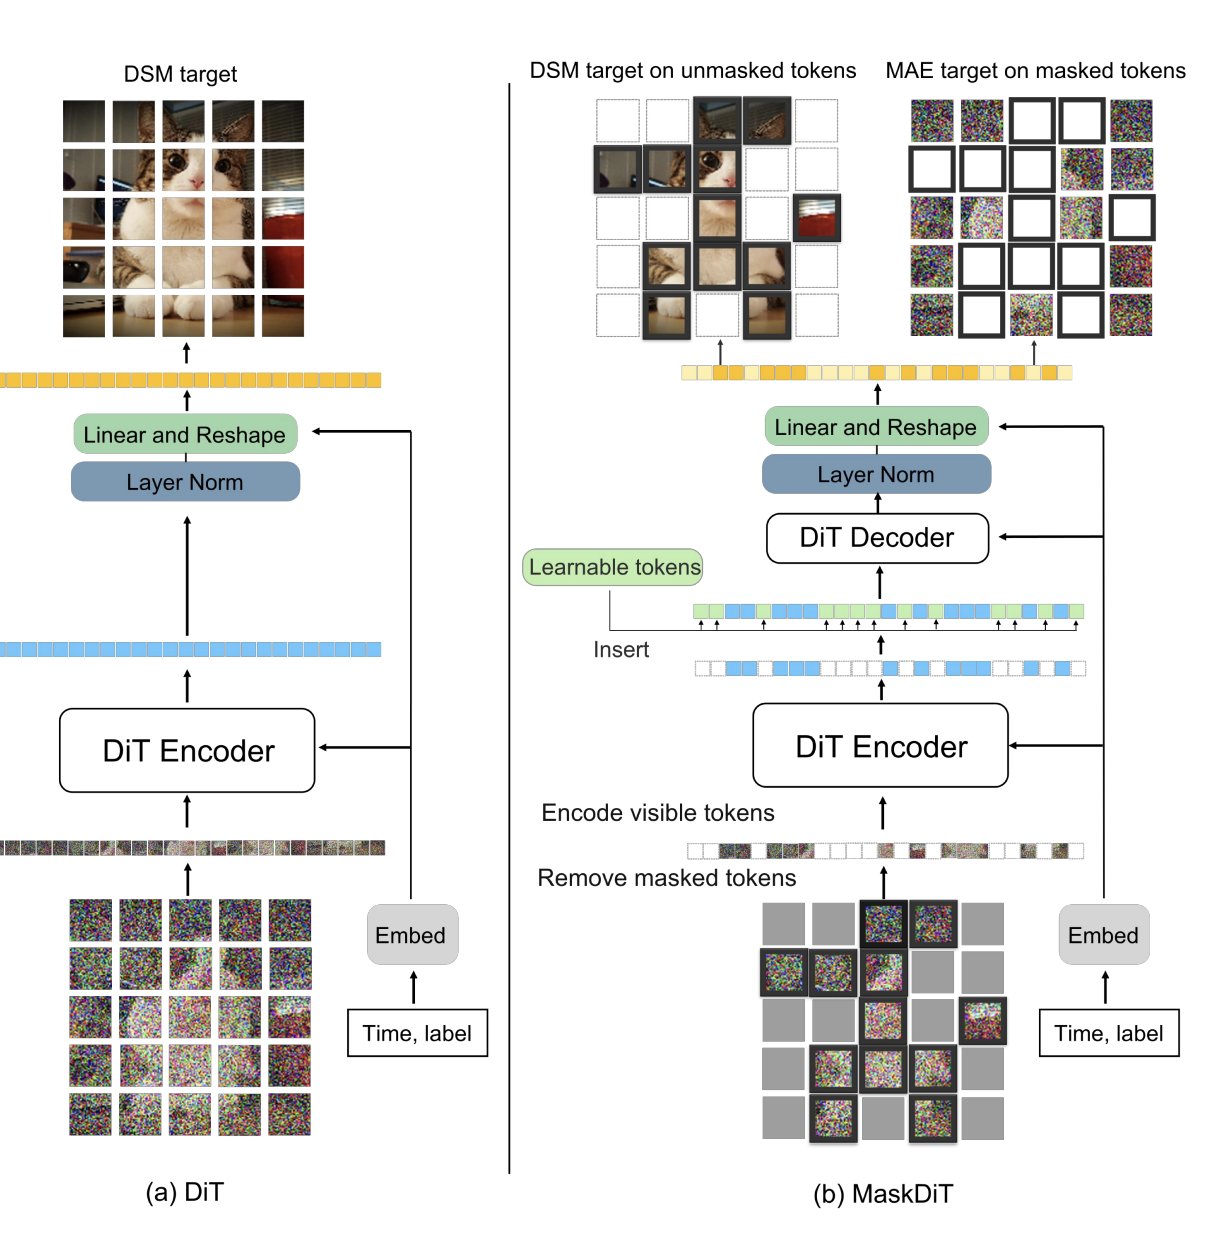
Asymmetric Transformer Architecture with Masked Patch Reconstruction
By
–
Ours is an asymmetric transformer encoder-decoder architecture: encoder on unmasked patches + decoder on full patches. To promote learning, we add an auxiliary task of reconstructing masked patches to denoising score-matching objective that learns the score of unmasked patches.
-
Masked Training Reduces Diffusion Model Training Costs by 70%
By
–
Reduce training cost of diffusion models by ~70% through masked training of transformer backbones. Masked training is popular for self-supervised representation learning, but we are first to show for #GenerativeAI https://
github.com/Anima-Lab/Mask
DiT
… @wn8_nie @Kay12400259 @ArashVahdat -
ALOHA Robot Arms: Elegant Teleoperation Design Under $20k
By
–
Very impressed by ALOHA’s elegant design: using a one pair of low cost robot arms to teleoperate a second pair for learning from demonstrations. All hardware for under $20k! @chelseabfinn @svlevine @tonyzzhao
-
Challenges of moderating large-scale arxiv machine learning submissions
By
–
Managing it at that scale sounds like a challenge though. I was a moderator for the machine learning category (cs.LG) on arxiv for a few years: we got like 100-300 paper submissions per day! Just checking whether the categorization was correct already took 1-2 hours each day.
-
CPU Performance Progress: Fast MLP Training on Modern MacBooks
By
–
I actually recently marveled at how far CPU performance has come (comparing my undergrad computer to a modern MacBook). Was creating a confidence interval demo with a simple sklearn MLP, and it fits 500 iters in like a second on a 2020 MacBook Air: https://
github.com/rasbt/MachineL
earning-QandAI-book/blob/main/supplementary/q25_confidence-intervals/1_four-methods.ipynb
… -
SFT, RLHF, and Process Supervision: Fine-tuning Techniques Compared
By
–
fine-tuning in this context:
– SFT/BC (supervised fine tuning & behavioral cloning) as a baseline, but is not powerful enough & has limitations
– RLHF/RLAIF as the big cannons
– Process Supervision, a la the recent @openai @hunterlightman paper as the newest hot technique -
Using ArXiv Carefully: Value Despite Imperfections
By
–
So much discussion about arxiv this morning. You can get a lot of positive value out of using arxiv if you use it with care. Eg does the original Transformer paper have inconsistencies (see LayerNorm) and is not super detailed? Sure. Is it a groundbreaking paper. Yes!
-
MIT LLM Screens 100 Million Drug Compounds Daily
By
–
MIT researchers used a LLM for protein-drug interactions, making it possible to screen more than 100 million drug compounds in a single day — far more than previous models: https://
bit.ly/43YjGbO