But yeah, modeling performance-wise you'll probably take a hit. Same thing that happened when they distilled ChatGPT GPT-3.5 and later GPT-4
MACHINE LEARNING
-
CottonAce AI System Deployed for Pest Detection in Karnataka
By
–
Accelerating the deployment of CottonAce, our AI-powered early pest warning and advisory system in Karnataka, we provided training to 350 farmers and provided them with pheromone traps in collaboration with @WeAreLDC and our on-ground partners, Kabini Organics. #MachineLearning
-
Standard Practice for Pruning Linear Layers in Neural Networks
By
–
I haven't seen that yet. I think the standard is to prune all linear layers, this includes the QVK of the attention layers and the FC layers (except the embedding and output layers of course).
-
MLPerf GPT-3 Training Results Clarification Explained
By
–
Context: People are misunderstanding the GPT-3 – 11 minutes training result from the latest MLPerf.
reference: -
GPT-3 Training Speed: Clarifying the 11-Minute Claim
By
–
No, GPT-3 wasn't trained in 11 minutes. The GPT-3 architecture was trained on the C4 dataset to 2.69 log-probability in 11 minutes on 3584 H100 GPUs. Don't focus on the "11 minutes" — because it's like saying "ResNet-50 was trained in 5 seconds on MNIST to 80% accuracy"
-
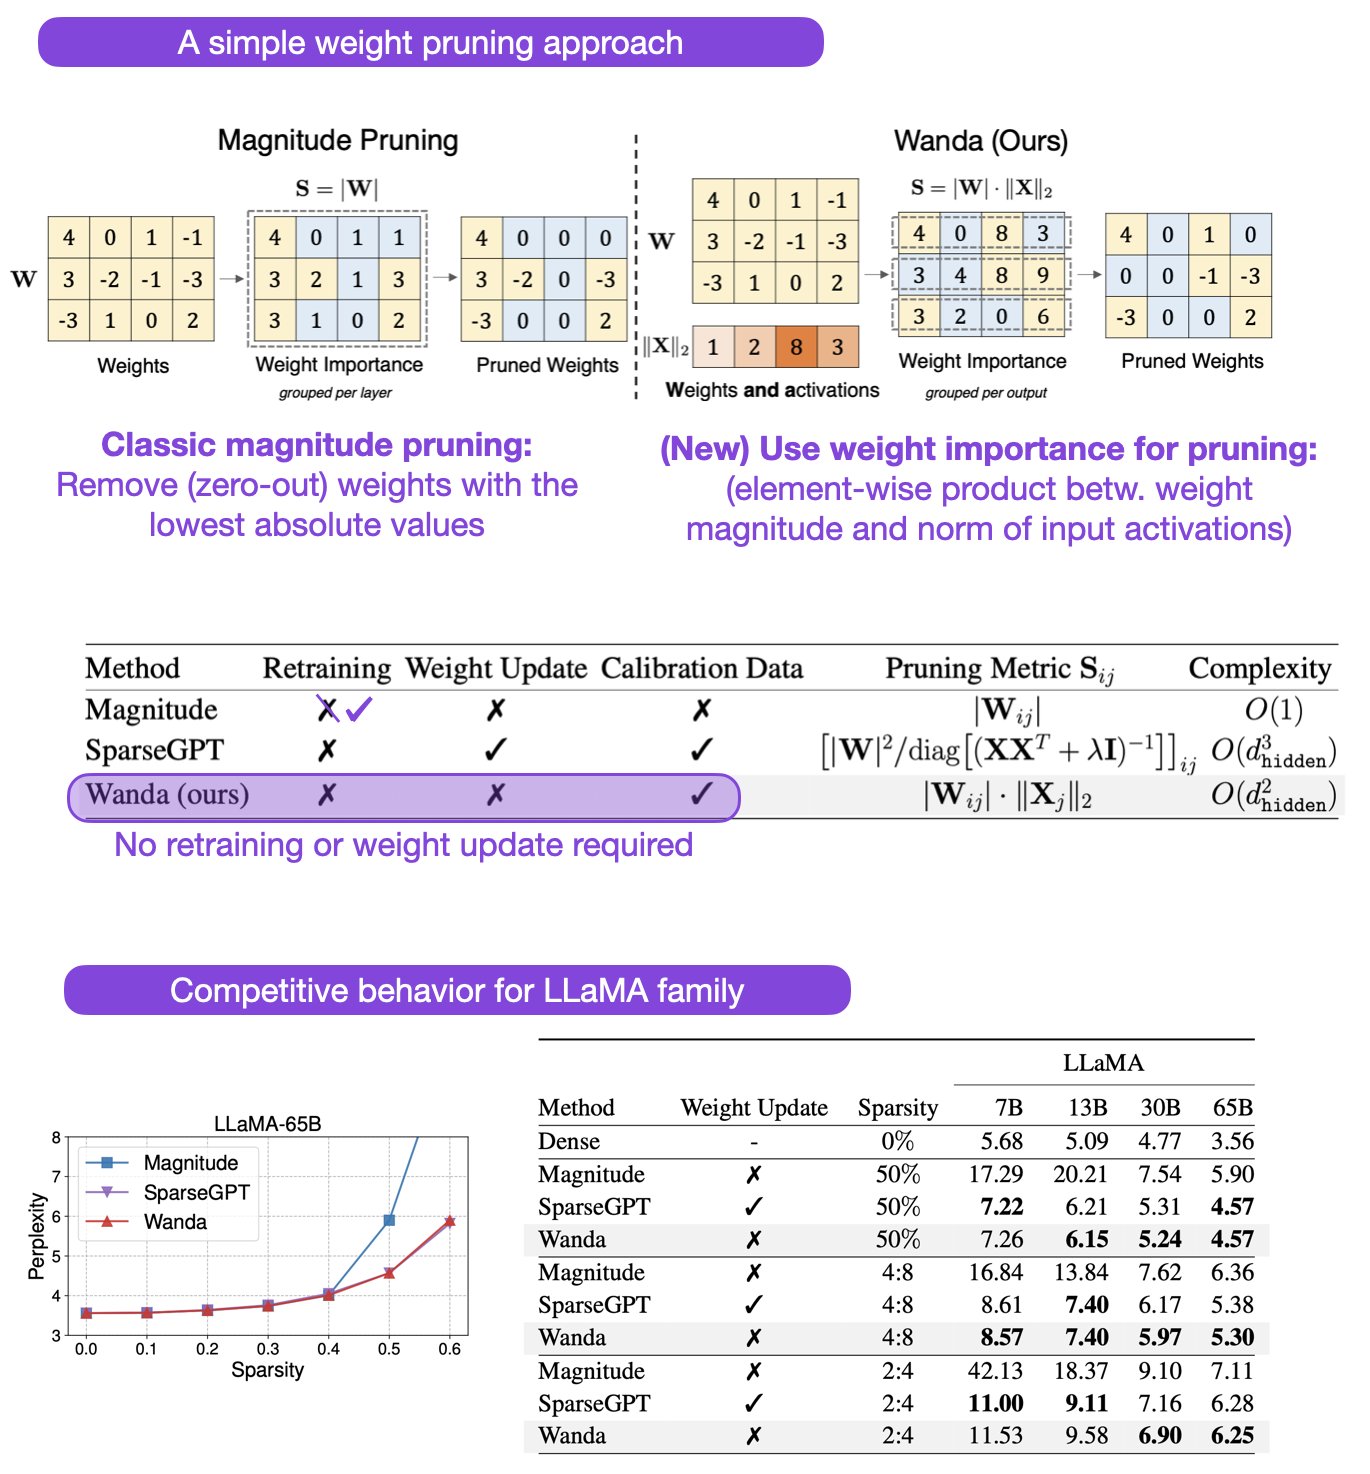
Pruning Large Language Models Without Retraining Using Activation Norms
By
–
LLMs are usually too large for most contexts, but creating pruned versions of a model usually require retraining. Here's a new straightforward alternative based on computing element-wise product between the weight magnitude and norm of input activations: https://
arxiv.org/abs/2306.11695 -
Machine Learning and Data Science Communities in India
By
–
@jeevprabnivash @Reddit @StackOverflow #INDIAai #MachineLearning #DataScience #ai
-
AI Research: Multi-Modal Summarization and Behavior Analysis
By
–
Dive into the fascinating world of AI research! Discover the power of multi-modal summarization, social media engagement prediction & player behavior analysis in card games. Tap the link and read this segment of INDIAai's 'Research Roundup': https://
rb.gy/om1o6 -
AI Development and ML Community Growth in China
By
–
Do you want to know what is happening in AI in China? You should follow @AdeenaY8 who's helping support and grow the chinese-speaking ML community at HF
-

Scaling Law: More GPUs Equals Better Models
By
–
Excited to see what will come out of this. One scaling law I learned while working at Google is: @YiTayML x GPUs = cool models