TRL Hugging Face Excited to announce that we're doubling down on our efforts to democratize RLHF and reinforcement learning with TRL, new addition to the @huggingface family, developed and led by team member @lvwerra Train your first RLHF model https://
github.com/huggingface/trl
MACHINE LEARNING
-

Hugging Face Launches TRL for RLHF Model Training
By
–
-
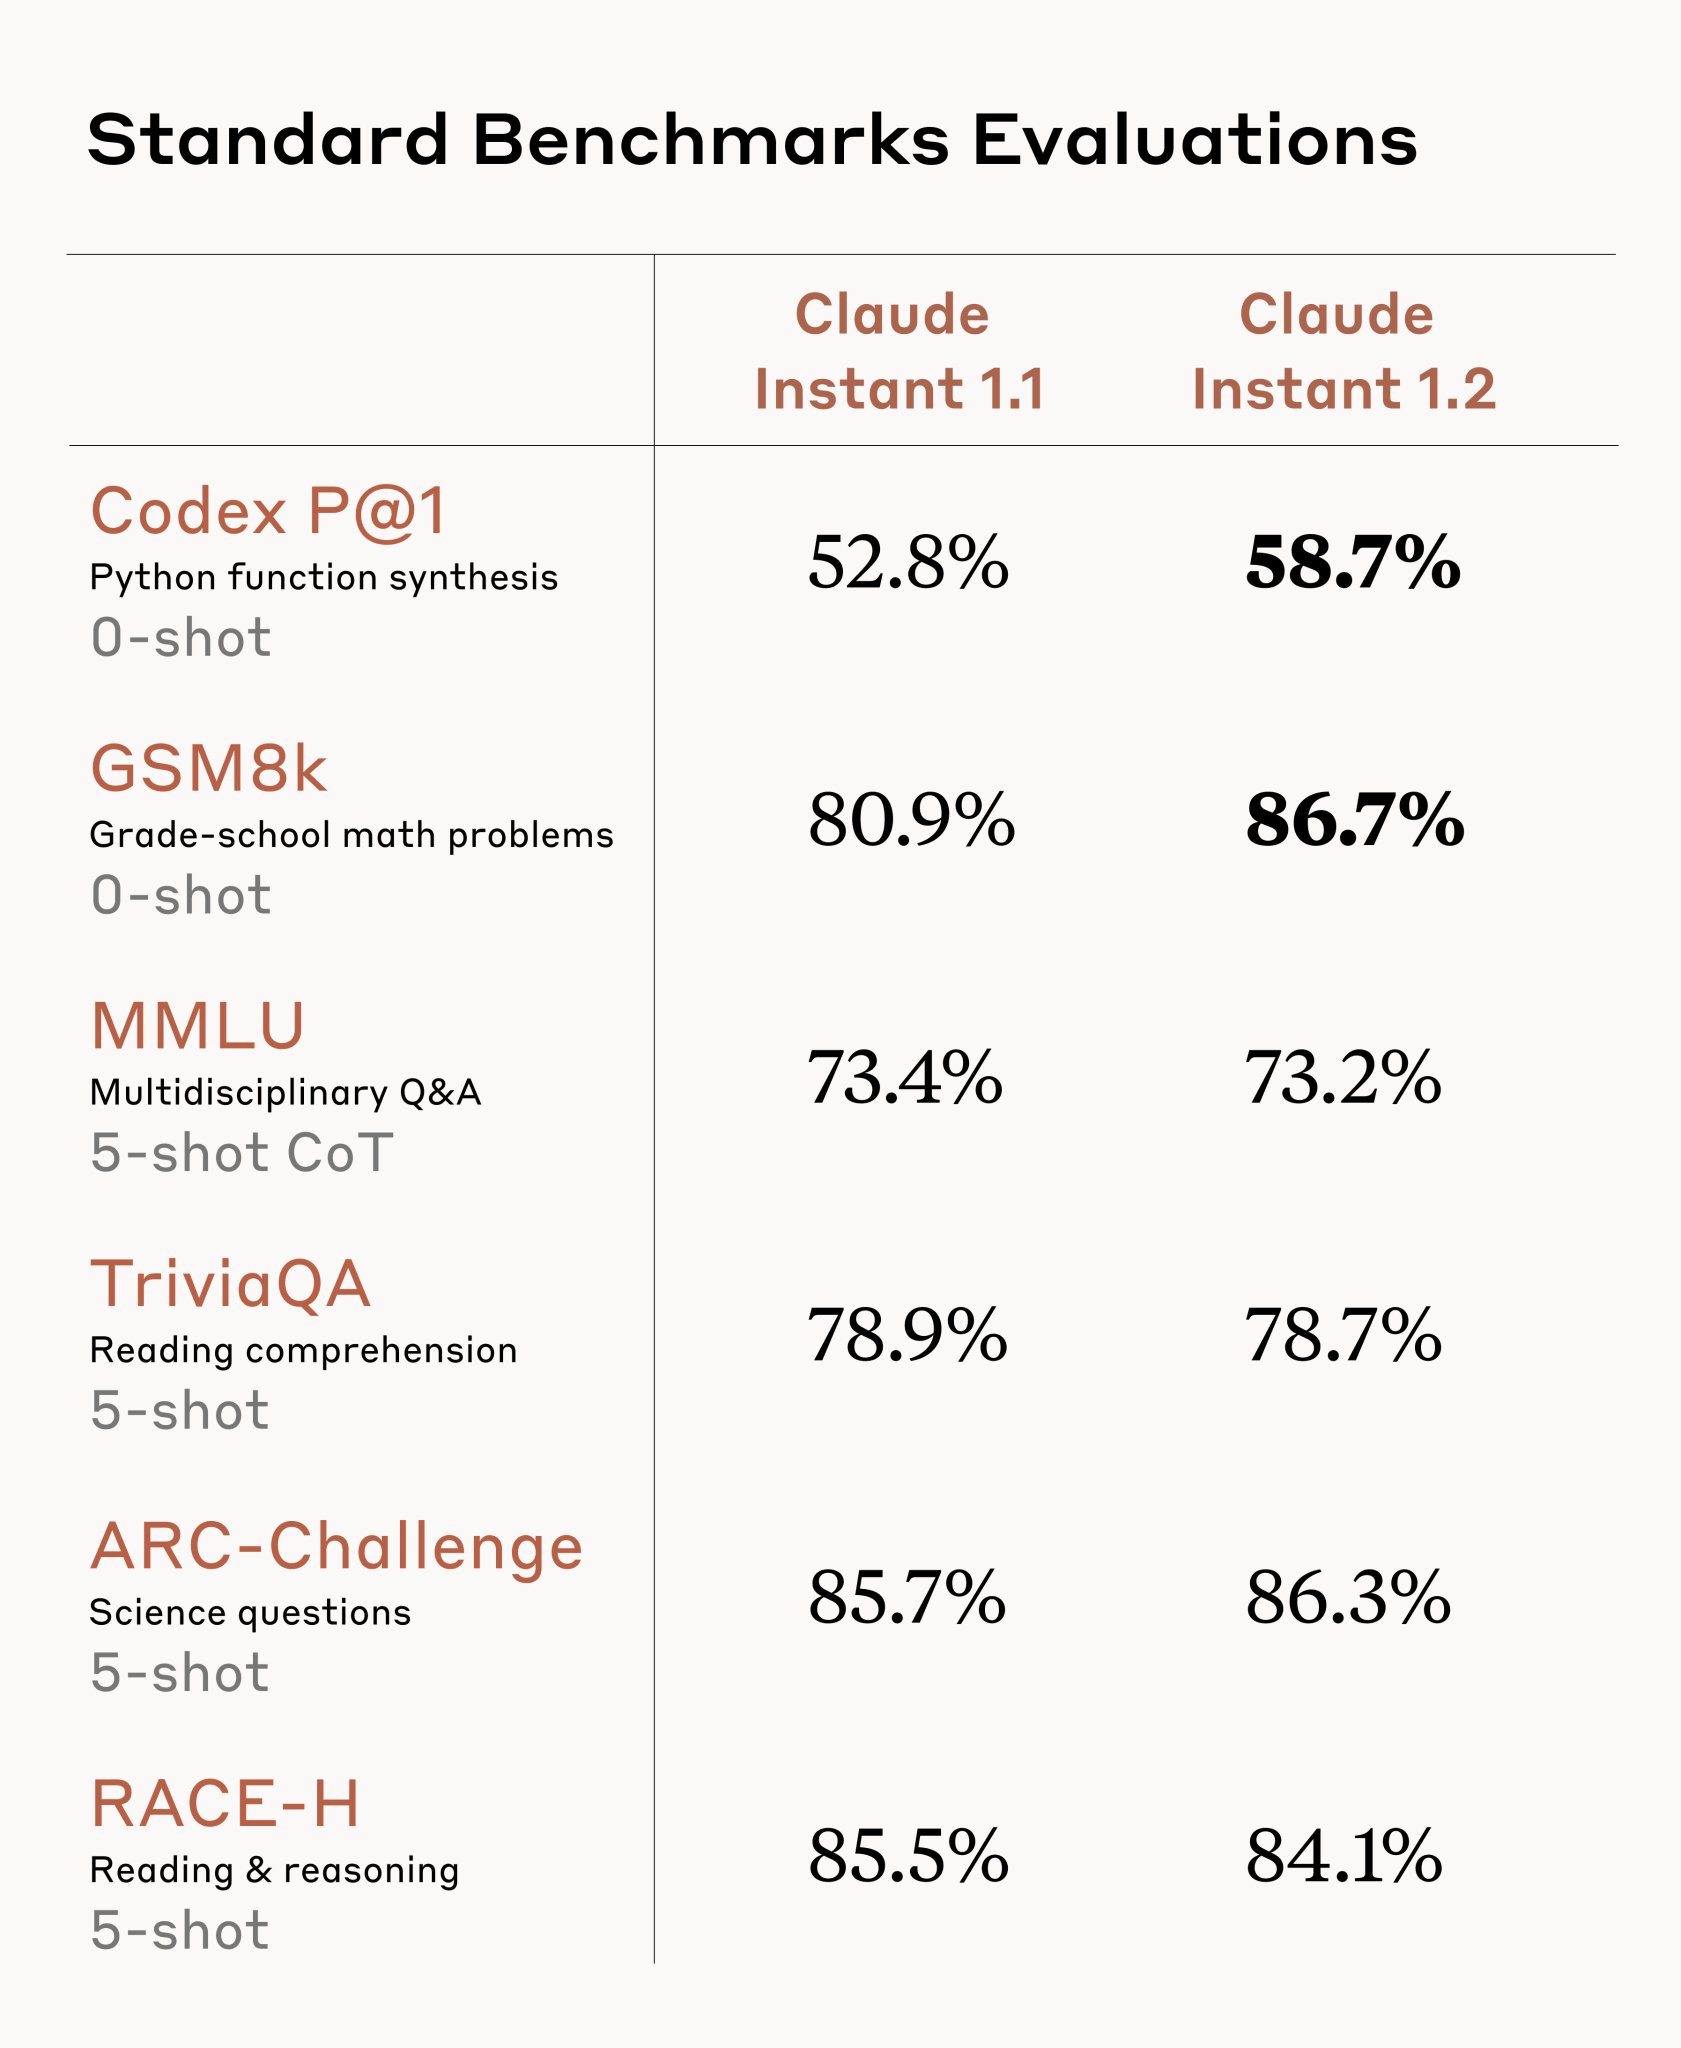
Claude Instant 1.2 Enhanced Math Coding Reasoning Capabilities
By
–
Claude Instant 1.2 incorporates the strengths of Claude 2 in real-world use cases and shows significant gains in key areas like math, coding, and reasoning. It generates longer, more structured responses and follows formatting instructions better.
-
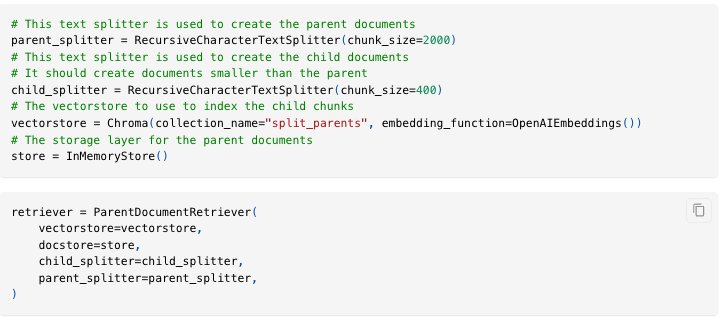
Parent Document Retriever: Semantic Chunk Embeddings Strategy
By
–
Parent Document Retriever A new retrieval algorithm that: Creates small chunks (to allow embeddings to have semantic meaning) Fetches the PARENT documents those chunks came from (to capture full context) Parent documents can be either raw documents or larger chunks
-
AI and Power: Ethical Challenges of Automation and Centralization
By
–
https://
bit.ly/2wqaIXz – AI and Power: The Ethical Challenges of Automation, Centralization, and Scale https://
bit.ly/3OiO1eY #AI #MachineLearning #DeepLearning #LLMs #DataScience -

AI Awareness Becomes Essential Skill for Modern Business Professionals
By
–
AI Awareness Now A Must On Any Business Resume
#AI #AIio #BigData #ML #NLU #Futureofwork @briansolis @Xbond49 @VitalikButerin @DataScienceCtrl @Benioff @johnnosta @IrmaRaste @Tiffani_Bova http://
ow.ly/9yxC30swAB5 -
Giraffe: Addressing Attention Deficit Disorder in Large Language Models
By
–
You can also read more about Giraffe at this link: https://
blog.abacus.ai/blog/2023/07/2
7/treating-attention-deficit-disorder-in-llms/
…. -
Abacus AI Open-Sources Giraffe Long-Context Models
By
–
We are open-sourcing the models and the evaluation datasets and performance experiments. Git repository: https://
github.com/abacusai/Long-
Context
…. You can use the model directly from HuggingFace. 4k version: https://
huggingface.co/abacusai/Giraf
fe-v1-delta-13b-scaled-4
…. 16k version: https://
huggingface.co/abacusai/Giraf
fe-v1-delta-13b-scaled-16
…. -

ReLoRA Paper: Exploring LoRA for LLM Pretraining Beyond Finetuning
By
–
Just catching up with the ReLoRA paper (
https://
arxiv.org/abs/2307.05695) that explores whether LoRA can be used for pretraining LLMs (vs finetuning). Looks promising! Caveat: they pretrained models up to 350 M parameters (the smallest Llama model is 7 B parameters, for comparison) -
AI answers biased by left-leaning online text training data
By
–
The AI’s answers are purely a result of the training data it ingests (and tech companies aren’t specific about what was precisely included in the training corpus) You could argue that a preponderance of online text is slightly left-leaning, as those who are compelled to write
-
Removing dataset to ensure fair neural network method comparison
By
–
Thanks. And yeah, good call removing that dataset because especially NN methods would have an unfair advantage there