I don’t think there’s a restriction wrt to multimodal LLMs though (eg using techniques like LLaMA-Adapter v2). But yeah, the evaluation datasets won’t include images.
MACHINE LEARNING
-
Positional Encoding and Attention Mechanisms in Neural Networks
By
–
Hm good point and not sure. The positional encoding might not be required (there was a paper on that recently referred to as NoPE). Attention mechanisms I’d say are a generalization of MLPs (they could learn uniform weights if that’s useful). So I’d tend to say no.
-
Transformer publication timeline close to Bahdanau attention
By
–
Ah no! Interesting, I didn’t know it was published only 1 month after Bahdanau attention for RNNs
-
Survey of Consciousness Theories and Potential for Conscious AI
By
–
A nice survey of several prominent theories of consciousness, including recurrent processing, global workspace, higher-order, predictive processing, and attention schema theories. They claim there are “no obvious barriers to building conscious AI systems”. https://
arxiv.org/abs/2308.08708 -
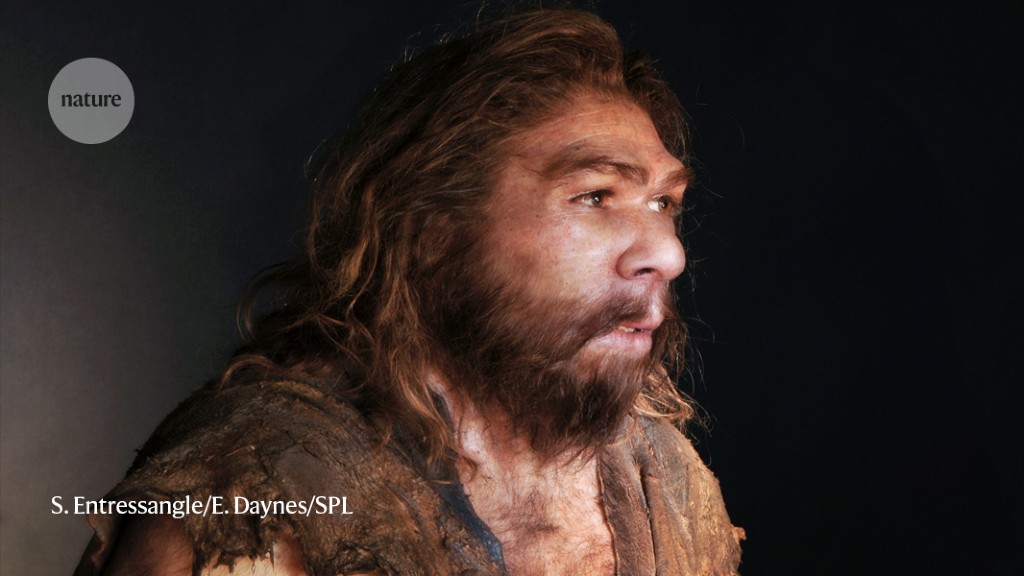
AI Resurrects Extinct Neanderthal Antibiotics Through Protein Analysis
By
–
AI search of Neanderthal proteins resurrects ‘extinct’ antibiotics https://
go.nature.com/3DM2zit #AI #MachineLearning #DeepLearning #LLMs #DataScience -
What retrieval areas deserve more research focus?
By
–
What areas of retrieval are most interesting to folks and we should push more on?
-

AI Is Forever Changing Our Jobs And Reinventing Work
By
–
AI Is Forever Changing Our Jobs And Reinventing The Way We Work
#AI #AIio #BigData #ML #NLU #Futureofwork @TopCyberNews @SpirosMargaris @MarshaCollier @MHiesboeck
@MHcommunicate @Fisher85M @MikeQuindazzi @NealSchaffer
http://
ow.ly/iO7v30swOuP -

Boston Dynamics founder says today’s robots are ‘as dumb as doorknobs’
By
–
FYI on 8/9/23, Boston Dynamics founder Marc Raibert: "Robots today are really stupid. They're as dumb as doorknobs…I think there's a future where the robots are smarter, & they use that intelligence to make it easier (for us) to have them do their task & to communicate w them."
-
Self-Attention Mechanisms in Transformers: From RNNs to LLMs
By
–
What motivated self-attention mechanisms in transformer-based LLMs in the first place?
— Sebastian Raschka (@rasbt) 21 août 2023
A made a short video covering
– the limitations of RNNs
– the original (Bahdanau) attention mechanism for RNNs,
– how it all led to the original Transformer architecture used in LLMs https://t.co/oMLNlJMef6What motivated self-attention mechanisms in transformer-based LLMs in the first place? A made a short video covering
– the limitations of RNNs
– the original (Bahdanau) attention mechanism for RNNs, – how it all led to the original Transformer architecture used in LLMs -
Mixed-Precision Training: Easy to Enable, High Impact Results
By
–
Awesome, glad to hear that helped. What’s nice is that mixed-precision training it’s so easy to enable but can have a huge impact in practice 🙂