GPT-2 is the "hello world" of LLMs I think (there must be a better analogy… err MOS 6502? xv6?), so that's why I started there. And it has a proper paper, weights released and available, and a lot is known about it. At this point it is an artifact of historical significance.
MACHINE LEARNING
-
GPT-2 Weight Initialization and Fine-tuning Strategy
By
–
atm we're doing init from gpt-2 weights and finetuning. this was very useful for debugging and when the code was slower. there is no code yet to init from scratch, so no code to warmup the lr etc. should be a very short addition though.
-
Lack of Public Documentation in AI Implementation Practices
By
–
That sounds like it would work in theory, I'd love to see documented examples with live demos of people doing that in practice I get the impression that people who do this rarely share their results publicly, which is a shame
-
Synthesizing AI Responses with RAG Pipelines and SFT Models
By
–
It can be done: Gather any available real query examples, add in synthetic Q’s derived from docs. Synthesize responses using RAG pipeline. SFT (a smaller model) on resulting Q&A’s, without RAG context. Whether it saves any money is another question.
-
Fine-tuning GPT-3.5: Use Cases and Community Experiences
By
–
Using https://
platform.openai.com/docs/guides/fi
ne-tuning
… ? What have you used that for – I've not heard many examples of people fine-tuning 3.5 -
torch.compile uses Triton kernels under the hood for optimization
By
–
So if you're using torch.compile you're already using a lot of triton under the hood, afaik PyTorch picks and chooses whether to call cuda kernels or triton for different ops / settings. Triton is really awesome, but of course you're staying in the Python / torch universe. Which
-
llm.c Matches PyTorch Performance Training GPT-2 on GPU
By
–
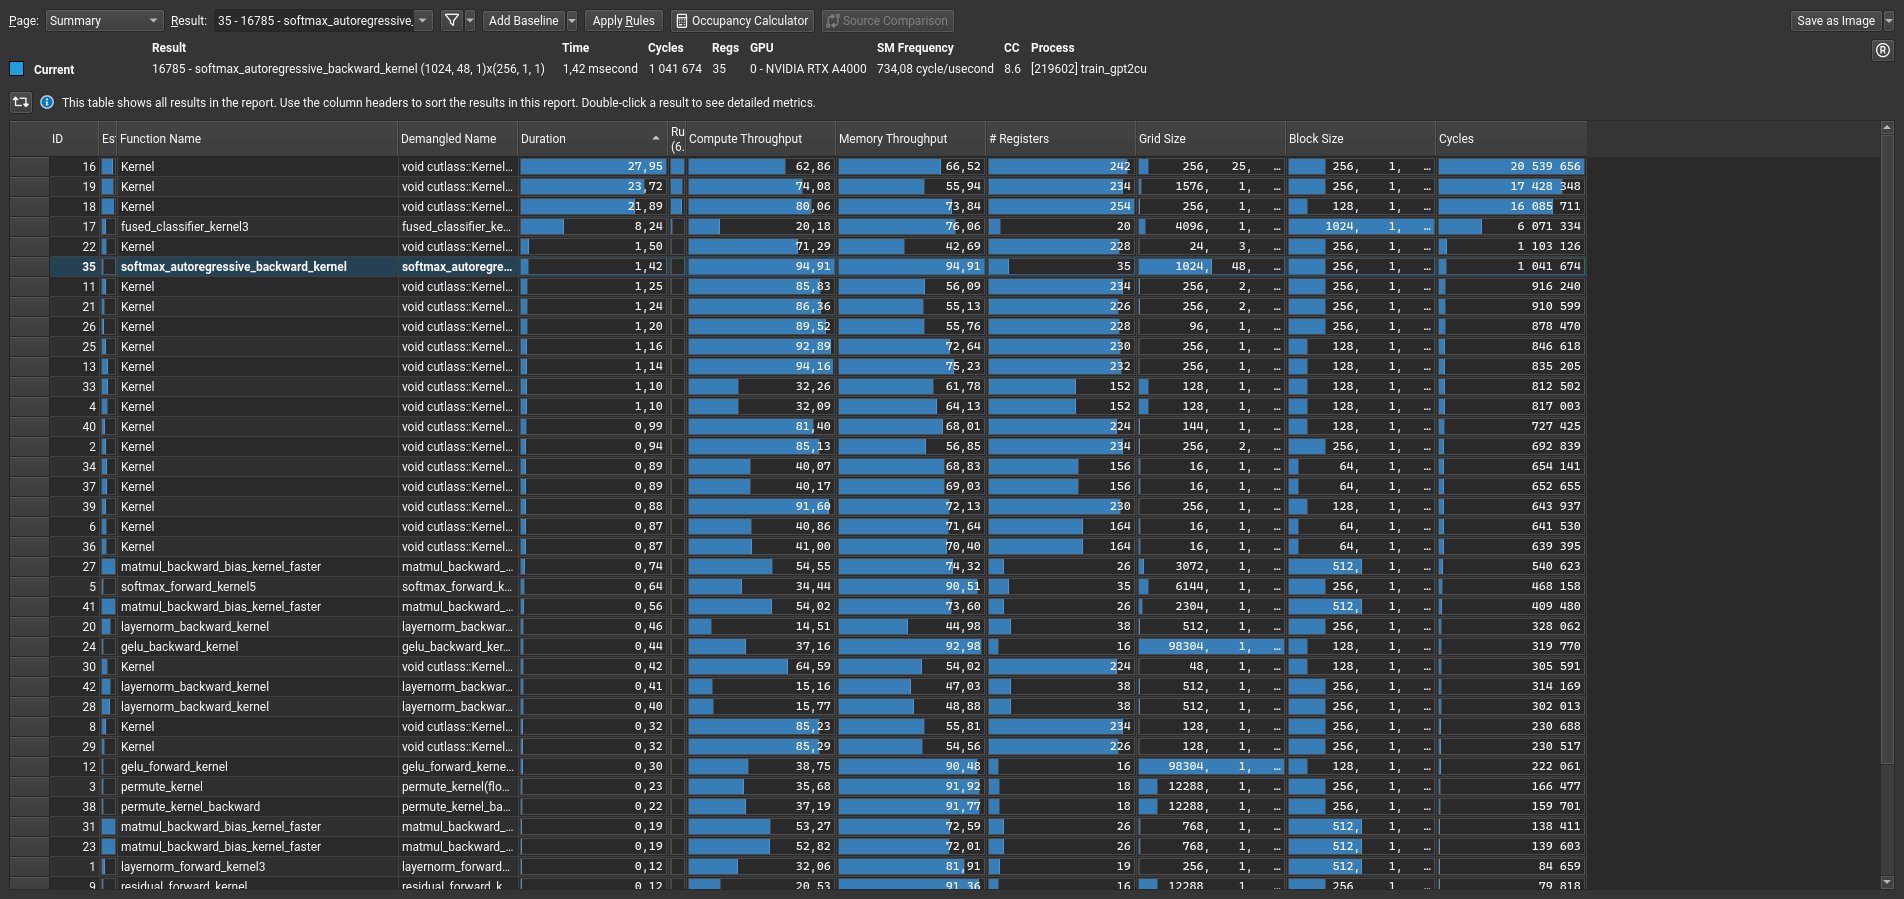
llm.c update: Our single file of 2,000 ~clean lines of C/CUDA code now trains GPT-2 (124M) on GPU at speeds ~matching PyTorch (fp32, no flash attention) https://
github.com/karpathy/llm.c
/blob/master/train_gpt2.cu
… On my A100 I'm seeing 78ms/iter for llm.c and 80ms/iter for PyTorch. Keeping in mind this is fp32, -
Wayfair Improves Model Accuracy 20+ Points Using Snorkel
By
–
If you missed our session with Wayfair and Google Cloud at Google Next '24… Register for our webinar on April 25 to learn how Wayfair leveraged Snorkel to label millions of images in months and improved the accuracy of their models by 20+ points. https://
buff.ly/4aXqt9w -

KRAS Cancer Mutations Now Druggable With AI Advances
By
–
Not many years ago we had no treatments vs KRAS driver mutations for cancer. Considered undruggable. Now look! https://
nature.com/articles/s4159
1-024-02903-0
… @NatureMedicine @EileenMOReilly @MSKCancerCenter -
Fine-tuning vs RAG: When to Use Each Approach
By
–
That's not the same as believing that fine tuning can't teach a model new knowledge under any circumstances – but in practice many people I see who think they need to fine tune a model would be better off using RAG instead