It's worth noting that this code specifically trains GPT-2.
PyTorch trains anything under the sun.
MACHINE LEARNING
-
GPT-2 Training Code vs PyTorch’s Universal Capability
By
–
-
Fused Classifier Kernel: Algorithmic Improvement Beyond Torch Compile
By
–
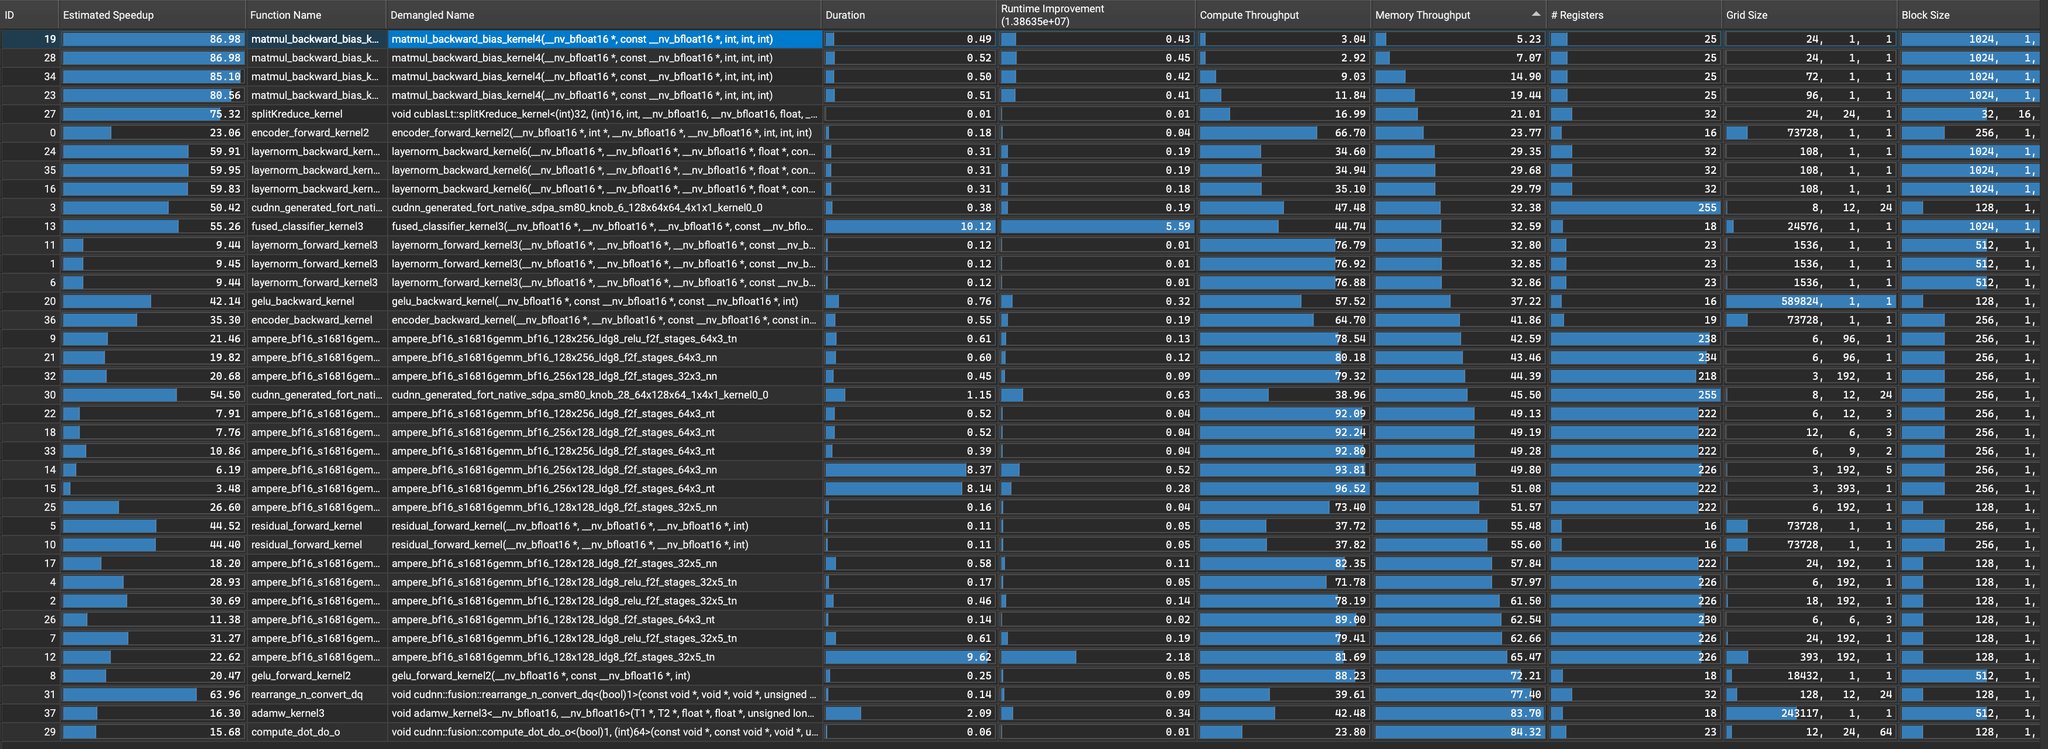
this is exactly what we're doing in the fused classifier kernel, and this is an *algorithmic* improvement on top of today's torch compile, which doesn't do this
-
GPU and Disk Constraints: Need for Smaller Dataset Variants
By
–
I'm not only GPU poor but disk poor too. 350GB?
(And ofc doing so wouldn't be representative of the full data distribution)
Also while replying, ideally there could be a "dataset miniseries", e.g. 1B, 10B, 100B, and then full. I think would be very helpful and bandwidth saving. -
cuBLASLt and cuDNN Dependencies for Optimized Performance
By
–
Yes, cuBLASLt for gemms, cuDNN for flash attention
The fp32 version will become more educational and will delete these dependencies. The "mainline" version we just want to be really fast, so we're less discriminating. cuBLASLt I think is ~ok dep, but cuDNN turned out surprisingly -
llm.c Day 24: Multi-GPU Training in C/CUDA Outperforms PyTorch
By
–
Day 24 of llm.c: we now do multi-GPU training, in bfloat16, with flash attention, directly in ~3000 lines of C/CUDA, and it is FAST! We're running ~7% faster than PyTorch nightly, with no asterisks, i.e. this baseline includes all modern & standard bells-and-whistles: mixed
-
Weak Supervision in AI: Automation and LLM Integration
By
–
Explore the future of weak supervision in AI and get in-depth insights on automating the weak supervision pipeline, multimodal integration, and the intersection of weak supervision with large language models. https://
buff.ly/4b0h9BS -

Building the Fastest and Most Efficient Fine-Tuning Stack
By
–
What does it take to build the #fastest, most #efficient fine-tuning stack? We got answers! Join our deep dive to learn: Latest fine-tuning #optimization techniques Metric driven analysis of each optimization How to get started on your own https://
pbase.ai/3Wq2ATG -
End-to-end learning robotics: Beyond the hype cycle
By
–
End to end learning for robotics is in a bit of a hype cycle but proponents sometimes miss the fact that practical results are not just end to end learning. As UC Berkeley Professor @Ken_Goldberg points out in this clip from a recent talk he gave at Stanford, Good Old Fashioned
-
How Large Language Models Work: Visual Explanation
By
–
How LLMs work, clearly explained with visuals: pic.twitter.com/ujKeJrw5Lf
— Sumanth (@Sumanth_077) 3 mai 2024How LLMs work, clearly explained with visuals:
-
Selective Model Weight Updates for Production AI Systems
By
–
Definitely a promising direction, but it doesn't look to me like that technique is useful for production scenarios yet Being able to selectively update model weights to tell a model "the new CEO of Fiat is X" would indeed be incredibly useful if it was fully reliable