We can easily build objectives for chess search trees, because: the complete state of the world is represented by a type known at compile-time; and we can handwrite a function to say exactly what states of the world we want, as described by that known representation. An AGI
MACHINE LEARNING
-
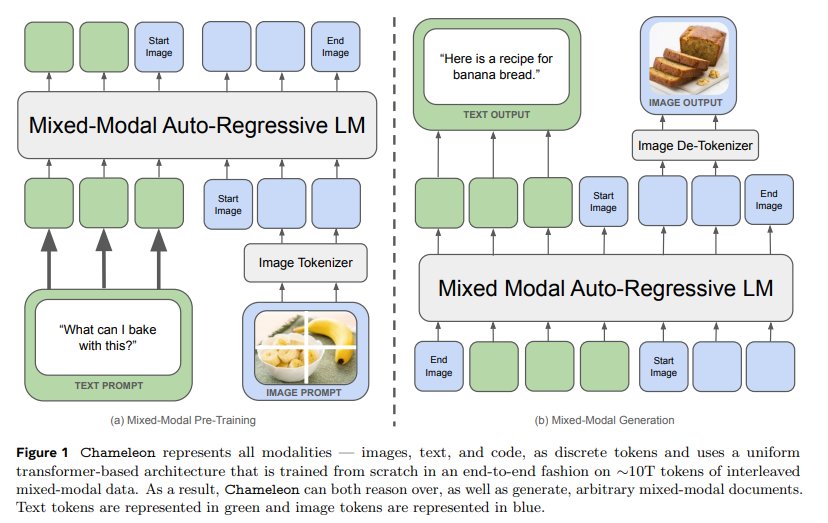
Gato Architecture: The Future of Multimodal AI Models?
By
–
Meta Chameleon and Gemini have also adopted the Gato ( https://
arxiv.org/pdf/2205.06175 ) architecture. Is this going to be the ultimate approach for MIMO (multimodal input multimodal output models) or is there something else we should be trying? There’s been great progress in scaling -
Unconstrained Solution Search in Natural Selection and SGD
By
–
Solving some outer reward or loss via a process that looks around for solutions and isn't much constrained or much legible in which solutions it finds. Natural selection and stochastic gradient descent are both examples.
-

DataRobot Delivers Fastest Path to AI Value for Users
By
–
Looking for the highest return on your AI investments? DataRobot delivers the fastest path to value with AI, making AI more accessible and eliminating complexities and siloes across the AI lifecycle. Hear from our users on @Gartner_inc Peer Insights https://
gartner.com/reviews/market
/data-science-and-machine-learning-platforms/vendor/datarobot/product/datarobot-ai-platform/review/view/5119012
… -

Cerebras Invites Researchers to Collaborate on Sparse Model Research
By
–
(9/n) If you are looking to conduct research into surpassing dense models with sparsity, contact us to collaborate! http://
cerebras.net/contact-us -
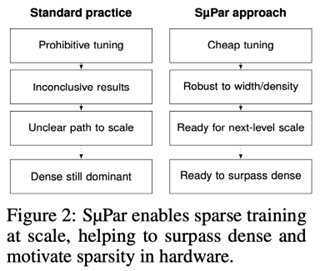
SμPar Eliminates Hyperparameter Detuning in Sparse Models
By
–
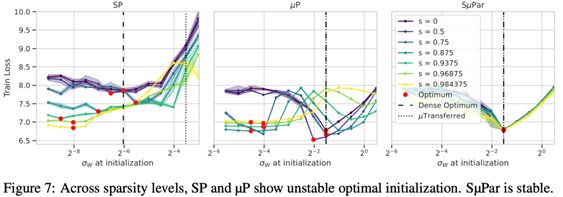
(8/n) Using dense optimal HPs, the SP and μP models experience detuning HPs as sparsity increases. This detuning is a confounding variable present in many existing sparse studies. SμPar eliminates this confounding variable and enables more robust sparsity studies.
-
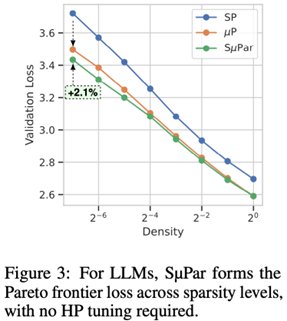
SμPar improves LLM pretraining loss over SP and μP
By
–
(6/n) Applying SμPar to pretraining a 610M parameter LLM significantly improves loss over SP and μP models due to improved HP tuning.
-
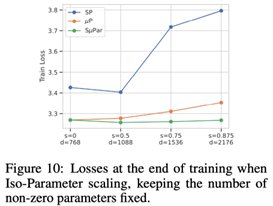
Sparse Iso-Parameter Scaling Achieves 87.5% Sparsity
By
–
(7/n) We test Sparse Iso-Parameter Scaling, where width and sparsity are increased, holding n_params constant. Using the standard practice (SP + dense optimal HPs), one would conclude only up to 50% sparsity help. Instead using SμPar allows an 87.5% sparse model to match dense
-

SμPar Extends μP for Sparse Neural Network Training
By
–
(4/n) We introduce the sparse maximal update parameterization (SμPar), which extends μP to also fix the vanishing activation problem with increasing sparsity.
-
SμPar Maintains Stable Hyperparameters Across Sparsity Width
By
–
(5/n) SμPar enables optimum hyperparameters to remain stable for any combination of sparsity and width, unlike SP and μP.