8). Z1 Z1 is a new method for making LLMs more compute-efficient at test time, especially during reasoning. It train LLMs with short and long code-based reasoning trajectories, and then dynamically adjusts reasoning depth during inference.
MACHINE LEARNING
-
Why LLMs Focus Attention on First Token
By
–
5). Why do LLMs Attend to First Token? This new paper explains why LLMs obsessively focus attention on the first token — a phenomenon known as an attention sink.
-
CodeScientist: AI System Autonomously Generates Tests Scientific Hypotheses
By
–
3). CodeScientist Researchers at AI2 release CodeScientist, a system that autonomously generates and tests scientific hypotheses via code-based experimentation.
-

RARE: New Reasoning-Focused LLM Training Paradigm
By
–
4). Retrieval-Augmented Reasoning Model Introduces RARE, a new paradigm for training domain-specific LLMs that focuses on reasoning, not memorization.
-
10M Token Processing and Infinite Context Length Breakthroughs
By
–
Wonder what compute times we will see with 10M input tokens on a rather beefy system. The NiH tests are also insane, It’s hard to believe we are moving towards infinite token context lengths with near perfect retrieval.
-

DeepSite: an ultra-high-performance AI that is 100% free surpasses Bolt and Manus
By
–
Forget Bolt, Manus AI and the others: here is DeepSite, an ultra-high-performance AI that is 100% free! The complete tutorial → https://youtu.be/l13s3lVNK4w #AITools #ArtificialIntelligence #Deepsite #Deepseek #DeepSeekv3
-
Running Large Models on Consumer GPUs: Parallelism and Quantization
By
–
I don't really use GPUs, as most of our work uses TPUs. I was just confused by @jeremyphoward 's statement that it wouldn't run on consumer GPUs, when the normal techniques of model parallelism, quantization, right compression, etc. seem like they should work just fine to run it
-
Study Questions Whether AI Models Truly Reason
By
–
Well this preprint’s title is already misleading because there is no evidence of “reasoning” in these models and even small changes in the benchmarks break and semblance of “reasoning.”
-

Llama 4 Scout and Maverick Powered by Llama 4 Behemoth Distillation
By
–
Llama 4 Scout and Llama 4 Maverick’s industry-leading performance is in large part thanks to distillation from Llama 4 Behemoth, our most powerful model yet. Be on the lookout for more details on Llama 4 Behemoth at a future date!
-
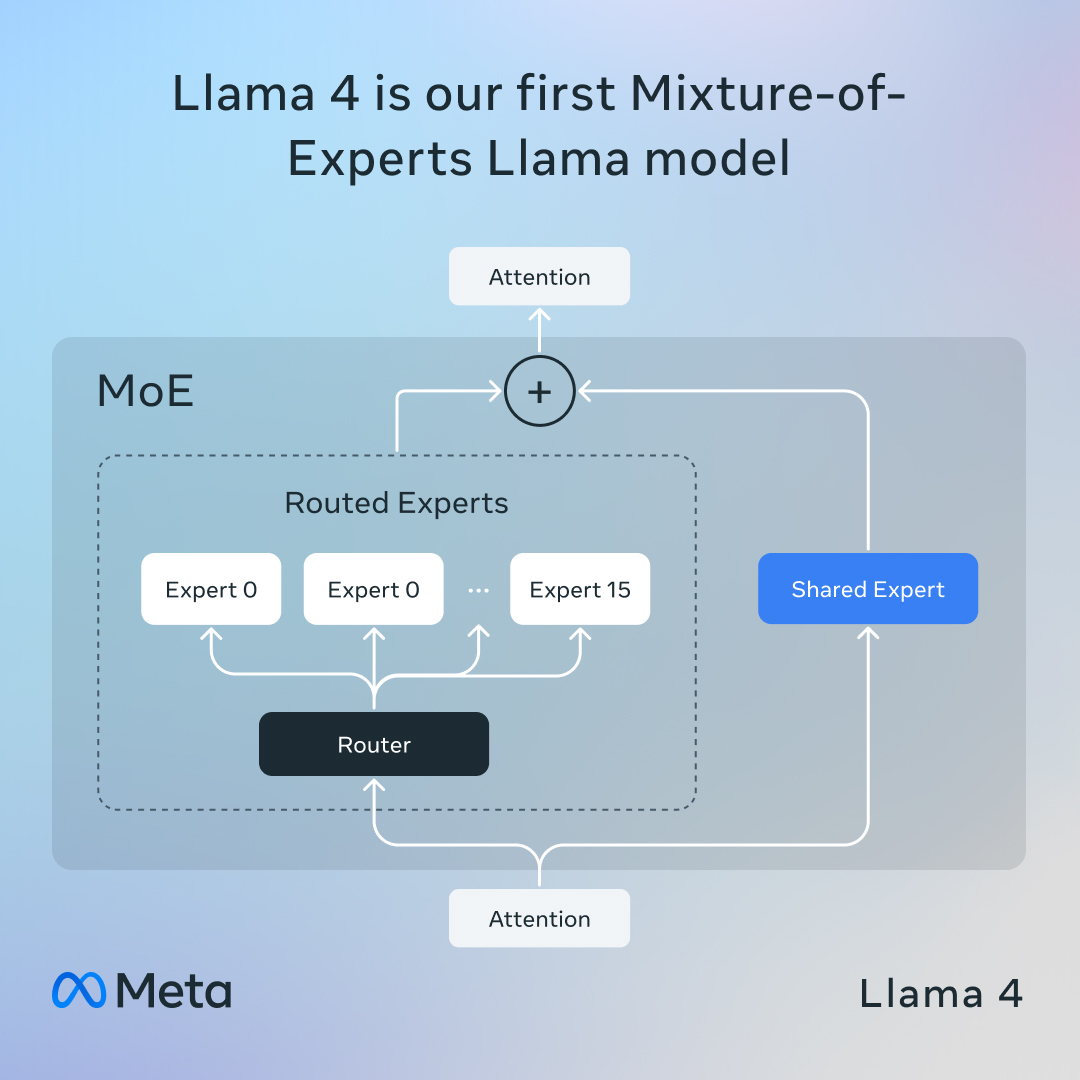
Llama 4: Mixture of Experts Architecture for Efficient Models
By
–
Llama 4 is our first collection of models built using a mixture of experts (MoE) architecture. This architecture is more compute efficient for model training and inference and delivers higher quality models compared to dense architectures.