
Chat-R1: Enhancing Spatio-Temporal Perception via Reinforcement Fine-Tuning This paper explores the use of Reinforcement Fine-Tuning (RFT) with Group Relative Policy Optimization (GRPO) to enhance spatio-temporal perception in video multimodal large language models (MLLMs),
MACHINE LEARNING
-

Language Model Size and Reasoning Capability Scaling Laws
By
–
Do Larger Language Models Imply Better Reasoning? A Pretraining Scaling Law for Reasoning This paper investigates the relationship between the size of language models (LLMs) and their reasoning abilities, focusing on a synthetic multi-hop reasoning task based on real-world
-

DeepResearcher: Scaling Deep Research via Reinforcement Learning
By
–
DeepResearcher: Scaling Deep Research via Reinforcement Learning in Real-world Environments DeepResearcher is a reinforcement learning framework that trains LLM agents to perform deep research through real-world web interactions, moving beyond static prompt or RAG-based
-

MedSAM2: Foundation Model for 3D Medical Image Segmentation
By
–
MedSAM2: Segment Anything in 3D Medical Images and Videos MedSAM2 is a foundation model for 3D medical image and video segmentation, extending SAM2 to support volumetric and temporal data across diverse clinical tasks. Problem: Existing segmentation models are mostly limited to
-

SmolVLM: Efficient Vision-Language Models for Edge Devices
By
–
SmolVLM: Redefining small and efficient multimodal models SmolVLM is a family of highly efficient, small-scale vision-language models (VLMs) engineered for low-memory, real-time multimodal inference on mobile and edge devices. These models achieve competitive or even superior
-
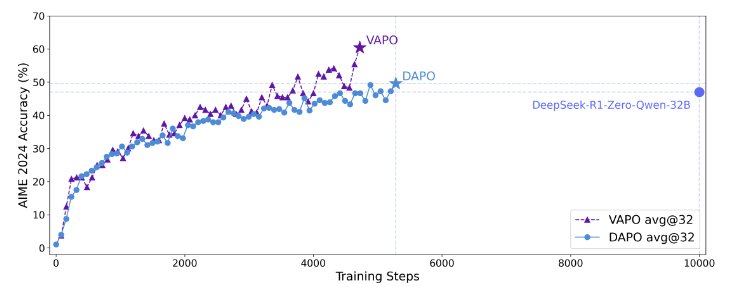
VAPO: Value-Based RL Framework for Advanced LLM Reasoning
By
–
VAPO: Efficient and Reliable Reinforcement Learning for Advanced Reasoning Tasks VAPO is a new value-based reinforcement learning framework designed to enhance long chain-of-thought reasoning in large language models. Built upon Qwen2.5-32B, it outperforms existing methods in
-

SWiRL: Synthetic Data and RL for Language Model Reasoning
By
–
Synthetic Data Generation & Multi-Step RL for Reasoning & Tool Use This paper introduces Step-Wise Reinforcement Learning (SWiRL), a method for improving multi-step reasoning and tool use in language models through synthetic data generation and offline RL. Problem: Standard RL
-

Test-Time Training Enables One-Minute Video Generation
By
–
One-Minute Generation with Test-Time Training This paper augments Transformers with Test-Time Training (TTT) layers—neural networks used as hidden states—to generate coherent one-minute videos from text storyboards. Problem: Long video generation is bottlenecked by
-

Top 10 Papers: Video Generation and Multimodal AI Models
By
–
Huge week for video generation and multimodal models, with detailed one-minute video generation and more efficient approaches to multimodality Check out the top 10 papers for the week – Hogwild! Inference: Parallel LLM Generation via Concurrent Attention
– One-Minute -

DataAISummit 2026: 700+ Sessions on Data, AI, and Analytics
By
–
Join #DataAISummit for access to 700+ sessions on data intelligence, data warehousing, AI, governance and more! Register now to secure your spot at the world’s largest data, analytics and AI conference. Register now – early bird ends April 30! Here’s a preview of the sessions