I couldn't have built https://
alignednews.com/ai without vibe coding. It might be gone in 24 months. Change is constant. But vibe coding is real and is just at the beginning.
MACHINE LEARNING
-
Vibe coding enables AI site, but change is inevitable
By
–
-
Capabilities learned not inherited: building from ground up
By
–
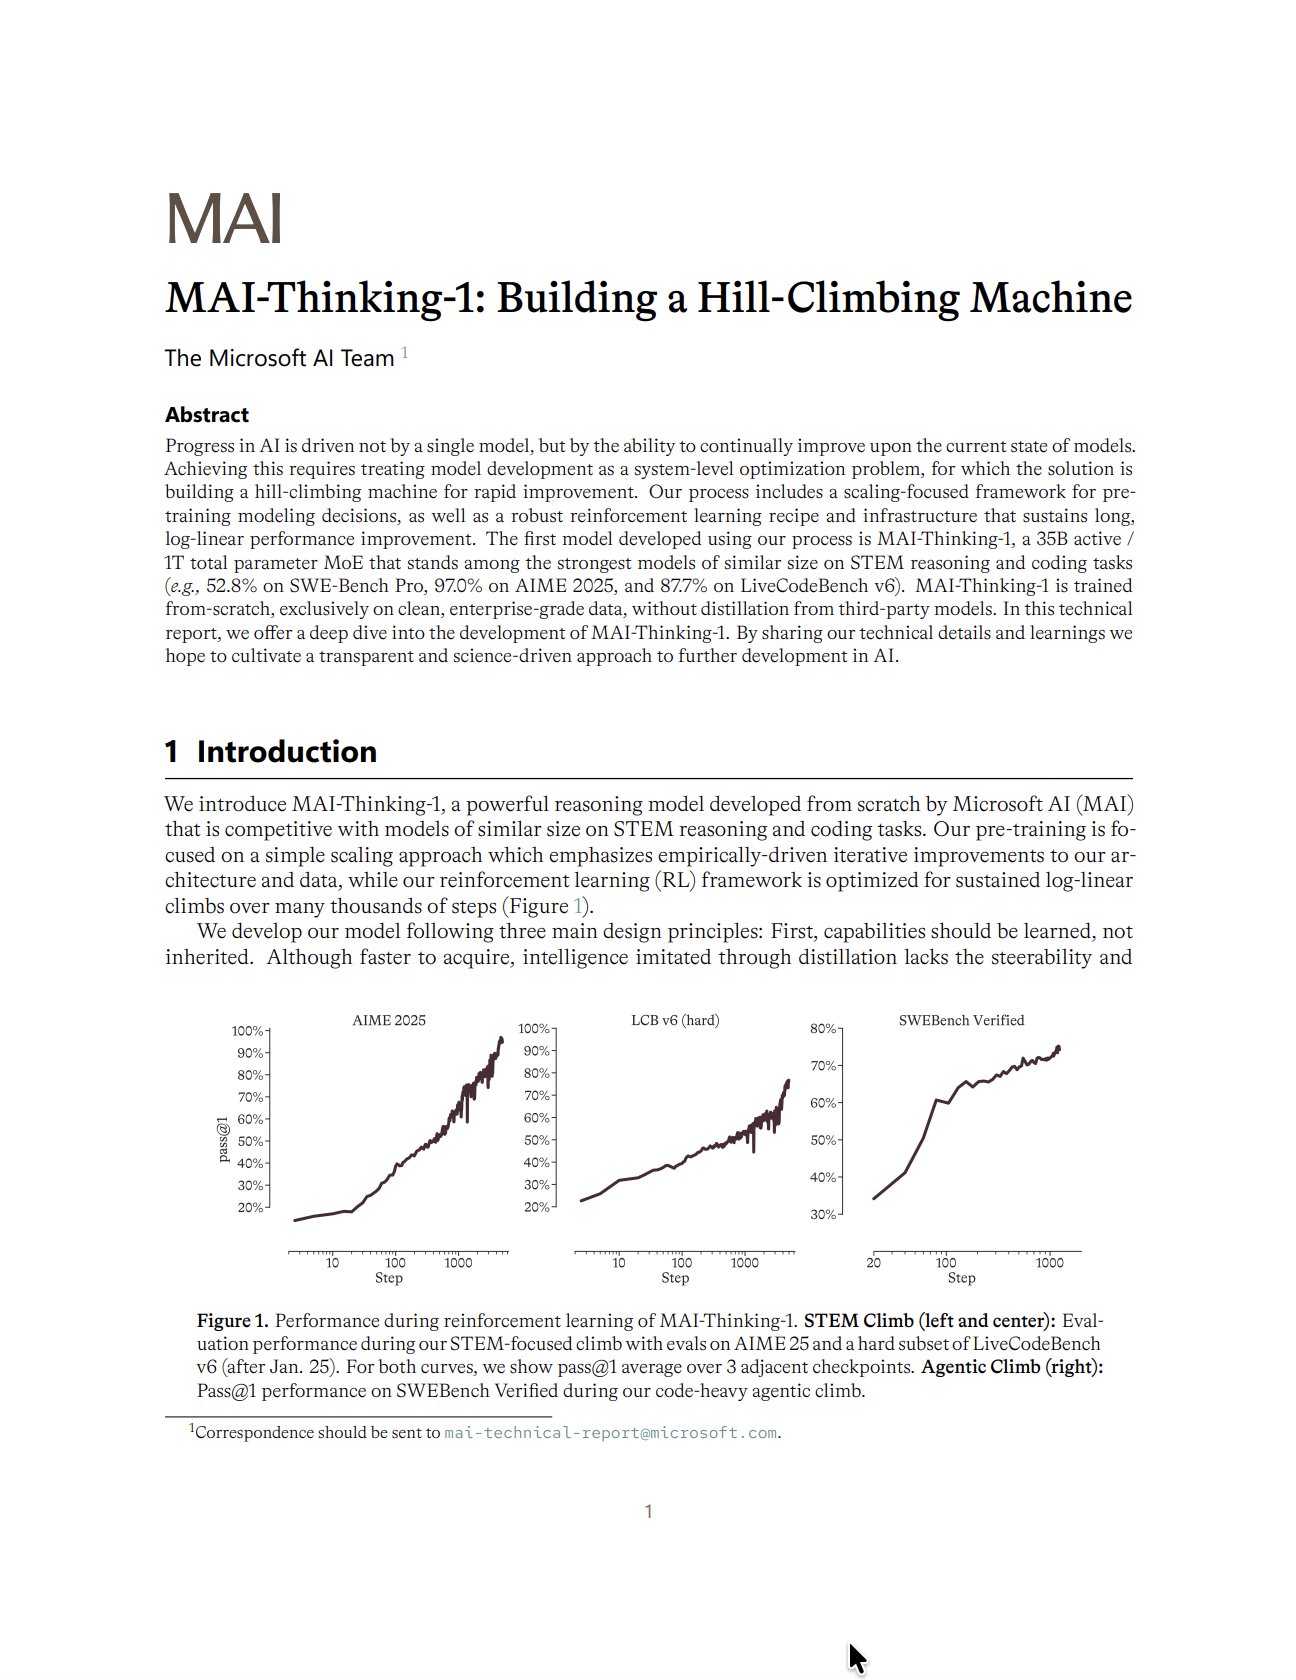
The phrase “capabilities should be learned, not inherited” is doing a lot of work here. It draws a clear line between imitating intelligence through distillation and building the internal machinery to generate, evaluate, and improve capabilities from the ground up. That
-
Microsoft AI’s MAI-Thinking-1: Progress is a model-improving machine
By
–
AI progress is not a model. It is a machine that keeps improving models. That is the core idea behind Microsoft AI’s new technical report: MAI-Thinking-1: Building a Hill-Climbing Machine This is not just a model release. It is a blueprint for turning frontier model
-
Learned vs. Inherited Capabilities: Distillation vs. Ground-Up Intelligence
By
–
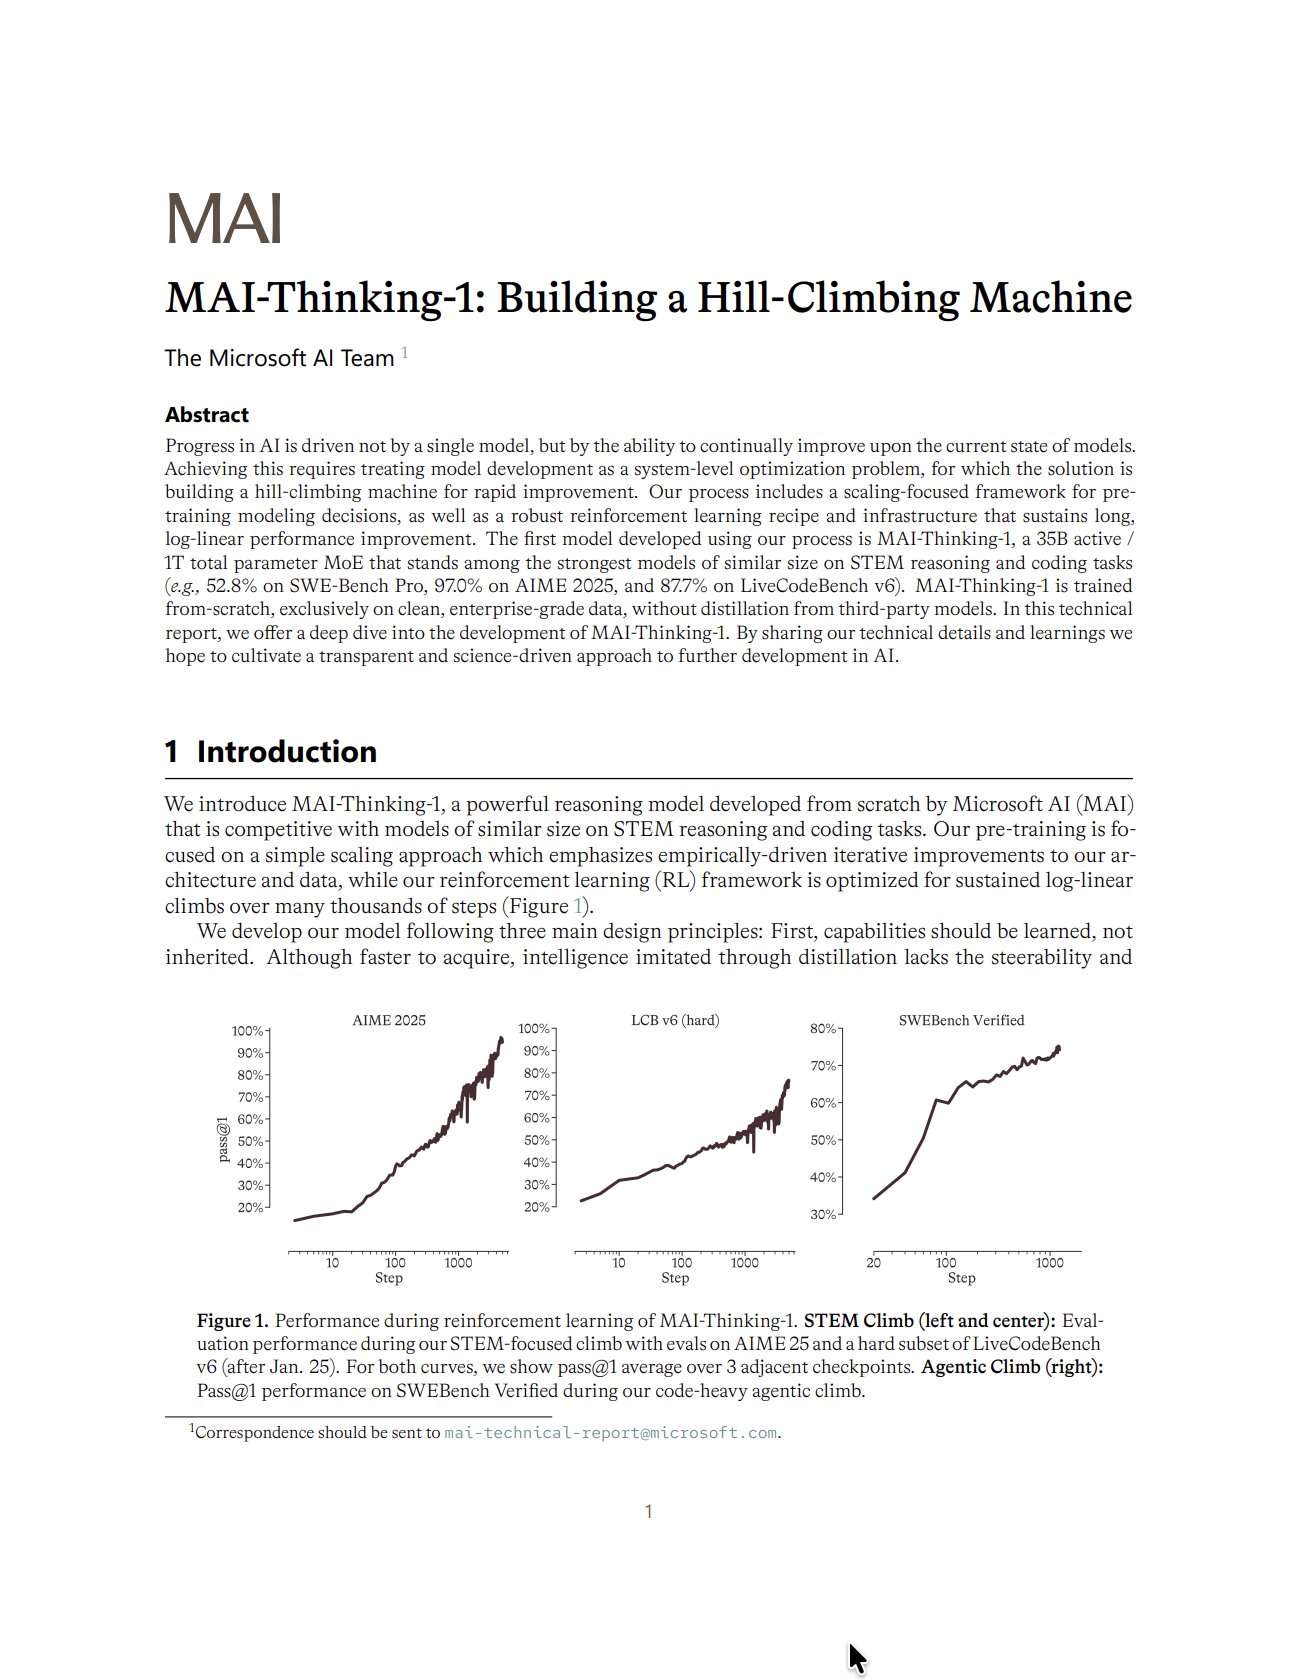
The phrase “capabilities should be learned, not inherited” is doing a lot of work here. It draws a clear line between imitating intelligence through distillation and building the internal machinery to generate, evaluate, and improve capabilities from the ground up. That
-
Microsoft AI’s MAI-Thinking-1: A Hill-Climbing Machine for Frontier Models
By
–
AI progress is not a model. It is a machine that keeps improving models. That is the core idea behind Microsoft AI’s new technical report: MAI-Thinking-1: Building a Hill-Climbing Machine This is not just a model release. It is a blueprint for turning frontier model
-
DeepSeek Sparse Attention reduces complexity from O(L²) to O(Lk)
By
–
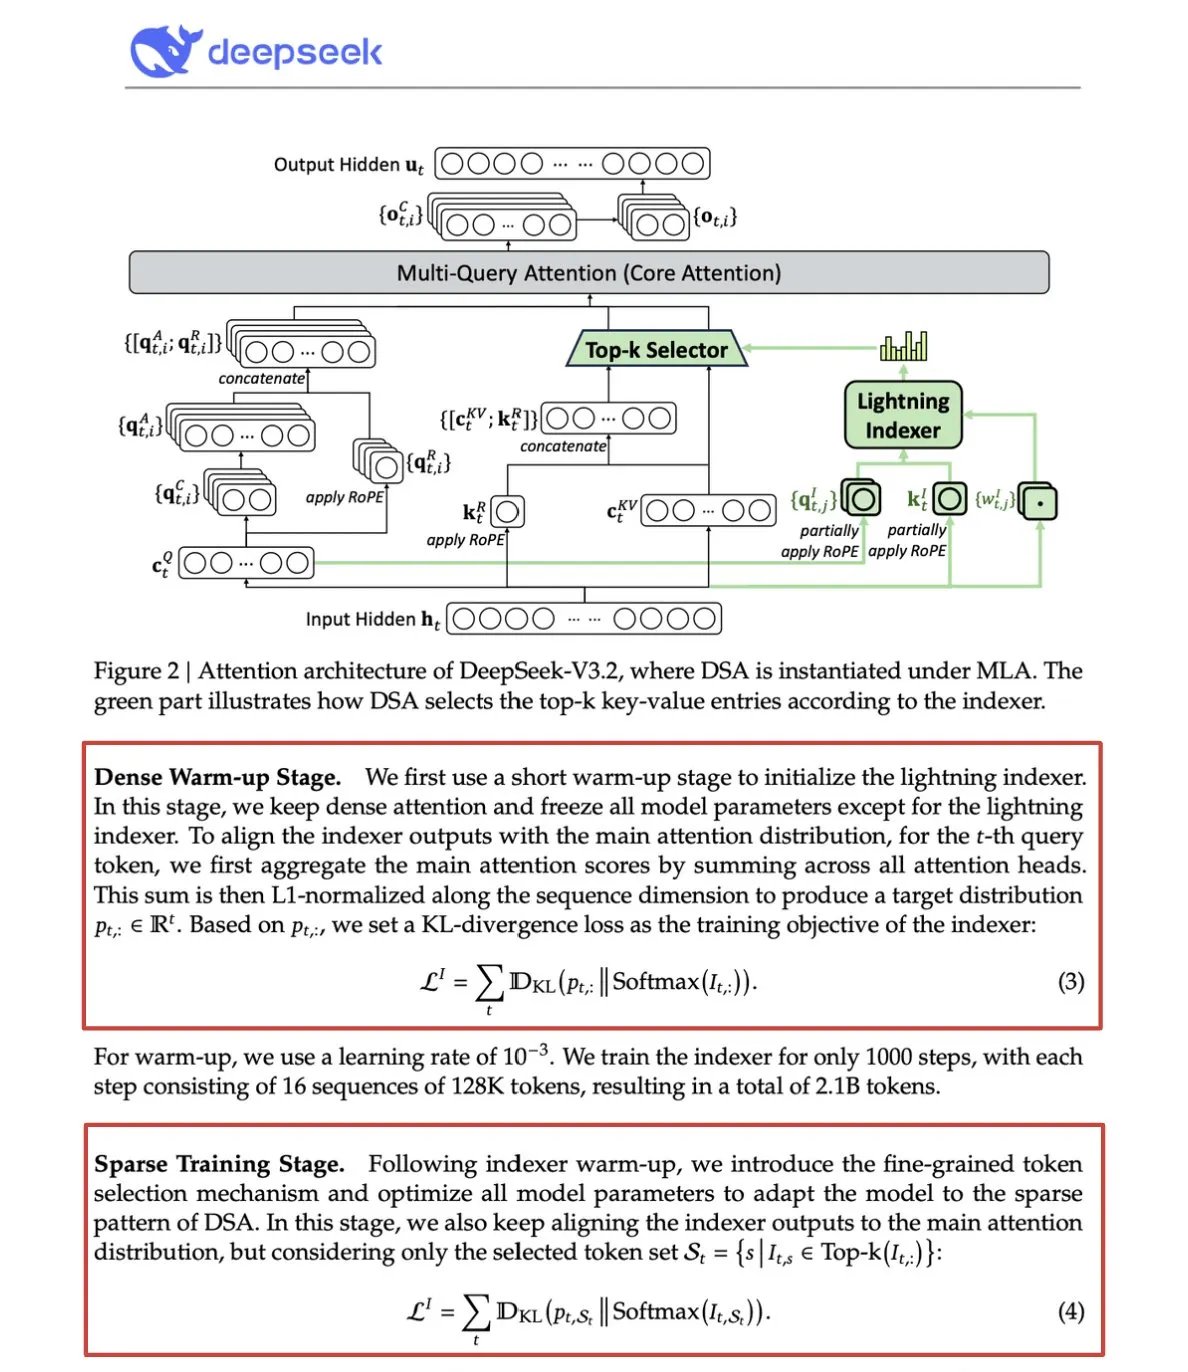
3) DeepSeek Sparse Attention (DSA) DeepSeek’s recently released V3.2 model introduced DeepSeek Sparse Attention (DSA), which brought complexity down from O(L²) to O(Lk), where k is fixed. How it works: A lightweight Lightning Indexer scores which tokens actually matter for
-
Flash Attention: Hardware-Level SRAM Caching Achieves 7.6x Speedup
By
–
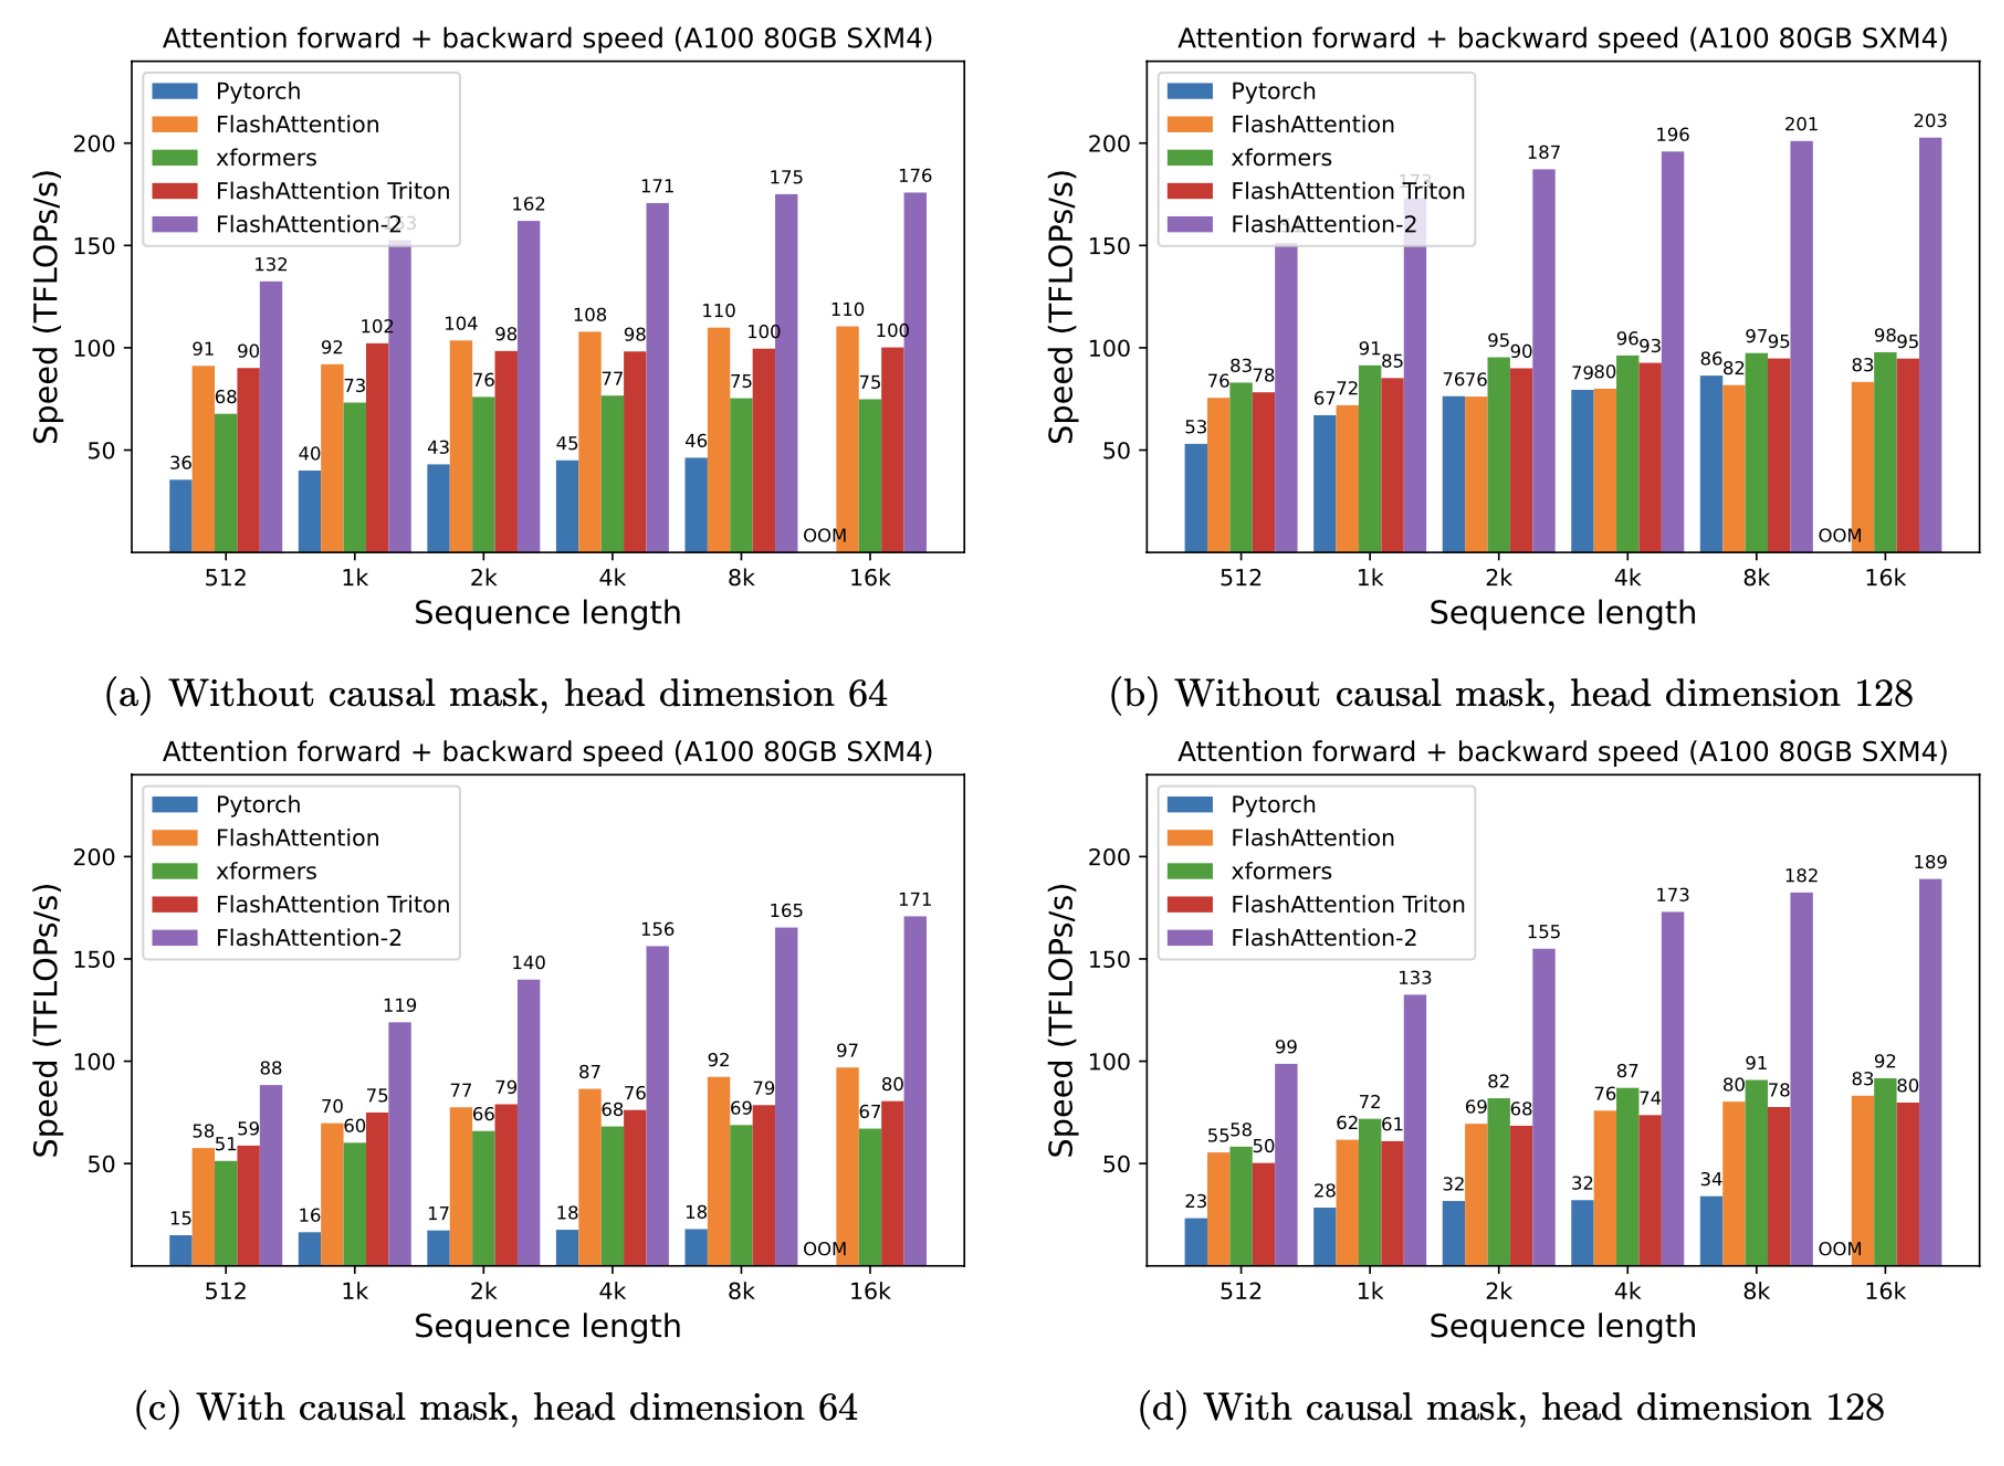
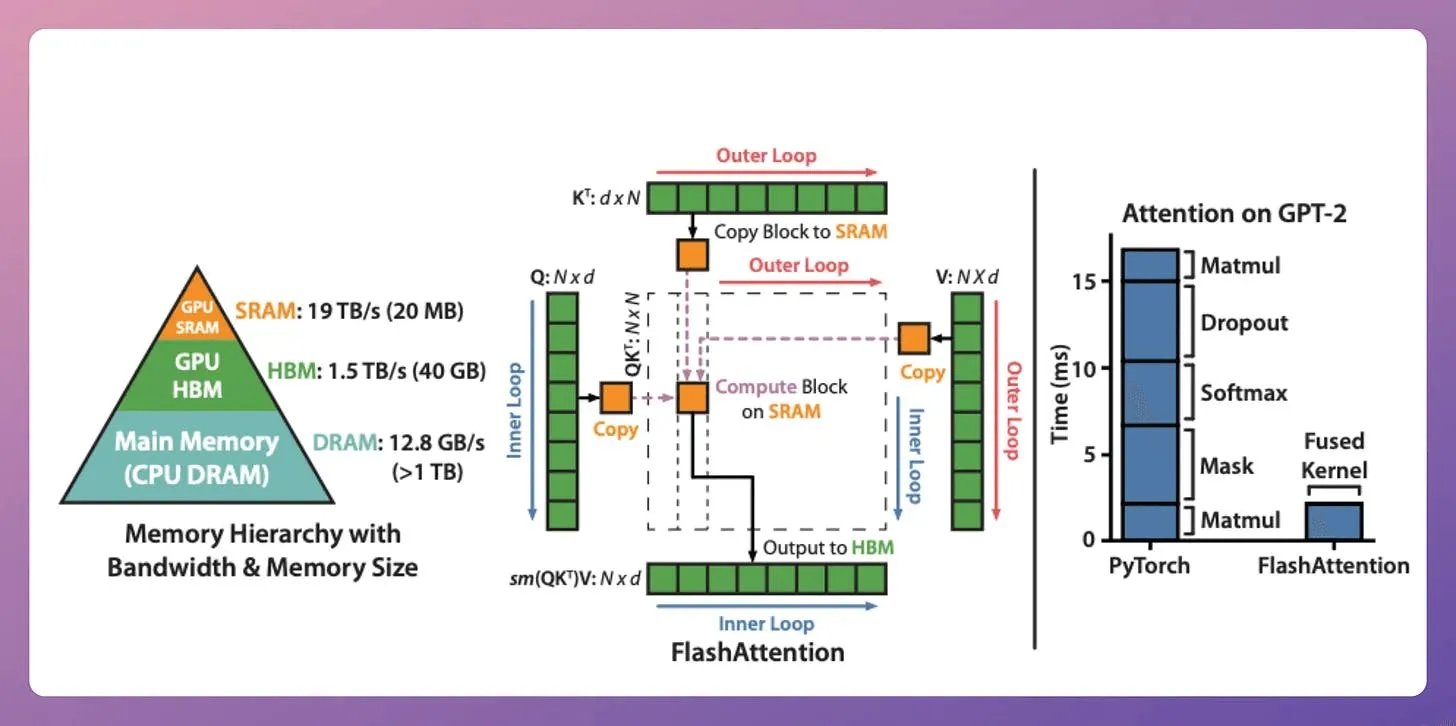
Flash attention involves hardware-level optimizations wherein it utilizes SRAM to cache the intermediate results. This way, it reduces redundant movements, offering a speed up of up to 7.6x over standard attention methods. Check this
-
Flash Attention: Efficient Global Attention via GPU Memory Optimization
By
–
2) Flash Attention This is a fast and memory-efficient method that retains the exactness of traditional attention mechanisms, i.e., it uses global attention but efficiently. The whole idea revolves around optimizing the data movement within GPU memory. Let's understand!
-
Local vs global attention in reading explained
By
–
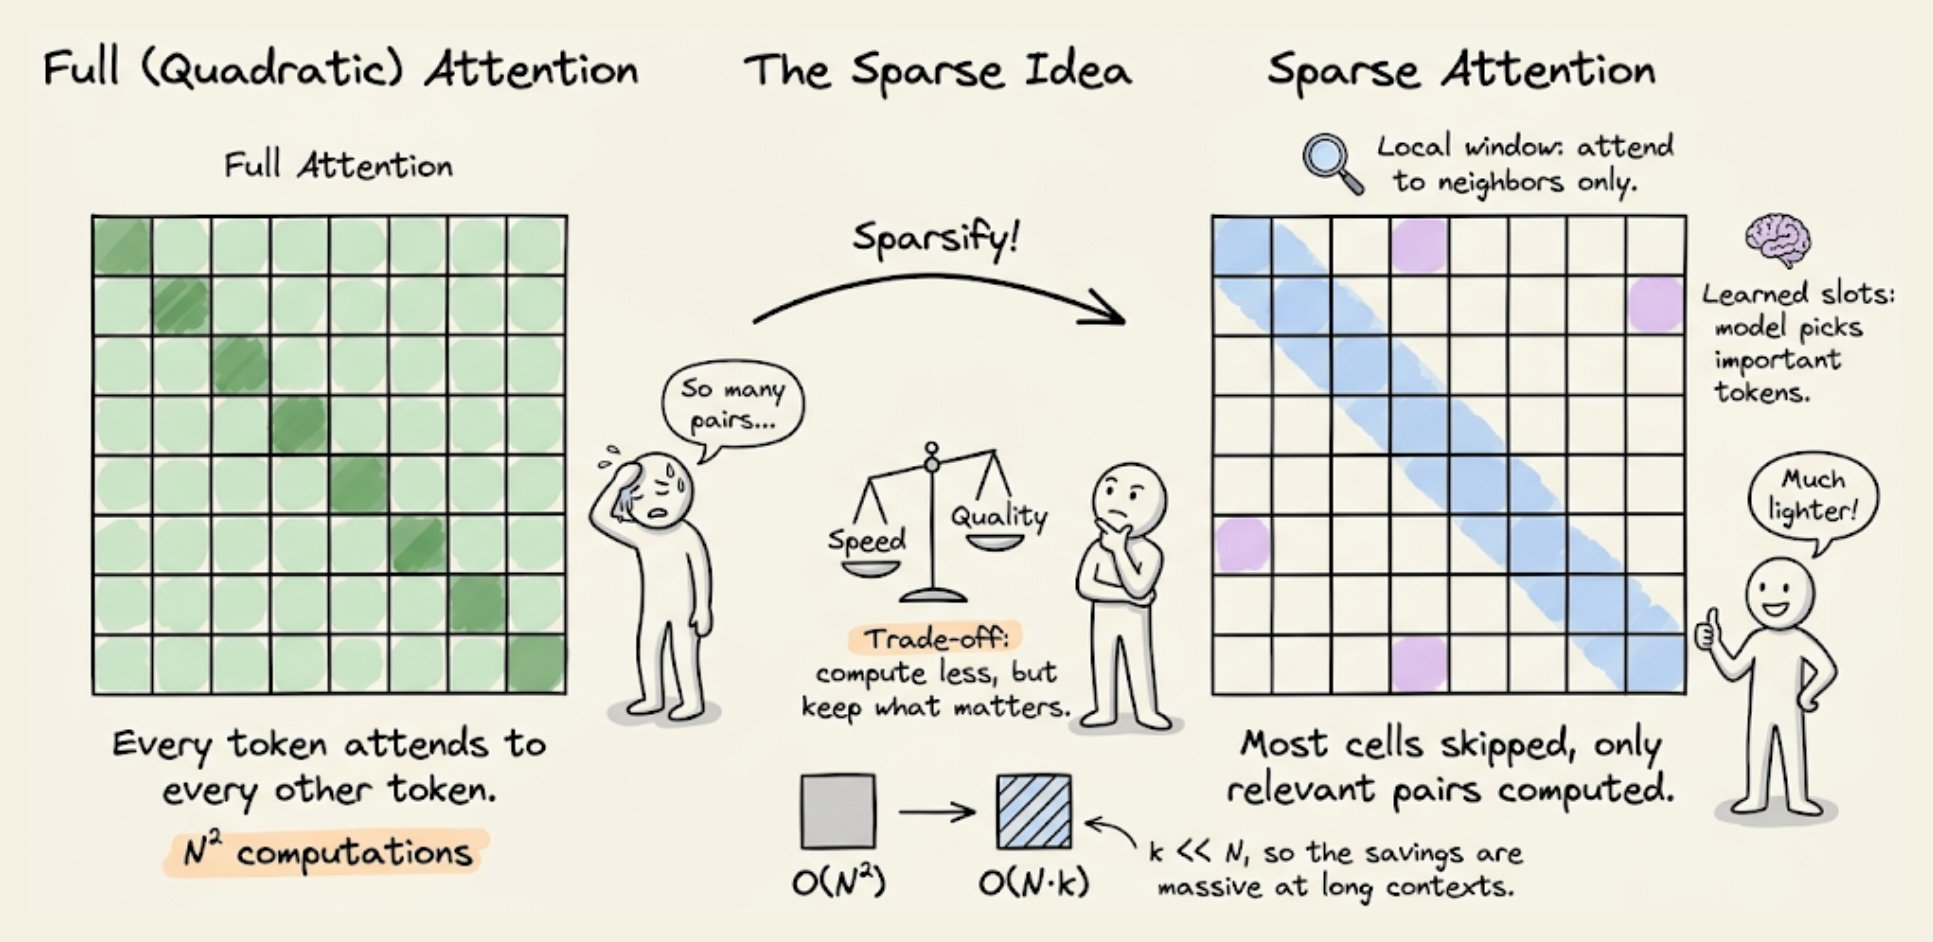
Here's an intuitive explanation taken from the paper: Picture yourself reading a book. For every sentence you read, do you need to be fully aware of the entire plot to understand most of it (full global attention)? Or is awareness of the current chapter enough (local
-
Sparse Attention: Local, Learned Focus with Trade-off
By
–
1) Sparse Attention It limits the attention computation to a subset of tokens by: – Using local attention (tokens attend only to their neighbors).
– Letting the model learn which tokens to focus on. But this has a trade-off between computational complexity and performance.