It turns out we can easily apply the material we’ve covered to get the policy gradient for fine tuning a diffusion model, see eg https://
arxiv.org/pdf/2305.13301 It becomes a multi step RL problem with the reward only happening at the end. It’s not very efficient I think, but I’d love to
MACHINE LEARNING
-
Policy Gradient for Diffusion Model Fine-tuning
By
–
-

Flow-GRPO: Online RL Integration into Flow Matching Models
By
–
Flow-GRPO: Training Flow Matching Models via Online RL This work introduces Flow-GRPO, the first method to embed online reinforcement learning into flow matching diffusion models. Two innovations drive it: 1. ODE → SDE conversion for richer, exploration-ready
-

ESS Measures Deep Learning Model Memory Efficiency
By
–
The performance of a Deep Learning model does not just depend on its size but on how well it makes use of its memory capacity (which in turn relates to its compressibility, destillability etc.). With ESS, LiquidAI finds a theoretically grounded measure for this
-
PyMuPdf drops figures; keeping images requires switching to VLM
By
–
Just PyMuPdf! So figures are dropped, a good direction for improvement would be to keep images, but then we'd need to switch to a VLM instead of LLM.
-
8K YOLOv8l inference on edge with tile-based processing
By
–
Rethinking high-res inference: Instead of downscaling, we split the 8K feed into hundreds of tiles—real-time, on the edge, with YOLOv8l on Metis. It’s about detail and performance, not one or the other. #EdgeAI #8K #YOLOv8 #AIInference #ComputerVisionhttps://t.co/9yDSoO14gz… pic.twitter.com/nPAQ68bR4v
— Axelera AI (@AxeleraAI) 9 mai 2025Rethinking high-res inference: Instead of downscaling, we split the 8K feed into hundreds of tiles—real-time, on the edge, with YOLOv8l on Metis. It’s about detail and performance, not one or the other. #EdgeAI #8K #YOLOv8 #AIInference #ComputerVision https://
community.axelera.ai/product-update
s/outperforming-the-ai-crowd-at-isc-west-with-8k-yolov8l-on-the-edge-153
… -
8K Real-time Edge AI Inference with YOLOv8 Tile Processing
By
–
Rethinking high-res inference: Instead of downscaling, we split the 8K feed into hundreds of tiles—real-time, on the edge, with YOLOv8l on Metis. It’s about detail and performance, not one or the other. #EdgeAI #8K #YOLOv8 #AIInference #ComputerVisionhttps://t.co/rlsdRN4CQW… pic.twitter.com/mFWIx2wyl2
— Axelera AI (@AxeleraAI) 9 mai 2025Rethinking high-res inference: Instead of downscaling, we split the 8K feed into hundreds of tiles—real-time, on the edge, with YOLOv8l on Metis. It’s about detail and performance, not one or the other. #EdgeAI #8K #YOLOv8 #AIInference #ComputerVision https://
eu1.hubs.ly/H0jZfmb0 -
Subscribe to AI Engineering Weekly Tutorials on ML and LLMs
By
–
If you're interested in ML, LLMs, and AI Agents and want to receive tutorials every week, subscribe to AI Engineering (for free): http://
aiengineering.beehiiv.com Github Repo to Docling: -
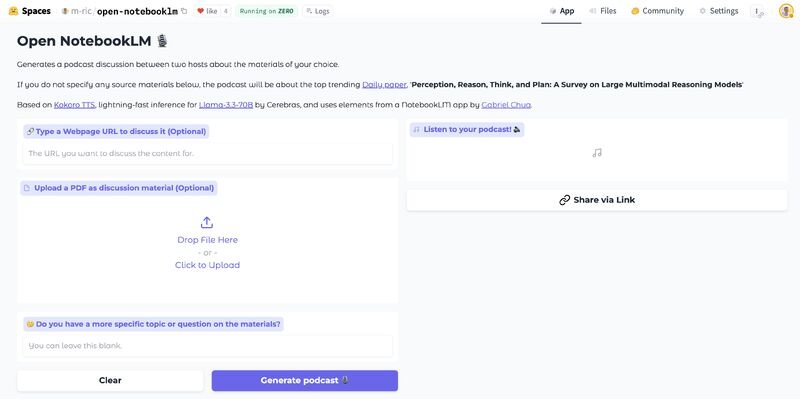
Open source NotebookLM alternative uses Llama 3.3-70B for podcasts
By
–
I've made an open and free version of Google's NotebookLM, and it shows how high the open source tech task has risen! The app's workflow is simple. Given a source PDF or URL, it extracts the content from it, then tasks @AIatMeta
's Llama 3.3-70B, with writing the podcast -

Toxic Data Improves LLM Post-Training Control and Separability
By
–
"Bad Data, Good Models?" A surprising take on LLM pretraining. This paper flips the script: pretraining with more toxic data can actually improve post-training control. Using Olmo-1B variants, the authors show that toxicity becomes more linearly separable—making
-

Elastic Reasoning: Smart CoT Control for Large Models
By
–
Controlling CoT in large reasoning models just got smarter. Elastic Reasoning decouples thinking and solution phases—allocating separate budgets to each. This means more reliable outputs under strict compute/token constraints . Trained with a lightweight, budget-aware