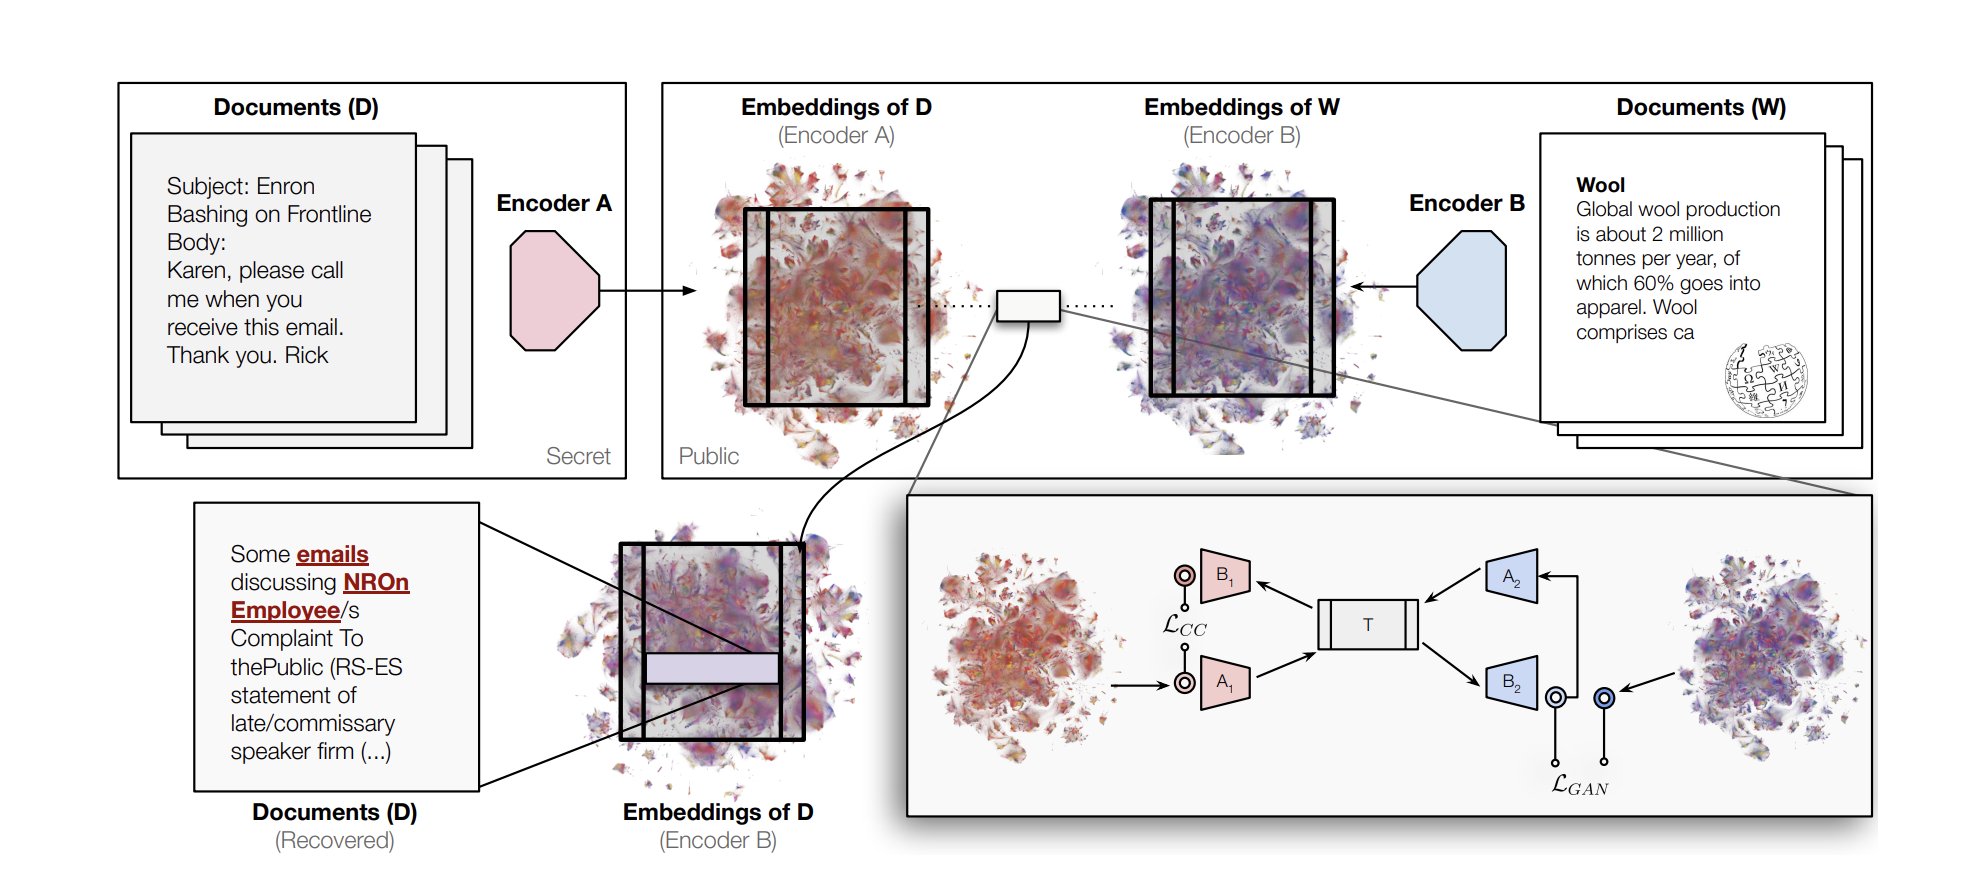
theoretically, the implications of this seem big. we call it The Strong Platonic Representation Hypothesis: models of a certain scale learn representations that are so similar that we can learn to translate between them, using *no* paired data (just our version of CycleGAN)
MACHINE LEARNING
-
Aligning AI Model Representations Through Structure Matching
By
–
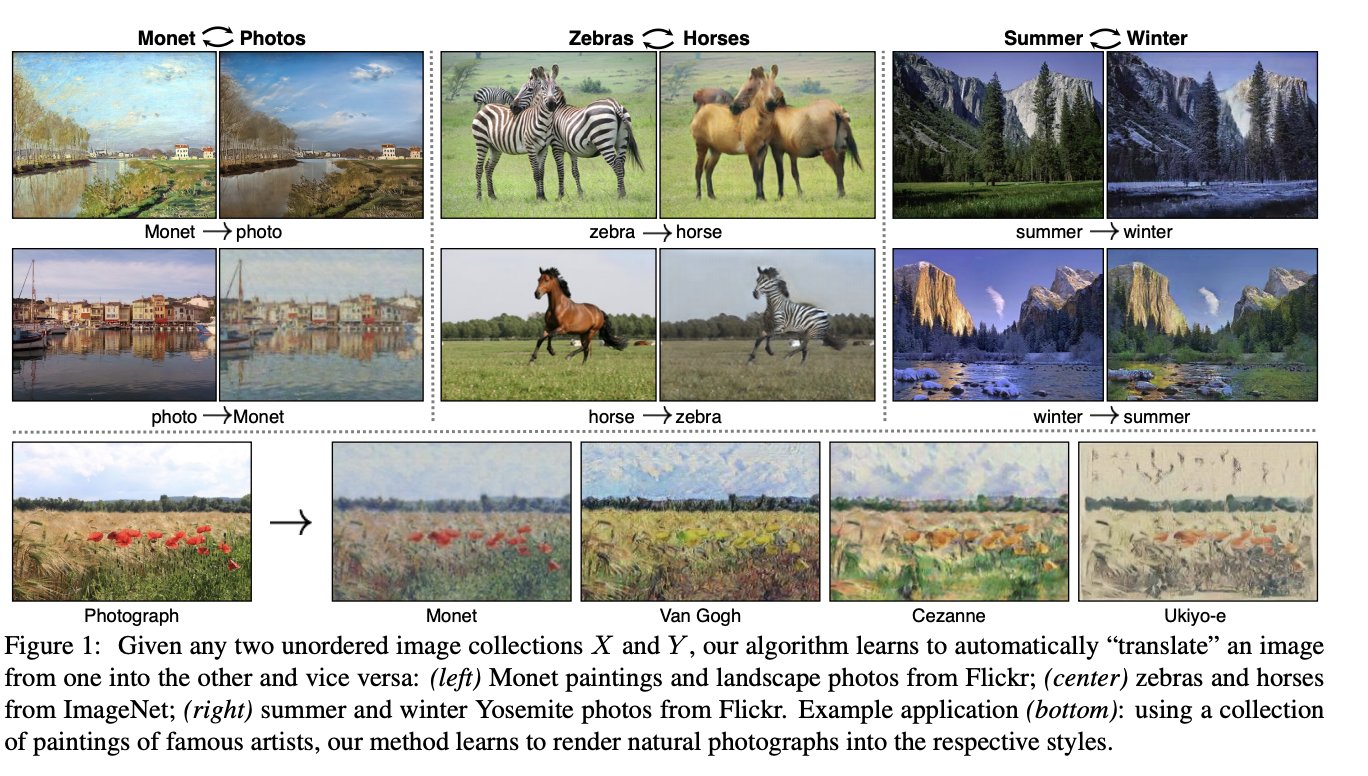
we take things a step further. if models E1 and E2 are learning 'similar' representations, what if we were able to actually align them? and can we do this with just random samples from E1 and E2, by matching their structure? we take inspiration from 2017 GAN papers that
-
GAN Training for Cross-Model Embedding Alignment
By
–
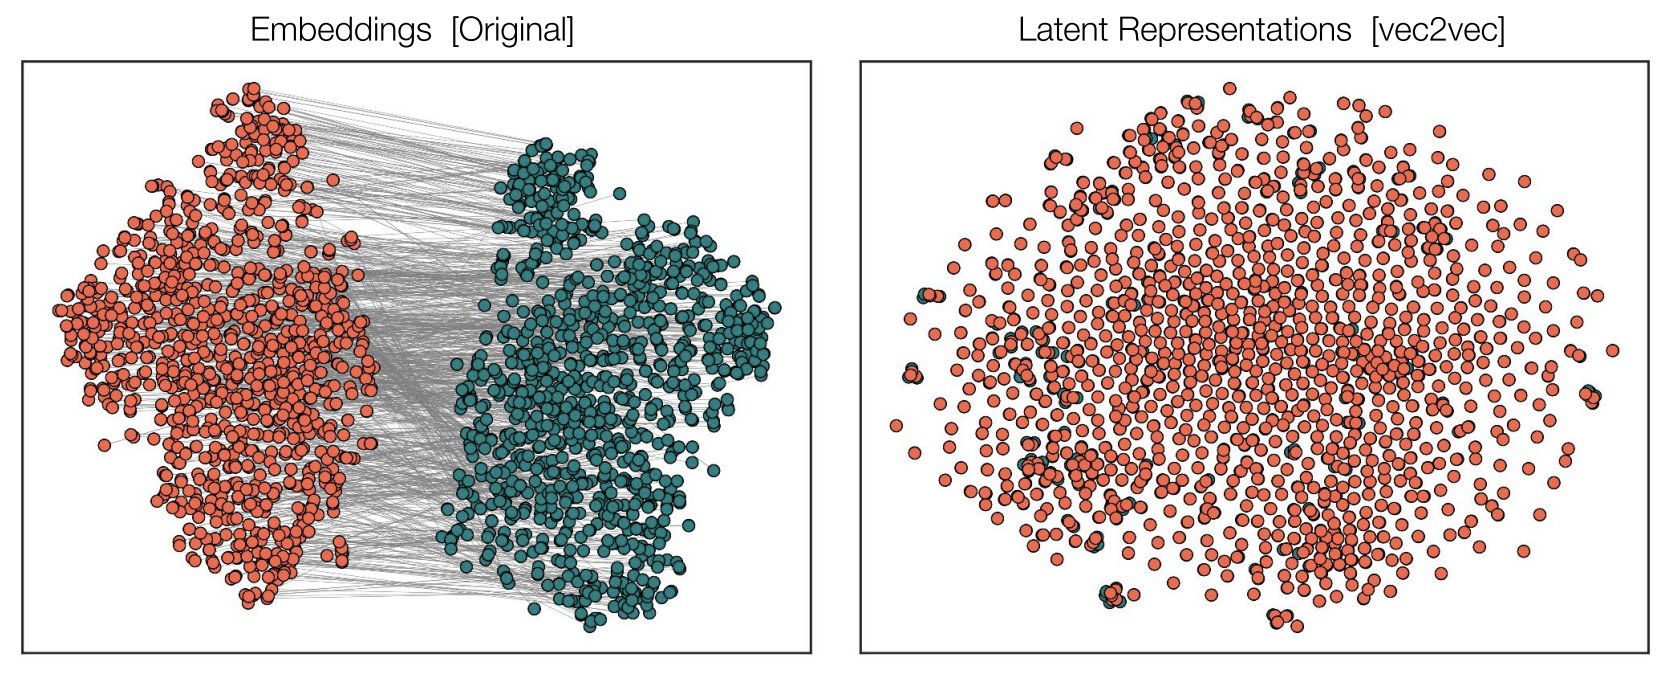
so yes, we're using a GAN. adversarial loss (to align representations) and cycle consistency loss (to make sure we align the *right* representations) and it works. here's embeddings from GTR (a T5-based model) and GTE (a BERT-based model), after training our GAN for 50 epochs:
-
All Embedding Models Learn The Same Thing
By
–
excited to finally share on arxiv what we've known for a while now:
— dr. jack morris (@jxmnop) 21 mai 2025
All Embedding Models Learn The Same Thing
embeddings from different models are SO similar that we can map between them based on structure alone. without *any* paired data
feels like magic, but it's real:🧵 https://t.co/Cwj1LytGosexcited to finally share on arxiv what we've known for a while now: All Embedding Models Learn The Same Thing embeddings from different models are SO similar that we can map between them based on structure alone. without *any* paired data feels like magic, but it's real:
-
Scale Convergence: Different AI Models Learn Identical Representations
By
–
a lot of past research (relative representations, The Platonic Representation Hypothesis, comparison metrics like CCA, SVCCA, …) has asserted that once they reach a certain scale, different models learn the same thing this has been shown using various metrics of comparison
-
Reinforcement Fine-Tuning LLMs with GRPO Short Course
By
–
New Course: Reinforcement Fine-Tuning LLMs with GRPO!
— Andrew Ng (@AndrewYNg) 21 mai 2025
Learn to use reinforcement learning to improve your LLM performance in this short course, built in collaboration with @Predibase, and taught by @TravisAddair, its Co-Founder and CTO, and @grg_arnav, its Senior Engineer and… pic.twitter.com/j5AXn3swADNew Course: Reinforcement Fine-Tuning LLMs with GRPO! Learn to use reinforcement learning to improve your LLM performance in this short course, built in collaboration with @Predibase
, and taught by @TravisAddair
, its Co-Founder and CTO, and @grg_arnav
, its Senior Engineer and -

AdaptThink: Reasoning Models Learn When to Think Efficiently
By
–
Sure, reasoning models can learn when to think, but how? A team from Tsinghua University find that NoThinking is a better choice for relatively simple tasks in terms of both performance and efficiency. Nothing surprise here. but they propose AdaptThink too! AdaptThink is a
-

Fractured Chain-of-Thought Reasoning Advances AI Reasoning
By
–
Fractured Chain-of-Thought Reasoning
Paper: https://
arxiv.org/pdf/2505.12992 -
Google Gemini 2.5 Scores 49% on USA Math Olympiad
By
–
A few months ago, the best LLM scored 5% on the USA Math Olympiad test. Models have been rapidly improving. Today, Google Gemini 2.5 scored 49%, which is better than 75% of the people who took the test (roughly the top 250 students in the USA).
-

Data AI Summit 2025 Major Event Announcement
By
–
Whatever you’re lining up early for, it’s happening at #DataAISummit 2025. Fill in the blank below