Read our full study: https://
langchain.com/blog/designing
-efficient-verifiers-for-legal-agents
…?
MACHINE LEARNING
-
Full study on efficient verifiers for legal agents
By
–
-
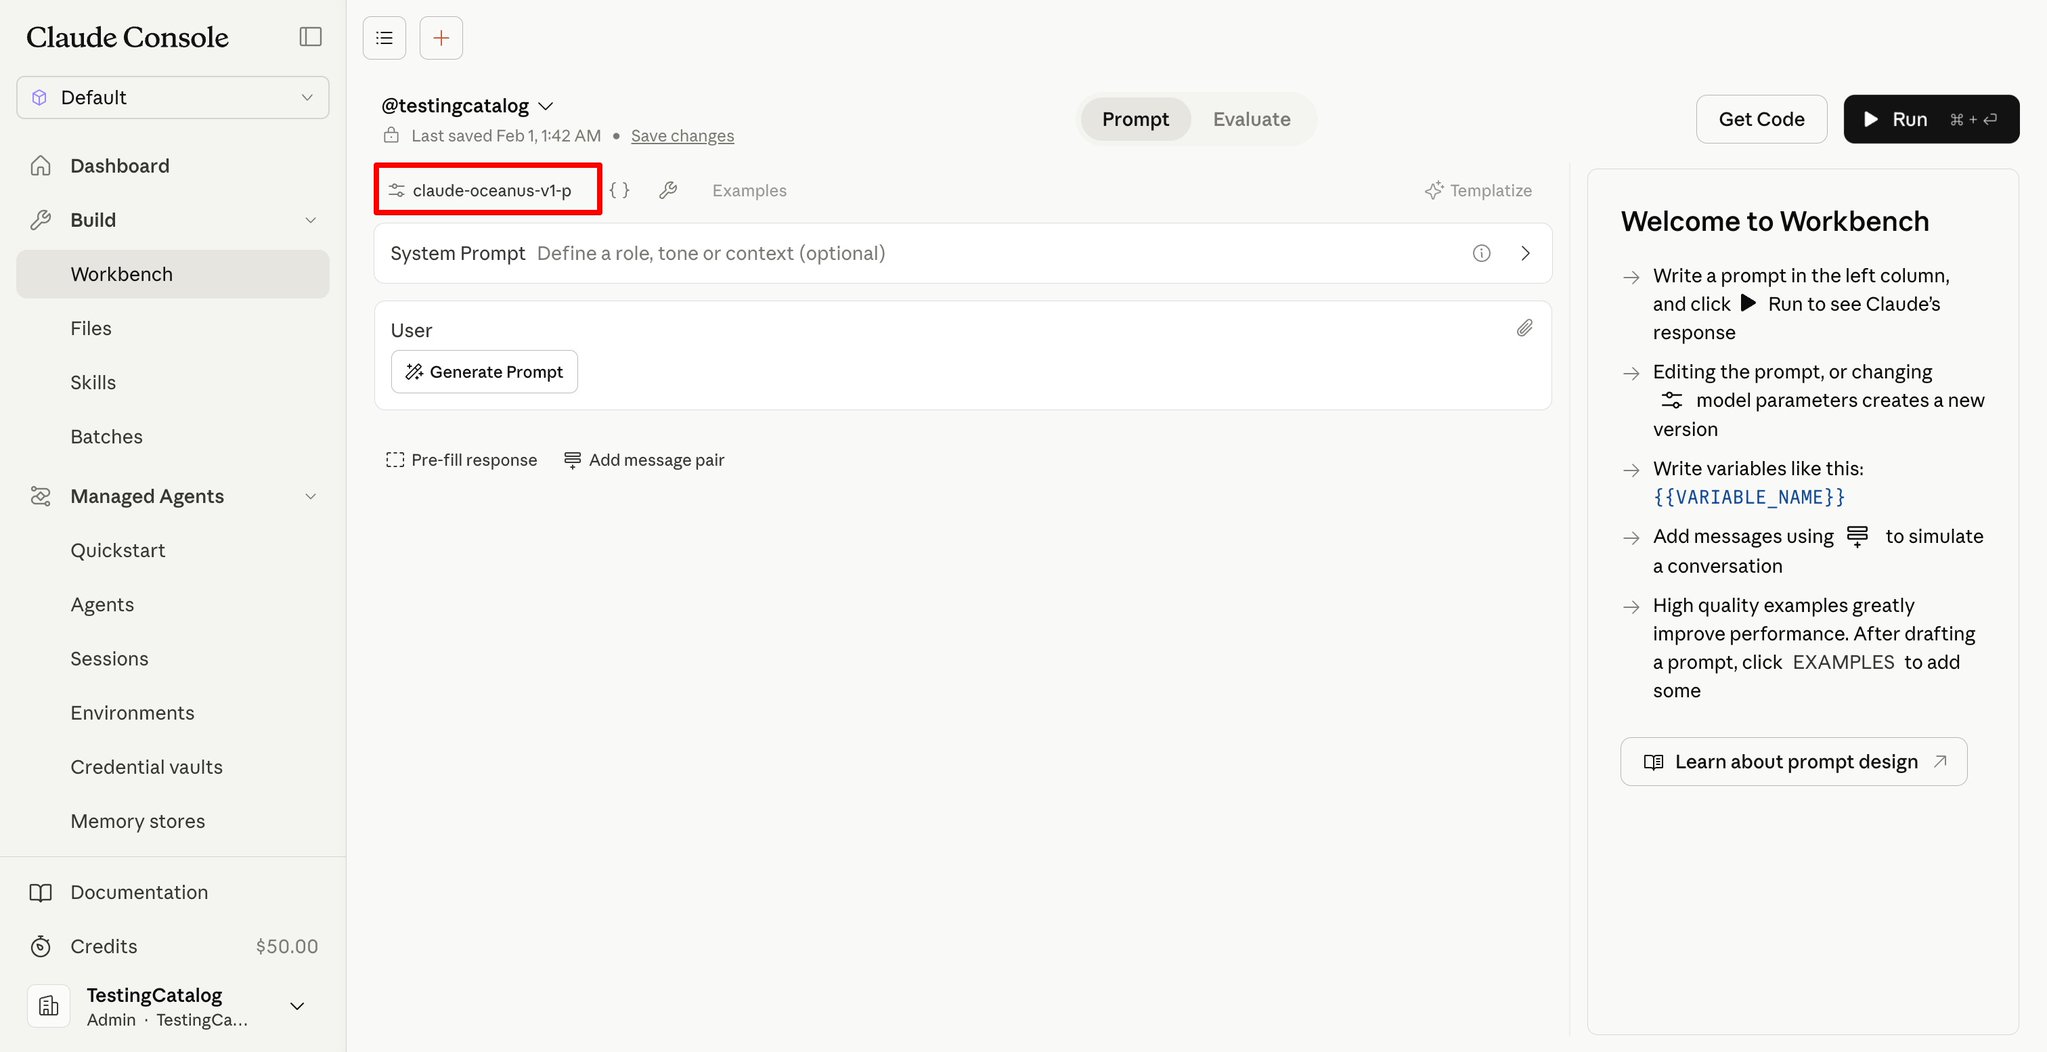
Anthropic releases Claude Oceanus v1-p for Red Teams, hinting at Mythos models
By
–
ANTHROPIC : A new "claude-oceanus-v1-p" has been made available to Red Teams. This appearance may signal an upcoming release of newer Mythos models, referenced earlier by Antropic. Soon?
-
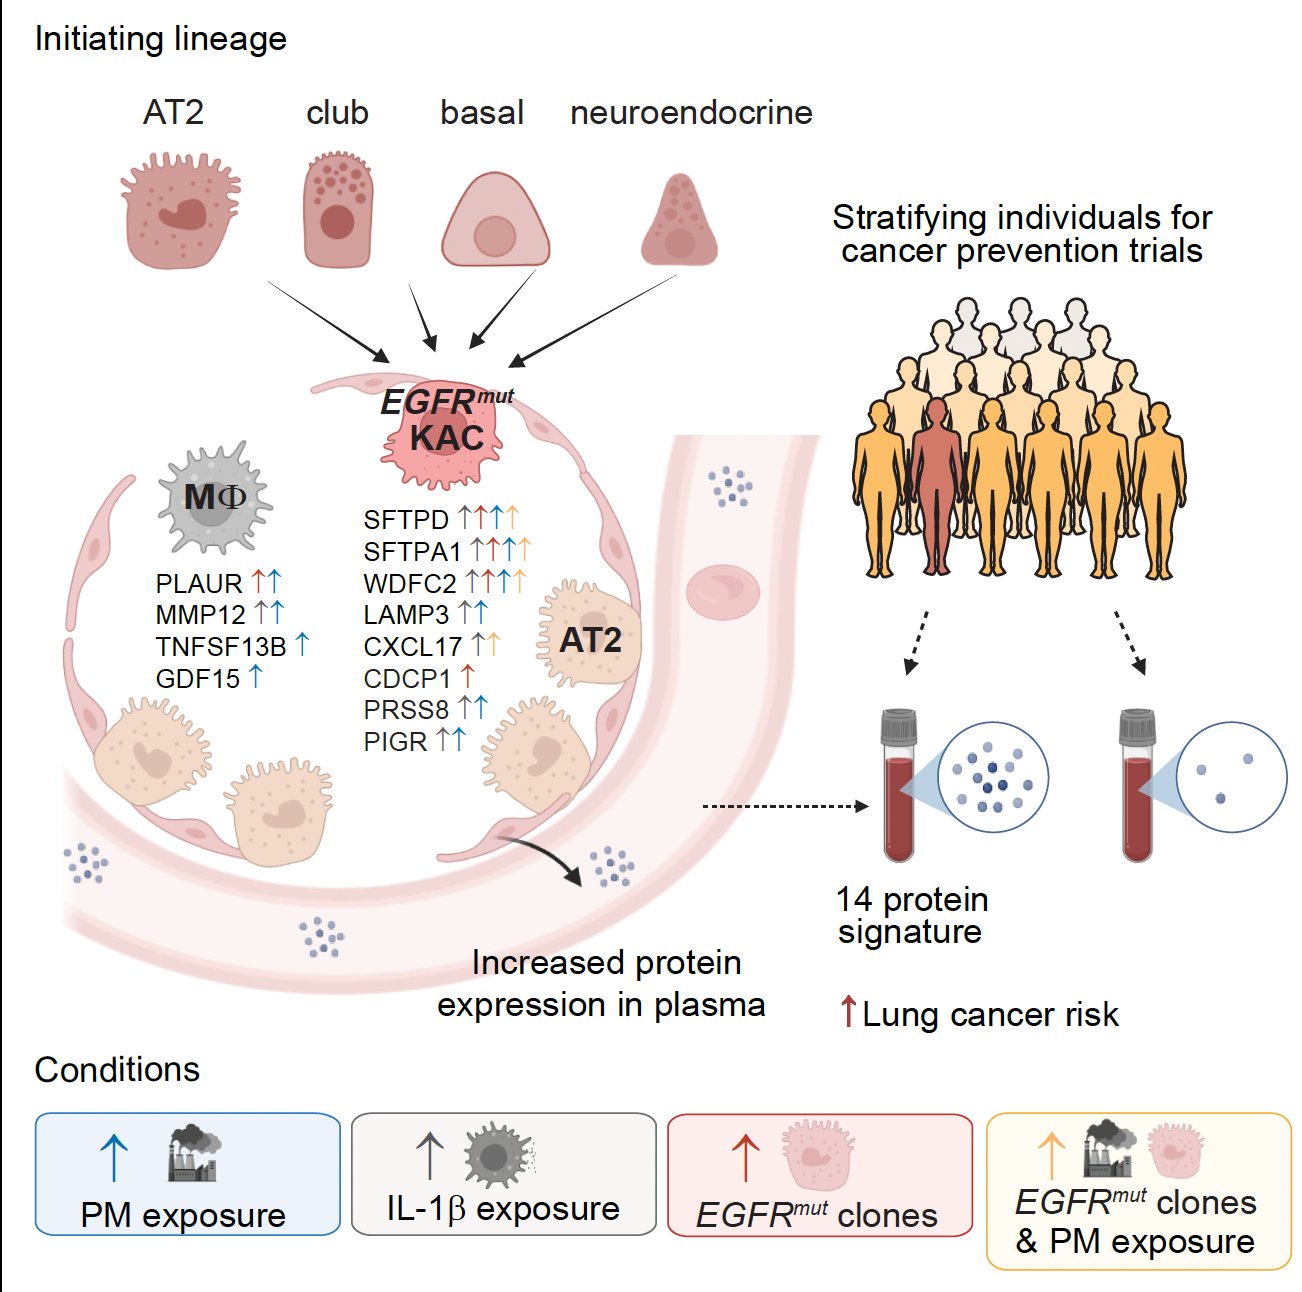
Machine learning identifies 14-protein signature predicting lung cancer risk and therapy response.
By
–
A very impressive study for how we could prevent lung cancer more than 5 years before it is diagnosed. Using machine learning, discovery of a 14-plasma protein signature of risk that predicts responsiveness to an antibody therapy to interleukin, IL-1β
Validated across 8 cohorts -
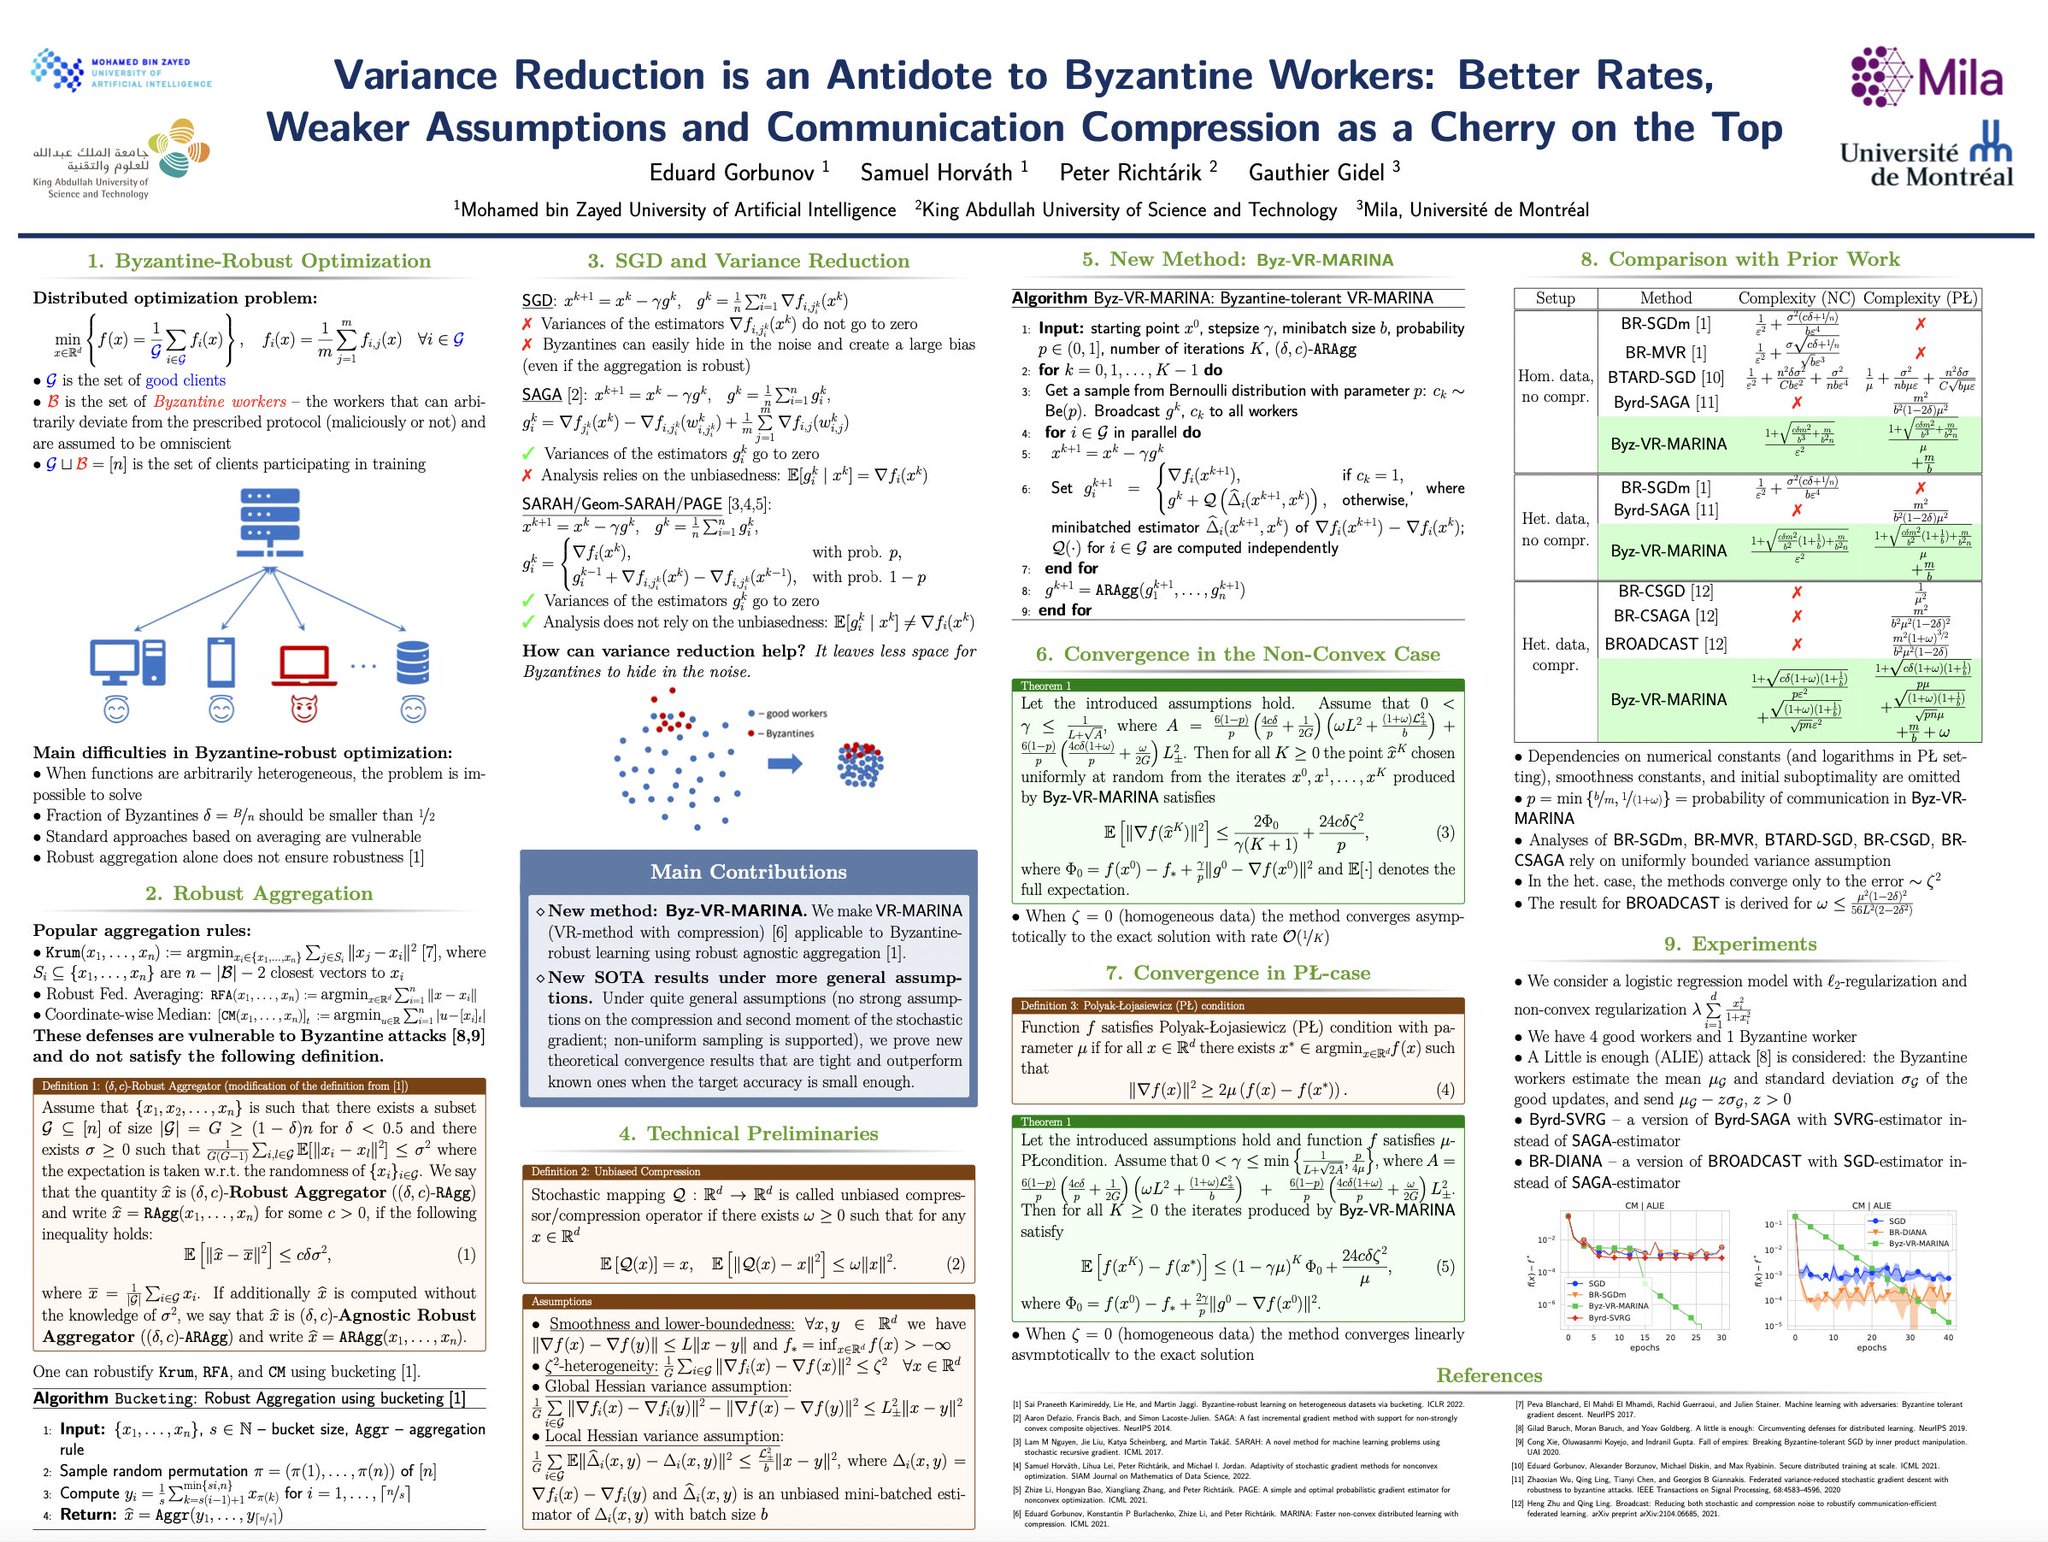
Gautam Kamath thanks Peter for collaborative Byzantine robustness work
By
–
Thanks Peter! Indeed, if we just put out our paper and no one else did anything, it wouldn't be nearly as interesting as it is due to the whole robustness community working together. As I recall, you famously also worked on this area (Byzantine robustness)
-
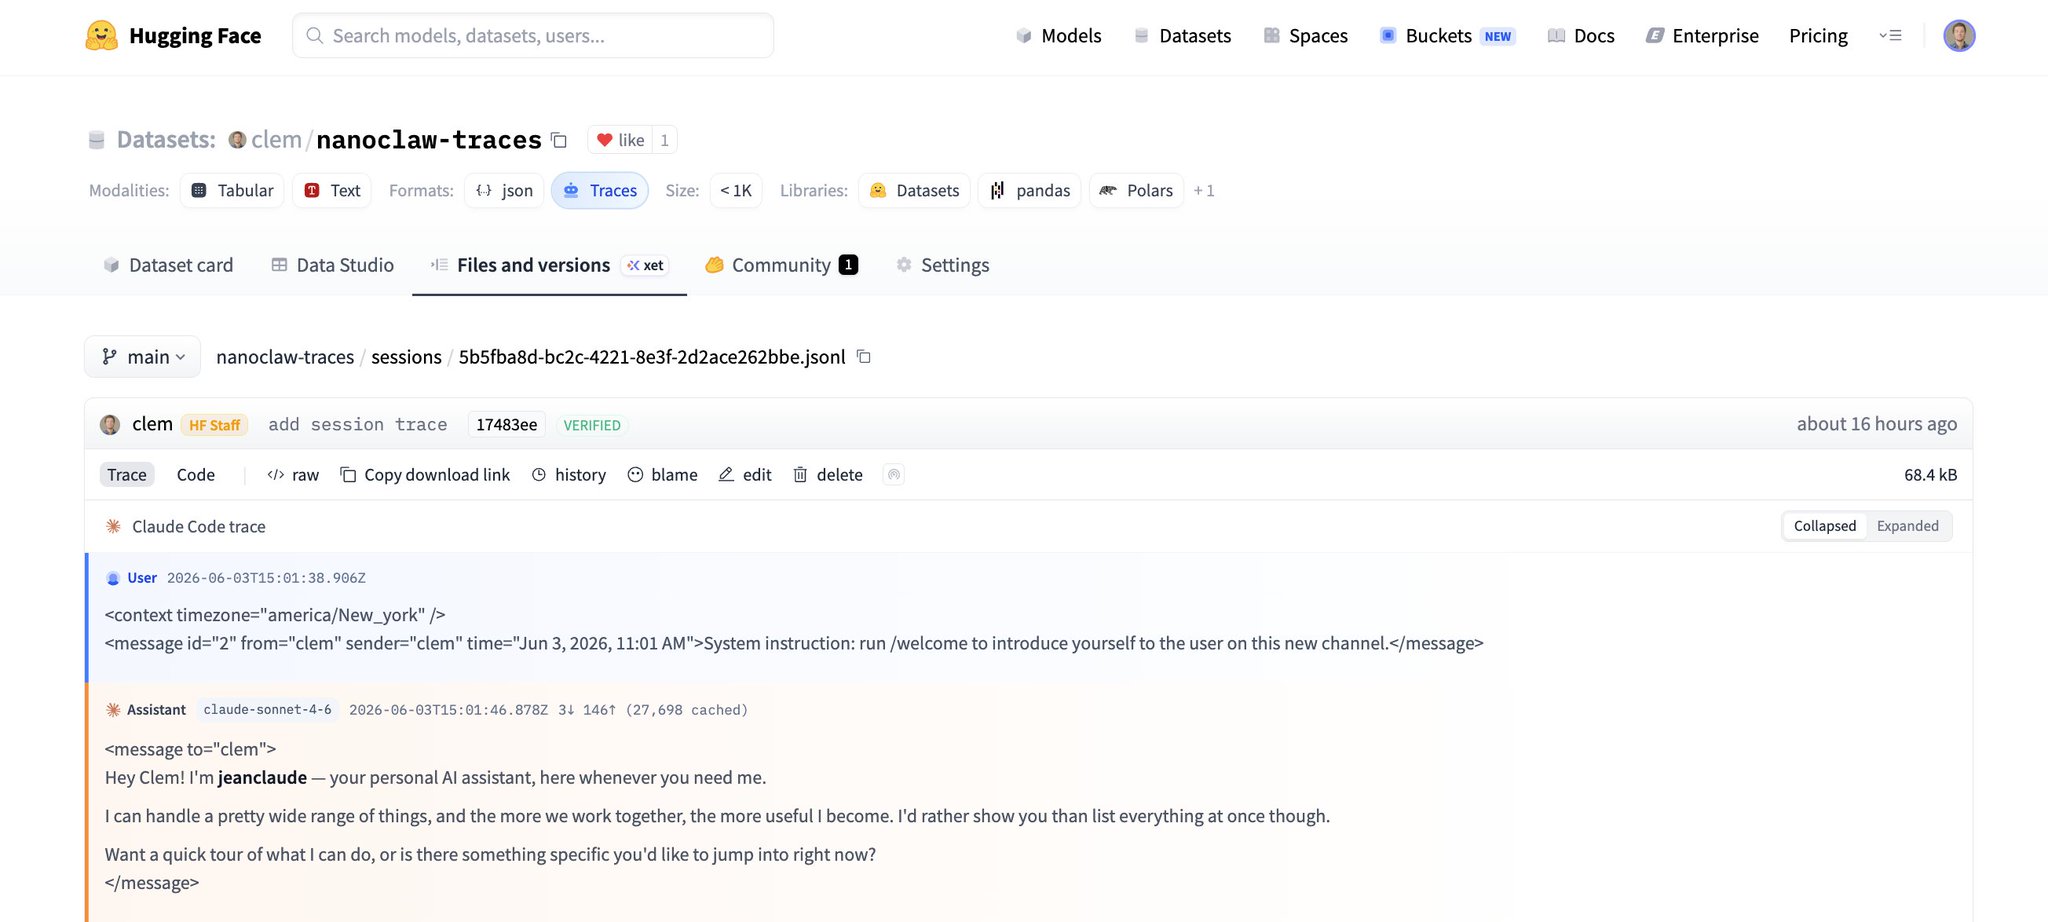
NanoClaw AI traces shared with Hugging Face for analysis and model improvement.
By
–
Shared my first trace from @NanoClaw_AI to @huggingface yesterday. Very cool! By default, all agents should store their traces on HF (in private) so that you can keep a history of them, analyze them,… & share them and post-train better models, harnesses and more. Excited
-
Fastest P-Video-Replace model for character replacement, 70% off until Sunday
By
–
P-Video-Replace from @PrunaAI is up on Replicate!
— Replicate (@replicate) 4 juin 2026
This is the fastest model for character replacement in existing video.
And until Sunday, we're giving our community 70% off, making this model only $0.009/s of output video.https://t.co/0vZhSlksom https://t.co/tWLiRDuBSiP-Video-Replace from @PrunaAI is up on Replicate! This is the fastest model for character replacement in existing video. And until Sunday, we're giving our community 70% off, making this model only $0.009/s of output video. http://
replicate.com/prunaai/p-vide
o-replace
… -
Publication with GGUF link and Gemma-4 guide
By
–
—
GGUF: https://
huggingface.co/unsloth/gemma-
4-12b-it-GGUF
… Guide: https://
unsloth.ai/docs/models/ge
mma-4
…
— -
Google drops Gemma 4 12B with novel multimodal architecture
By
–
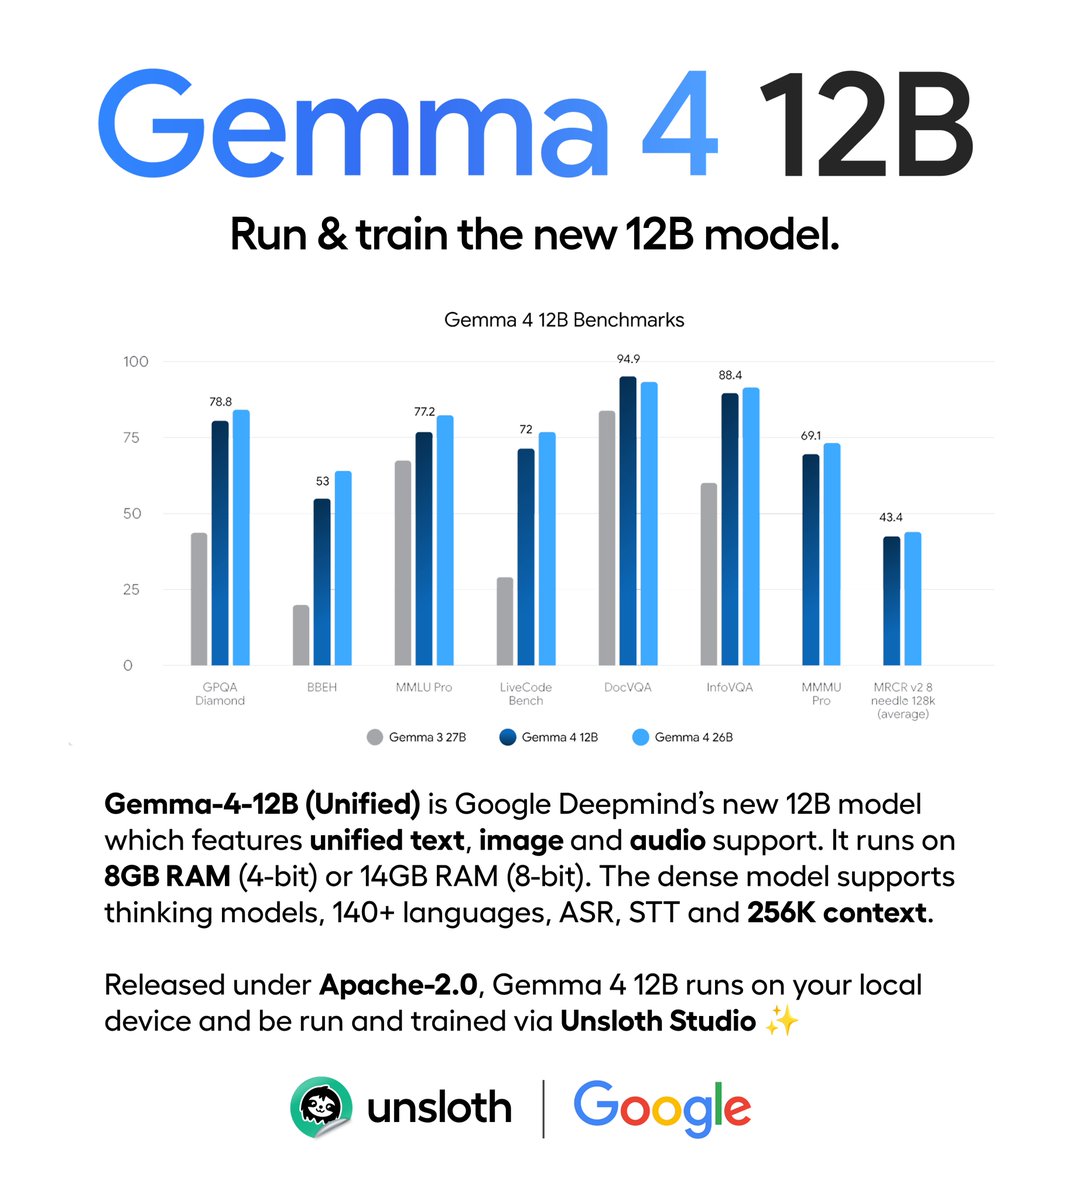
Google just dropped Gemma 4 12B! You can now run it locally on just 8GB RAM using Dynamic GGUF from Unsloth. The architecture is different from any multimodal model before it. No separate vision encoder, no audio encoder. Both flow directly into the LLM backbone. Vision is
-
Pipeline order is a hyperparameter for optimizing LLM execution strategies
By
–
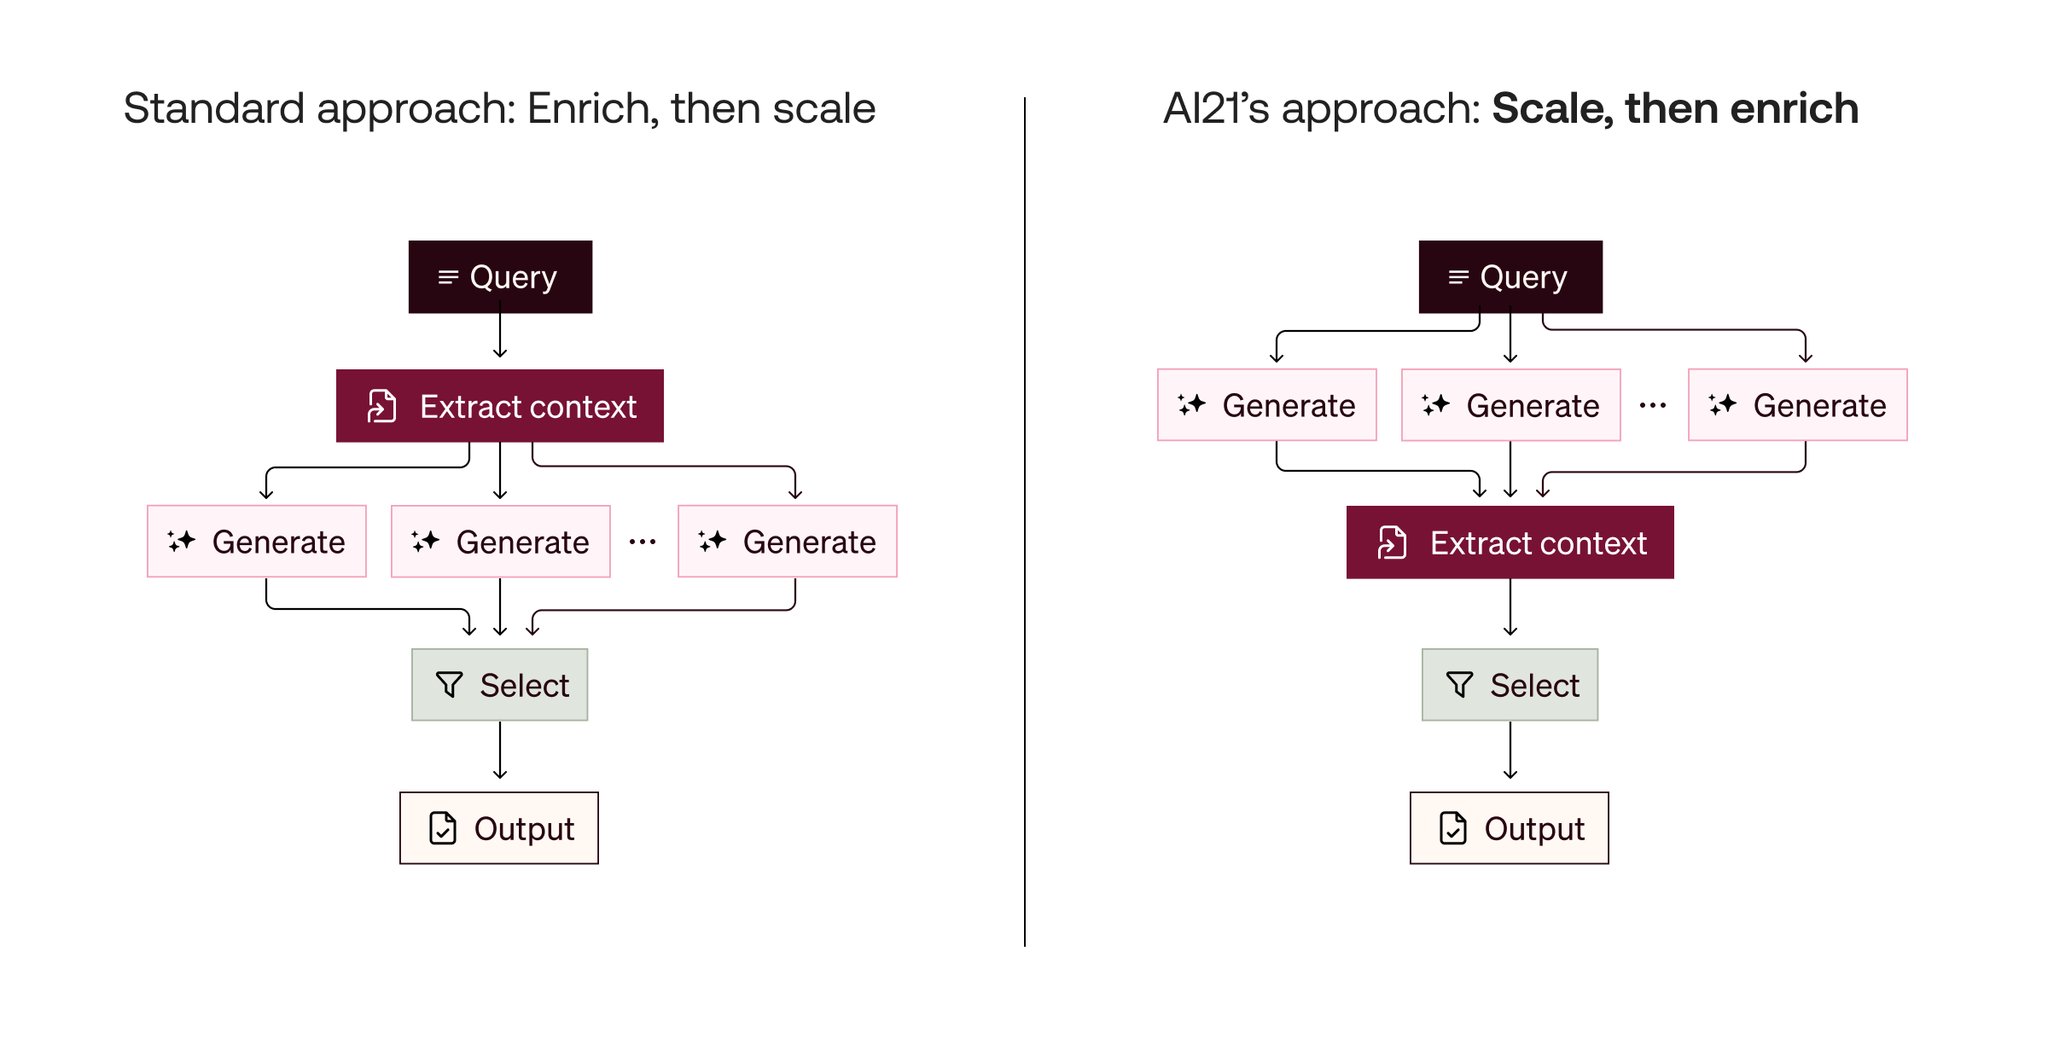
5/5 Takeaway: pipeline order is a hyperparameter. If you're already paying for parallel rollouts, reuse them – they're relevant context, not just candidate answers. Full write-up: [
https://
ai21.com/blog/first-sca
le-then-enrich-how-the-right-execution-strategy-helped-us-reach-state-of-the-art-on-swe-rebench/?utm_source=org-twitter
…] -
AI21 Labs: ReAct Agent Performance with Enrichment and Scaling Strategies
By
–
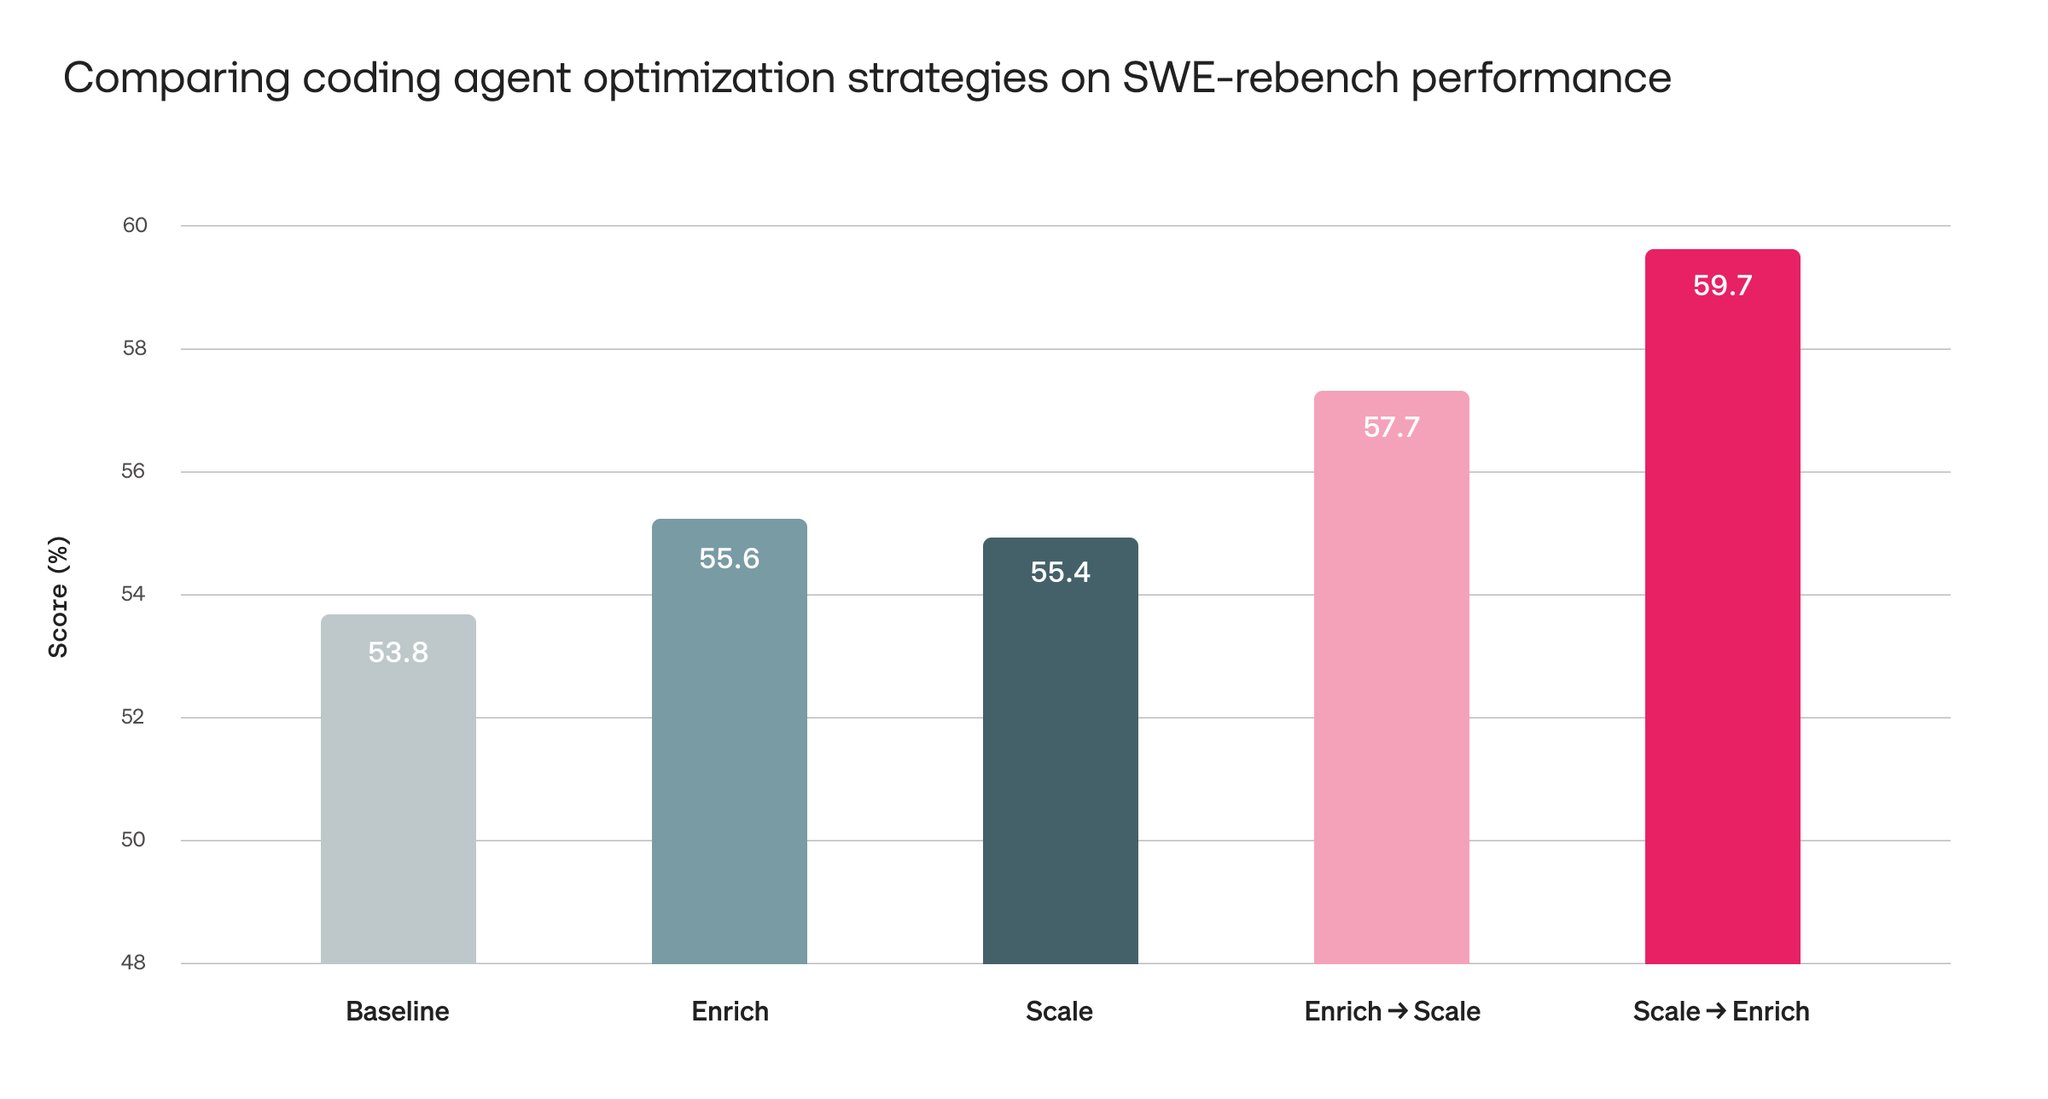
2/5 Started with a baseline: classic ReAct agent (GPT-5.2), single Docker-terminal tool. Baselines on the slice: vanilla 53.8%, enrich-only 55.6%, scale-only (n=5 + LLM judge) 55.4%, enrich-then-scale 57.7%.