
Hive: This project is supported by the @Evermind community, it's really great, highly recommended. CLI agent: Everyone is racing to develop their own memory solutions. Claude Code goes with offline "dreaming" batch processing, Hermes goes with on-site embedding, but they all
LLMS
-
Codex Goal Mode Now Available in Multiple Interfaces
By
–
3️⃣ Goal mode is now available in the Codex app, IDE extension, and CLI.
— OpenAI (@OpenAI) 22 mai 2026
Goal mode makes Codex more hands-off, letting you set a goal that it can work towards for hours or even days. pic.twitter.com/OZ18P1YxBfGoal mode is now available in the Codex app, IDE extension, and CLI. Goal mode makes Codex more hands-off, letting you set a goal that it can work towards for hours or even days.
-

OpenAI integrates ChatGPT into PowerPoint for slide creation
By
–
OPENAI : ChatGPT is now available directly in PowerPoint, allowing users to create and edit slides. PowerGPT
-

Scaling embedding learning rate by model width removes need for µP
By
–
Turns out you never really needed µP, you just needed to scale the embedding learning rate by model width I'm no nanoGPT speedrunner, but isn't it something people stumbled into by using Muon for hidden layers + Adam for the rest?
-
Skills enable deterministic execution for parallel model usage
By
–
Skills can allow you to have deterministic execution patterns, so I have a lot of minimal harnesses for repeated tasks, that way I can control outcome no matter what model I use This is extremely helpful if you have multiple endpoints / models that you want to run in parallel
-

Using GPT 5.5 for Equidistant Point Placement
By
–
I just told GPT 5.5 to come up with a new equidistant point placement on the plane based on the recent OpenAI research paper. Should we be worried?
-
Complete guide to understanding LLMs from first principles free online
By
–
INCREDIBLE The MOST COMPLETE GUIDE for understanding LLMs from first principles is now available online to read for free Covers the model mechanics – Tokens / tokenizers
– Transformers
– Attention
– KV cache
– Prefill vs decode
– Decoding controls
– Model packages
– Chat -
HRM Outperforms Transformers 7x Its Size
By
–
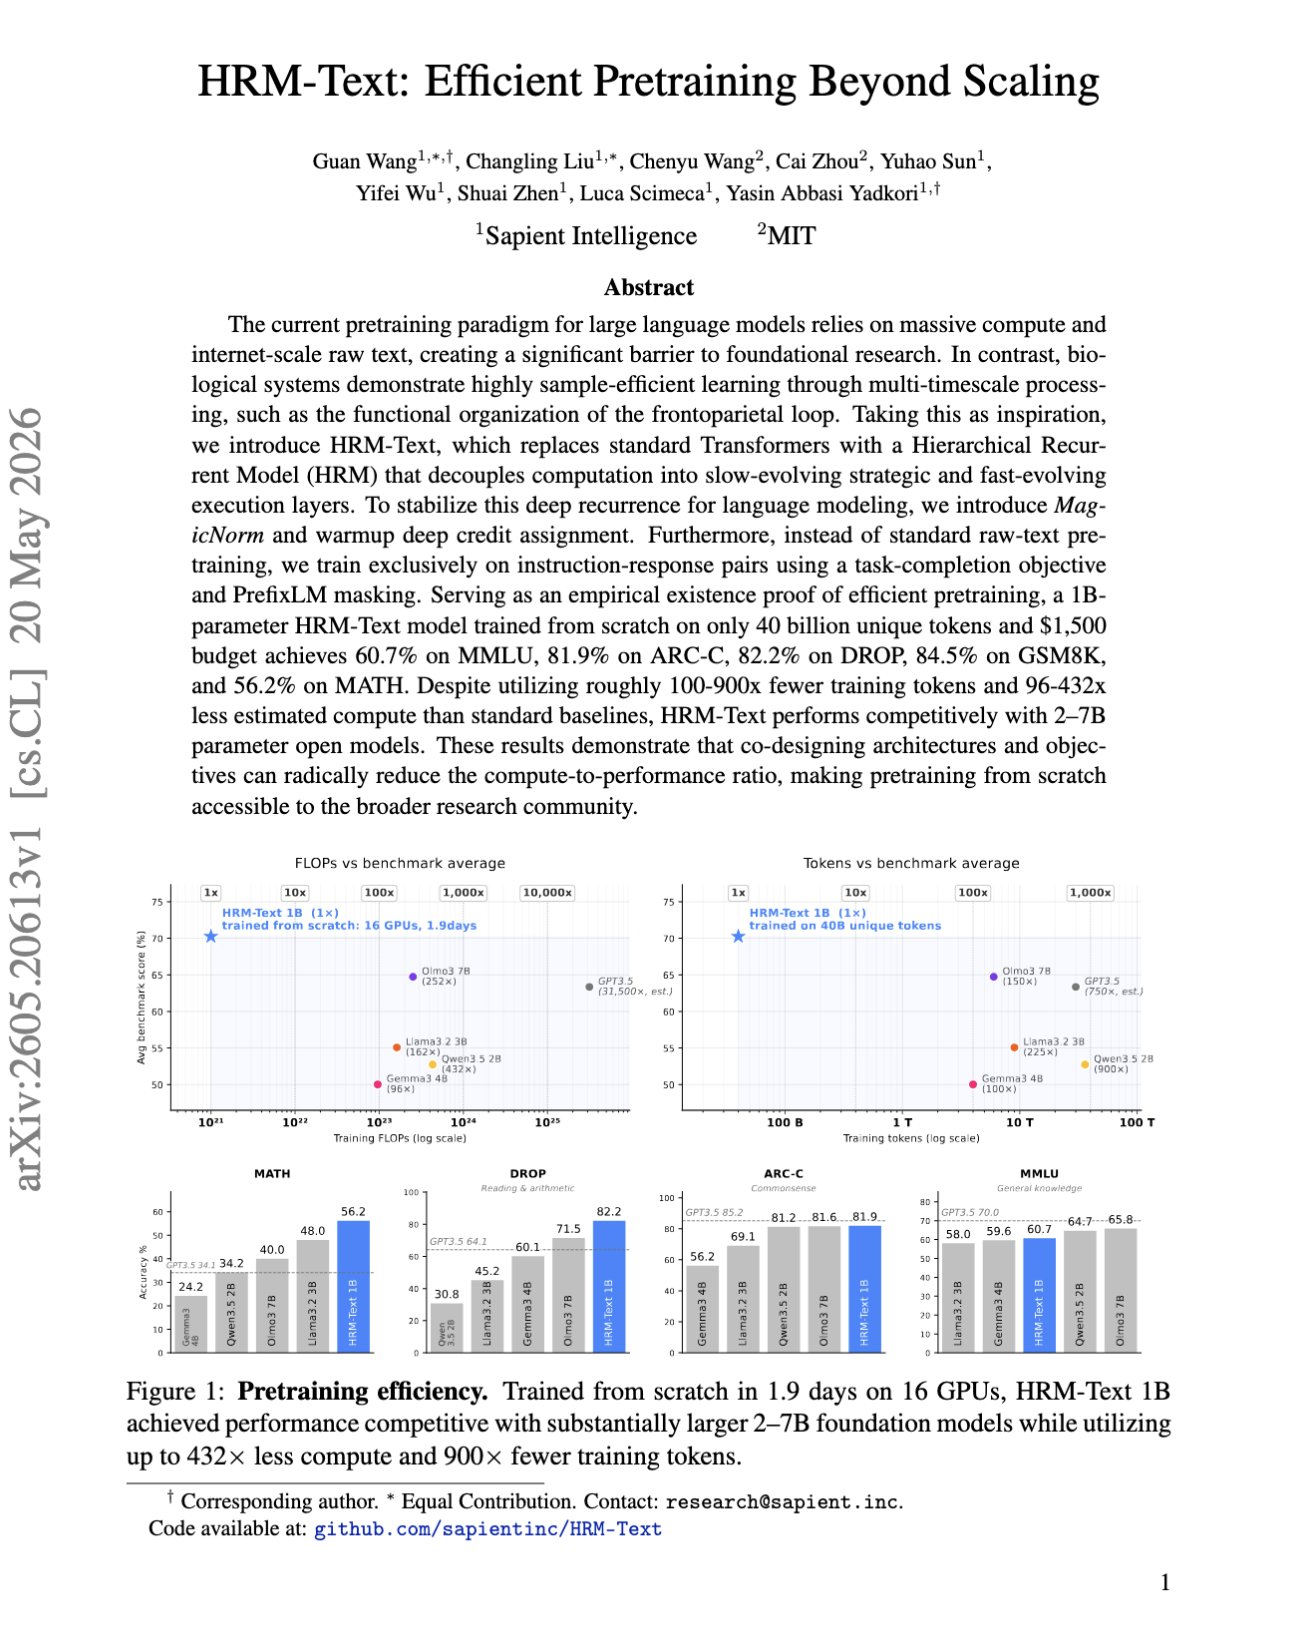
HRM beats Transformers seven times its size in language modeling!? "HRM-Text: Efficient Pretraining Beyond Scaling" This paper introduces the Hierarchical Recurrent Model (HRM), which incorporates slow planning layers and fast execution layers to enhance planning and recurrence. The model was trained directly on…
-
LLMs: symbolic AI triumph with more noise
By
–
Looked at this way, LLMs are the triumph of symbolic AI, just with more noise.
-
Testing Gemma 4 and Qwen with SQL generation quality comparison
By
–
I've tried it with Gemma 4 and Qwen 3.5/3.6 so far, works well with the >4B models, sometimes works with 4B but they're more likely to mess up the SQL