Except a shader like this is a very good measure of model capability because of the technical difficulty of building this sort of code. It translates to other coding as well. Feel free to see my many other tweets and substack posts (& book) about AI applications in businesses.
LLMS
-

Client Spent $500M in a Month After Missing Claude Usage Limits
By
–
NEW: AI consultant reveals a client accidentally spent $500,000,000.00 in a single month after failing to set employee limits on Claude usage.
-

AI Wins Gold at Math Olympiad via Simple Unified Scaling
By
–
Cool! AI can win gold at the International Math Olympiad via Simple and Unified Scaling! Researchers from Shanghai AI Lab, CUHK, Tsinghua and PKU introduce SU-01. Their simple recipe: first train on proof-search and self-checking behaviors, then scale via two-stage
-
Half of reactions would be LLM-related psychosis
By
–
I think that half of them vaguely correspond to a psychosis linked to LLMs!
-

AI Reasoning Laziness and Prompt Injection Solutions
By
–
Anthropic semble avoir trouvé une solution aux problèmes où l’IA vous donne une réponse incorrect car elle a la flemme et préfère arrêter le raisonnement. Moi je dis ils doivent faire du prompt injections à chaque thinking avec des menaces .
-

Anthropic Acceleration: Model Release Cycle Shortening Trend
By
–

Anthropic released the next version sooner than I thought – the trend is accelerating – from 50-70 days before, down to 42 days since Opus 4.7
-
Opus 4.8 research workflow and GPT-5.5 feedback
By
–
Opus 4.8 formulated the hypotheses in advance, conducting data cleaning, did research on references, conducted analyses, did robustness checks, and put out the whole paper in LaTEX style. GPT-5.5 found one issue with a hallucinated result, and had other constructive feedback.
-
Grok Build 0.2.7 Released with New Features and Image Understanding Improvements
By
–
Grok Build 0.2.7 is now out, with /usage, /login, shared terminals across subagents, and improved image understanding See all updates at https://
x.ai/build/changelog -
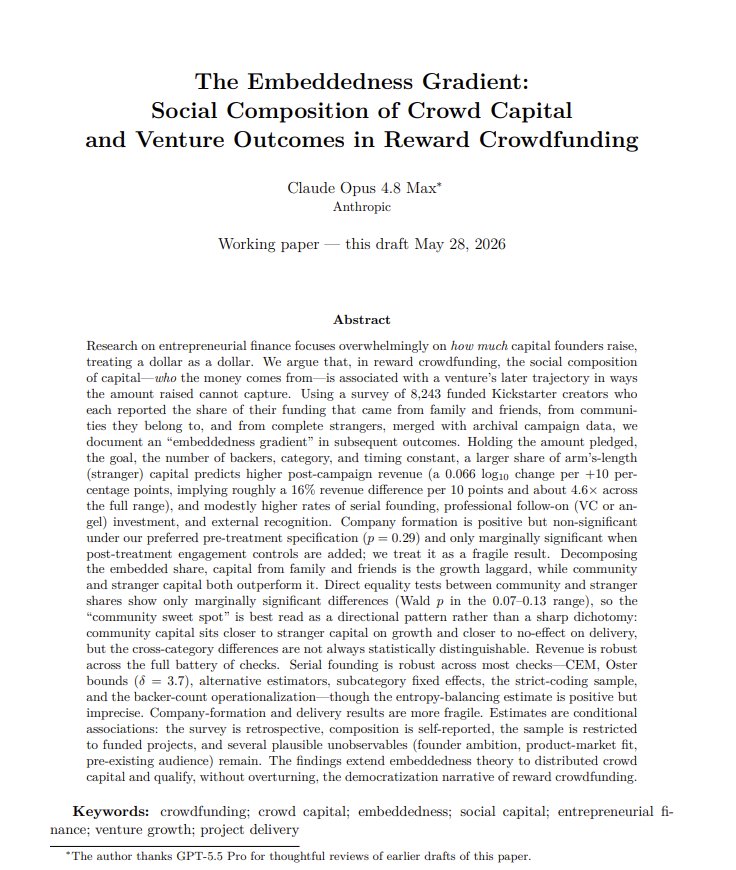
AI agents wrote and reviewed an academic paper
By
–
I had Opus 4.8 in Claude Code write a sophisticated, if minor, academic paper from a archive of hundreds of de-identified research files from years ago I had to use GPT-5.5 Pro as a reviewer, it spotted one major error & some minor points. Opus corrected https://
embeddedness-gradient.netlify.app -
Most Powerful AI Models Growing Stronger Every 1-2 Months
By
–
What a trip that every 1-2 months the most powerful models on the planet, used by everyone, get even more powerful.