I couldn't have built https://
alignednews.com/ai without vibe coding. It might be gone in 24 months. Change is constant. But vibe coding is real and is just at the beginning.
LLMS
-
Vibe coding enables AI site, but change is inevitable
By
–
-
AI as personal tutor: learn faster with quizzes, flashcards, and role play
By
–
Stop studying alone, AI can be your personal tutor on demand.
— Bernard Marr (@BernardMarr) 3 juin 2026
In this video, I share practical ways to use AI to learn anything faster, turn your notes into quizzes and flashcards, ask it to quiz you like an examiner, get explanations at different levels, role play real… pic.twitter.com/1OrDlrJcYgStop studying alone, AI can be your personal tutor on demand. In this video, I share practical ways to use AI to learn anything faster, turn your notes into quizzes and flashcards, ask it to quiz you like an examiner, get explanations at different levels, role play real
-
Capabilities learned not inherited: building from ground up
By
–
The phrase “capabilities should be learned, not inherited” is doing a lot of work here. It draws a clear line between imitating intelligence through distillation and building the internal machinery to generate, evaluate, and improve capabilities from the ground up. That
-
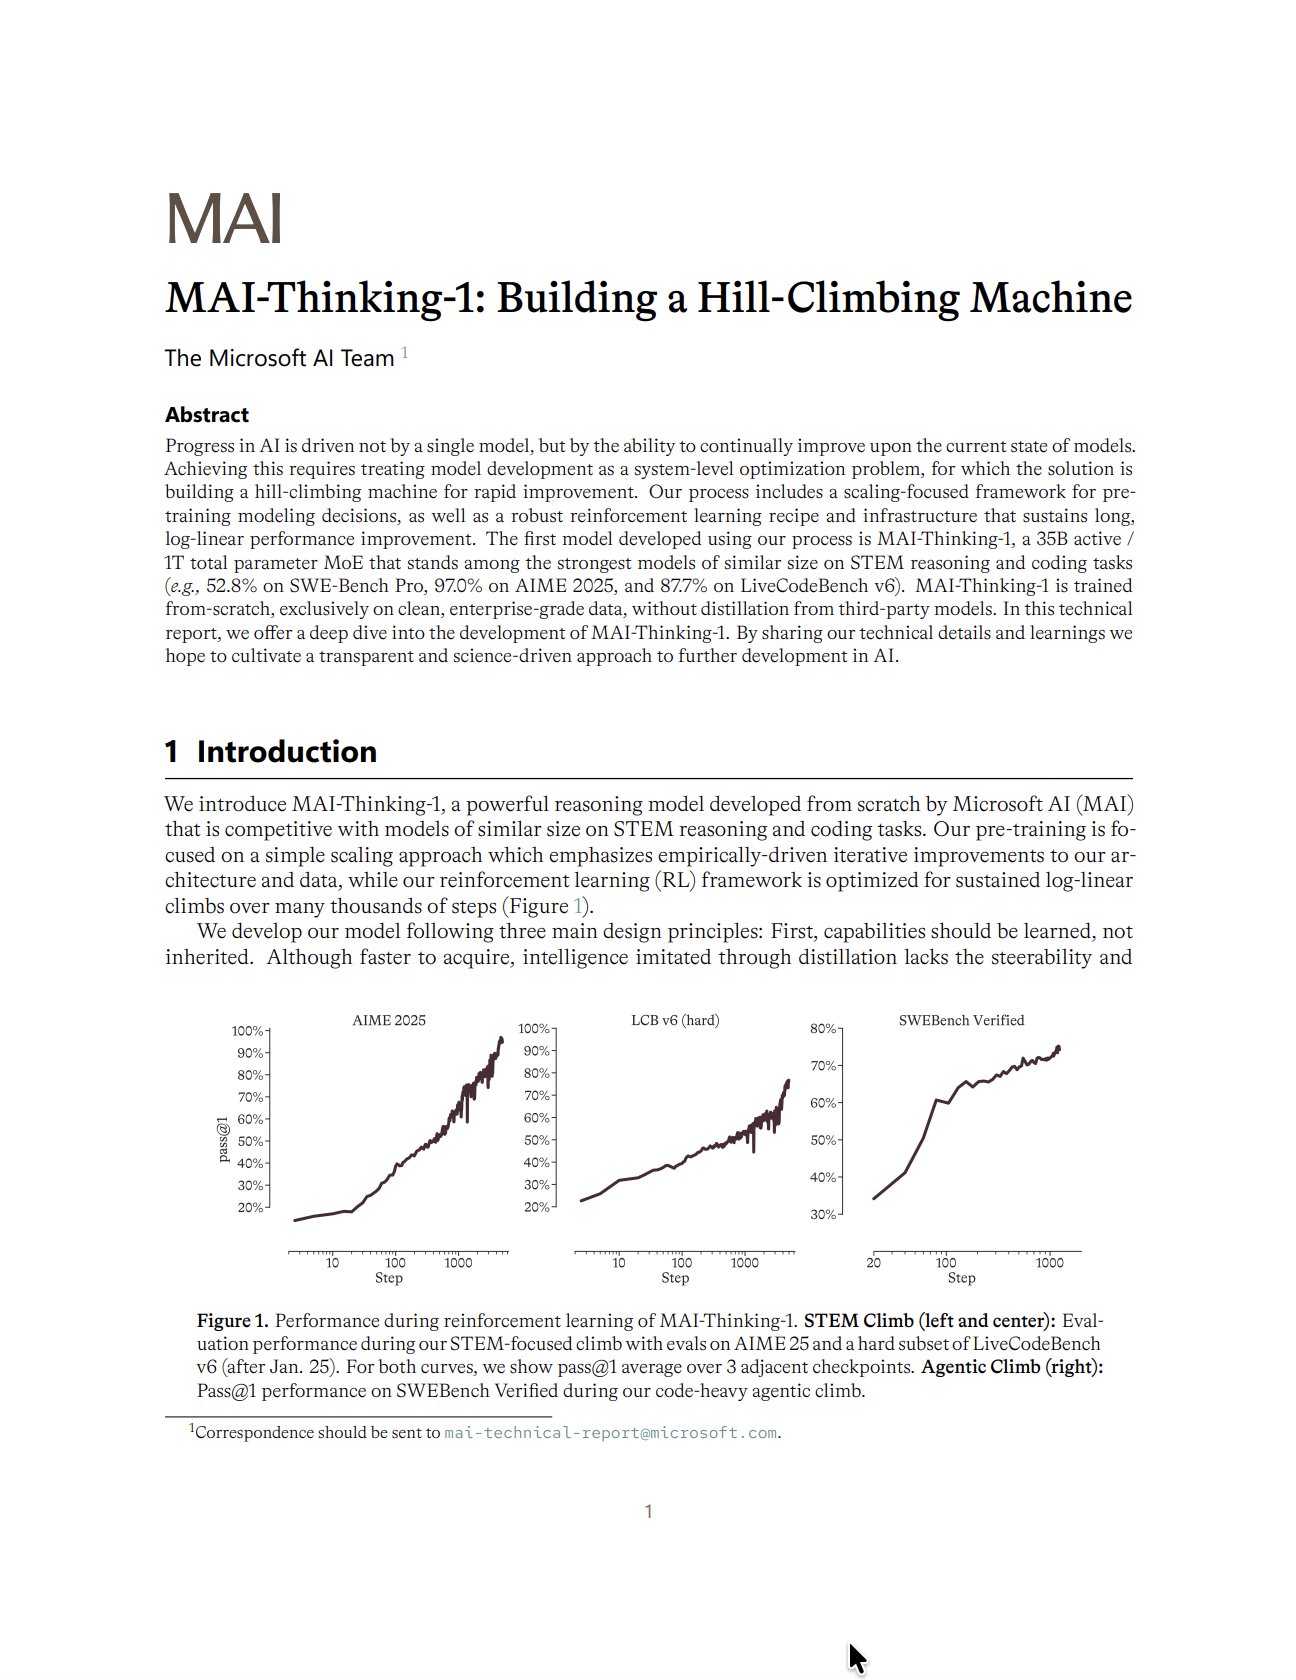
Microsoft AI’s MAI-Thinking-1: Progress is a model-improving machine
By
–
AI progress is not a model. It is a machine that keeps improving models. That is the core idea behind Microsoft AI’s new technical report: MAI-Thinking-1: Building a Hill-Climbing Machine This is not just a model release. It is a blueprint for turning frontier model
-
Learned vs. Inherited Capabilities: Distillation vs. Ground-Up Intelligence
By
–
The phrase “capabilities should be learned, not inherited” is doing a lot of work here. It draws a clear line between imitating intelligence through distillation and building the internal machinery to generate, evaluate, and improve capabilities from the ground up. That
-
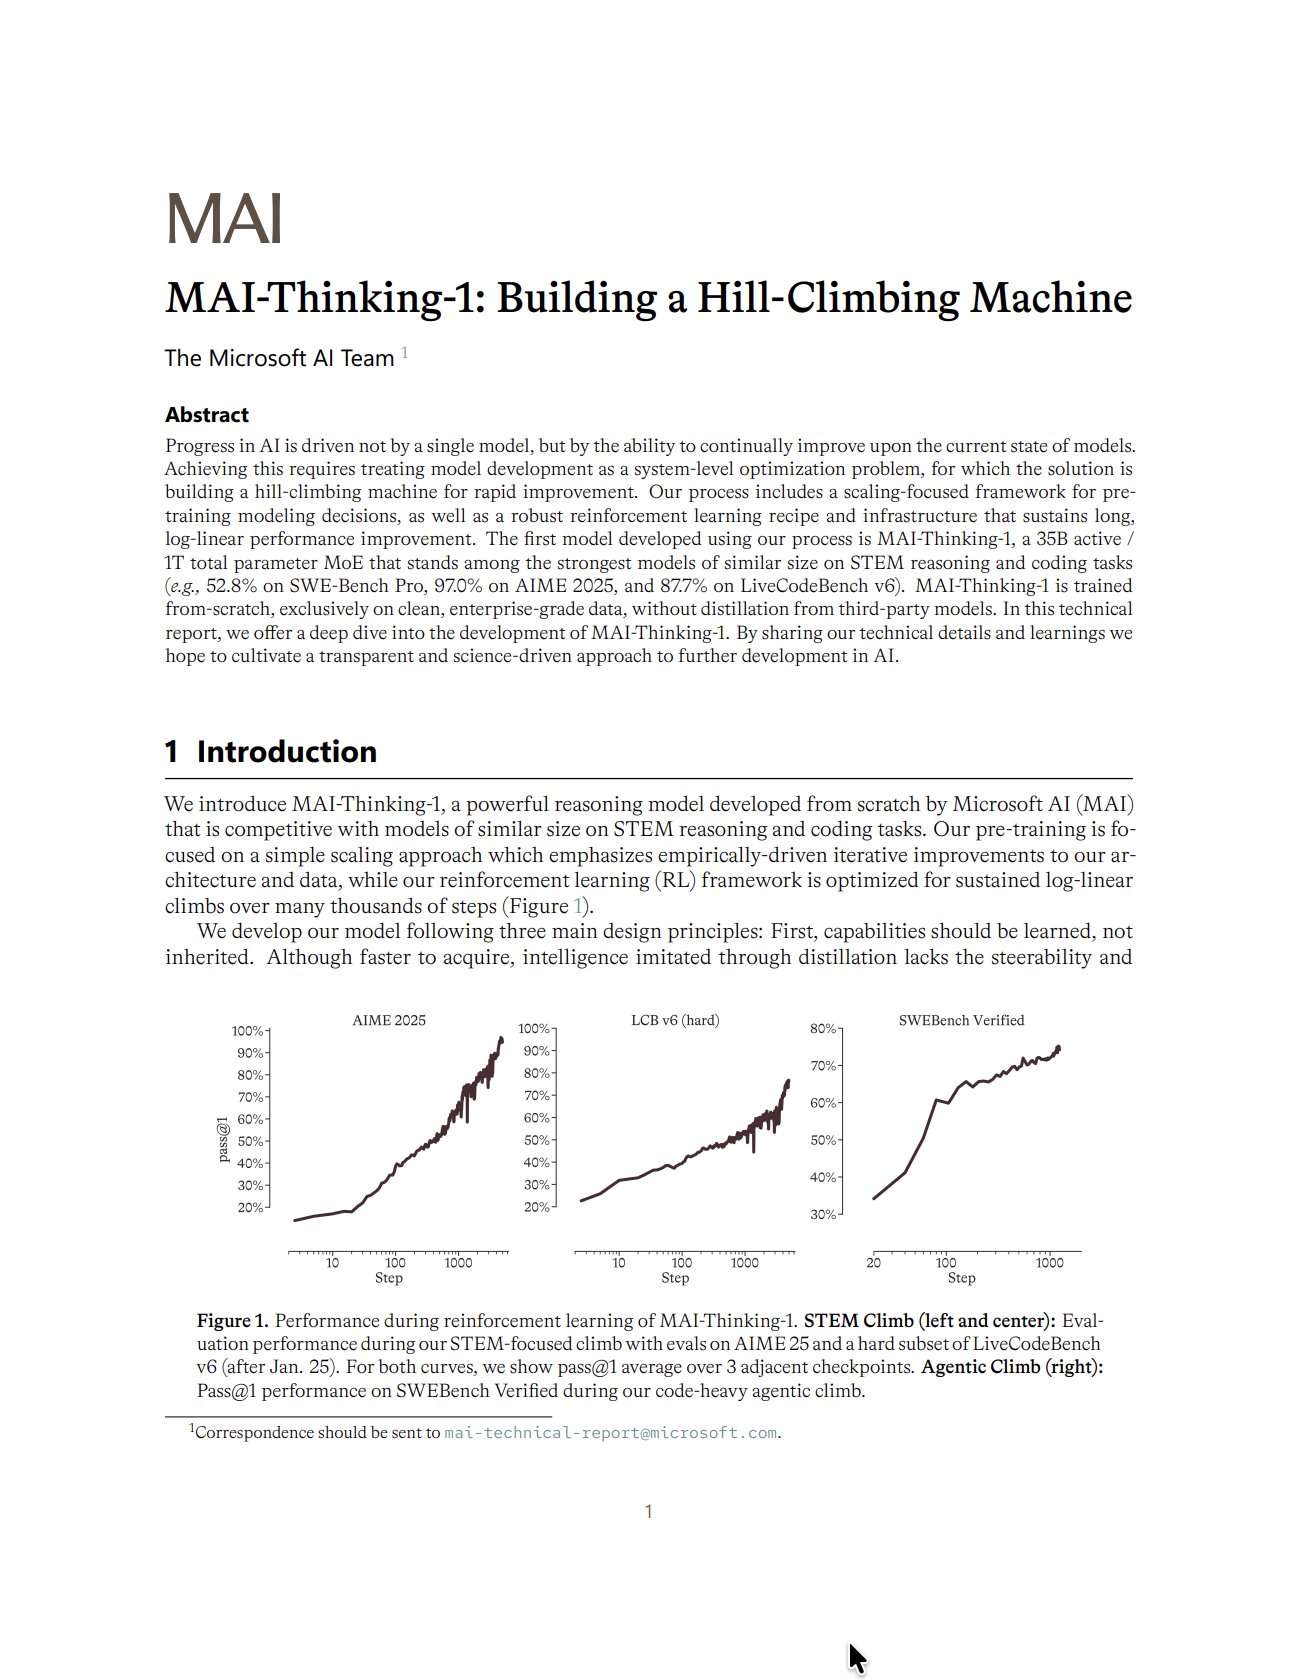
Microsoft AI’s MAI-Thinking-1: A Hill-Climbing Machine for Frontier Models
By
–
AI progress is not a model. It is a machine that keeps improving models. That is the core idea behind Microsoft AI’s new technical report: MAI-Thinking-1: Building a Hill-Climbing Machine This is not just a model release. It is a blueprint for turning frontier model
-
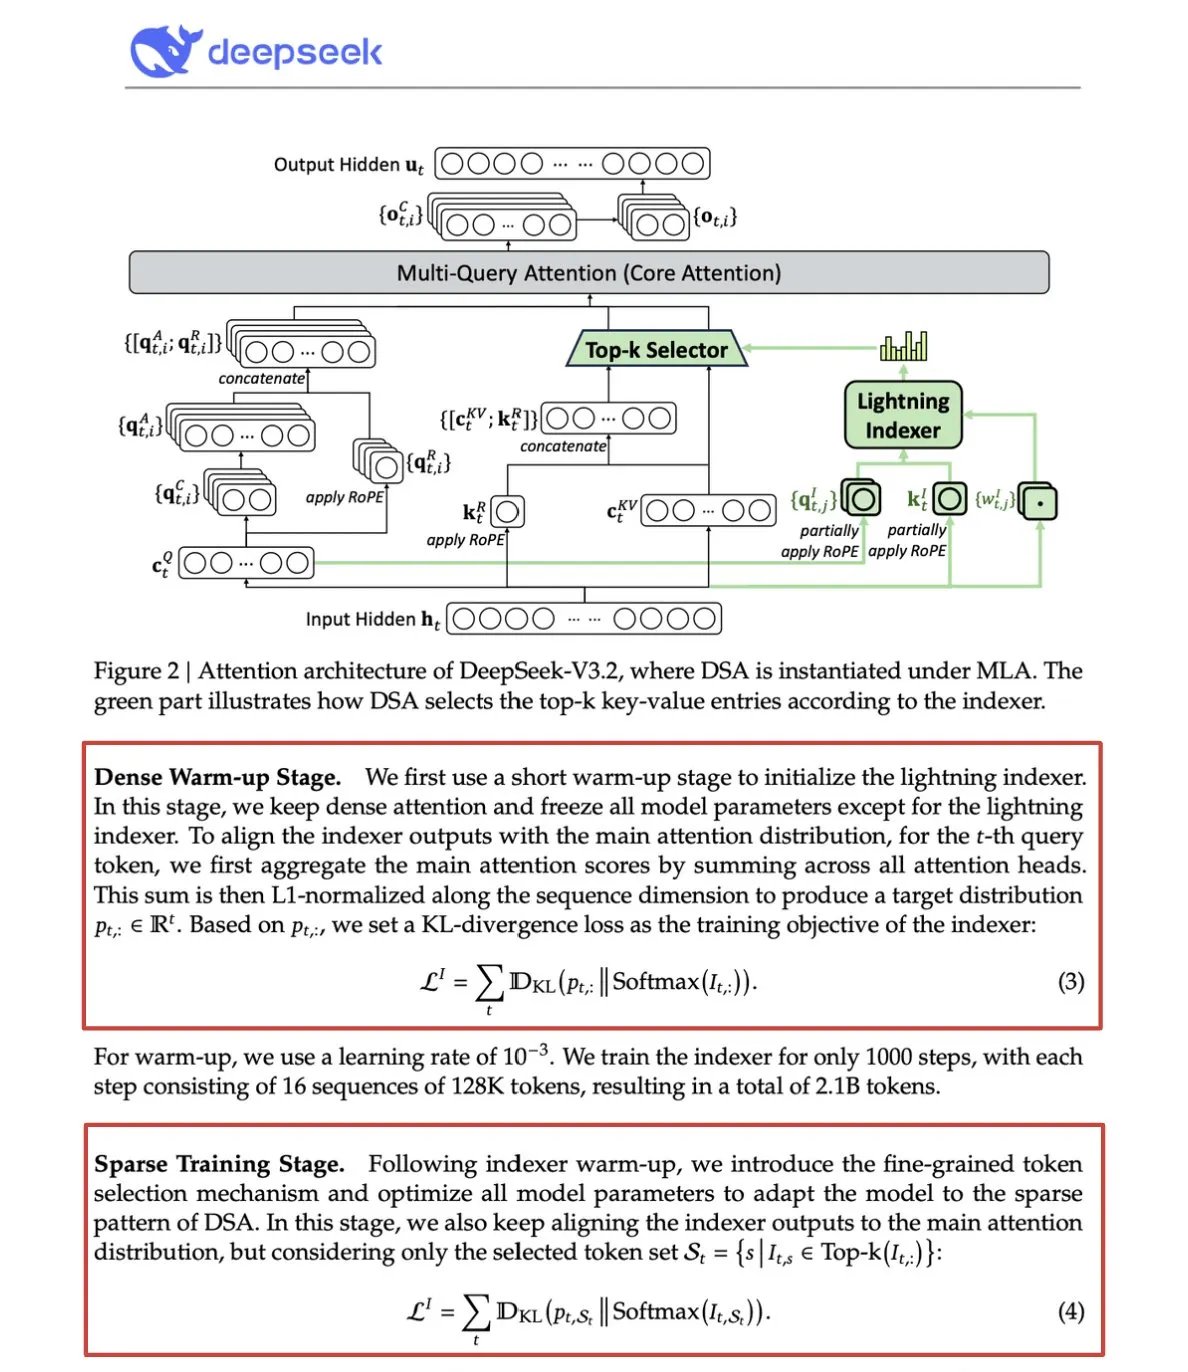
DeepSeek Sparse Attention reduces complexity from O(L²) to O(Lk)
By
–
3) DeepSeek Sparse Attention (DSA) DeepSeek’s recently released V3.2 model introduced DeepSeek Sparse Attention (DSA), which brought complexity down from O(L²) to O(Lk), where k is fixed. How it works: A lightweight Lightning Indexer scores which tokens actually matter for
-
Local vs global attention in reading explained
By
–
Here's an intuitive explanation taken from the paper: Picture yourself reading a book. For every sentence you read, do you need to be fully aware of the entire plot to understand most of it (full global attention)? Or is awareness of the current chapter enough (local
-
Why fine-tuning alone isn’t enough for 128K context
By
–
You're in a Research Scientist interview at OpenAI. The interviewer asks: "How would you expand the context length of an LLM from 2K to 128K tokens?" You: "I will fine-tune the model on longer docs with 128K context." Interview over. Here's what you missed:
-

SambaNova unveils disaggregated inference demo with 2x speedup
By
–
The first disaggregated inference demo for AI agents is now live. At #COMPUTEX2026, SambaNova demonstrated premium inference running in production at VC2 — using NVIDIA B200 GPUs for prefill and SambaNova RDUs for decode. The result: 2x faster inference than B200-only