
NEW: Spiral 4.0—a writing partner for you and your agent by @every -> Stylometry: we built a new Style Engine based on the principles of stylometry to extract you and your brand's voice and produce great writing every time, based on examples of your past work -> MCP and CLI:
LLMS
-
Memanto: free and open source infinite memory for Claude, Codex, Cursor
By
–
Ahora puedes darle memoria infinita a Claude, Codex y Cursor.
— Nico (@nicos_ai) 4 juin 2026
100% gratis y open source.
Memanto ya es tendencia con +5.000 estrellas en GitHub.
La herramienta:
→ guarda el contexto de tus sesiones de trabajo
→ lo comprime y organiza con IA
→ recupera lo relevante en menos… pic.twitter.com/r9pnRvDMJDNow, you can give infinite memory to Claude, Codex, and Cursor. 100% free and open source. Memanto is already trending with +5,000 stars on GitHub. The tool: → saves the context of your work sessions → compresses and organizes it with AI →
-
LangSmith Engine automates agent team improvement loop from traces
By
–
Most agent team runs the same manual improvement loop:
— LangChain (@LangChain) 4 juin 2026
Trace → find failure patterns → fix prompts or code → create evals → test → ship → repeat
LangSmith Engine helps turn production traces into named issues, root-cause analysis, proposed fixes, and stronger eval… pic.twitter.com/TozrvKwfTHMost agent team runs the same manual improvement loop: Trace → find failure patterns → fix prompts or code → create evals → test → ship → repeat LangSmith Engine helps turn production traces into named issues, root-cause analysis, proposed fixes, and stronger eval
-

NVIDIA Nemotron 3 Ultra: 5x faster inference, 30% lower costs
By
–
NVIDIA : Nemotron 3 Ultra has been released on Huggingface with 5x faster inference and 30% lower costs in comparison to other open models. > Nemotron-3-Ultra-550B-A55B-NVFP4 is a frontier-scale large language model (LLM) trained by NVIDIA, designed to deliver strong agentic,
-
Cursor AI: Interactive report for agent context usage in canvas
By
–
Cursor can now show your agent's context usage as an interactive report in a canvas.
— Cursor (@cursor_ai) 4 juin 2026
The context explorer breaks down where tokens go across the system prompt, tool definitions, rules, skills, and more. pic.twitter.com/FccilnZzOzCursor can now show your agent's context usage as an interactive report in a canvas. The context explorer breaks down where tokens go across the system prompt, tool definitions, rules, skills, and more.
-

ChatLLM Integrates Grok 1.5 Imagine, Auto-Routes to Best AI Model
By
–
ChatLLM now has Grok 1.5 Imagine Use The Best AI For Your Use Case. We smartly route to the best model for you AUTOMATICALLY – SeeDance 2.0, Grok 1.5 imagine
Front-end – Opus 4.8
Back-end – GPT 5.5 xHigh
Chat- Flash 3.5 Cheap – DeepSeek Flash Image – GPT -

No shortcuts to frontier: detailed technical report on MAI-Thinking-1
By
–
There are no shortcuts to the frontier. Disciplined, patient, meticulous attention to detail is critical. To give everyone a good sense of our progress we've published a very detailed technical report (109 pages!) outlining how we trained MAI-Thinking-1 and what we learned along
-

Anthropic Engineer Reveals Claude’s Simple Internal Prompting Secrets
By
–
An engineer at Anthropic just shared how the team prompts Claude internally. It looks nothing like the 3,000-word mega-templates the gurus sell you, and the difference is the entire lesson. Look at what it contains. It names real tools from memory: /goal, AskUserQuestion, the
-

LLM Gateway in LangSmith: traceable governance and live updates
By
–
Most governance tools live in their own consoles or dashboards. LLM Gateway lives in LangSmith. When requests are blocked or info is redacted, you get traceable events. See what your agents do, update system prompts or tool configs, re-evaluate against existing test sets, all
-
New Benchmark for Visual State Tracking in Video Understanding
By
–
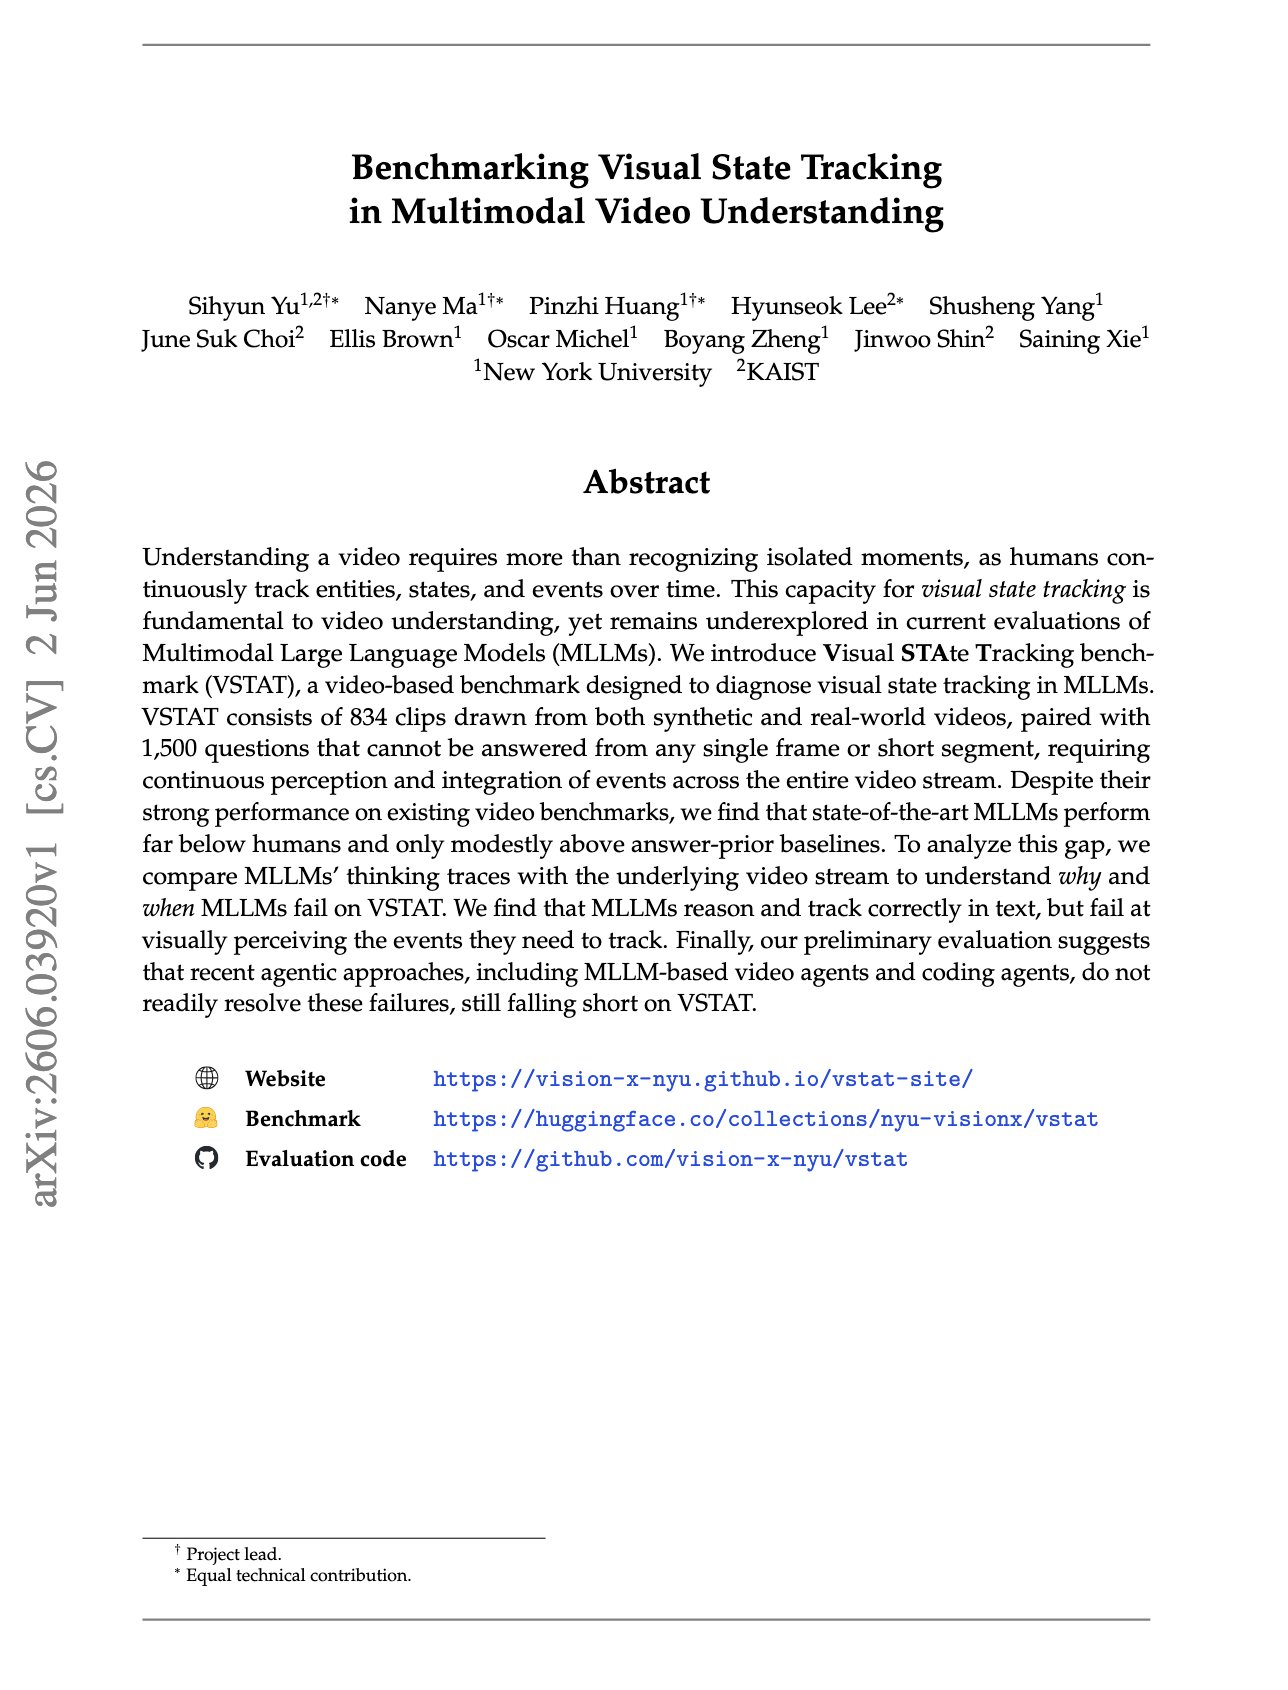
"Benchmarking Visual State Tracking in Multimodal Understanding" A new benchmark for tracking visual states. Even though video MLLMs can describe clips really well, they still cannot reliably track what changes over time. This benchmark contains 834 videos and 1,500