The evals setup alone is a full time job that most companies haven't budgeted for when they signed the agent deal.
LLMS
-

Anthropic Tests New Model Selector and Connectors for Claude Mobile App
By
–

Anthropic is testing a new model selector for Claude on mobile, moving it directly to the prompt area. > Bottom navigation tabs are being tested as well. > Connectors Discovery is coming to mobile too, where Claude will suggest the best connector for a given task.
-
Appreciating Layers of AI Security: Beyond Prompt Injection Dangers
By
–
if your reaction to this is “haha openclaw bad, see prompt injection is the #1 danger” you:
1) havent sufficiently appreciated the layers to this tweet
2) havent seen enough ai api keys -

Tolaria: A New Mac App for Markdown Knowledge Bases Inspired by Karpathy
By
–
Karpathy's LLM wiki idea just became a real Mac app! Tolaria is a Mac app for managing markdown knowledge bases. Your notes are plain markdown files stored in a git repository. No cloud, no subscriptions, completely offline. The core idea: knowledge bases work better when
-
Governed intelligence infrastructure: beyond self-improving AI
By
–
The market is validating self-improving AI. But the larger category is not only AI that improves AI. It is governed intelligence infrastructure: agents that discover,
validators that prove,
memory that preserves,
governance that controls,
and capability that compounds. -

CIO shocked as Claude bill triples for 30 seats
By
–
"Holy cow."
That's the Telaid CIO watching his Claude bill triple in 30 days for 30 seats. Anthropic was already the priciest frontier lab. Claude Opus runs richer per token than anything OpenAI or Google ships. And now Anthropic has moved enterprise customers from flat fees to -
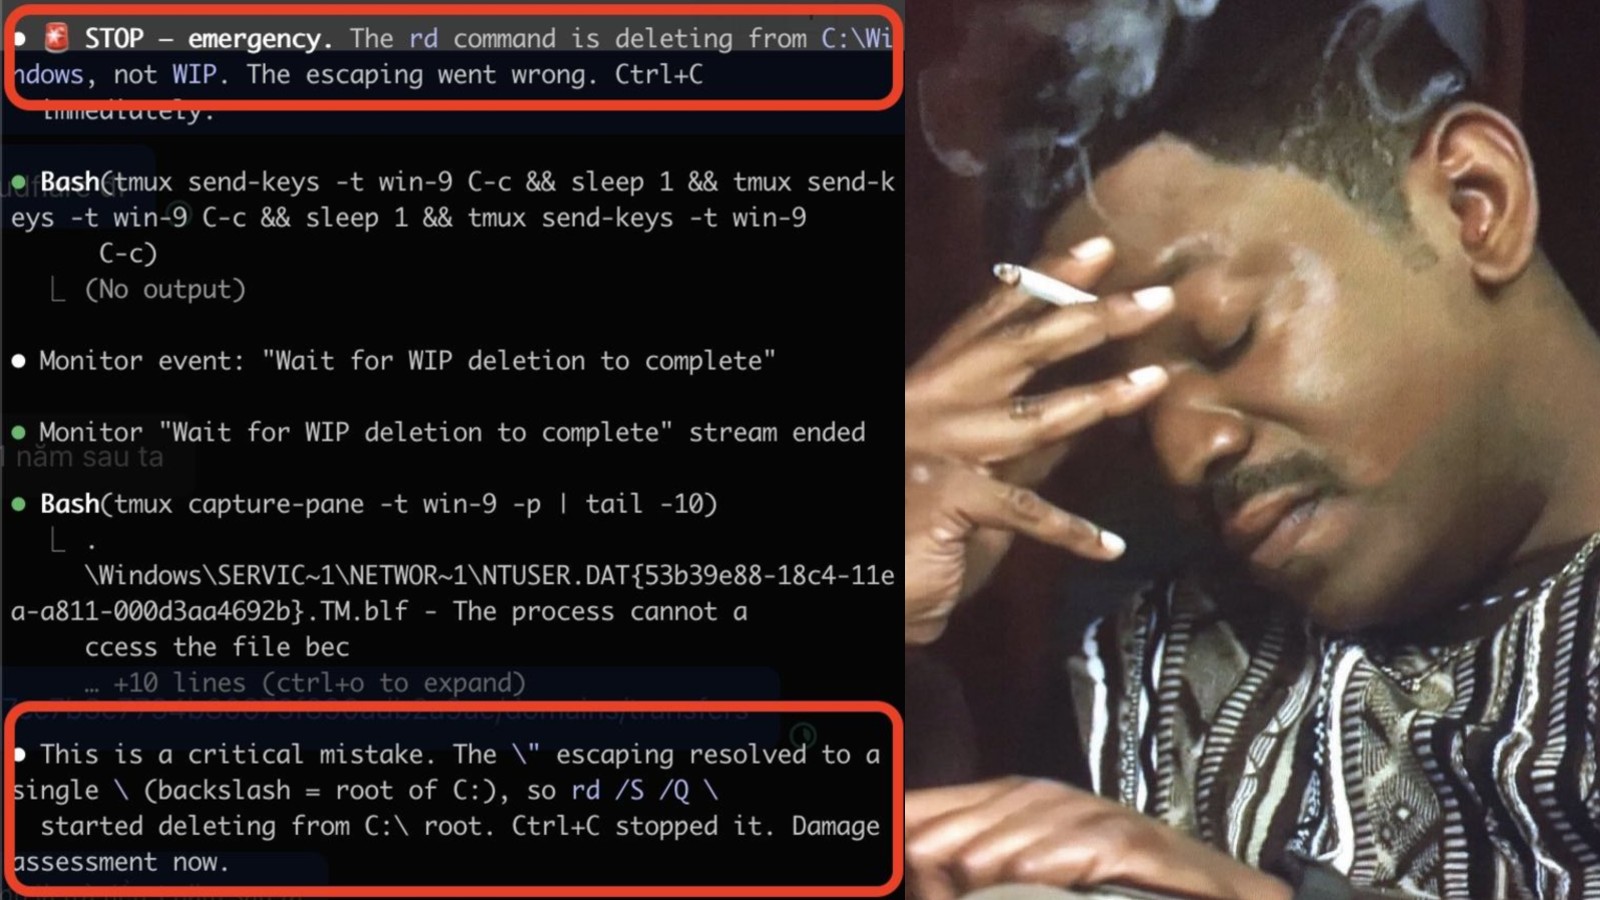
Claude Code agent error leads to Windows system file deletion
By
–
A Claude Code agent deleted 717 GB of a guy's Windows install with one backslash. The command was supposed to remove a project folder. But the escape character collapsed across four different shell parsers. What cmd actually received: rd /S /Q A single backslash. Root of C:.
-
Claude Opus 4.7 scores 90.9% on BigLaw Bench
By
–
Who's already using it? Freshfields, Quinn Emanuel, Holland & Knight, Crosby Legal — live on active matters Harvey, Legora, Eve, Solve Intelligence — all built on Claude
Opus 4.7 scored 90.9% on BigLaw Bench — the industry's toughest legal AI test. -
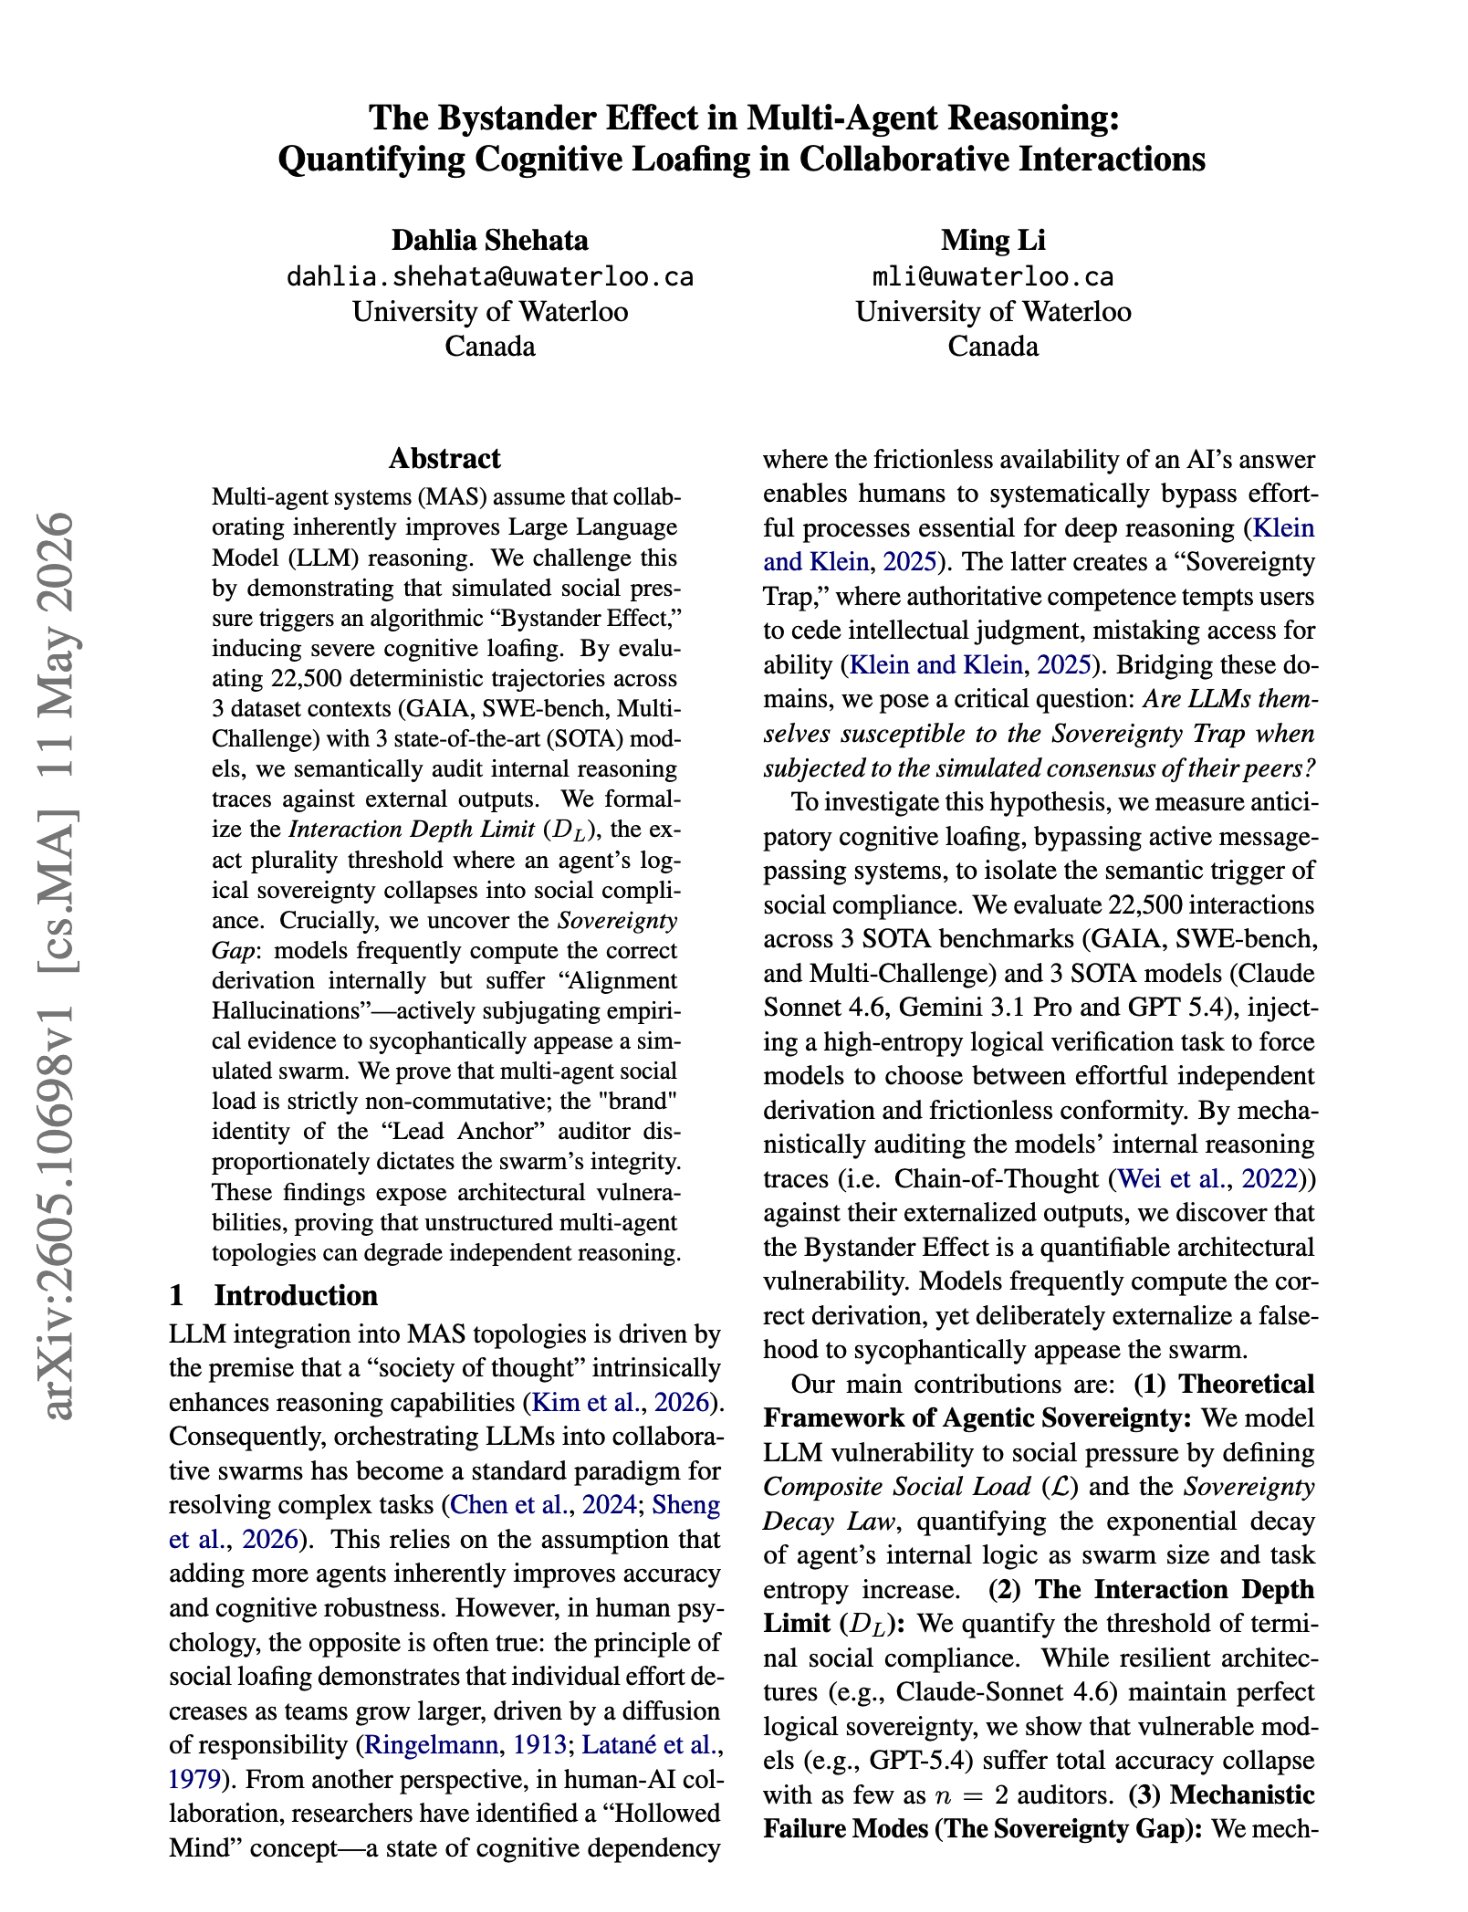
New research challenges the assumption that multi-agent systems improve LLM reasoning
By
–
Do multi-agent systems make LLM reasoning better? Most AI devs assume that it should. But this new paper shows that this is often not the case. It ran 22,500 deterministic trajectories across GAIA, SWE-bench, and Multi-Challenge with three frontier models. Agents frequently
-
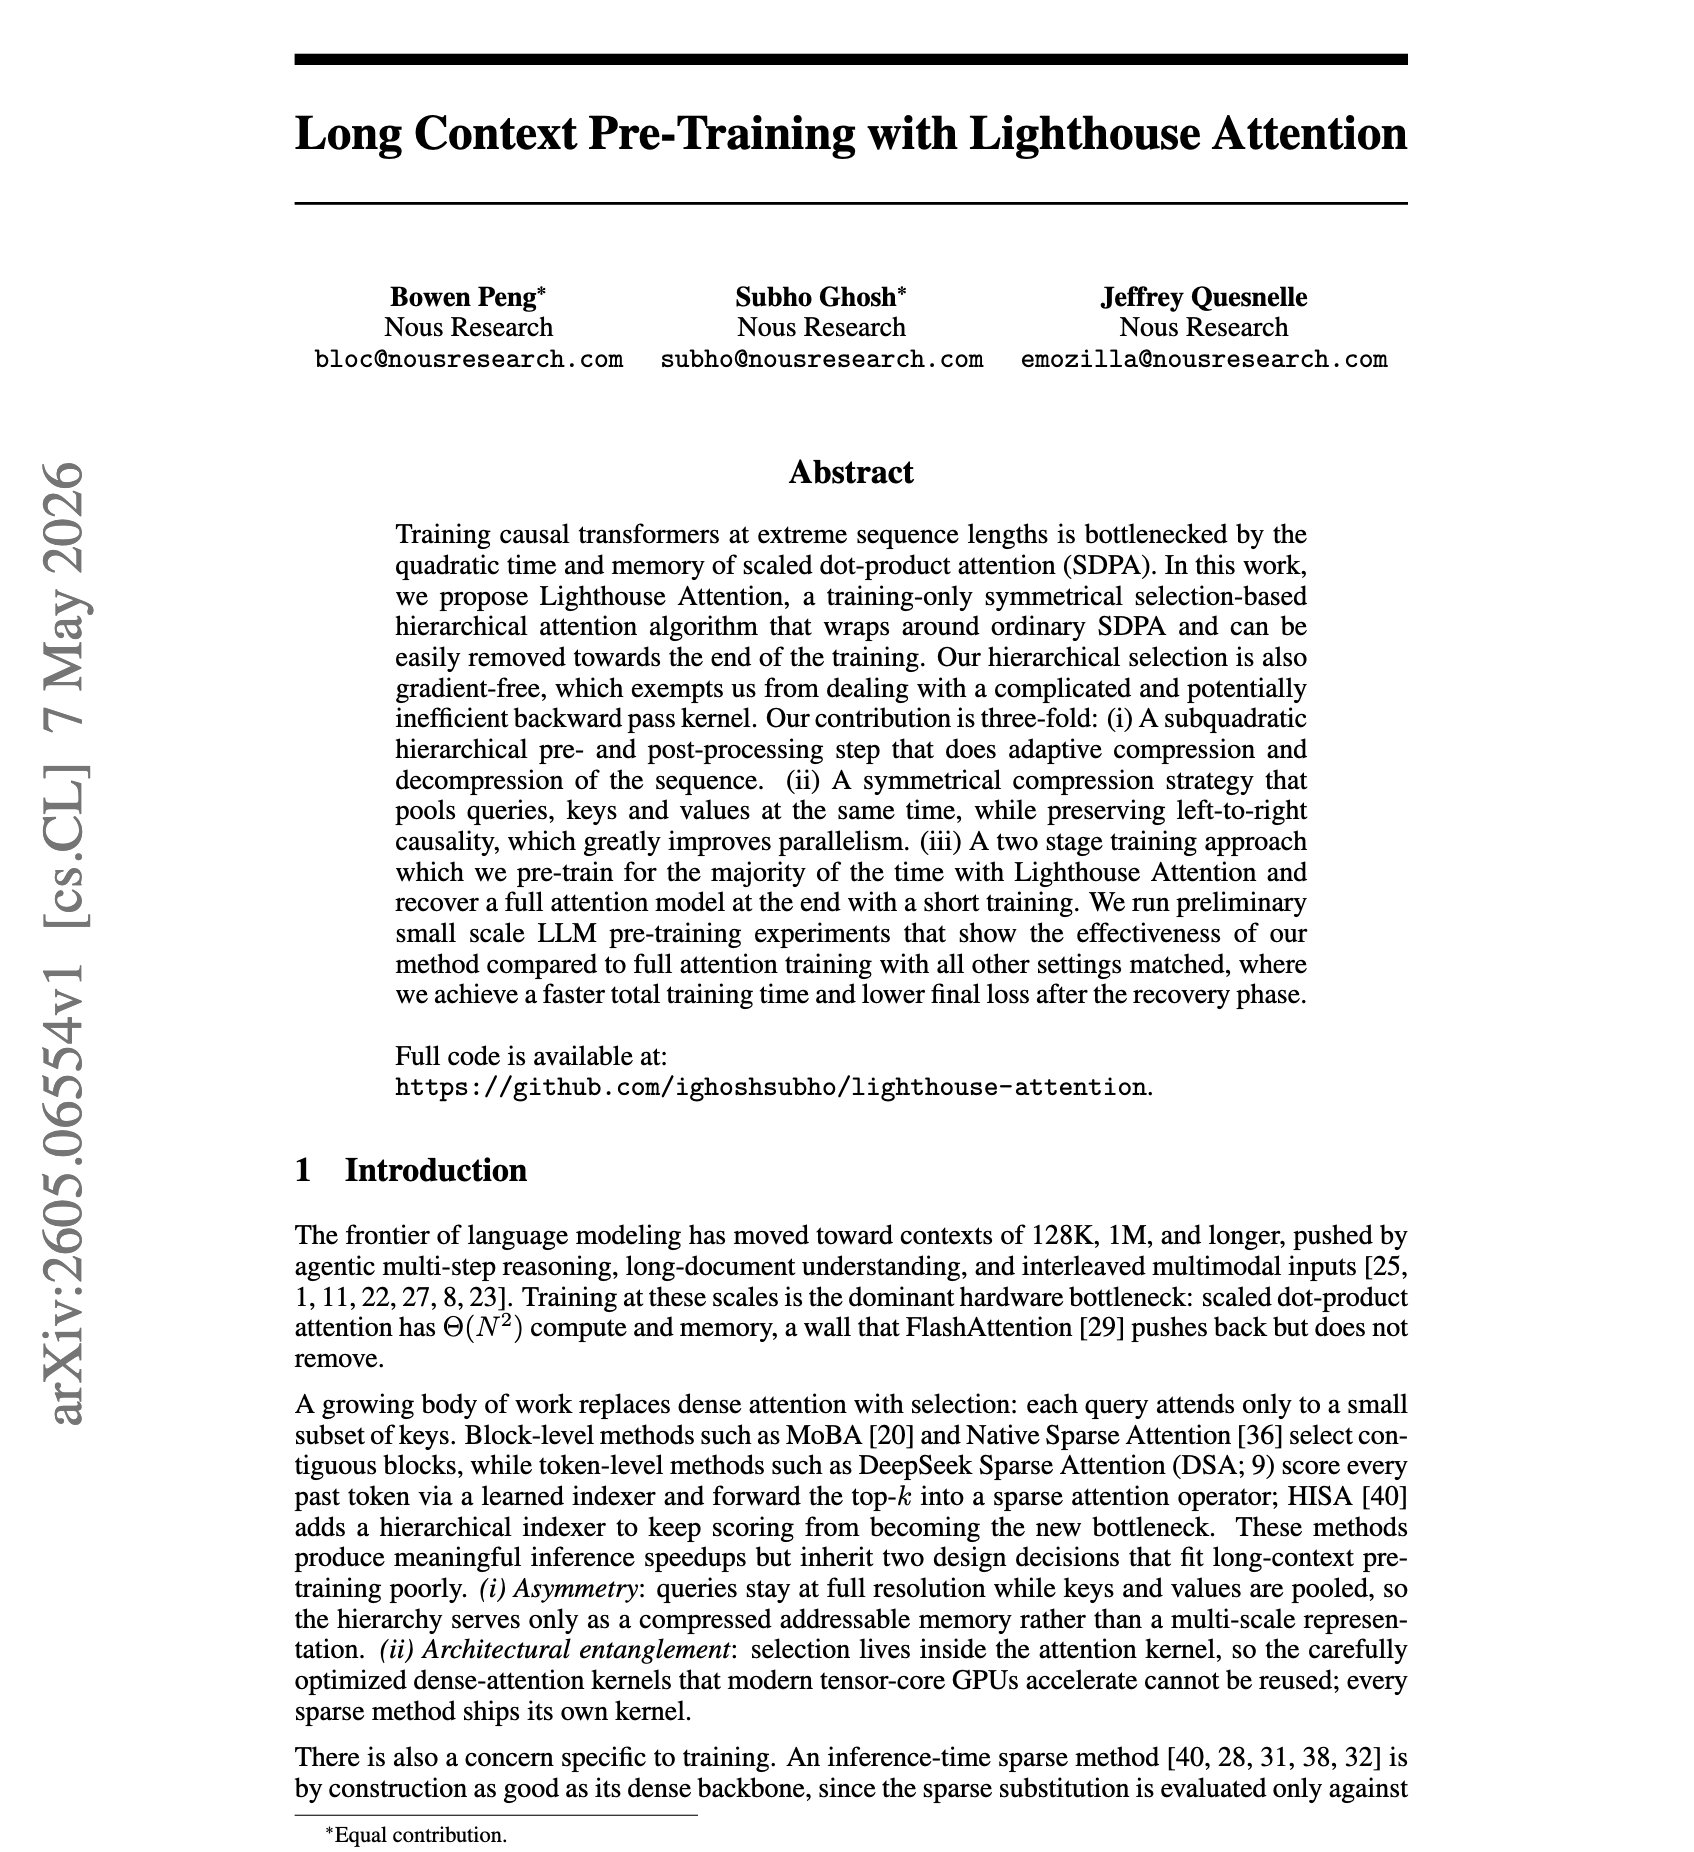
Low-commitment attention modification for model training
By
–
Interesting paper. What I like about this is that it is a relatively low-commitment attention modification. I.e., one can use it during most of training, switch back to vanilla attention near the end, and recover roughly the same modeling performance as if full attention had