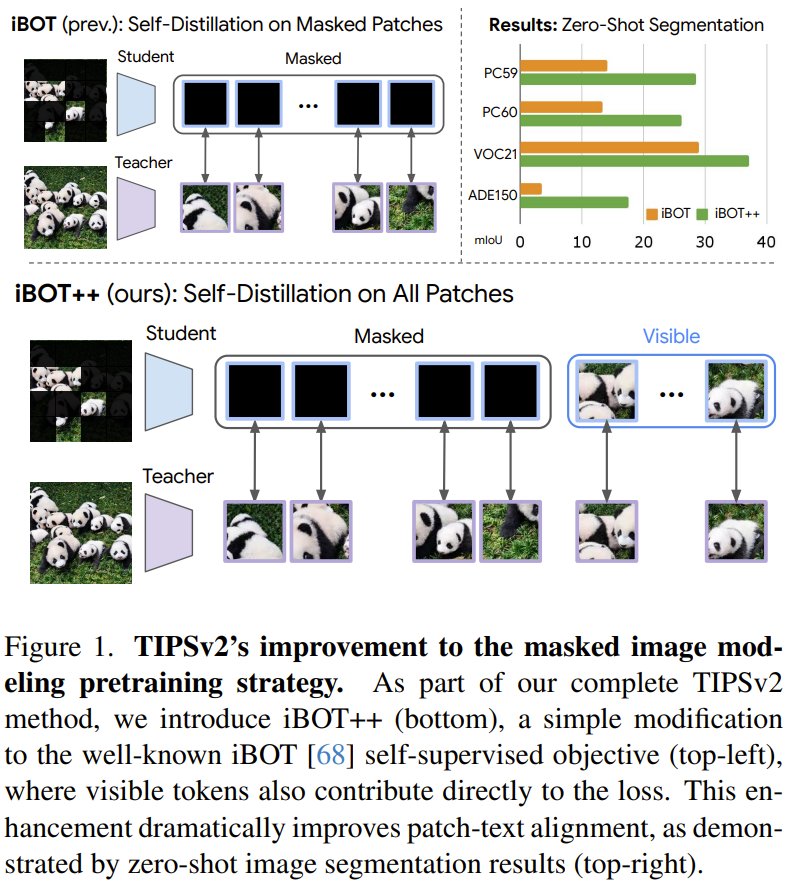
Can vision-language models truly see the fine-grained details in images? Google DeepMind presents TIPSv2. They boost dense patch-text alignment using three novel tricks: a distillation method where the student outperforms the teacher, an upgraded masked image objective
LLMS
-
26TB AI Model Archive Preserved Against Potential Disappearance
By
–
More than 26TB of models 🙂 Just in case they vanish from the internet
-
LangChain Fleet Agents Now Support Multiple AI Models at Scale
By
–
No longer are Fleet agents constrained to a single model.
— LangChain (@LangChain) 4 mai 2026
With multi-model support, you can build more efficient agents at scalehttps://t.co/YJI6Y7SjK0 https://t.co/5cK3wOOadiNo longer are Fleet agents constrained to a single model. With multi-model support, you can build more efficient agents at scale http://
langchain.com/langsmith/fleet -
AI Transparency and Cognitive Impact on Developing Brains Needed
By
–
At the minimum, transparency in what queries lead to which outputs (interpretability), how this connects to educational principles/pedagogy, more evidence of how this may impact cognition, especially of developing brains, in the short, medium and long term.
-
RLHF requires pairwise comparison, not thumbs-up/down
By
–
The thumbs-up/down buttons aren’t for RLHF. The HF in RLHF is selecting the better of two outputs for the same prompt (or, if you have more than two, ordering them best-to-worst). Pointwise data (thumbs, star ratings, etc.) generally doesn’t work well AFAIK.
-

Grok 4.3: 10x cheaper, close to frontier models
By
–
Grok 4.3 is literally 10x cheaper than GPT-5.5 or Claude for token output costs. It's also shockingly close on benchmarks (or better in some long-horizon agent tests) to the frontier models.
-
AI Agent Drifts From Instructions After a Few Days
By
–
Mostly instructing it to do things on a schedule and then it drifting further and further away from what it was instructed to do. Like it will follow instructions for a day or two and then seemingly forget what was instructed a few days prior.
-
Use the right AI model for each task
By
–
Stop asking one AI to do everything. The frontier isn't one model. It's knowing which model to use for which job.
-
Model personality swap creates perfect planner-executor combo
By
–
The models swapped personalities this month. Opus 4.7 got more rigid and precise. GPT-5.5 got more natural and conversational. That's not a bug. That's why this combo works. One model became the perfect planner. The other became the perfect executor. Use them for what
-
Opus outlines, GPT-5.5 drafts and executes
By
–
This works beyond coding. Content strategy: use Opus to outline the argument structure. Use GPT-5.5 to draft. Research: use Opus to design the research methodology. Use GPT-5.5 to execute the analysis. Business planning: use Opus to define the framework. Use GPT-5.5 to